FLASH: Possibly the Most Interesting Efficient Transformer Design in Recent Times
Efficient Transformers—a general term for work aimed at improving Transformer efficiency—are something I've been following relatively closely for a while. The earliest blog post I wrote on the topic goes back to 2019, Born to Save: From Standard Attention to Sparse Attention], back when very little work was being done in this area. Later, such work gradually became more common, and I followed along with some of it, such as linear attention], Performer], and Nyströmformer], and even did some exploration of my own, like the earlier series "The Path to Transformer Upgrades]." As time went on, related work kept multiplying, but most of it was quite dull, so I stopped paying much attention to it.
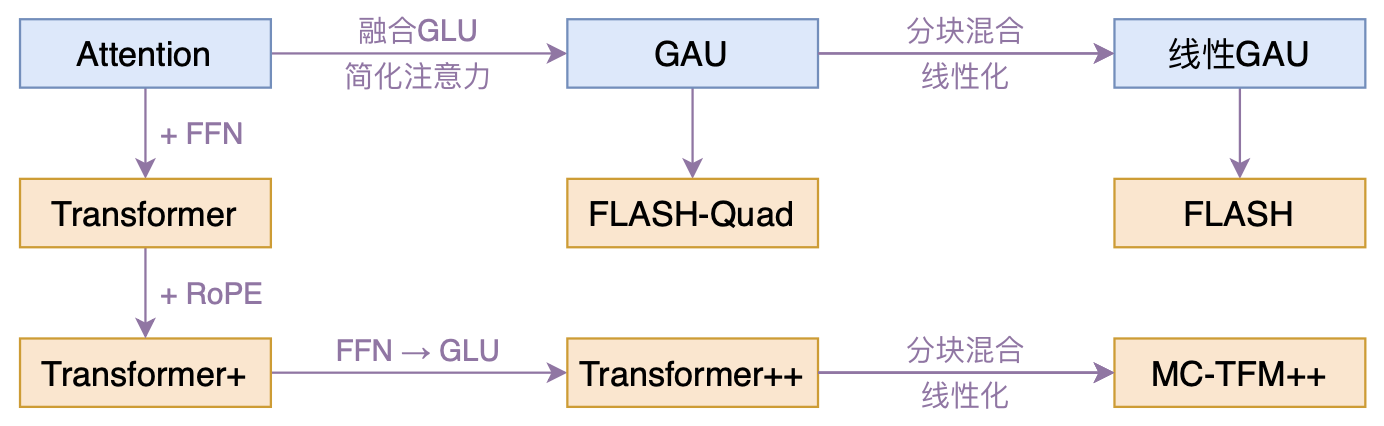
Model lineage diagram for this post
It's a bit like "rain after a long drought" — finally, an efficient Transformer paper has appeared that's genuinely interesting: Google's Transformer Quality in Linear Time]. After reading it closely, I found the paper to be, quite frankly, full of surprises.
What's So Exciting About It
What kind of result deserves to be called a "surprise"? Am I exaggerating? Let's first look at what the paper actually achieves:
1. It proposes a new Transformer variant that still has quadratic complexity, but compared to the standard Transformer, it is faster, uses less GPU memory, and achieves better performance;
2. It proposes a new linearized Transformer scheme that not only improves upon existing linear attention in terms of performance, but also preserves the ability to act as a decoder—while keeping efficient training parallelism when used as a decoder.
Honestly, I think achieving either one of these on its own would already be quite impressive, and this paper manages to achieve both at once, which is why I'm willing to call it "full of surprises." More importantly, the improvements in the paper are, on the whole, fairly natural and elegant, unlike many similar works that feel rather forced. I also carried out a simple reproduction experiment myself, and the results suggest the paper's reproducibility is quite good—so I really do get the sense that "the Transformer is in trouble."
Gated Attention
Without further ado, let's get to the point. We know that the standard Transformer] is built by alternating attention layers and FFN layers, and the core of this paper is proposing a new design that fuses the two: GAU (Gated Attention Unit). This is the key to why the new model is faster, cheaper, and better, and it also means the entire model consists of only one type of layer, which makes it look more elegant as well.
An Early Show of Strength
How exactly do we fuse attention and the FFN? First, the standard FFN is a two-layer MLP:
\begin{equation}\boldsymbol{O}=\phi(\boldsymbol{X}\boldsymbol{W}_u)\boldsymbol{W}_o\end{equation}
Here $\boldsymbol{X}\in\mathbb{R}^{n\times d},\boldsymbol{W}_u\in\mathbb{R}^{d\times e},\boldsymbol{W}_o\in\mathbb{R}^{e\times d}$, and $\phi$ is the activation function. Later, GLU Variants Improve Transformer] found that an FFN using a GLU (Gated Linear Unit) works better, and this was adopted by the later mT5], taking the form:
\begin{equation}\boldsymbol{O}=(\boldsymbol{U}\odot\boldsymbol{V})\boldsymbol{W}_o,\quad \boldsymbol{U}=\phi_u(\boldsymbol{X}\boldsymbol{W}_u),\quad\boldsymbol{V}=\phi_v(\boldsymbol{X}\boldsymbol{W}_v)\end{equation}
Here $\boldsymbol{W}_u,\boldsymbol{W}_v\in\mathbb{R}^{d\times e}$, and $\odot$ denotes elementwise multiplication (the Hadamard product). It's not surprising that GLU is more effective — as far back as 2017, Facebook's Convolutional Sequence to Sequence Learning] found GLU to be crucial, and my own earlier work on DGCNN] also confirmed GLU's effectiveness.
Typically, in a GLU, $\boldsymbol{U}$ has no activation function while $\boldsymbol{V}$ uses Sigmoid, but this paper applies the activation function Swish] (also known as SiLU], Sigmoid Linear Unit) to both $\boldsymbol{U},\boldsymbol{V}$. This can be confirmed from the source code in the appendix, and it's worth pointing out since it differs slightly from the mainstream usage of GLU.
Joining Forces
Since GLU-style FFNs are more effective, let's use that as the basis for our modification. Notice that the FFN cannot replace attention because there's no interaction between tokens—each row of the matrix $\boldsymbol{U},\boldsymbol{V}$ is computed independently. To make up for this shortcoming, a natural idea is to incorporate token-to-token relationships into $\boldsymbol{U},\boldsymbol{V}$, and to make the connection to attention explicit, a fairly natural design is:
\begin{equation}\boldsymbol{O}=(\boldsymbol{U}\odot\boldsymbol{A}\boldsymbol{V})\boldsymbol{W}_o\label{eq:mix}\end{equation}
where $\boldsymbol{A}\in\mathbb{R}^{n\times n}$ is the attention matrix, responsible for fusing information across tokens. The resulting $\boldsymbol{O}$ then includes token-level interactions, and in principle could replace attention on its own. As for how $\boldsymbol{A}$ is computed, we'll get to that shortly.
In formula $\eqref{eq:mix}$, if $\boldsymbol{A}$ equals the identity matrix $\boldsymbol{I}$, this reduces to the GLU-style FFN; and if $\boldsymbol{U}$ is the all-ones matrix, it reduces to ordinary attention. So $\eqref{eq:mix}$ is a simple and natural fusion of attention and FFN, and we'd expect it to be able to replace both attention and FFN, potentially with even better performance.
Weak Attention
As just mentioned, GLU on its own is already quite powerful—otherwise Facebook couldn't have achieved SOTA on Seq2Seq at the time using CNN+GLU. Given how strong GLU already is, one might guess that it weakens the model's reliance on attention. That is, although $\boldsymbol{A}$ is indispensable in formula $\eqref{eq:mix}$, perhaps we can simplify its form. And indeed, that's the case: the original paper uses the following simplified attention matrix:
\begin{equation}\boldsymbol{A}=\frac{1}{n}\text{relu}^2\left(\frac{\mathcal{Q}(\boldsymbol{Z})\mathcal{K}(\boldsymbol{Z})^{\top}}{\sqrt{s}}\right)=\frac{1}{ns}\text{relu}^2\left(\mathcal{Q}(\boldsymbol{Z})\mathcal{K}(\boldsymbol{Z})^{\top}\right),\quad \boldsymbol{Z}=\phi_z(\boldsymbol{X}\boldsymbol{W}_z)\label{eq:relu-att}\end{equation}
Here $\boldsymbol{W}_z\in\mathbb{R}^{d\times s}$, and $s$ is the head size of the attention (set to $s=128$ in the paper), $\mathcal{Q},\mathcal{K}$ is a simple affine transform (like the scale-and-shift with $\gamma$ and $\beta$ in Layer Norm), and $\text{relu}^2$ is the squared result of $\text{relu}$.
Similar to standard scaled dot-product self-attention, the attention matrix here is still derived from an inner product of $\boldsymbol{Q},\boldsymbol{K}$ divided by the square root of the dimension, so the complexity remains $\mathcal{O}(n^2)$. The difference is that the transformation producing $\boldsymbol{Q},\boldsymbol{K}$ has been simplified here, and the activation function has been swapped for $\text{relu}^2$. This activation function might be unfamiliar to many readers—it was in fact discovered via NAS by the same author team in their earlier paper Primer: Searching for Efficient Transformers for Language Modeling]. The final $1/n$ is simply a normalization factor used to remove the effect of sequence length. The success of this design also shows that softmax isn't strictly necessary in attention—it can be replaced with an ordinary activation function plus a simple normalization.
Note that, according to the reference code in the paper's appendix, the actual scaling factor used in the paper's simplified version is $\frac{1}{n^2}$, not $\frac{1}{ns}$ as written above. Personally, I think $\frac{1}{ns}$ makes more sense—otherwise, when $n$ is sufficiently large, every attention term ends up far too small. Besides, if we compare with the denominator used in the softmax of standard attention, it's only on the order of $\mathcal{O}(n)$, so setting it to $n^2$ really doesn't feel principled. I did a simple side-by-side comparison myself and found that at a sequence length of 512, the $\frac{1}{ns}$ version performs slightly better—so I'll go with my own intuition here in this write-up.
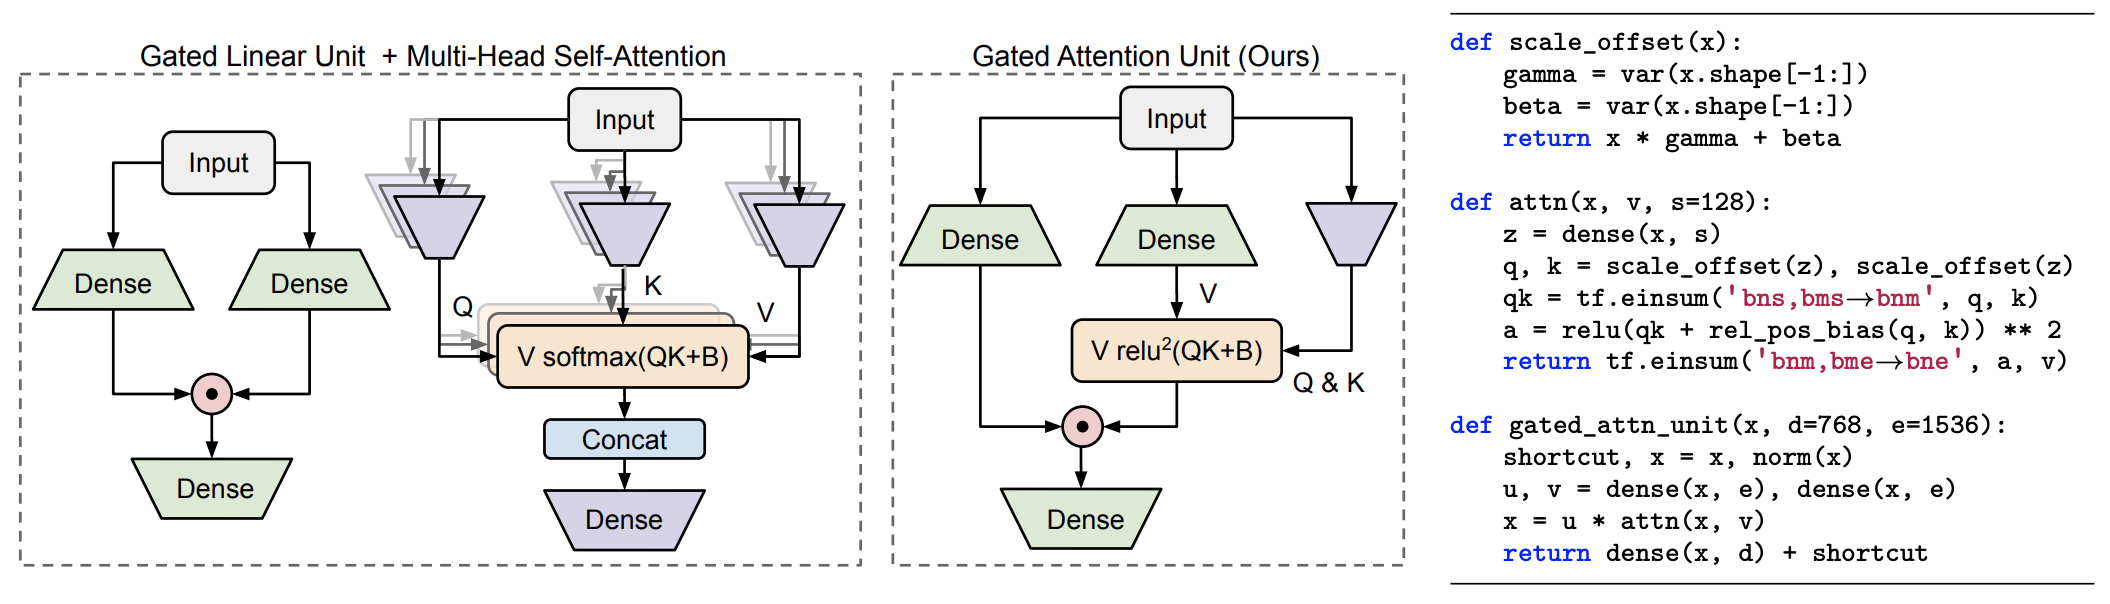
Diagram of GAU and its pseudocode
One Head Doing the Work of Ten
Now, don't blink, because the real "heavyweight" result is about to appear! It seems GLU really is so powerful that its reliance on attention is astonishingly weak—so much so that the authors found: a single head is enough!
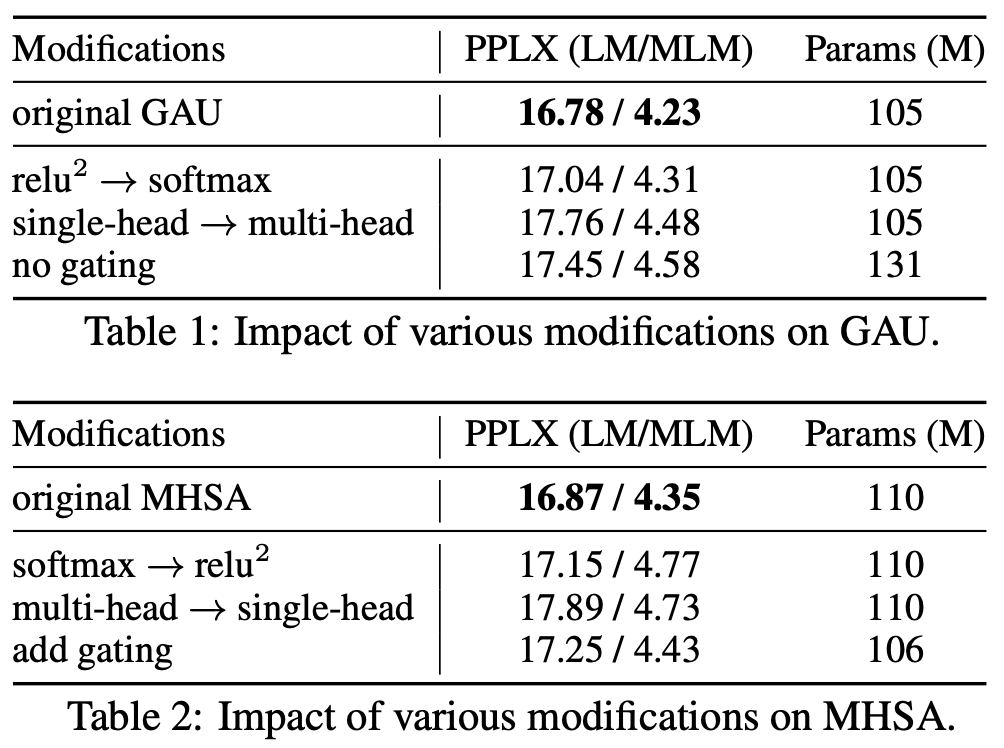
Ablation analysis of GAU vs. multi-head attention
We know that the standard Transformer uses multi-head attention, which requires computing a matrix of size $bhn^2$ during its forward pass, where $b$ is the batch size and $h$ is the number of heads. Just imagine: when $n=1000$, $n=2000$, or even larger, $n^2$ is already "miserable" enough on its own, and now it has to be multiplied by $h$ on top of that—adding insult to injury in terms of both time and space complexity. Now, however, a GAU with just a single head can match or even exceed the same performance—improving computational speed while also lowering memory usage. It's almost a "free lunch."
When GAU has just one head, the parameter count of $\boldsymbol{W}_z$ becomes very small, with most of the parameters residing in $\boldsymbol{W}_u,\boldsymbol{W}_v,\boldsymbol{W}_o$, so GAU's total parameter count is roughly $3de$. In the standard Transformer, on the other hand, attention has $4d^2$ parameters, and the FFN has $8d^2$ parameters (typically $e=4d$ in a standard FFN), giving a total of $12d^2$. So, in terms of parameter count, when $e=2d$, two layers of GAU are roughly equivalent to one layer of Attention plus one layer of FFN in the original model.
Accordingly, in their experiments with GAU, the authors fix $e=2d$, so that a standard Transformer with "$n$ attention layers + $n$ FFN layers" corresponds to a new model with "$2n$ GAU layers," which we'll call FLASH-Quad, where Quad is short for "Quadratic," indicating that the complexity is still quadratic. (I'll come to what FLASH itself means shortly.)
Going Linear and Efficient
FLASH-Quad is already an excellent drop-in replacement for the standard Transformer, but the authors weren't satisfied with its quadratic complexity, and went on to propose FLASH (Fast Linear Attention with a Single Head), which has linear complexity. To do this, the authors propose a "Mixed Chunk Attention" scheme, which can be used not only in the GAU described above but also in standard attention—it's a fairly general-purpose linearization technique.
Existing Approaches
Mainstream efficient-Transformer work on improving attention can broadly be grouped into two categories: "sparsification" and "linearization."
The post mentioned at the start of this article, Born to Save: From Standard Attention to Sparse Attention], is one example of "sparsification" work, and later approaches like Reformer] belong to this camp too, as do pooling-based methods like Linformer], which can be understood as a generalized form of "sparsification." The common feature of this line of work is introducing some inductive prior that forces most attention values to zero, thereby theoretically reducing computation. The drawback is that such approaches often require specialized engineering to actually realize the speedup, or are hard to use for decoders (in the case of pooling-based methods); moreover, their effectiveness tends to depend heavily on the specific inductive prior introduced, which feels somewhat unnatural.
As for "linearization," which we've covered before in Exploring Linear Attention: Does Attention Need a Softmax?], there's relatively more research in this direction. Later works like Performer], Nyströmformer], and more recently cosFormer] and Flowformer] all fall into this category. Broadly speaking, these methods replace the $\phi(\boldsymbol{Q}\boldsymbol{K}^{\top})\boldsymbol{V}$ of standard attention with $(\phi_q(\boldsymbol{Q})\phi_k(\boldsymbol{K})^{\top})\boldsymbol{V}=\phi_q(\boldsymbol{Q})(\phi_k(\boldsymbol{K})^{\top}\boldsymbol{V})$, thereby achieving linear complexity. The advantage of this approach is ease of implementation, but it has two main problems: first, its low-rank nature tends to noticeably degrade performance (see The Path to Transformer Upgrades: 3. From Performer to Linear Attention]); second, when used as a decoder (causal setting), it sacrifices training parallelism, since it must be computed as an RNN—or, if parallelism is to be preserved, it requires $bhns^2$ space complexity, which, compared to the $bhn^2$ of standard attention, only becomes advantageous once $n \gg s^2$, and even then, at $s=64$, it would already require $n \gg 4096$, which is impractical in most cases.
Mixed Chunking
FLASH adopts a "local-global" mixed chunking scheme, combining the advantages of both "sparsification" and "linearization." First, for an input sequence of length $n$, we split it (without overlap) into $n/c$ chunks of length $c$ (without loss of generality, assuming $c$ is divisible by $n$; the paper uses $c=256$). Let $\boldsymbol{U}_g,\boldsymbol{V}_g\in\mathbb{R}^{c\times e},\boldsymbol{Z}_g\in\mathbb{R}^{c\times s}$ denote the $g$-th chunk, with $\boldsymbol{U},\boldsymbol{V},\boldsymbol{Z}$ defined as before. Just as in formula $\eqref{eq:relu-att}$, we obtain $\boldsymbol{Q}_g^{\text{quad}},\boldsymbol{K}_g^{\text{quad}},\boldsymbol{Q}_g^{\text{lin}},\boldsymbol{K}_g^{\text{lin}}$ from $\boldsymbol{Z}_g$ via four simple affine transforms.
Of these, $\boldsymbol{Q}_g^{\text{quad}},\boldsymbol{K}_g^{\text{quad}}$ is used to compute intra-chunk self-attention:
\begin{equation}\hat{\boldsymbol{V}}_g^{\text{quad}}=\frac{1}{cs}\text{relu}^2\left(\boldsymbol{Q}_g^{\text{quad}}{\boldsymbol{K}_g^{\text{quad}}}^{\top}\right)\boldsymbol{V}_g\end{equation}
This represents interaction among tokens within each chunk, which is essentially a form of "sparsification" too, with complexity roughly $\mathcal{O}(n/c\times c^2)=\mathcal{O}(nc)$, proportional to $n$. In implementation, this is equivalent to multi-head attention with $n/c$ heads and sequence length $c$, which can be fully parallelized. If used as a decoder, one simply masks out the upper-triangular part of the attention matrix.
The remaining $\boldsymbol{Q}_g^{\text{lin}},\boldsymbol{K}_g^{\text{lin}}$ is used for global attention, computed directly using the linear attention approach described earlier:
\begin{equation}\hat{\boldsymbol{V}}_g^{\text{lin}}=\frac{1}{n}\boldsymbol{Q}_g^{\text{lin}}\sum_{h=1}^{n/c} {\boldsymbol{K}_h^{\text{lin}}}^{\top}\boldsymbol{V}_h\end{equation}
Note that this operation is exactly equivalent to applying linear attention directly to the full matrices $\boldsymbol{Q}^{\text{lin}},\boldsymbol{K}^{\text{lin}}\in\mathbb{R}^{n\times s}$ and $\boldsymbol{V}$; writing it this way just makes the connection to chunking clearer. If we're building a decoder, we need to prevent leakage of future information, so this must be rewritten in cumulative-sum form:
\begin{equation}\hat{\boldsymbol{V}}_g^{\text{lin}}=\frac{1}{(g-1)n/c}\boldsymbol{Q}_g^{\text{lin}}\sum_{h=1}^{g-1} {\boldsymbol{K}_h^{\text{lin}}}^{\top}\boldsymbol{V}_h\end{equation}
In this case, to preserve parallelism, we only need $b(n/c)se$ space complexity, whereas if we applied linear attention directly without chunking, it would require $bns^2$ (and if the original multi-head usage is included on top of that, it becomes $bhns^2$); given the current parameter settings, $e/c\ll s$, so this is more memory-efficient.
Finally, combining the results of both types of attention and integrating them into GAU gives us the linear version of GAU:
\begin{equation}\boldsymbol{O}_g=\left[\boldsymbol{U}_g\odot\left(\hat{\boldsymbol{V}}_g^{\text{quad}} + \hat{\boldsymbol{V}}_g^{\text{lin}}\right)\right]\boldsymbol{W}_o\end{equation}
The Transformer model built from this linear GAU is what the authors call FLASH.
Some Discussion
I believe the reason for building this "local-global" mixed attention via chunking, beyond just reducing computational cost, is that it produces an attention distribution more closely aligned with reality. Based on our empirical understanding of NLP, dependencies in natural language are mostly local; global, extremely long-range dependencies do exist, but they aren't dominant. This mixed attention design therefore helps the model emphasize local dependencies without discarding long-range ones. The original paper also runs an ablation study showing that local attention is relatively more important than global attention, and that the mixed design performs best overall.
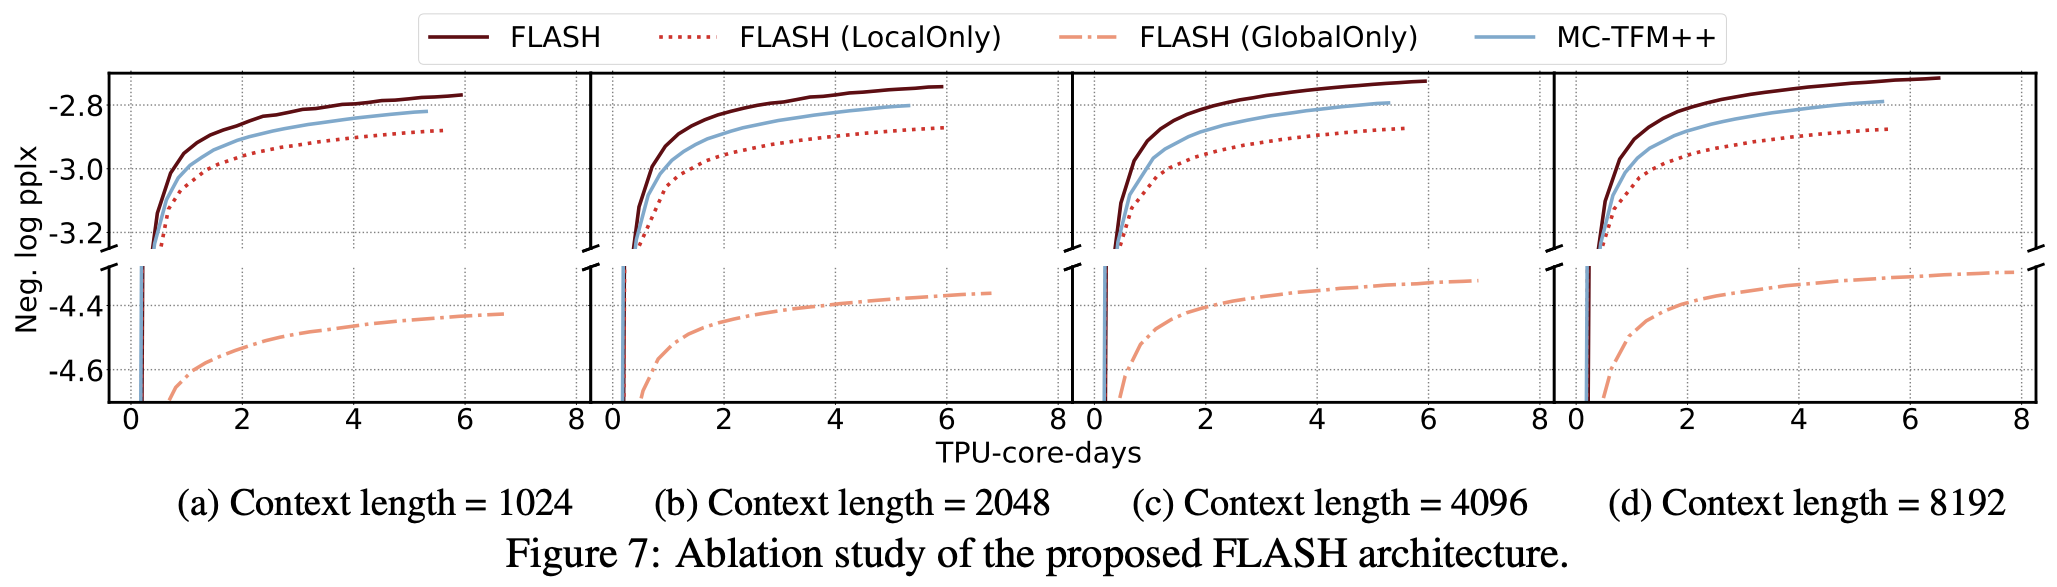
Ablation experiments on global and local attention
Some readers might also worry that non-overlapping chunking could hurt prediction quality at chunk boundaries. The original paper addresses this: it notes that introducing more sophisticated overlapping local attention does improve performance somewhat, but at additional computational cost—and given an equal increase in computational budget, the gains from overlapping local attention are smaller than what you'd get by simply adding a few more layers of the current non-overlapping GAU. So the current non-overlapping design strikes a good enough balance between speed and performance.
Finally, this "mixed chunking" linearization scheme is inherently general-purpose—it can be applied not only within GAU, but also within the standard Transformer, i.e., keeping the standard Attention+FFN combination but linearizing attention via mixed chunking. The original paper calls this "MC-TFM" and includes a corresponding comparison, showing that GAU still has an edge over MC-TFM in the linearized setting.
Experimental Analysis
Regarding the experimental results for GAU and FLASH, I think two things are most worth highlighting.
The first is the comparison between the newly designed Gated Attention Unit (GAU) and standard multi-head self-attention (MHSA)—essentially, the comparison between FLASH-Quad and the standard Transformer, shown below:
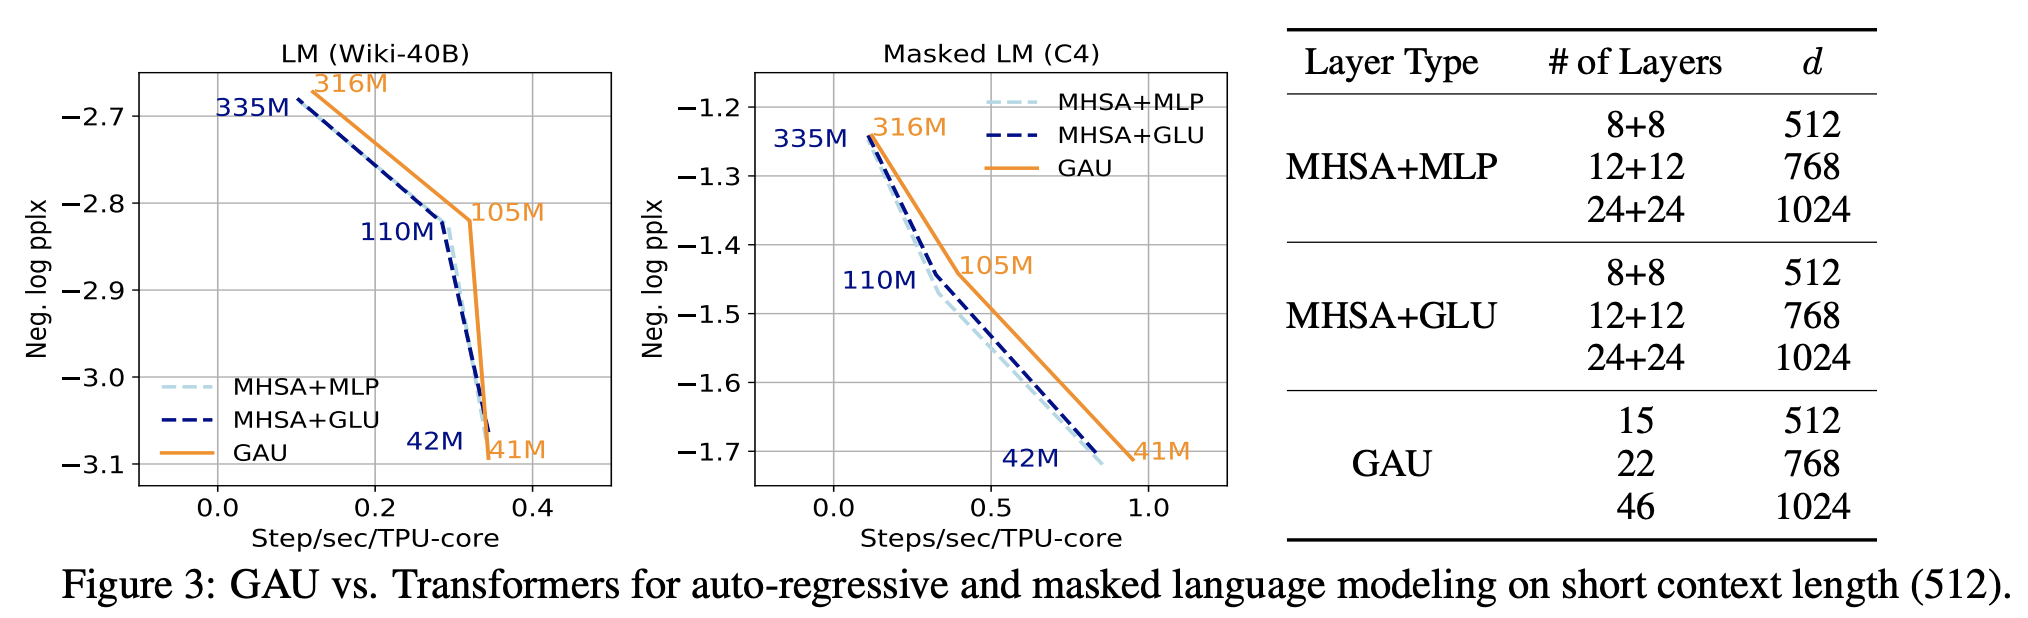
Comparison between GAU and multi-head attention
Note that the x-axis is speed and the y-axis is performance—points closer to the top right of such a plot are more desirable (both faster and better). The figure above shows that regardless of model size, GAU has an edge over the corresponding multi-head attention model.
The second is the experimental results table for the FLASH model:
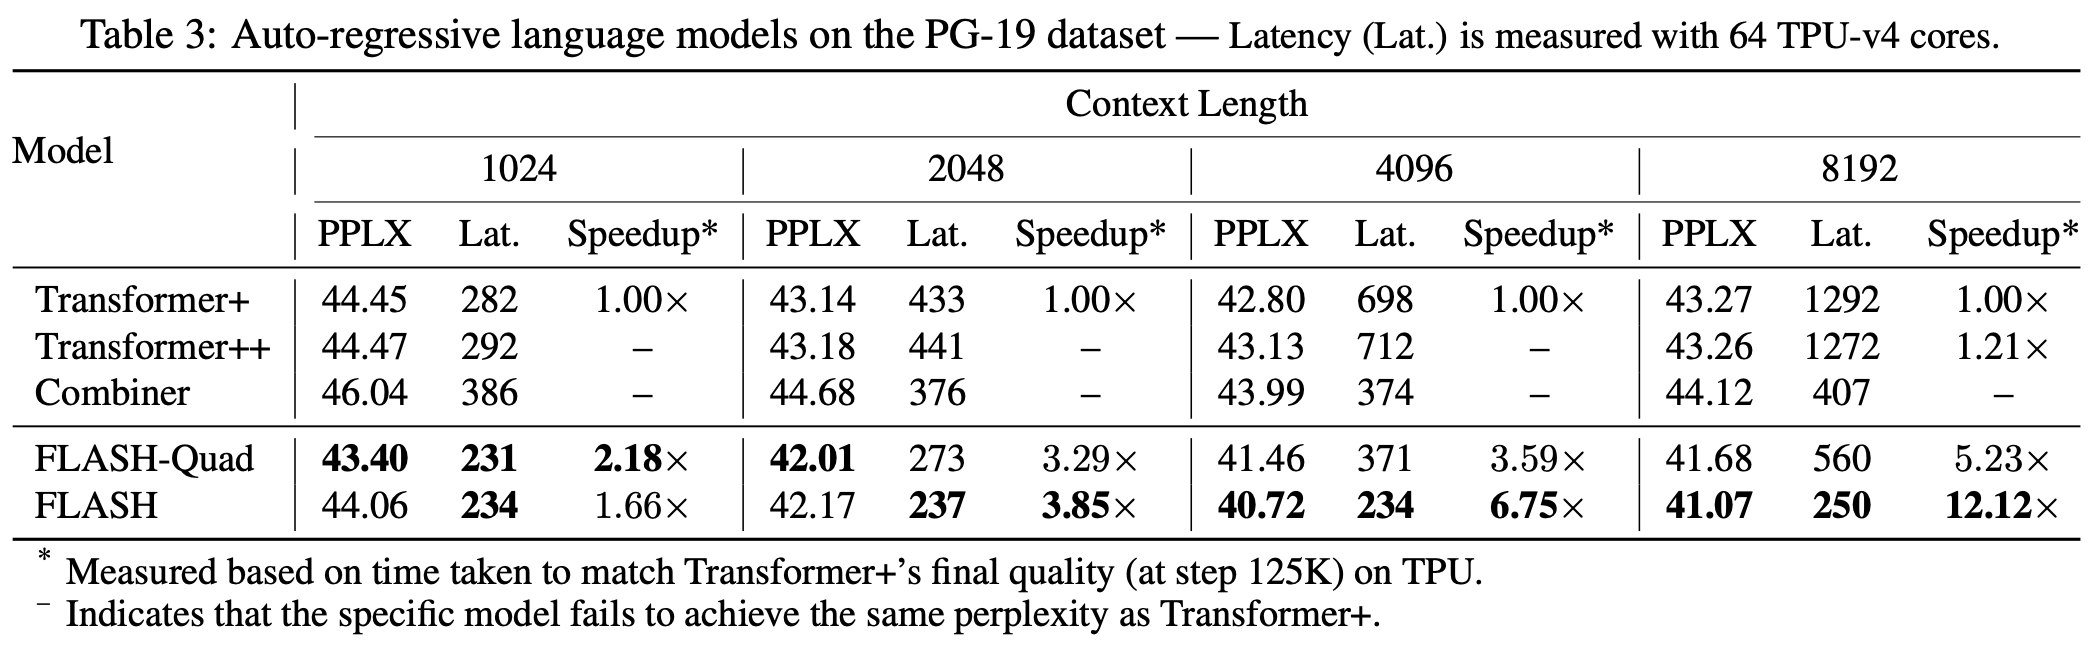
Comparison between FLASH and standard Transformer
This table shows even more directly that:
1. Even though FLASH-Quad and the Transformer are both quadratic in complexity, FLASH-Quad is both faster and better;
2. When sequences are sufficiently long, the linear-complexity FLASH is faster than FLASH-Quad while achieving comparable performance.
Honestly, even just the speedup achieved by FLASH-Quad—which is still quadratic in complexity—is more than what many so-called "linear complexity" works manage to achieve, which really shows how powerful GAU is. By the way, the paper specifically notes that rotary position embedding (RoPE)], which I proposed earlier, notably improves the performance of both the Transformer and FLASH, so the Transformer+, Transformer++, FLASH-Quad, and FLASH models in the paper's experiments all incorporate RoPE encoding—so I'll allow myself a small moment of pride here.
Additionally, the table above doesn't include a comparison of memory usage. In my own testing, at the base scale with a sequence length of 1024, the maximum usable batch size for FLASH-Quad is nearly double that of the Transformer, which indicates it clearly reduces memory consumption. I also briefly tried Chinese pretraining with the small version of FLASH-Quad, and found its performance to even edge out RoFormer (RoPE+Transformer), so the results reported in the paper really do hold up. Unfortunately, I currently have limited compute available, so I couldn't run more thorough tests—I'll share more results if I get the chance later on.
Further Thoughts
That brings the introduction to GAU and FLASH to a close. As of writing this post, the authors hadn't yet released the full source code on GitHub, but the appendix already includes key source code (in TensorFlow) that can be almost directly copied and used, so implementing it shouldn't pose any real difficulty. Anyone with the interest and the compute is welcome to try reproducing the experiments themselves. Also, if anything in the paper is unclear, the source code in the appendix can serve as a helpful reference.
Now for a bit of nitpicking—let me point out a few places where I feel the paper falls short of perfection.
First, I think FLASH-Quad and FLASH aren't decoupled quite as cleanly as they could be. As I noted at the start of this post, both FLASH-Quad and FLASH are "heavyweight" results in their own right—and to me, FLASH-Quad is arguably even more valuable, since the quadratic complexity of self-attention itself provides enough degrees of freedom to enable interesting tricks, like those used in UniLM]. So FLASH-Quad really deserves to stand as its own independent, worthy model—but in the original paper, it feels more like a transitional stepping stone toward FLASH, which I think somewhat "shortchanges" FLASH-Quad. Thankfully, the authors did separate out the GAU concept on its own, which helps mitigate this to some extent.
Also, since GAU can replace both attention and the FFN, and by design it's meant to replace self-attention, the authors don't seem to have addressed whether it could also replace cross-attention—there's no corresponding experiment in the paper. So, could GAU potentially replace cross-attention too? Judging from the form of equation $\eqref{eq:mix}$, it seems plausible in principle, but it's unclear whether GAU could still get away with just a single head when replacing cross-attention, since the single-head property is arguably the biggest highlight of GAU's replacement of self-attention—it's the key to being both faster and cheaper. Furthermore, the paper only conducts LM and MLM language modeling experiments, without any "pretrain + fine-tune" experiments, so it's unclear how well GAU transfers. Perhaps once I have more compute available, I'll try to fill in this gap myself.
Lastly, there's one thing I don't fully understand: GAU/FLASH-Quad/FLASH simultaneously use three types of positional encoding—additive absolute, additive relative, and RoPE—even though, in principle, using just one should suffice. In my own GAU experiments, I only used RoPE and still got quite good results, so I'm not sure what the rationale is for combining all three here. Also, judging from the source code given in the paper's appendix, the authors don't seem to have handled padding very carefully, and the recursive computation of the normalization factor for the decoder case doesn't look quite right either (the sum of the first $t$ terms should be divided by $t$, not $n$)—these are minor but fixable details. Of course, it's possible the authors' actual code is correct, and the appendix code was simplified purely for readability, since it's explicitly labeled as "pseudocode" there anyway.
Summary
This post introduced a new efficient-Transformer design from Google, which fuses attention and the FFN into a single new layer type called GAU, yielding the Transformer variant FLASH-Quad. The authors further propose a "mixed chunking" linearization scheme, yielding the linear-complexity FLASH model. Current experimental results show that both FLASH-Quad and FLASH outperform the standard Transformer in speed, memory efficiency, and quality all at once. Perhaps before long, All You Need won't be Attention anymore, but GAU.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.