The chart-topping T5 model — now you can play with it in Chinese
I wonder if anyone still remembers Google's chart-topping work from last year, T5? The one flying the banner of "everything is Seq2Seq," scaled up to a whopping 11 billion parameters, and swept multiple NLP leaderboards including GLUE and SuperGLUE. Even a full year later, T5 still sits at #1 on the SuperGLUE leaderboard, comfortably holding a 2% lead over second place. However, for those of us in the Chinese NLP community, T5 has probably felt a bit irrelevant, for a simple reason: there was no Chinese version of T5 to use. Well, that's about to change, because Google has recently released a multilingual version of T5 (mT5), which of course includes Chinese. It's not a dedicated Chinese-only version, but it's good enough to make do with.
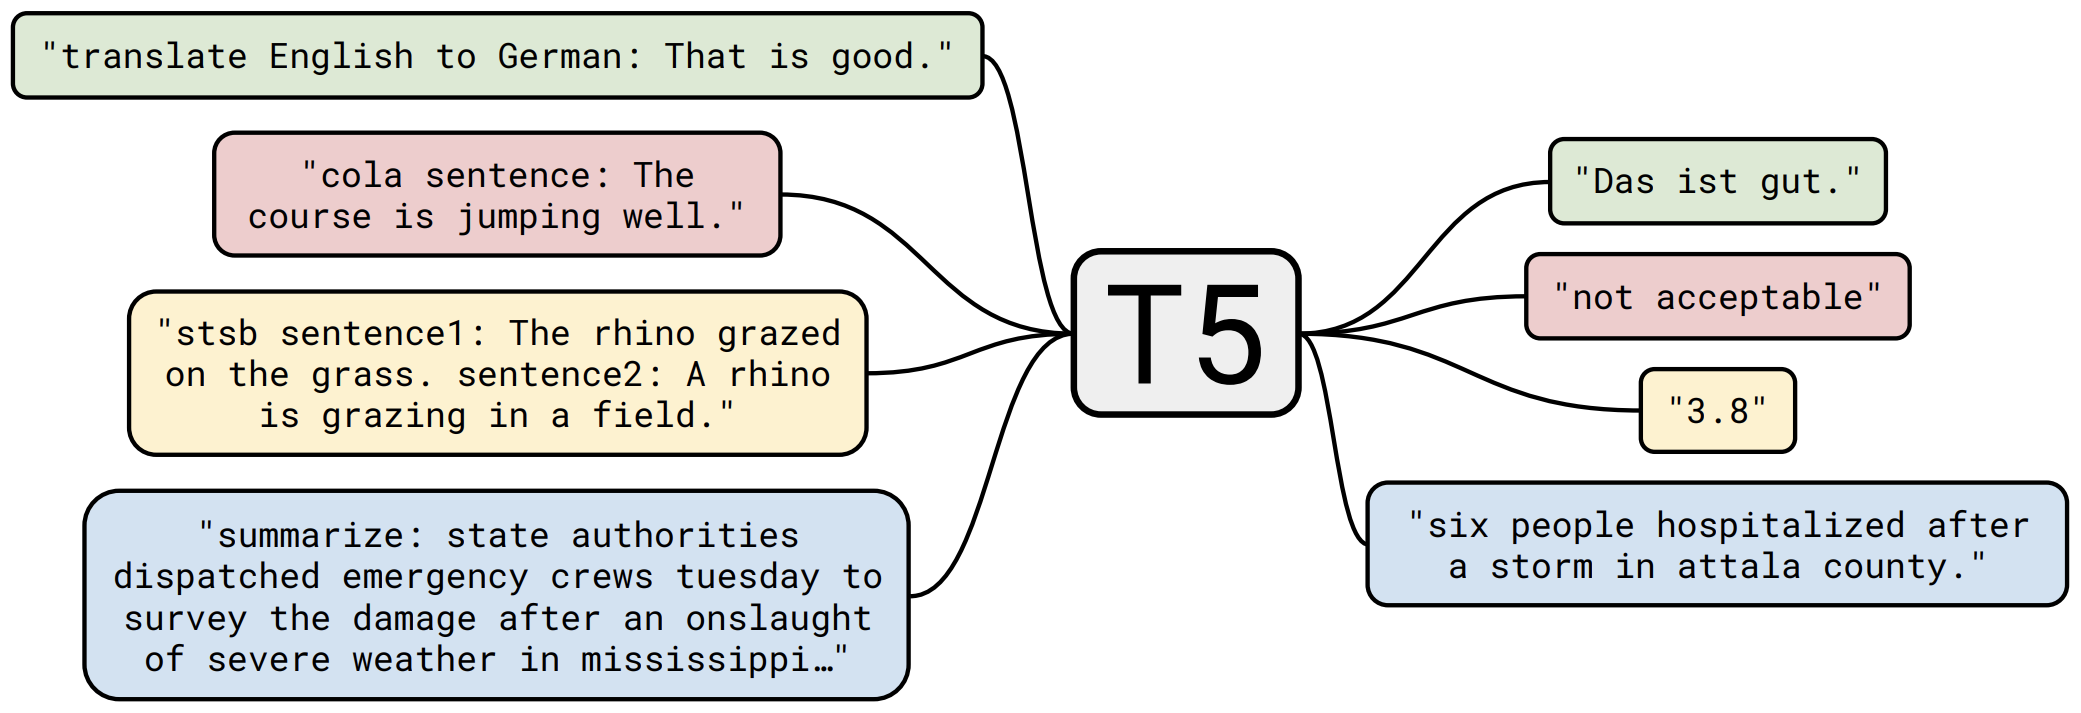 T5, where "everything is Seq2Seq"
This post will give a brief review and introduction of the T5 model, and then show how to call mT5 in bert4keras to perform Chinese-language tasks. As a native Seq2Seq pretrained model, mT5 performs quite well on text generation tasks, and is well worth trying out. more
T5
Like BERT, T5 is a pretrained model from Google, introduced in the paper Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer, with code at text-to-text-transfer-transformer. T5's philosophy is "everything is Seq2Seq": it uses a standard Encoder-Decoder architecture and builds both unsupervised and supervised text-generation pretraining tasks, ultimately pushing performance to a new level.
Training
T5's pretraining consists of both unsupervised and supervised parts. The unsupervised part uses a nearly 800GB corpus built by Google (called C4 in the paper), and the training objective is similar to BERT's, except reformulated as a Seq2Seq task — you can think of it as an advanced fill-in-the-blank problem:
Input: When will there be a bright moon again, [M0] I ask the blue sky, I don't know [M1], what year is tonight? I want to [M2] and go back, but fear the jade towers and jasper halls, too [M3] high up; dancing [M4] with my clear shadow, how could it compare to being in the human world.
Output: [M0] raising my wine cup and asking [M1] the palace in the sky [M2] riding the wind [M3] unbearably cold [M4] playing with
The supervised part, meanwhile, collects data from common NLP supervised tasks and likewise converts them uniformly into Seq2Seq tasks for training. For example, sentiment classification can be converted like this:
Input: Identify the sentiment of this sentence: This trip to Beijing was really great.
Output: Positive
Topic classification can be converted like this:
Input: What kind of news is this? Eight months later, we can finally see the women's volleyball team back on the court.
Output: Sports
Reading comprehension can be converted like this:
Input: Reading comprehension: Trump and Biden are both running for the next U.S. presidency. Based on the above, answer the question: What nationality is Trump?
Output: American
As you can see, this kind of transformation shares the same spirit as GPT-2, GPT-3, and PET — the idea is to express whatever task we want to perform in natural language, and then convert everything into text prediction. Readers can also refer back to an earlier post, Do we really need GPT-3? No, BERT's MLM can also do few-shot learning, for related background. Overall, in our internal experiments, a large enough model, enough data, and supervised pretraining are all key ingredients in T5's success, and "everything is Seq2Seq" provides an effective way of combining these key ingredients.
Results
T5's main achievements are summarized in the table below:
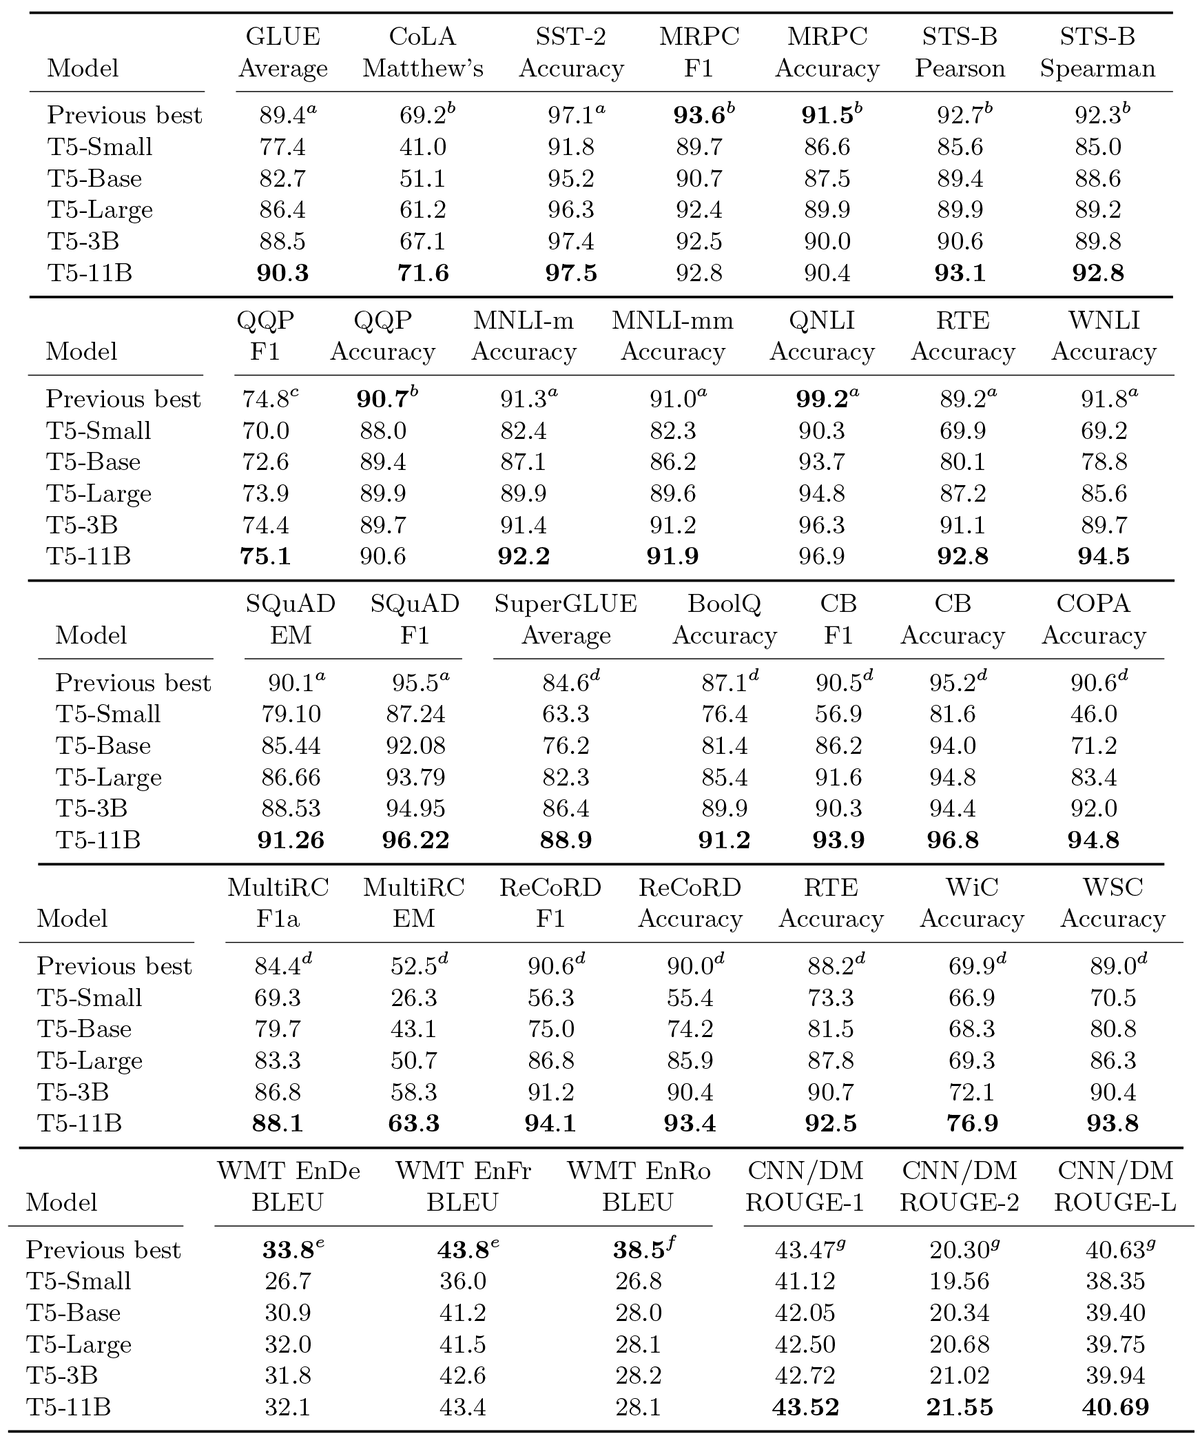 Summary of T5's results
Besides topping multiple leaderboards, T5 also systematically tuned many of the adjustable hyperparameters across the entire training pipeline — for instance, whether a standard Encoder-Decoder architecture works better than a UniLM-style structure, whether BERT's masking approach is better than alternatives for unsupervised pretraining, whether a 15% random-mask ratio is really optimal, and so on. In the end they produced the table below, and rather ruefully remarked that "we actually feel our T5 experiments weren't thorough enough" — which gives off a bit of a "we've paved the road so thoroughly that no one else has anywhere left to go" vibe. In any case, these training results are well worth a careful look for anyone working on language models — they might save us all a lot of trial and error.
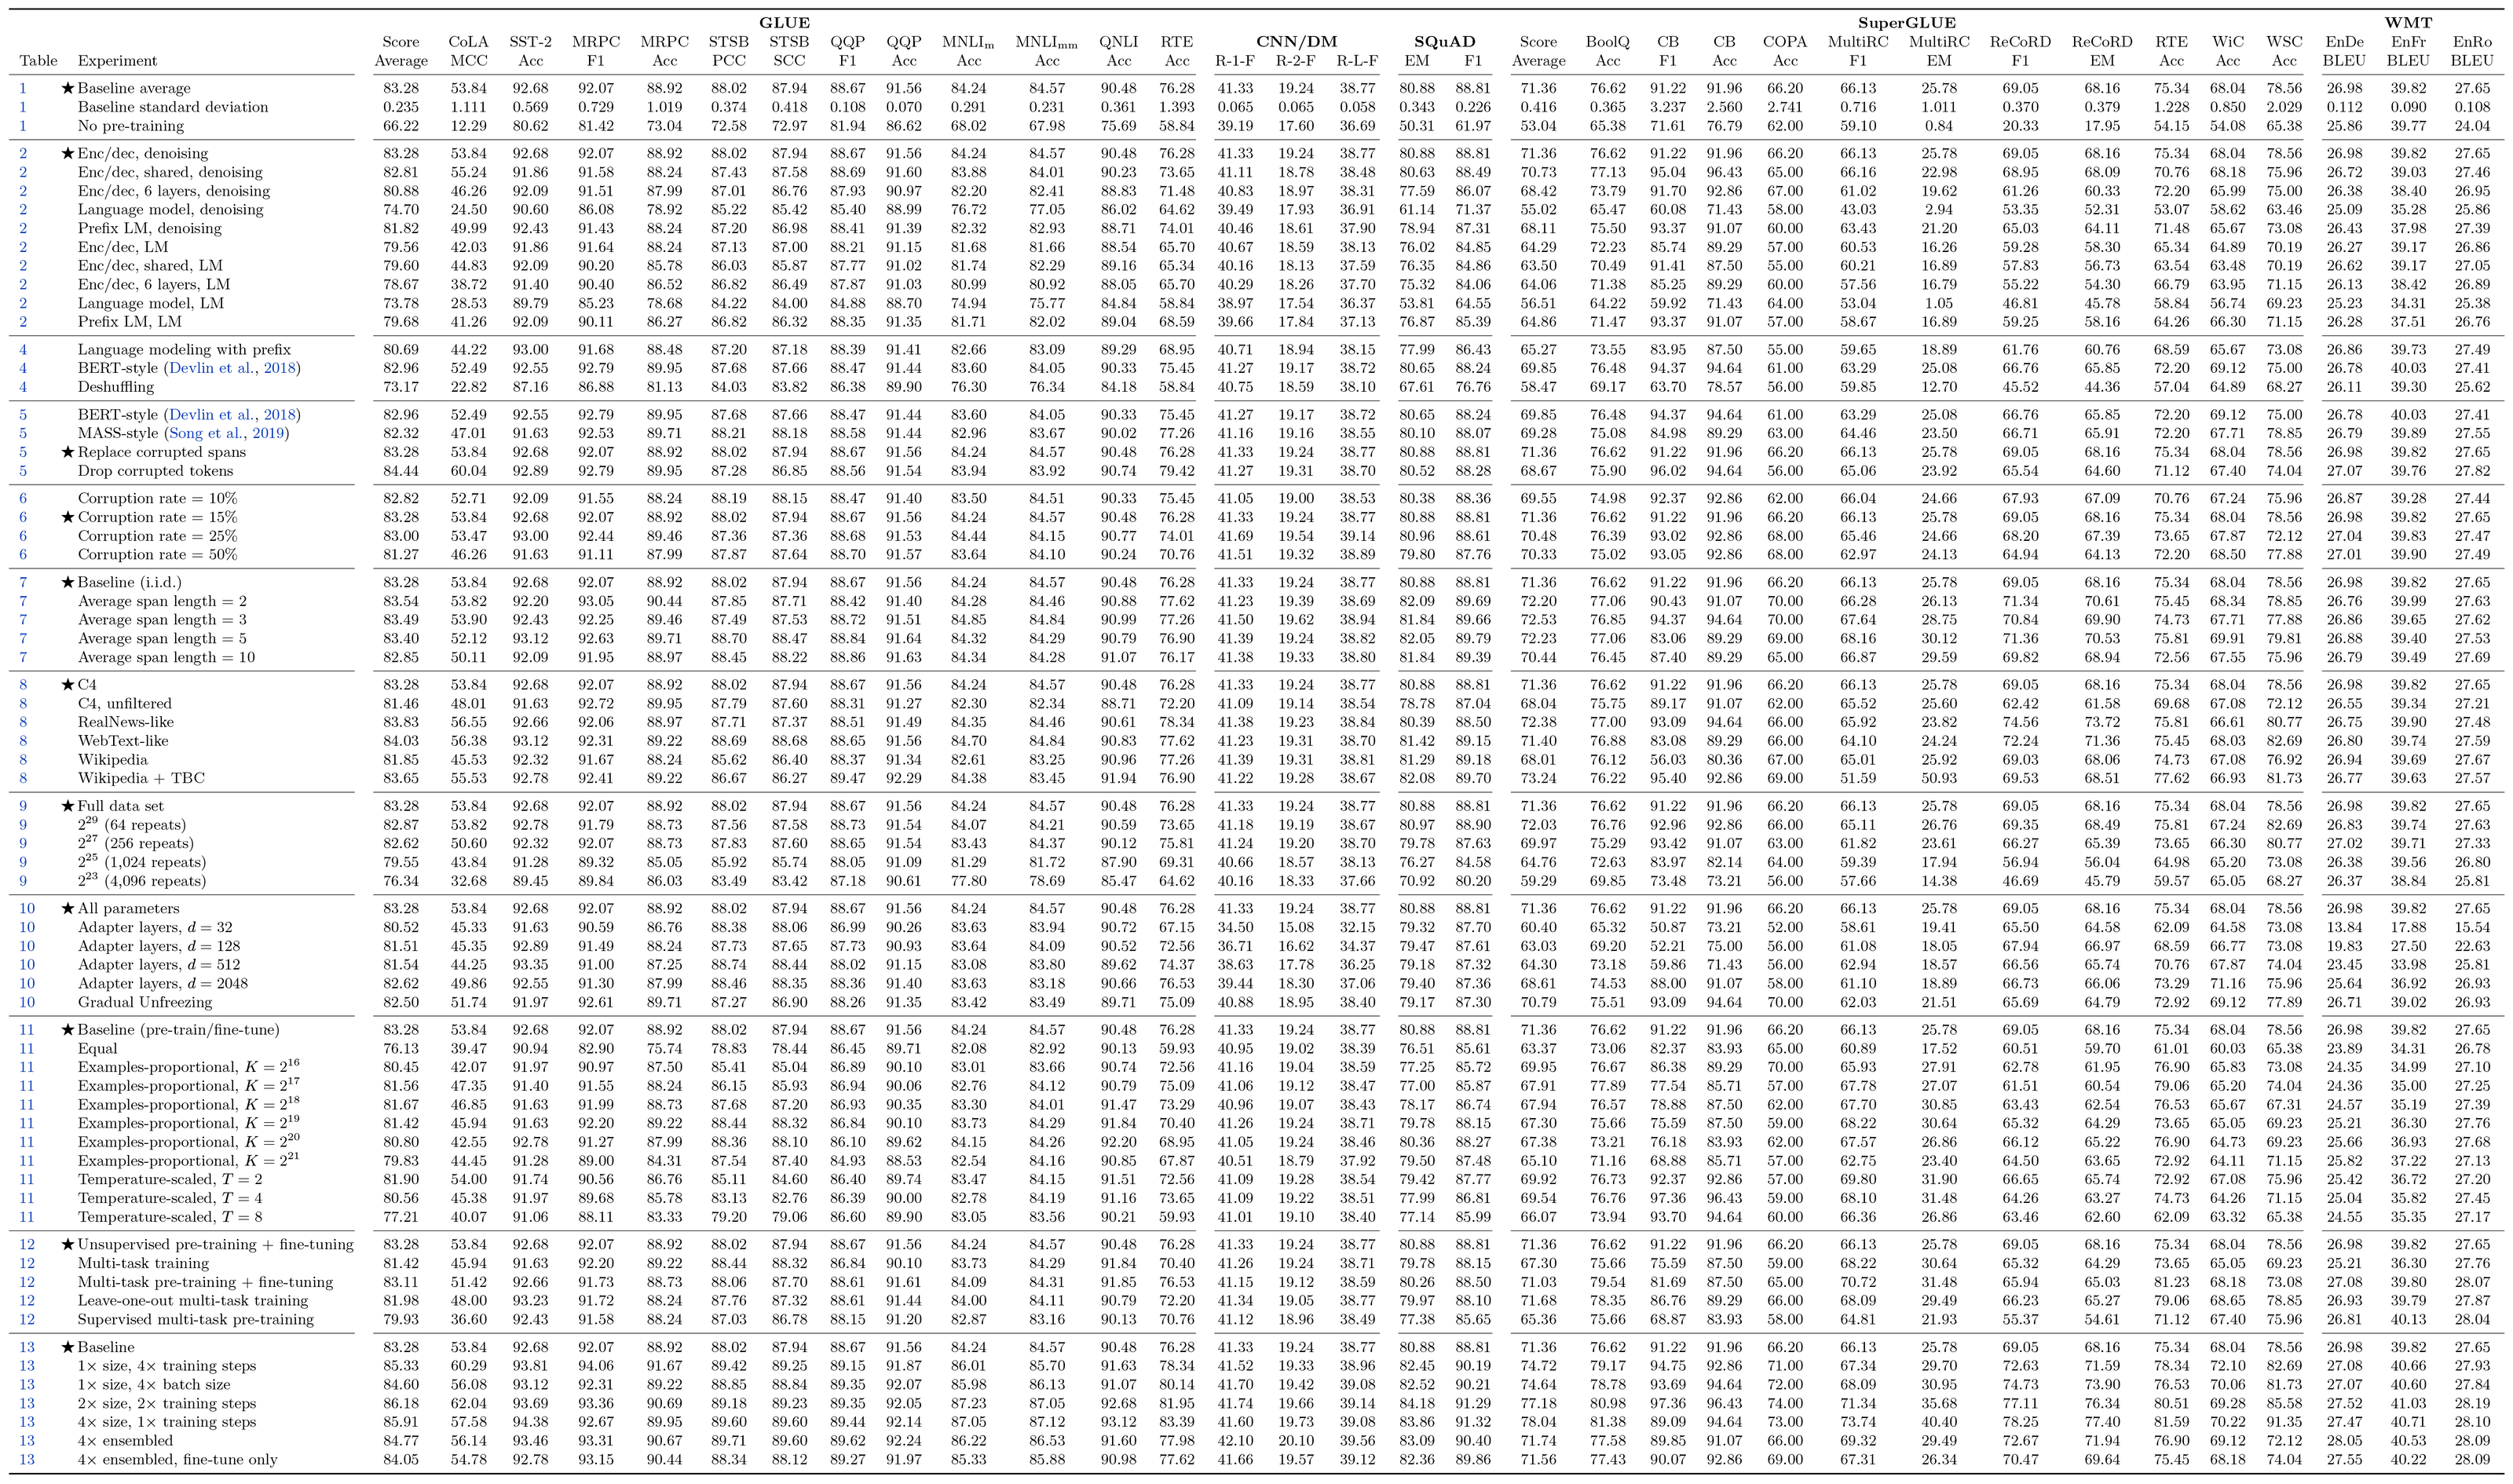 T5's exhaustively detailed "training bible" (click to enlarge)
mT5
As for mT5, i.e. Multilingual T5, the multilingual version of T5, it comes from the recent paper mT5: A massively multilingual pre-trained text-to-text transformer, with code at multilingual-t5, which has likewise pushed multilingual NLP leaderboards to a new level. For us, of course, the most important thing is that mT5 includes Chinese, so we finally have a chance to try T5 on Chinese tasks.
T5.1.1
Overall, mT5 inherits directly from T5 and is basically the same architecture, but in terms of model structure, mT5 uses the T5.1.1 scheme, which we'll briefly introduce here.
Something many people don't know is that, since its release last October, T5 quietly went through a minor upgrade this year — details can be found in the GitHub link. Officially, the pre-upgrade T5 is called T5.1.0, and the post-upgrade version is called T5.1.1. The main change comes from the paper GLU Variants Improve Transformer, which borrows the GLU (Gated Linear Unit) from Language Modeling with Gated Convolutional Networks to enhance the FFN block. Specifically, T5's original FFN was (T5 has no bias terms):
\begin{equation}\text{FFN}(x)=\text{relu}(xW_1)W_2\end{equation}
which is now changed to:
\begin{equation}\text{FFN}_{\text{GEGLU}}(x)=\big(\text{gelu}(xW_1)\otimes xW_2\big)W_3\end{equation}
That is, the first transformation layer, which used a relu activation, has been changed to a gated linear unit with gelu activation. This increases the FFN's parameter count by 50%, but according to the paper's results, it noticeably improves performance. In addition, T5.1.1 also changed the embedding layer: in the original T5.1.0, the encoder's embedding layer, the decoder's embedding layer, and the softmax layer used for the decoder's final probability distribution all shared the same embedding matrix. Now, in T5.1.1, only the encoder and decoder embedding layers are shared, while the softmax layer for the decoder's final probability distribution uses a separate embedding matrix. Of course this substantially increases the parameter count, but Google's findings show that this yields better results — a conclusion summarized in the recent paper Rethinking embedding coupling in pre-trained language models. One last change: T5.1.1 removes dropout during pretraining, using dropout only during downstream fine-tuning.
After these adjustments, Google retrained and released the entire T5.1.1 model family, downloadable from the GitHub link mentioned above. Note that T5.1.1 only underwent unsupervised pretraining, yet its performance is still quite excellent. Since T5.1.1 brings a clear improvement, mT5 also adopted the T5.1.1 architecture.
Results
mT5 essentially rebuilds a multilingual version of the dataset, mC4, and then trains it using the T5.1.1 scheme — there's no notable technical innovation on the methodology side. As for training details, readers can check the original paper, which is actually fairly short, since T5 already paved the way.
As for mT5's results, they are mainly summarized in the following table:
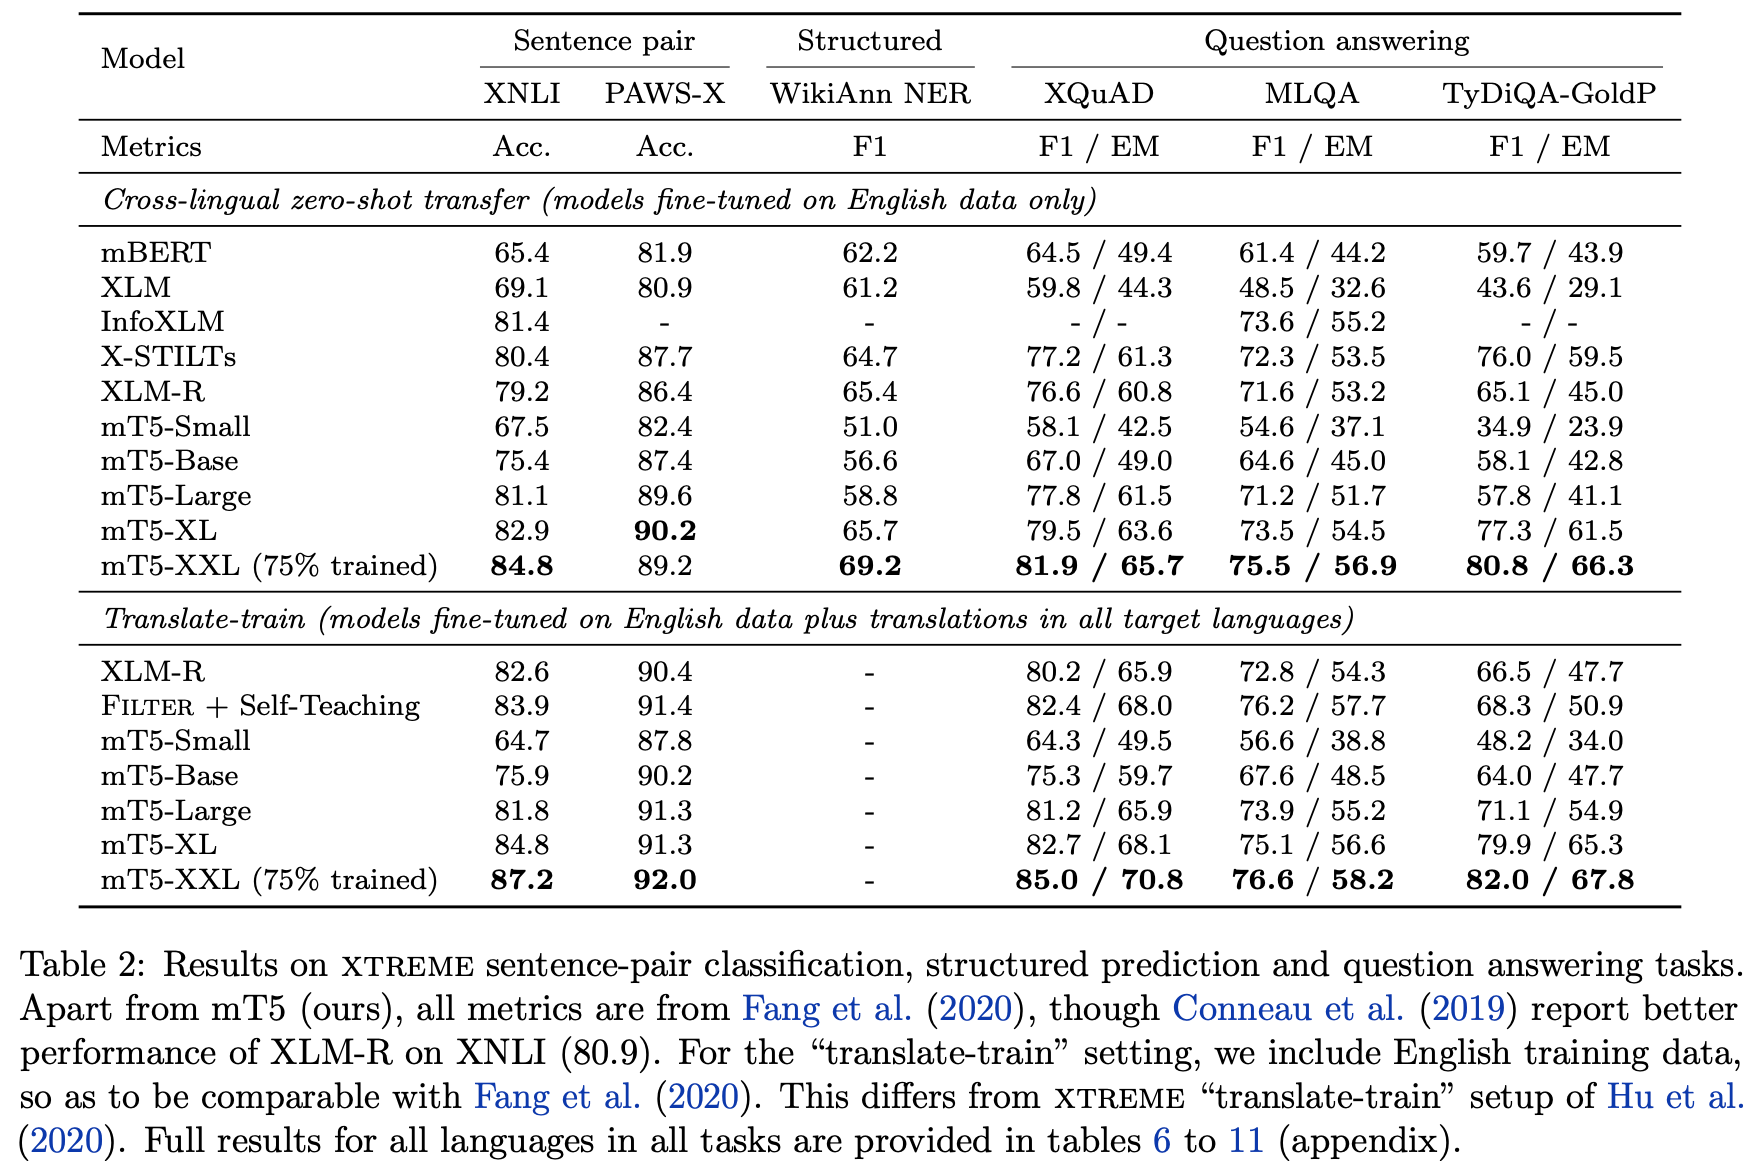 mT5's "results"
Readers might wonder how one should even evaluate a multilingual model like this. The simple approach would be to directly fine-tune a cross-lingual machine translation task on top of it and see how much it improves. But in fact, for multilingual models, researchers are more concerned with its zero-shot performance across languages — in plain terms, given the same task, if you fine-tune on one language, can the model be used directly on other languages without further training? This is exactly what "Cross-lingual zero-shot transfer (models fine-tuned on English data only)" means in the figure above, and as you can see, mT5 performs quite impressively there.
Hands-on
Now, finally, for the part everyone's been waiting for: hands-on practice. Here we'll briefly walk through the workflow and tricks for using the mT5 model in bert4keras to perform Chinese text-generation tasks. bert4keras has supported calling mT5 since version 0.9.1, so if you want to follow along with the experiments below, please upgrade bert4keras to 0.9.1 or later first.
GitHub link: https://github.com/bojone/t5_in_bert4keras
Basics
The basic code for loading the mT5 model into Keras via bert4keras is:
# 模型路径
config_path = '/root/kg/bert/mt5/mt5_small/t5_config.json'
checkpoint_path = '/root/kg/bert/mt5/mt5_small/model.ckpt-1000000'
spm_path = '/root/kg/bert/mt5/sentencepiece.model'

# 加载分词器
tokenizer = SpTokenizer(spm_path, token_start=None, token_end='</s>')

# 加载模型
t5 = build_transformer_model(
    config_path=config_path,
    checkpoint_path=checkpoint_path,
    model='t5.1.1',
    return_keras_model=False,
    name='T5',
)

encoder = t5.encoder
decoder = t5.decoder
model = t5.model
As you can see, this isn't very different from loading BERT in bert4keras. Building t5_config.json and downloading model.ckpt-1000000 are both explained in detail on GitHub — please head there for the specifics. The complete code (including training and decoding details) can also be found on GitHub, so I won't go into it further here.
Worth mentioning: for Chinese, the results given by the tokenizer contain words, meaning that mT5 operates at the word level for Chinese, just with a relatively coarse vocabulary granularity. This further confirms that the direction we took in our earlier work, Faster without sacrificing accuracy: WoBERT, a word-granularity Chinese BERT, was the right one.
Chinese
I believe most readers of this blog only care about Chinese tasks, some may also care about English tasks, and few readers, if any, care about tasks in languages other than Chinese and English. However, mT5 covers 101 languages with a total vocabulary of 250,000 tokens, and since it uses the T5.1.1 architecture where the softmax doesn't share parameters, the embedding layer ends up eating up a huge chunk of the parameter budget. For example, mT5 small has 300 million parameters in total, of which 250 million belong to the embedding layers — and the key issue is that most of those parameters are useless to us, purely a waste. So, for those of us mainly interested in Chinese tasks, it's worth trimming down this embedding layer.
Trimming the model is straightforward — you just need to remove the unneeded rows from the two embedding matrices. The key question is how to decide which tokens to keep, and how to obtain a trimmed-down sentencepiece model afterward. Deciding which tokens to keep might seem simple at first — just keep the Chinese tokens — but you also need to keep a portion of English tokens, and it might look like a mere regular-expression problem, but it's actually not that simple: a token made of English letters isn't necessarily English, and a token made of Chinese characters isn't necessarily Chinese either — it's a rather annoying issue. So I came up with another approach: use this 250,000-token tokenizer to tokenize a Chinese corpus of several dozen GB that I had collected, count the frequency of the resulting tokens, and then select the top tokens by frequency (in the end I kept just over 30,000 tokens). This is a bit more time-consuming, but much more reliable, ensuring that the tokens we actually need are retained. Once the vocabulary is decided, you then need to build a new sentencepiece model — this was a bit of a hassle too, but after some searching I eventually got it working, and the method is shared on GitHub.
After this kind of processing, building the new model requires only adding three extra lines of code related to keep_tokens, and the GPU memory required drops substantially, while the quality of Chinese generation remains essentially unchanged:
# 模型路径
config_path = '/root/kg/bert/mt5/mt5_base/t5_config.json'
checkpoint_path = '/root/kg/bert/mt5/mt5_base/model.ckpt-1000000'
spm_path = '/root/kg/bert/mt5/sentencepiece_cn.model'
keep_tokens_path = '/root/kg/bert/mt5/sentencepiece_cn_keep_tokens.json'

# 加载分词器
tokenizer = SpTokenizer(spm_path, token_start=None, token_end='</s>')
keep_tokens = json.load(open(keep_tokens_path))

# 加载模型
t5 = build_transformer_model(
    config_path=config_path,
    checkpoint_path=checkpoint_path,
    keep_tokens=keep_tokens,
    model='t5.1.1',
    return_keras_model=False,
    name='T5',
)

encoder = t5.encoder
decoder = t5.decoder
model = t5.model
Results
Finally, you're probably wondering, after all this effort, whether generation quality actually improved, and whether it's worth using in practice. Here's the bottom line: a CSL title-generation model fine-tuned from the mT5 small version matches the BLEU score of a UniLM model based on WoBERT, while decoding 130% faster; and a CSL title-generation model fine-tuned from the mT5 base version exceeds the WoBERT-based UniLM model's metric by over 1%, while also decoding 60% faster.
$$\begin{array}{c} \text{CSL summarization results (beam size=1)}\\ {\begin{array}{c|cccc|c} \hline & \text{Rouge-L} & \text{Rouge-1} & \text{Rouge-2} & \text{BLEU} & \text{decoding speed}\\ \hline \text{BERT base} & 63.81 & 65.45 & 54.91 & 45.52 & \text{1x}\\ \text{WoBERT base} & 66.38 & 68.22 & 57.83 & 47.76 & \text{1.1x}\\ \hline \text{mT5 small} & 65.14 & 67.08 & 56.71 & 47.69 & \text{2.3x}\\ \text{mT5 base} & \textbf{66.81} & \textbf{68.94} & \textbf{58.49} & \textbf{49.49} & \text{1.6x}\\ \hline \end{array}$$}
\end{array}
In short, it really is both faster and better. As for hardware requirements: if you've been able to run BERT base, you should generally be able to run mT5 small/base, and even the large version is worth a try; as for XL and XXL, those are much harder to handle, so I'd suggest just letting those go. As for further surprises, I'll leave those for you to discover yourselves~~ Oh, and one more reminder: when fine-tuning the T5 model, the learning rate needs to be more than 10 times larger than when fine-tuning BERT (i.e., on the order of $10^{-4}$, whereas BERT is typically on the order of $10^{-5}$) — this is determined by the difference in model architecture between the two.
Summary
This post reviewed Google's T5 model released last year, then introduced the recently released multilingual mT5, and finally showed how to fine-tune mT5 in bert4keras for Chinese-language tasks. The results show that mT5 performs quite well at Chinese text generation, making it well worth trying for anyone working on text generation tasks.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.