Nyströmformer: A Linearized Attention Scheme Based on Matrix Decomposition
The $\mathcal{O}(n^2)$ complexity of standard attention is truly a headache for researchers. Some time ago, in the blog post 《Performer: Linearizing the Complexity of Attention via Random Projections》, we introduced Google's Performer model, which converts standard attention into linear attention through random projections. Coincidentally, a few days ago a paper appeared on Arxiv, 《Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention》 (AAAI 2021), which proposes another way to linearize standard attention from a different angle.
As the name suggests, this scheme is Nyström-based, meaning it uses the Nyström method to approximate standard attention. To be honest, though, before reading this paper I had never even heard of the Nyström method, and throughout the paper there are a lot of matrix decomposition derivations that, at first glance, left me rather bewildered—they were quite difficult to follow. Interestingly, though, despite the complexity of the author's derivation, I found that the final result can be understood in a considerably simpler way. So I've organized my own understanding of Nyströmformer here for readers' reference.more
A Brief Review
If readers aren't very familiar with linear attention yet, I'd suggest first reading through 《Exploring Linear Attention: Does Attention Really Need a Softmax?》 and 《Performer: Linearizing the Complexity of Attention via Random Projections》. In general, linear attention reduces the complexity of attention by exploiting the associativity of matrix multiplication.
Standard Attention
Standard scaled dot-product attention, written in matrix form, is (there's sometimes an extra scaling factor in the exponent, which we omit here for simplicity):
\begin{equation}Attention(\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V}) = softmax\left(\boldsymbol{Q}\boldsymbol{K}^{\top}\right)\boldsymbol{V}\end{equation}
Here $\boldsymbol{Q}, \boldsymbol{K}, \boldsymbol{V}\in\mathbb{R}^{n\times d}$ (corresponding to self-attention). Also, throughout this post, every softmax is normalized over the second dimension of the matrix.
In the expression above, $\boldsymbol{Q}\boldsymbol{K}^{\top}$ must be computed first before we can apply softmax, which prevents us from using the associativity of matrix multiplication. And $\boldsymbol{Q}\boldsymbol{K}^{\top}$ is the inner product of $n^2$ vectors, so both the time and space complexity are $\mathcal{O}(n^2)$.
Linear Attention
The more straightforward approach to linear attention is
\begin{equation}\left(\phi(\boldsymbol{Q})\varphi(\boldsymbol{K})^{\top}\right)\boldsymbol{V}=\phi(\boldsymbol{Q})\left(\varphi(\boldsymbol{K})^{\top}\boldsymbol{V}\right)\end{equation}
where $\phi,\varphi$ is an activation function with a non-negative range. For ease of comparison, the expression above doesn't explicitly write out the normalization factor, focusing instead on the main computational part. The complexity of the left-hand side above is still $\mathcal{O}(n^2)$; but since matrix multiplication satisfies associativity, we can compute the product of the latter two matrices first, reducing the overall complexity to $\mathcal{O}(n)$.
The expression above directly defines attention as the product of two matrices in order to exploit associativity of multiplication. Alternatively, one can (approximately) transform standard attention into a matrix product to exploit associativity, as with Performer, discussed in the next section. Furthermore, the matrices being multiplied don't necessarily have to number two—for example, in the Nyströmformer we're about to introduce, attention is expressed as the product of three matrices.
Performer
For Performer, random projections are used to find a matrix $\tilde{\boldsymbol{Q}},\tilde{\boldsymbol{K}}\in\mathbb{R}^{n\times m}$ such that the softmax term $e^{\boldsymbol{Q}\boldsymbol{K}^{\top}}\approx \tilde{\boldsymbol{Q}}\tilde{\boldsymbol{K}}^{\top}$ can be expressed accordingly, allowing standard attention to be approximated as the linear attention discussed in the previous section. For details, see the earlier post 《Performer: Linearizing the Complexity of Attention via Random Projections》.
Readers familiar with SVMs and kernel methods may recognize that this approach is essentially the idea behind kernel functions: a kernel function between two vectors in a low-dimensional space can be mapped to the inner product of two vectors in a high-dimensional space. It can also be connected to LSH (Locality Sensitive Hashing).
Nyströmformer
In this section, we start from a simple linear attention scheme based on a "double softmax" form, and gradually work toward a form that more closely approximates standard attention, eventually arriving at Nyströmformer.
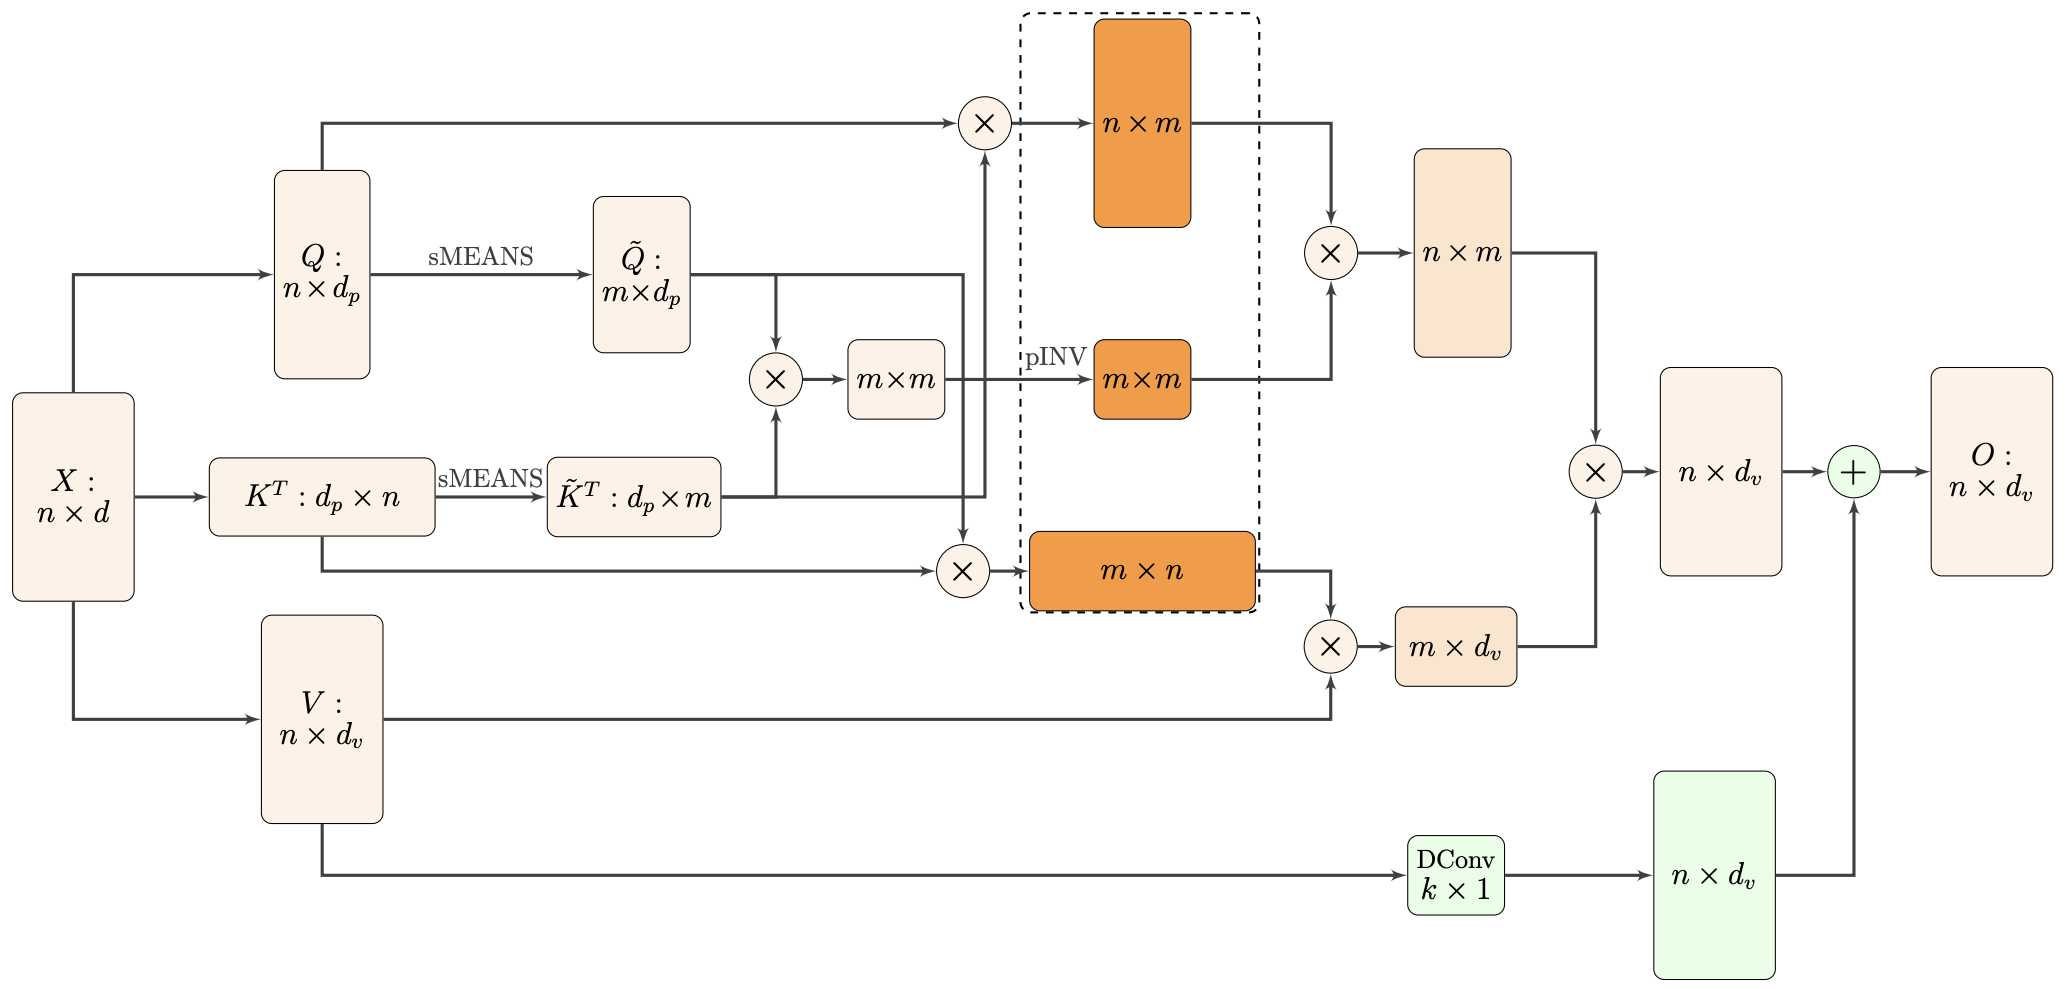 Schematic diagram of the Nyströmformer architecture. Readers may want to come back to this figure after reading through the following sections.
Double Softmax
In the post 《Exploring Linear Attention: Does Attention Really Need a Softmax?》 we mentioned a rather interesting form of linear attention that uses a double softmax to construct the attention matrix:
\begin{equation}\left(softmax(\boldsymbol{Q}) softmax\left(\boldsymbol{K}^{\top}\right)\right)\boldsymbol{V}=softmax(\boldsymbol{Q})\left(softmax\left(\boldsymbol{K}^{\top}\right)\boldsymbol{V}\right)\label{eq:2sm}\end{equation}
One can show that an attention matrix constructed this way automatically satisfies the normalization requirement—it's a simple and elegant linear attention scheme, one has to admit.
However, applying softmax directly to $\boldsymbol{Q},\boldsymbol{K}^{\top}$ feels a bit odd—there's a nagging sense that something isn't quite right about applying softmax without first computing a similarity (inner product) comparison. To address this, Nyströmformer first treats $\boldsymbol{Q},\boldsymbol{K}$ as $n$ vectors of dimension $d$, then clusters them into $m$ groups to obtain a matrix $m$ made up of $\tilde{\boldsymbol{Q}},\tilde{\boldsymbol{K}}\in\mathbb{R}^{m\times d}$ cluster centers. At this point we can define attention via the following formula:
\begin{equation}\left(softmax\left(\boldsymbol{Q}\tilde{\boldsymbol{K}} ^{\top}\right)softmax\left(\tilde{\boldsymbol{Q}}\boldsymbol{K}^{\top}\right)\right)\boldsymbol{V} = softmax\left(\boldsymbol{Q} \tilde{\boldsymbol{K}}^{\top}\right)\left(softmax\left(\tilde{\boldsymbol{Q}}\boldsymbol{K}^{\top}\right)\boldsymbol{V}\right)\label{eq:2sm2}\end{equation}
We'll discuss the specific clustering procedure later. For now, the object of the softmax is the result of an inner product, which has a fairly clear physical meaning, so this formula can be considered more reasonable than the earlier expression $\eqref{eq:2sm}$. If we choose a relatively small $m$, then the complexity of the right-hand side above only scales linearly with $n$, so this is also a form of linear attention.
Moving Closer to the Standard
Purely from the standpoint of improving on equation $\eqref{eq:2sm}$, equation $\eqref{eq:2sm2}$ has already achieved its goal. But Nyströmformer isn't satisfied with just that—it also wants the improved result to be closer to standard attention. To this end, notice that the attention matrix $softmax\left(\boldsymbol{Q}\tilde{\boldsymbol{K}}^{\top}\right)softmax\left(\tilde{\boldsymbol{Q}}\boldsymbol{K}^{\top}\right)$ in equation $\eqref{eq:2sm2}$ is the product of a $n\times m$ matrix and a $m\times n$ matrix. In order to fine-tune the result without increasing the complexity too much, we can consider inserting a $m\times m$ matrix $\boldsymbol{M}$ in between:
\begin{equation}softmax\left(\boldsymbol{Q}\tilde{\boldsymbol{K}} ^{\top}\right) \,\boldsymbol{M}\, softmax\left(\tilde{\boldsymbol{Q}}\boldsymbol{K}^{\top}\right)\end{equation}
How should we choose $\boldsymbol{M}$? A reasonable requirement is that when $m=n$, the result should be exactly equivalent to standard attention. In that case $\tilde{\boldsymbol{Q}}=\boldsymbol{Q}, \tilde{\boldsymbol{K}}=\boldsymbol{K}$, which gives
\begin{equation}\boldsymbol{M} = \left(softmax\left(\boldsymbol{Q}\boldsymbol{K}^{\top}\right)\right)^{-1} = \left(softmax\left(\tilde{\boldsymbol{Q}}\tilde{\boldsymbol{K}}^{\top}\right)\right)^{-1}\end{equation}
For general $m$, $\left(softmax\left(\tilde{\boldsymbol{Q}}\tilde{\boldsymbol{K}}^{\top}\right)\right)^{-1}$ happens to be a $m\times m$ matrix, so choosing it as $\boldsymbol{M}$ is at least reasonable from the standpoint of matrix operations. And based on the special case $m=n$, we can "boldly" conjecture that choosing it as $\boldsymbol{M}$ will bring the new attention mechanism closer to standard attention. That's why Nyströmformer ultimately chooses
\begin{equation}softmax\left(\boldsymbol{Q}\tilde{\boldsymbol{K}} ^{\top}\right) \, \left(softmax\left(\tilde{\boldsymbol{Q}}\tilde{\boldsymbol{K}}^{\top}\right)\right)^{-1} \, softmax\left(\tilde{\boldsymbol{Q}}\boldsymbol{K}^{\top}\right)\end{equation}
as the attention matrix—it is the product of three small matrices, so it can be converted into linear attention via the associativity of matrix multiplication.
There is, however, a small theoretical detail to fill in: the expression above involves the inverse of a matrix, and $softmax\left(\tilde{\boldsymbol{Q}}\tilde{\boldsymbol{K}}^{\top}\right)$ is not necessarily invertible. In practice, of course, the probability that a real-valued square matrix is not invertible is essentially zero (non-invertibility means the determinant is exactly zero, and probabilistically, being nonzero is far more likely than being exactly zero), so this case can be ignored in actual experiments. Theoretically, though, it still needs to be handled properly. Fortunately, this is simple: if the matrix isn't invertible, we just switch to the "pseudo-inverse" (denoted $^{\dagger}$), which exists for any matrix, and which equals the ordinary inverse whenever the matrix is invertible.
So, the final form of the Nyströmformer attention matrix is
\begin{equation}softmax\left(\boldsymbol{Q}\tilde{\boldsymbol{K}} ^{\top}\right) \, \left(softmax\left(\tilde{\boldsymbol{Q}}\tilde{\boldsymbol{K}}^{\top}\right)\right)^{\dagger} \, softmax\left(\tilde{\boldsymbol{Q}}\boldsymbol{K}^{\top}\right)\label{eq:2sm3}\end{equation}
Iteratively Computing the Inverse Matrix
Theoretically, equation $\eqref{eq:2sm3}$ already achieves the goal, but putting it into practice requires handling a few details—for instance, how to compute the pseudo-inverse above. The pseudo-inverse, also known as the generalized inverse or Moore-Penrose inverse, is typically computed via SVD. Let the SVD decomposition of matrix $\boldsymbol{A}$ be $\boldsymbol{U} \boldsymbol{\Lambda} \boldsymbol{V}^{\top}$; then its pseudo-inverse is
\begin{equation}\boldsymbol{A}^{\dagger} = \boldsymbol{V} \boldsymbol{\Lambda}^{\dagger} \boldsymbol{U}^{\top}\end{equation}
where the pseudo-inverse $\boldsymbol{\Lambda}^{\dagger}$ of the diagonal matrix $\boldsymbol{\Lambda}$ is the new diagonal matrix obtained by taking the reciprocal of every nonzero value along the diagonal. Although SVD is theoretically straightforward, it's computationally expensive, and gradients aren't easy to compute either, so it isn't an ideal way to implement the pseudo-inverse.
Nyströmformer adopts an approximate iterative method for computing the inverse. Specifically, it uses the iterative algorithm provided in the paper 《Chebyshev-type methods and preconditioning techniques》:
If the initial matrix $\boldsymbol{V}_0$ satisfies $\Vert \boldsymbol{I} - \boldsymbol{A} \boldsymbol{V}_0\Vert < 1$, then for the following iterative scheme
\begin{equation}\begin{aligned} > \boldsymbol{V}_{n+1} =&\,\left[\boldsymbol{I} + \frac{1}{4}\left(\boldsymbol{I} - \boldsymbol{V}_n \boldsymbol{A}\right)\left(3 \boldsymbol{I} - \boldsymbol{V}_n \boldsymbol{A}\right)^2\right] \boldsymbol{V}_n \\ > =&\,\frac{1}{4} \boldsymbol{V}_n (13 \boldsymbol{I} − \boldsymbol{A} \boldsymbol{V}_n (15 \boldsymbol{I} − \boldsymbol{A} \boldsymbol{V}_n (7 \boldsymbol{I} − \boldsymbol{A} \boldsymbol{V}_n))) > \end{aligned}\end{equation}
it holds that $\lim\limits_{n\to\infty} \boldsymbol{V}_n = \boldsymbol{A}^{\dagger}$.
Here $\Vert\cdot\Vert$ can be any matrix norm, and a relatively simple initial value satisfying the condition can be
\begin{equation}\boldsymbol{V}_0 = \frac{\boldsymbol{A}^{\top}}{\Vert\boldsymbol{A}\Vert_1 \Vert\boldsymbol{A}\Vert_{\infty}} = \frac{\boldsymbol{A}^{\top}}{\left(\max\limits_j\sum\limits_i |A_{i,j}|\right)\left(\max\limits_i\sum\limits_j |A_{i,j}|\right)}\end{equation}
In the Nyströmformer paper, the authors directly use the above initial value and iterative scheme, taking the result after 6 iterations as a substitute for $\boldsymbol{A}^{\dagger}$. Six iterations may sound like a lot, but since the $m$ chosen in the paper is fairly small (64, as stated in the paper), and the iterations only involve matrix multiplications, the computational cost of the iteration isn't too large. Moreover, since only multiplication is involved, computing gradients is easy. This resolves the problem of computing the pseudo-inverse; the paper abbreviates this iterative procedure as pINV.
Pooling as Clustering
Another problem that needs to be resolved is the choice of clustering method. The most direct idea, naturally, would be to apply K-Means directly. However, just as with the pseudo-inverse issue above, when designing a model we need to consider not only the forward computation but also backpropagation. Applying K-Means directly involves an $\mathop{\text{argmin}}$ (argmax-style) operation, which makes it impossible to obtain meaningful gradients—the operation needs to be "softened" before it can be embedded in the model. Once you go through this series of steps, it essentially becomes equivalent to the "dynamic routing" process in capsule networks, details of which we discussed in 《Yet Another New-Year Feast: From K-Means to Capsules》. The main issue with this approach is that K-Means is an iterative process requiring several iterations to guarantee good results, which noticeably increases the computational cost—not particularly desirable.
Nyströmformer opted for an extremely simple approach: assuming the sequence length $n$ is an integer multiple of $m$ (if not, pad with zero vectors), it averages every $n/m$ vectors of $\boldsymbol{Q},\boldsymbol{K}$ to obtain each vector of $\tilde{\boldsymbol{Q}}, \tilde{\boldsymbol{K}}$. This operation is called Adaptive Average Pooling (referred to in the original paper as Segment-Means, or sMEANS for short)—it's a form of average pooling where an adaptive window size ensures the pooled feature matrix has a fixed shape. Nyströmformer's experiments show that this simple adaptive pooling, without any more sophisticated clustering method, already achieves very competitive results. Moreover, it only needs $m=64$ to be roughly the same order of magnitude as the original $d$, which is much better than Performer, which needs to choose $m$ several times larger than $d$.
However, one obvious drawback of adaptive pooling is that it "blends" the information within each interval, which means it can't prevent leakage of future information—so it can't be used for autoregressive generation (language models or Seq2Seq decoders). This is basically a drawback of any model that incorporates pooling.
Experiments and Analysis
Here we summarize Nyströmformer's experimental results and share some of my own thoughts on it.
Performance and Results
Perhaps limited by computational resources, the original paper's experiments aren't especially extensive—mainly comparing small and base versions of BERT with standard attention replaced by Nyströmformer. The main results are shown in the two figures below. One is the pretraining results, where interestingly Nyströmformer performs even better than standard attention on the MLM task. The other shows fine-tuning results on downstream tasks, demonstrating competitiveness compared with standard attention (i.e., BERT).
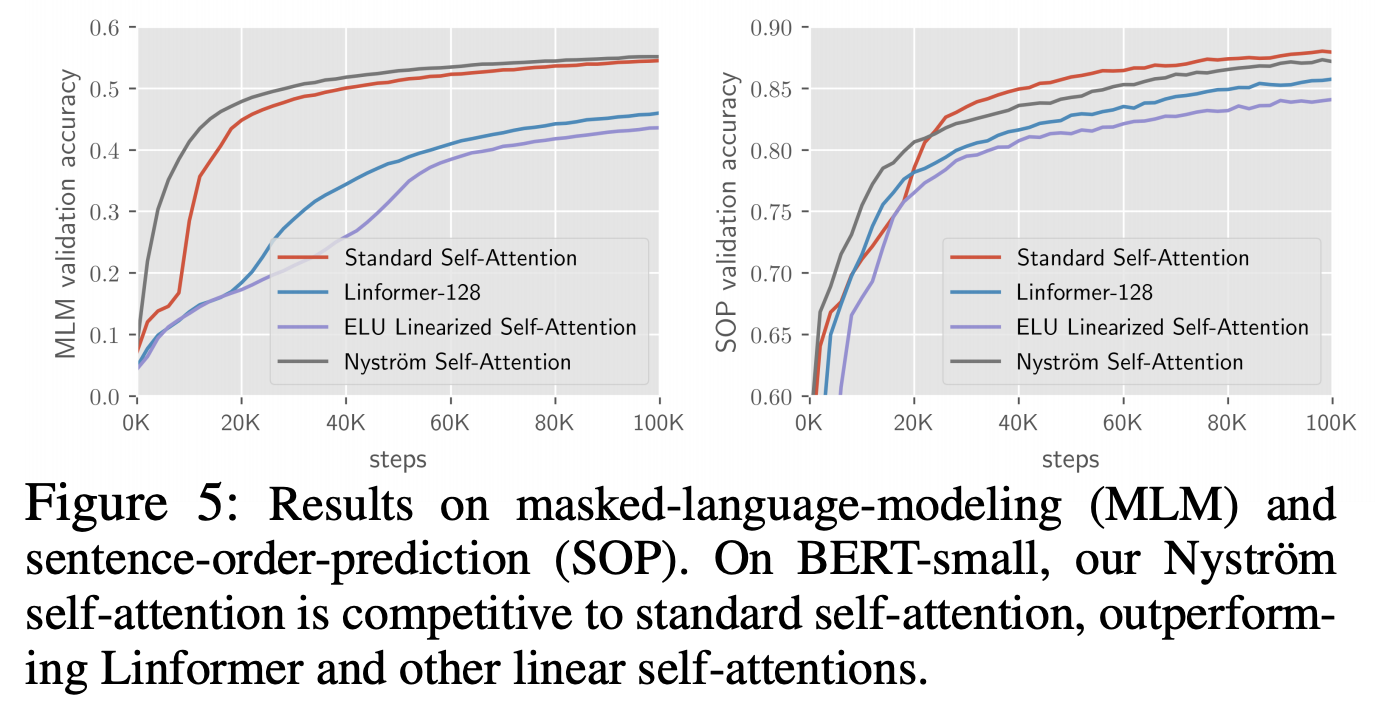 Nyströmformer's performance on pretraining tasks (MLM and SOP)
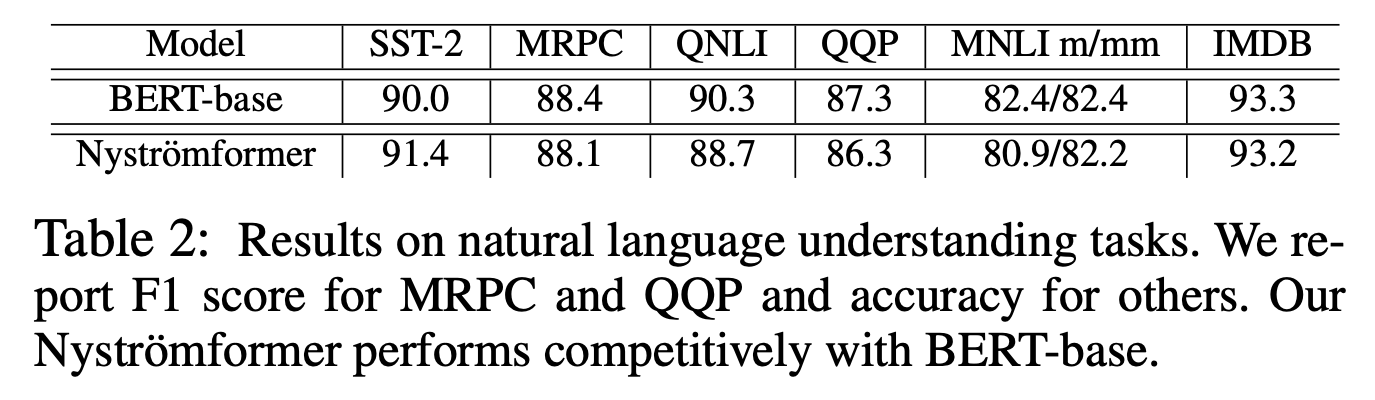 Nyströmformer's fine-tuning results on downstream tasks
However, the original paper does not compare Nyströmformer's performance against similar models, only providing the complexity comparison chart below, so it's hard to fully appreciate Nyströmformer's competitiveness from the paper alone:
 Comparison chart of time and space complexity across different models
My Own Thoughts
Overall, Nyströmformer's approach to approximately linearizing standard attention is a fairly novel idea, well worth studying and referencing. That said, the handling of the pseudo-inverse feels somewhat unnatural to me—this could be a point for future improvement. If one could avoid the approximation altogether, that would be ideal. Also, quantitatively estimating the error between Nyströmformer and standard attention is a theoretical question worth thinking further about.
Experimentally, Nyströmformer does appear competitive compared with standard attention, especially given that its MLM results are even better than standard attention's, which shows its potential. As mentioned earlier, though, the inclusion of pooling—which prevents autoregressive generation—is a notable drawback of Nyströmformer. I don't know whether there's a way to remedy this; at least, I haven't come up with a good direction yet.
Compared with Performer, Nyströmformer removes the randomness involved in the linearization process. Since Performer achieves linearization through random projections, it inevitably introduces randomness, which some readers with a strong preference for determinism might find hard to accept. Nyströmformer has no such randomness, which is also worth noting as a strength.
The Nyström Method
Some readers might want to learn a bit more about the Nyström method, so let me add a brief supplement here. To understand the Nyström method, we first need a basic understanding of the CUR decomposition of matrices.
Most people have probably heard of the SVD decomposition of a matrix, written as $\boldsymbol{A}=\boldsymbol{U} \boldsymbol{\Lambda} \boldsymbol{V}^{\top}$, where $\boldsymbol{U},\boldsymbol{V}$ are orthogonal matrices and $\boldsymbol{\Lambda}$ is a diagonal matrix. Note that being orthogonal matrices means $\boldsymbol{U},\boldsymbol{V}$ are dense, so when $\boldsymbol{A}$ is large, the computational and storage cost of SVD is high (even with approximation). Now suppose $\boldsymbol{A}$ is large but sparse—in that case, its SVD decomposition is far less economical than the original matrix itself. This is where the CUR decomposition comes in: it selects $k$ columns from the original matrix to form matrix $\boldsymbol{C}$, selects $k$ rows to form matrix $\boldsymbol{R}$, and inserts a $k\times k$ matrix $\boldsymbol{U}$, such that
\begin{equation}\boldsymbol{A} \approx \boldsymbol{C}\boldsymbol{U}\boldsymbol{R}\end{equation}
Since $\boldsymbol{C},\boldsymbol{R}$ are all pieces of the original matrix, they inherit its sparsity. For more on the CUR decomposition, readers can consult the 《Dimensionality Reduction》 section of Stanford's CS246 course. Unlike SVD, the CUR decomposition, in my view, is more of a decomposition philosophy than a single concrete algorithm—it has various implementations, one of which is the Nyström method, whose decomposition form is
\begin{equation}\begin{pmatrix}\boldsymbol{A} & \boldsymbol{B} \\ \boldsymbol{C} & \boldsymbol{D}\end{pmatrix} \approx \begin{pmatrix}\boldsymbol{A} & \boldsymbol{B} \\ \boldsymbol{C} & \boldsymbol{C}\boldsymbol{A}^{\dagger}\boldsymbol{B}\end{pmatrix} = \begin{pmatrix}\boldsymbol{A} \\ \boldsymbol{C}\end{pmatrix} \boldsymbol{A}^{\dagger} \begin{pmatrix}\boldsymbol{A} & \boldsymbol{B}\end{pmatrix}\end{equation}
where $\begin{pmatrix}\boldsymbol{A} \\ \boldsymbol{C}\end{pmatrix}$ and $\begin{pmatrix}\boldsymbol{A} & \boldsymbol{B}\end{pmatrix}$ are the selected column and row matrices. For convenience of description, here we assume that after permutation, the selected rows and columns are arranged at the front of the matrix. Nyströmformer, in fact, doesn't directly apply the Nyström method (indeed, it can't be applied directly, as the original paper explains), but rather borrows the decomposition idea underlying the Nyström method.
Regarding the Nyström method, the original paper primarily cites 《Improving CUR Matrix Decomposition and the Nyström Approximation via Adaptive Sampling》, but I wouldn't recommend this paper for beginners; I'd instead recommend 《Matrix Compression using the Nyström Method》 and 《Using the Nyström Method to Speed Up Kernel Machines》.
I should stress that I myself only recently learned about the CUR decomposition and Nyström method, so there may be inaccuracies in my understanding. Readers should judge for themselves, and those familiar with the relevant theory are welcome to discuss and correct me.
A Brief Summary
This post introduced Nyströmformer, a new piece of work aimed at improving Transformer efficiency. It draws on the ideas of the Nyström method to construct a linear attention mechanism that approximates standard attention. Performer represents similar work along the same lines; the two approaches each have their own pros and cons, and both are worth studying. This post shared my own understanding of Nyströmformer, which I personally believe offers an easier path to comprehension. If there are any errors, I'd be grateful for readers' corrections.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.