Transformer Upgrade Path: 2. Rotary Position Embedding That Draws on the Best of Both Worlds
In the previous post, we gave a fairly detailed derivation and discussion of the original Sinusoidal positional encoding, and the overall impression was that Sinusoidal positional encoding is "an absolute position encoding that wants to be a relative position encoding." Generally speaking, absolute position encodings have the advantages of being simple to implement and fast to compute, while relative position encodings directly capture relative position signals, matching our intuition, and often achieve better performance in practice. It follows that if we could implement relative position encoding through an absolute position encoding scheme, we'd be getting "the best of both worlds" — having our cake and eating it too. Sinusoidal position encoding hints at this, but not well enough.
This post introduces our self-developed Rotary Transformer (RoFormer) model. Its main innovation is the application of what I designed as "Rotary Position Embedding (RoPE)" — a design that, in conjunction with the attention mechanism, achieves "implementing relative position encoding via absolute position encoding." Precisely because of this design, it is also currently the only relative position encoding that can be used with linear attention.
RoFormer: https://github.com/ZhuiyiTechnology/roformer
Basic idea
In an earlier post, Transformer Position Encoding That Racked Researchers' Brains, we already briefly introduced RoPE, calling it the "fusion approach" at the time. This post gives a more detailed account of where it comes from and what properties it has. In RoPE, our starting point is "implementing relative position encoding through absolute position encoding," which has both theoretical elegance and practical usefulness — for example, the fact that it can be extended to linear attention is mainly due to this property.
To achieve this goal, we suppose that absolute position information is added to $\boldsymbol{q},\boldsymbol{k}$ through the following operation:
\begin{equation}\tilde{\boldsymbol{q}}_m = \boldsymbol{f}(\boldsymbol{q}, m), \quad\tilde{\boldsymbol{k}}_n = \boldsymbol{f}(\boldsymbol{k}, n)\end{equation}
That is to say, we design an operation $\boldsymbol{f}(\cdot, m),\boldsymbol{f}(\cdot, n)$ separately for $\boldsymbol{q},\boldsymbol{k}$, such that after this operation, $\tilde{\boldsymbol{q}}_m,\tilde{\boldsymbol{k}}_n$ carries the absolute position information of position $m,n$. Since the core operation of attention is the inner product, we would like the result of the inner product to carry relative position information, so we assume the existence of the identity:
\begin{equation}\langle\boldsymbol{f}(\boldsymbol{q}, m), \boldsymbol{f}(\boldsymbol{k}, n)\rangle = g(\boldsymbol{q},\boldsymbol{k},m-n)\end{equation}
So we need to find a (as simple as possible) solution to this identity. Solving it also requires some initial conditions; clearly we can reasonably set $\boldsymbol{f}(\boldsymbol{q}, 0)=\boldsymbol{q}$ and $\boldsymbol{f}(\boldsymbol{k}, 0)=\boldsymbol{k}$.
Derivation
Following the same approach as in the previous post, let's first consider the two-dimensional case and solve it with the help of complex numbers. In complex numbers, we have $\langle\boldsymbol{q},\boldsymbol{k}\rangle=\text{Re}[\boldsymbol{q}\boldsymbol{k}^*]$, where $\text{Re}[]$ denotes the real part of the complex number, so we have
\begin{equation}\text{Re}[\boldsymbol{f}(\boldsymbol{q}, m)\boldsymbol{f}^*(\boldsymbol{k}, n)] = g(\boldsymbol{q},\boldsymbol{k},m-n)\end{equation}
For simplicity, we assume there exists a complex number $\boldsymbol{g}(\boldsymbol{q},\boldsymbol{k},m-n)$ such that $\boldsymbol{f}(\boldsymbol{q}, m)\boldsymbol{f}^*(\boldsymbol{k}, n) = \boldsymbol{g}(\boldsymbol{q},\boldsymbol{k},m-n)$, and then, using the exponential form of complex numbers, we set
\begin{equation}\begin{aligned} \boldsymbol{f}(\boldsymbol{q}, m) =&\, R_f (\boldsymbol{q}, m)e^{\text{i}\Theta_f(\boldsymbol{q}, m)} \\ \boldsymbol{f}(\boldsymbol{k}, n) =&\, R_f (\boldsymbol{k}, n)e^{\text{i}\Theta_f(\boldsymbol{k}, n)} \\ \boldsymbol{g}(\boldsymbol{q}, \boldsymbol{k}, m-n) =&\, R_g (\boldsymbol{q}, \boldsymbol{k}, m-n)e^{\text{i}\Theta_g(\boldsymbol{q}, \boldsymbol{k}, m-n)} \\ \end{aligned}\end{equation}
Substituting into the equation gives us the system of equations
\begin{equation}\begin{aligned} R_f (\boldsymbol{q}, m) R_f (\boldsymbol{k}, n) =&\, R_g (\boldsymbol{q}, \boldsymbol{k}, m-n) \\ \Theta_f (\boldsymbol{q}, m) - \Theta_f (\boldsymbol{k}, n) =&\, \Theta_g (\boldsymbol{q}, \boldsymbol{k}, m-n) \end{aligned}\end{equation}
For the first equation, substituting $m=n$ gives
\begin{equation}R_f (\boldsymbol{q}, m) R_f (\boldsymbol{k}, m) = R_g (\boldsymbol{q}, \boldsymbol{k}, 0) = R_f (\boldsymbol{q}, 0) R_f (\boldsymbol{k}, 0) = \Vert \boldsymbol{q}\Vert \Vert \boldsymbol{k}\Vert\end{equation}
The last equality follows from the initial conditions $\boldsymbol{f}(\boldsymbol{q}, 0)=\boldsymbol{q}$ and $\boldsymbol{f}(\boldsymbol{k}, 0)=\boldsymbol{k}$. So now we can simply set $R_f (\boldsymbol{q}, m)=\Vert \boldsymbol{q}\Vert, R_f (\boldsymbol{k}, m)=\Vert \boldsymbol{k}\Vert$, i.e., it does not depend on $m$. As for the second equation, again substituting $m=n$ gives
\begin{equation}\Theta_f (\boldsymbol{q}, m) - \Theta_f (\boldsymbol{k}, m) = \Theta_g (\boldsymbol{q}, \boldsymbol{k}, 0) = \Theta_f (\boldsymbol{q}, 0) - \Theta_f (\boldsymbol{k}, 0) = \Theta (\boldsymbol{q}) - \Theta (\boldsymbol{k})\end{equation}
Here $\Theta (\boldsymbol{q}),\Theta (\boldsymbol{k})$ is the argument of $\boldsymbol{q},\boldsymbol{k}$ itself, and the last equality also follows from the initial conditions. From the above equation we get $\Theta_f (\boldsymbol{q}, m) - \Theta (\boldsymbol{q}) = \Theta_f (\boldsymbol{k}, m) - \Theta (\boldsymbol{k})$, so $\Theta_f (\boldsymbol{q}, m) - \Theta (\boldsymbol{q})$ should be a function that depends only on $m$ and not on $\boldsymbol{q}$; denote it as $\varphi(m)$, i.e., $\Theta_f (\boldsymbol{q}, m) = \Theta (\boldsymbol{q}) + \varphi(m)$. Substituting $n=m-1$ and rearranging, we get
\begin{equation}\varphi(m) - \varphi(m-1) = \Theta_g (\boldsymbol{q}, \boldsymbol{k}, 1) + \Theta (\boldsymbol{k}) - \Theta (\boldsymbol{q})\end{equation}
That is, $\{\varphi(m)\}$ forms an arithmetic sequence. Letting the right-hand side be $\theta$, we solve to get $\varphi(m)=m\theta$.
Encoding form
Putting it all together, we obtain the two-dimensional RoPE expressed in complex numbers:
\begin{equation} \boldsymbol{f}(\boldsymbol{q}, m) = R_f (\boldsymbol{q}, m)e^{\text{i}\Theta_f(\boldsymbol{q}, m)} = \Vert q\Vert e^{\text{i}(\Theta(\boldsymbol{q}) + m\theta)} = \boldsymbol{q} e^{\text{i}m\theta}\end{equation}
Based on the geometric meaning of complex multiplication, this transformation actually corresponds to a rotation of the vector, which is why we call it "Rotary Position Embedding." It can also be written in matrix form:
\begin{equation} \boldsymbol{f}(\boldsymbol{q}, m) =\begin{pmatrix}\cos m\theta & -\sin m\theta\\ \sin m\theta & \cos m\theta\end{pmatrix} \begin{pmatrix}q_0 \\ q_1\end{pmatrix}\end{equation}
Since the inner product satisfies linear superposition, RoPE in any even dimension can be expressed as a concatenation of the two-dimensional case, i.e.,
\begin{equation}\scriptsize{\underbrace{\begin{pmatrix} \cos m\theta_0 & -\sin m\theta_0 & 0 & 0 & \cdots & 0 & 0 \\ \sin m\theta_0 & \cos m\theta_0 & 0 & 0 & \cdots & 0 & 0 \\ 0 & 0 & \cos m\theta_1 & -\sin m\theta_1 & \cdots & 0 & 0 \\ 0 & 0 & \sin m\theta_1 & \cos m\theta_1 & \cdots & 0 & 0 \\ \vdots & \vdots & \vdots & \vdots & \ddots & \vdots & \vdots \\ 0 & 0 & 0 & 0 & \cdots & \cos m\theta_{d/2-1} & -\sin m\theta_{d/2-1} \\ 0 & 0 & 0 & 0 & \cdots & \sin m\theta_{d/2-1} & \cos m\theta_{d/2-1} \\ \end{pmatrix}}_{\boldsymbol{\mathcal{R}}_m} \begin{pmatrix}q_0 \\ q_1 \\ q_2 \\ q_3 \\ \vdots \\ q_{d-2} \\ q_{d-1}\end{pmatrix}}\end{equation}
That is, we multiply the vector $\boldsymbol{q}$ at position $m$ by the matrix $\boldsymbol{\mathcal{R}}_m$, and multiply the vector $\boldsymbol{k}$ at position $n$ by the matrix $\boldsymbol{\mathcal{R}}_n$, and then compute attention using the transformed sequences $\boldsymbol{Q},\boldsymbol{K}$. Attention then automatically incorporates relative position information, because the following identity holds:
\begin{equation}(\boldsymbol{\mathcal{R}}_m \boldsymbol{q})^{\top}(\boldsymbol{\mathcal{R}}_n \boldsymbol{k}) = \boldsymbol{q}^{\top} \boldsymbol{\mathcal{R}}_m^{\top}\boldsymbol{\mathcal{R}}_n \boldsymbol{k} = \boldsymbol{q}^{\top} \boldsymbol{\mathcal{R}}_{n-m} \boldsymbol{k}\end{equation}
It's worth pointing out that $\boldsymbol{\mathcal{R}}_m$ is an orthogonal matrix, so it does not change the norm of the vector, and therefore generally does not affect the stability of the original model.
Due to the sparsity of $\boldsymbol{\mathcal{R}}_m$, directly implementing it via matrix multiplication would be a waste of compute. We recommend implementing RoPE in the following way instead:
\begin{equation}\begin{pmatrix}q_0 \\ q_1 \\ q_2 \\ q_3 \\ \vdots \\ q_{d-2} \\ q_{d-1} \end{pmatrix}\otimes\begin{pmatrix}\cos m\theta_0 \\ \cos m\theta_0 \\ \cos m\theta_1 \\ \cos m\theta_1 \\ \vdots \\ \cos m\theta_{d/2-1} \\ \cos m\theta_{d/2-1} \end{pmatrix} + \begin{pmatrix}-q_1 \\ q_0 \\ -q_3 \\ q_2 \\ \vdots \\ -q_{d-1} \\ q_{d-2} \end{pmatrix}\otimes\begin{pmatrix}\sin m\theta_0 \\ \sin m\theta_0 \\ \sin m\theta_1 \\ \sin m\theta_1 \\ \vdots \\ \sin m\theta_{d/2-1} \\ \sin m\theta_{d/2-1} \end{pmatrix}\end{equation}
where $\otimes$ denotes element-wise multiplication, i.e., the $*$ operation in computation frameworks like Numpy and Tensorflow. From this implementation, we can also see that RoPE can be viewed as a variant of multiplicative position encoding.
Long-range decay
We can see that RoPE resembles Sinusoidal position encoding in form, except Sinusoidal is additive while RoPE can be viewed as multiplicative. For the choice of $\theta_i$, we likewise follow the scheme used for Sinusoidal position encoding, i.e., $\theta_i = 10000^{-2i/d}$, which brings a certain degree of long-range decay.
Here's a concrete proof: after pairing up the components of $\boldsymbol{q},\boldsymbol{k}$ two by two, their inner product after adding RoPE can be expressed via complex multiplication as
\begin{equation} (\boldsymbol{\mathcal{R}}_m \boldsymbol{q})^{\top}(\boldsymbol{\mathcal{R}}_n \boldsymbol{k}) = \text{Re}\left[\sum_{i=0}^{d/2-1}\boldsymbol{q}_{[2i:2i+1]}\boldsymbol{k}_{[2i:2i+1]}^* e^{\text{i}(m-n)\theta_i}\right]\end{equation}
Denote $h_i = \boldsymbol{q}_{[2i:2i+1]}\boldsymbol{k}_{[2i:2i+1]}^*, S_j = \sum\limits_{i=0}^{j-1} e^{\text{i}(m-n)\theta_i}$, and let $h_{d/2}=0,S_0=0$ by convention. Then, by the Abel transform (summation by parts), we obtain:
\begin{equation}\sum_{i=0}^{d/2-1}\boldsymbol{q}_{[2i:2i+1]}\boldsymbol{k}_{[2i:2i+1]}^* e^{\text{i}(m-n)\theta_i} = \sum_{i=0}^{d/2-1} h_i (S_{i +1} - S_i) = -\sum_{i=0}^{d/2-1} S_{i+1}(h_{i+1} - h_i)\end{equation}
so
\begin{equation}\begin{aligned} \left|\sum_{i=0}^{d/2-1}\boldsymbol{q}_{[2i:2i+1]}\boldsymbol{k}_{[2i:2i+1]}^* e^{\text{i}(m-n)\theta_i}\right| =&\, \left|\sum_{i=0}^{d/2-1} S_{i+1}(h_{i+1} - h_i)\right| \\ \leq&\, \sum_{i=0}^{d/2-1} |S_{i+1}| |h_{i+1} - h_i| \\ \leq&\, \left(\max_i |h_{i+1} - h_i|\right)\sum_{i=0}^{d/2-1} |S_{i+1}| \end{aligned}\end{equation}
We can therefore examine how $\frac{1}{d/2}\sum\limits_{i=1}^{d/2} |S_i|$ changes with relative distance as a manifestation of the decay property. The Mathematica code is as follows:
d = 128;
\[Theta][t_] = 10000^(-2*t/d);
f[m_] = Sum[
    Norm[Sum[Exp[I*m*\[Theta][i]], {i, 0, j}]], {j, 0, d/2 - 1}]/(d/2);
Plot[f[m], {m, 0, 256}, AxesLabel -> {相对距离, 相对大小}]
The results are shown in the figure below:
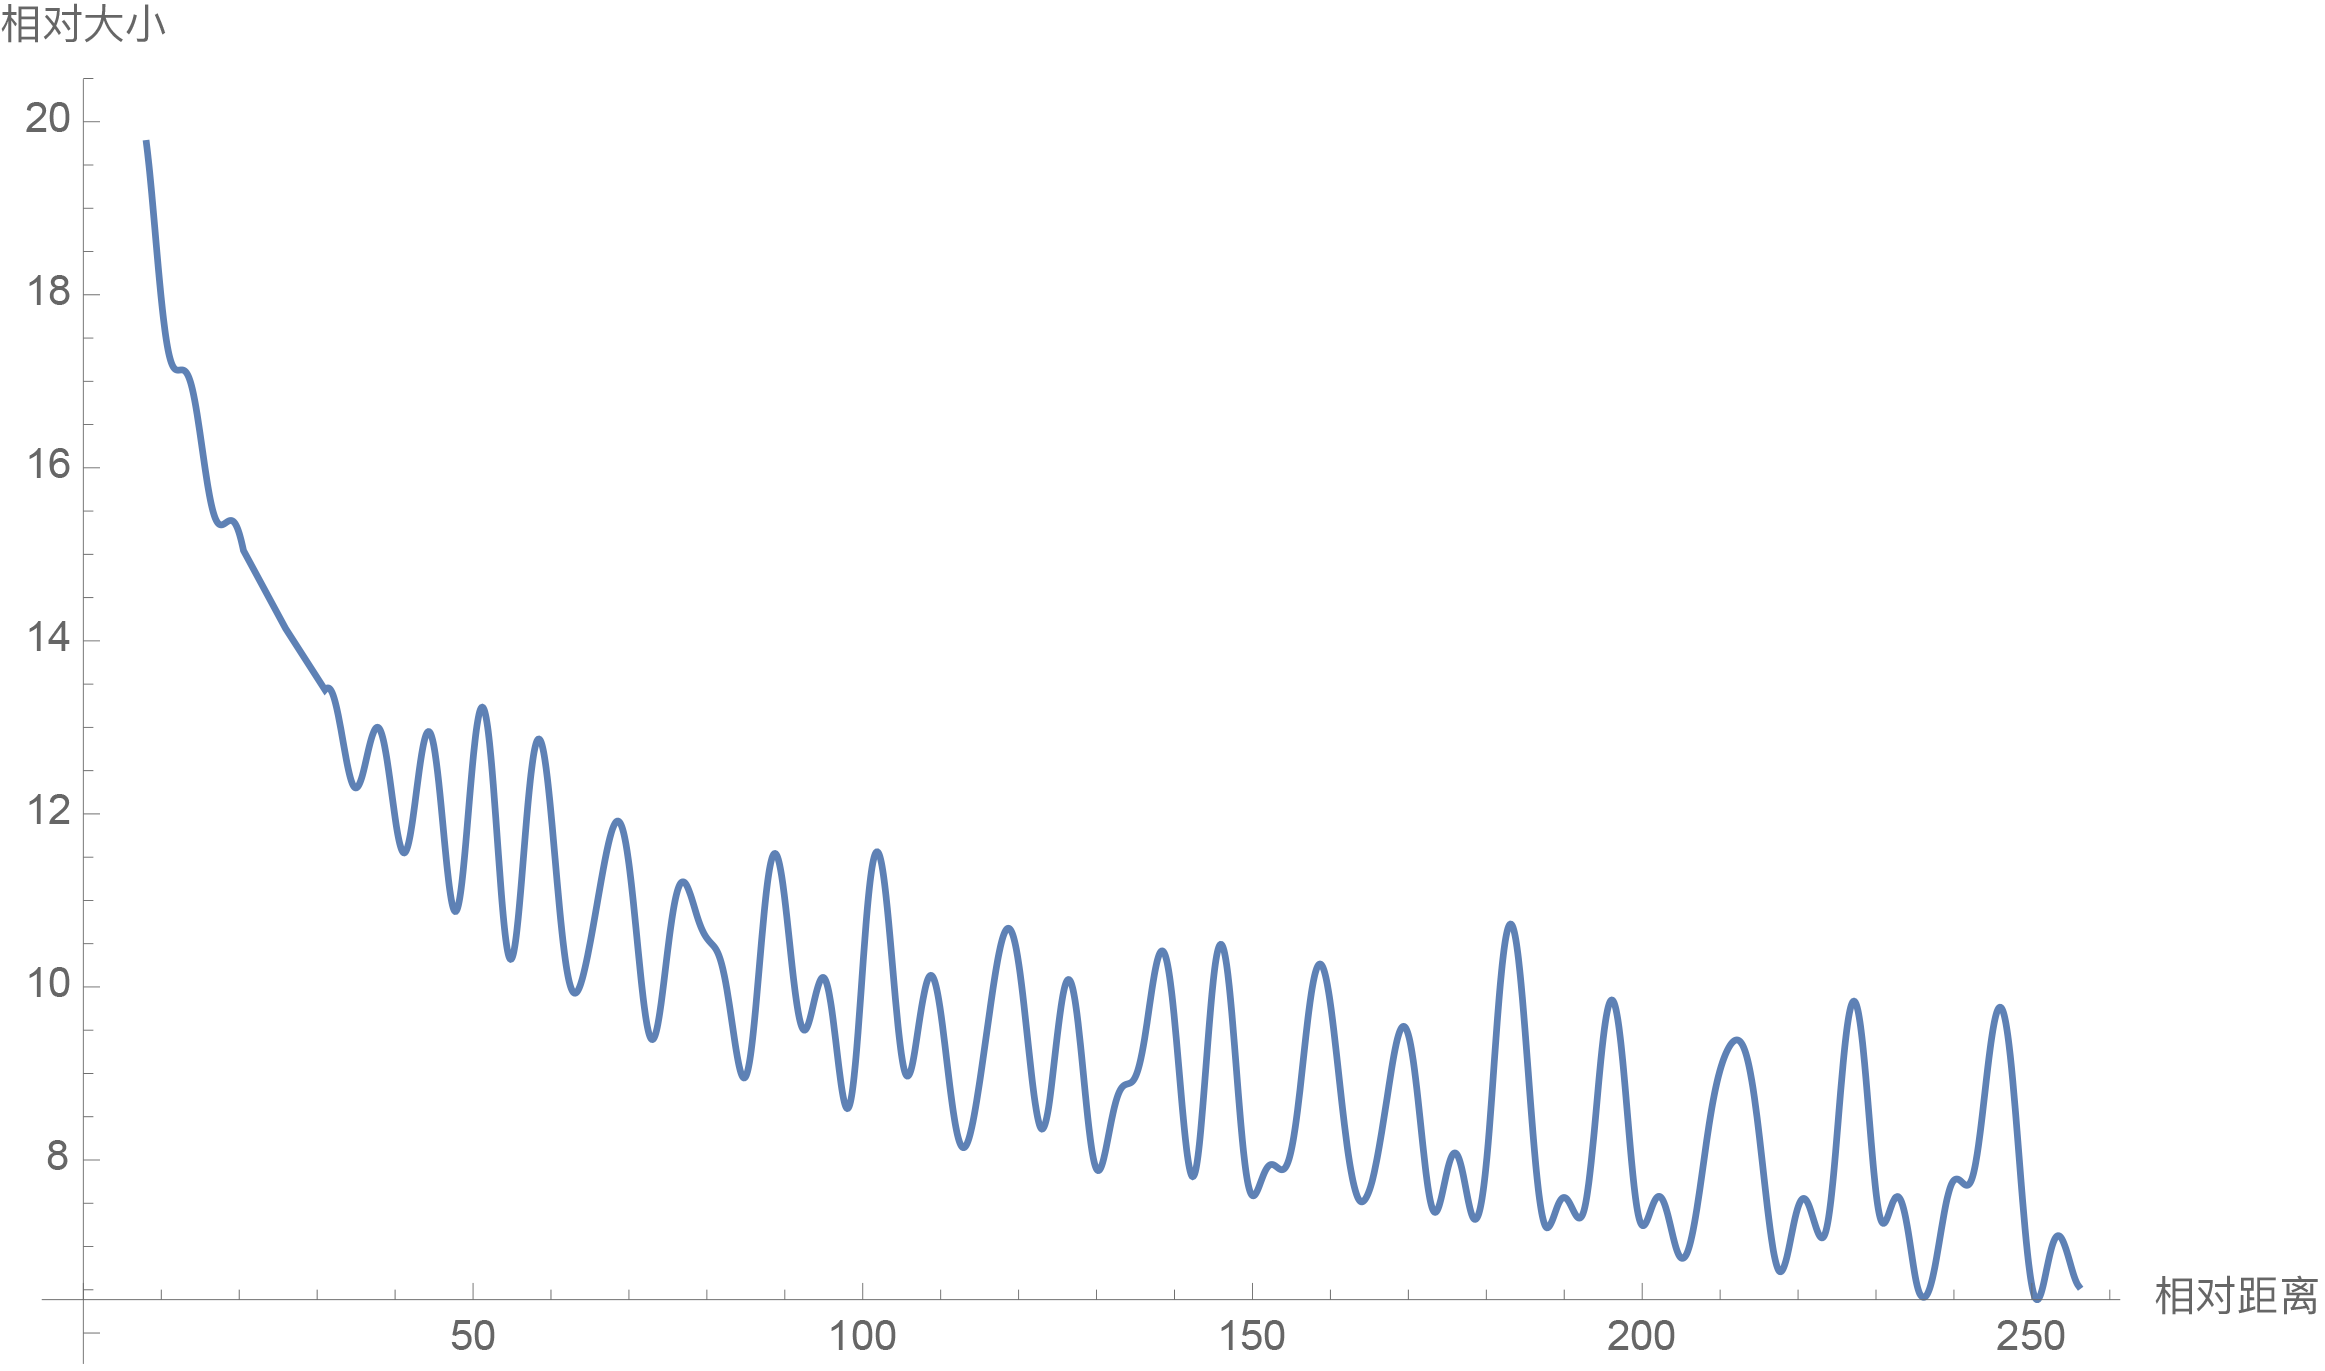 RoPE's long-range decay property (d=128)
From the figure we can see that as the relative distance grows, the inner product does show a decaying trend. So choosing $\theta_i = 10000^{-2i/d}$ does indeed bring some degree of long-range decay. Of course, as noted in the previous post, this choice is not the only one that can bring about long-range decay — almost any smooth, monotonic function would work; we're simply reusing the existing choice here. I also tried initializing with $\theta_i = 10000^{-2i/d}$ and treating $\theta_i$ as a trainable parameter. After training for a while, I found that $\theta_i$ did not update significantly, so I just fixed $\theta_i = 10000^{-2i/d}$ outright.
Linear-attention scenario
Finally, we point out that RoPE is currently the only relative position encoding that can be used with linear attention. This is because other relative position encoding schemes operate directly on the attention matrix, but linear attention never explicitly computes an attention matrix in the first place, so there's no attention matrix to operate on — meaning other schemes simply cannot be applied to linear attention. As for RoPE, since it implements relative position encoding via absolute position encoding without needing to operate on the attention matrix, it has the potential to be applied to linear attention.
We won't repeat the introduction to linear attention here; interested readers can refer to Exploring Linear Attention: Does Attention Need a Softmax?. The common form of linear attention is:
\begin{equation}Attention(\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V})_i = \frac{\sum\limits_{j=1}^n \text{sim}(\boldsymbol{q}_i, \boldsymbol{k}_j)\boldsymbol{v}_j}{\sum\limits_{j=1}^n \text{sim}(\boldsymbol{q}_i, \boldsymbol{k}_j)} = \frac{\sum\limits_{j=1}^n \phi(\boldsymbol{q}_i)^{\top} \varphi(\boldsymbol{k}_j)\boldsymbol{v}_j}{\sum\limits_{j=1}^n \phi(\boldsymbol{q}_i)^{\top} \varphi(\boldsymbol{k}_j)}\end{equation}
where $\phi,\varphi$ is an activation function with non-negative range. Since linear attention is also based on inner products, a natural idea is to insert RoPE into the inner product:
\begin{equation}\frac{\sum\limits_{j=1}^n [\boldsymbol{\mathcal{R}}_i\phi(\boldsymbol{q}_i)]^{\top} [\boldsymbol{\mathcal{R}}_j\varphi(\boldsymbol{k}_j)]\boldsymbol{v}_j}{\sum\limits_{j=1}^n [\boldsymbol{\mathcal{R}}_i\phi(\boldsymbol{q}_i)]^{\top} [\boldsymbol{\mathcal{R}}_j\varphi(\boldsymbol{k}_j)]}\end{equation}
The problem here, though, is that the inner product $[\boldsymbol{\mathcal{R}}_i\phi(\boldsymbol{q}_i)]^{\top} [\boldsymbol{\mathcal{R}}_j\varphi(\boldsymbol{k}_j)]$ can be negative, so this is no longer conventional probabilistic attention, and the denominator risks being zero, which could cause instability in optimization. Considering that $\boldsymbol{\mathcal{R}}_i,\boldsymbol{\mathcal{R}}_j$ are orthogonal matrices that don't change vector norms, we can abandon the conventional requirement of probabilistic normalization and instead use the following operation as a new form of linear attention:
\begin{equation}\frac{\sum\limits_{j=1}^n [\boldsymbol{\mathcal{R}}_i\phi(\boldsymbol{q}_i)]^{\top} [\boldsymbol{\mathcal{R}}_j\varphi(\boldsymbol{k}_j)]\boldsymbol{v}_j}{\sum\limits_{j=1}^n \phi(\boldsymbol{q}_i)^{\top} \varphi(\boldsymbol{k}_j)}\end{equation}
That is, RoPE is only inserted into the numerator, while the denominator is left unchanged. This form of attention is no longer probability-based (the attention matrix no longer satisfies non-negative normalization), but in some sense it is still a normalization scheme, and there's no evidence that non-probabilistic attention is necessarily worse (for example, Nyströmformer also constructs attention in a way that doesn't strictly follow a probability distribution). So we're treating this as one of our candidate schemes for experimentation, and our preliminary results show that this form of linear attention is also effective.
Additionally, in Exploring Linear Attention: Does Attention Need a Softmax? I proposed another linear attention scheme: $\text{sim}(\boldsymbol{q}_i, \boldsymbol{k}_j) = 1 + \left( \frac{\boldsymbol{q}_i}{\Vert \boldsymbol{q}_i\Vert}\right)^{\top}\left(\frac{\boldsymbol{k}_j}{\Vert \boldsymbol{k}_j\Vert}\right)$, which doesn't rely on non-negativity of the range. Since RoPE also doesn't change vector norms, RoPE can be directly applied to this type of linear attention without altering its probabilistic interpretation.
Open-sourced model
We have finished training the first version of the RoFormer model and have open-sourced it on Github:
RoFormer: https://github.com/ZhuiyiTechnology/roformer
Simply put, RoFormer is a WoBERT model with its absolute position encoding replaced by RoPE. Here's how its architecture compares with other models:
$$\begin{array}{c|cccc} \hline & \text{BERT} & \text{WoBERT} & \text{NEZHA} & \text{RoFormer} \\ \hline \text{token unit} & \text{word} & \text{token} & \text{word} & \text{token} & \\ \text{positional encoding} & \text{absolute position} & \text{absolute position} & \text{classic relative position} & \text{RoPE}\\ \hline \end{array}$$
For pretraining, we started from WoBERT Plus and used a scheme of alternating between multiple sequence lengths and batch sizes during training, so the model can get accustomed to different training scenarios ahead of time:
$$\begin{array}{c|ccccc} \hline & \text{maxlen} & \text{batch size} & \text{training steps} & \text{final loss} & \text{final acc}\\ \hline 1 & 512 & 256 & 20\text{ten thousand} & 1.73 & 65.0\%\\ 2 & 1536 & 256 & 1.25\text{ten thousand} & 1.61 & 66.8\%\\ 3 & 256 & 256 & 12\text{ten thousand} & 1.75 & 64.6\%\\ 4 & 128 & 512 & 8\text{ten thousand} & 1.83 & 63.4\%\\ 5 & 1536 & 256 & 1\text{ten thousand} & 1.58 & 67.4\%\\ 6 & 512 & 512 & 3\text{ten thousand} & 1.66 & 66.2\%\\ \hline \end{array}$$
The table also shows that increasing the sequence length actually improves pretraining accuracy, which indirectly reflects how well RoFormer handles long-text semantics, and also demonstrates RoPE's good length-extrapolation ability. On short-text tasks, RoFormer performs similarly to WoBERT; RoFormer's main advantage is that it can directly handle text of arbitrary length. Below are our experimental results on the CAIL2019-SCM task:
$$\begin{array}{c|cc} \hline & \text{val set} & \text{test set} \\ \hline \text{BERT-512} & 64.13\% & 67.77\% \\ \text{WoBERT-512} & 64.07\% & 68.10\% \\ \text{RoFormer-512} & 64.13\% & 68.29\% \\ \text{RoFormer-1024} & \textbf{66.07%} & \textbf{69.79%} \\ \hline \end{array}$$
Here the parameter following $\text{-}$ is the maxlen truncation used during fine-tuning. As we can see, RoFormer indeed handles long-text semantics fairly well. As for hardware requirements, on a card with 24GB of GPU memory, we can run maxlen=1024 with a batch size of 8 or more. Currently, this is the only task I've found in Chinese that's well-suited for testing long-text capability, so it's the only one we tested for long-text performance — readers are welcome to test it themselves or recommend other benchmark tasks.
Of course, although in theory RoFormer can handle sequences of arbitrary length, it currently still has quadratic complexity. We are also training a RoFormer model based on linear attention, and we'll open-source it once the experiments are complete — stay tuned.
(Note: RoPE and RoFormer have been written up as the paper RoFormer: Enhanced Transformer with Rotary Position Embedding and submitted to Arxiv. Feel free to use and cite it, ha ha~)
Summary
This post introduced our self-developed Rotary Position Embedding (RoPE) and the corresponding pretrained model RoFormer. Theoretically, RoPE has some things in common with Sinusoidal position encoding, but RoPE doesn't rely on Taylor expansion, making it more rigorous and interpretable. Based on the results from the pretrained RoFormer model, RoPE exhibits good length-extrapolation properties, and when applied within Transformers it shows strong capability for handling long text. In addition, RoPE remains, at present, the only relative position encoding that can be used with linear attention.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.