For the Sake of Efficiency: From Standard Attention to Sparse Attention
 attention, please!
Nowadays Attention dominates the NLP field, and not just NLP — in the CV field, Attention also has its place (Non Local, SAGAN, etc.). Back in early 2018, in A Brief Reading of "Attention is All You Need" (Introduction + Code), we already discussed the Attention mechanism. The core of Attention lies in the interaction and fusion of three vector sequences, $\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V}$: the interaction between $\boldsymbol{Q},\boldsymbol{K}$ gives some kind of correlation (weight) between pairs of vectors, and the final output sequence is obtained by summing $\boldsymbol{V}$ weighted by those correlations.
Clearly, a wealth of NLP and CV results has already thoroughly confirmed the effectiveness of Attention. In this post we introduce several variants of Attention that share a common trait — they are "born for efficiency," saving both time and GPU memory.
Background
The Attention discussed in Attention is All You Need is what we call "multiplicative attention," and this is by far the most widely used form today:
\begin{equation}Attention(\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V}) = softmax\left(\frac{\boldsymbol{Q}\boldsymbol{K}^{\top}}{\sqrt{d_k}}\right)\boldsymbol{V}\end{equation}more
There is also additive attention, but additive attention is not easy to parallelize (or rather, it consumes a lot of GPU memory when implemented in parallel), so it is generally only used to encode variable-length vector sequences into a fixed-length vector (as a substitute for simple pooling), and is rarely used for sequence-to-sequence encoding. Among multiplicative attention variants, Self Attention is by far the most widely used. In this case, $\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V}$ are all the result of the same $\boldsymbol{X}$ after a linear transformation, so the output is a vector sequence of the same length as $\boldsymbol{X}$, and it can directly capture the relationship between any two vectors in $X$. It is also easy to parallelize — these are all advantages of Self Attention.
However, in theory, both the computation time and GPU memory usage of Self Attention scale as $\mathcal{O}(n^2)$ (where $n$ is the sequence length), which means that if the sequence length doubles, the memory usage becomes 4 times as large, and the computation time also becomes 4 times as large. Of course, if there are enough parallel cores, the computation time may not actually increase to 4 times the original, but the 4x increase in memory usage is real and unavoidable — this is also why fine-tuning BERT often runs into OOM errors.
Sparse Attention
We say Self Attention is $\mathcal{O}(n^2)$ because it computes the correlation between every pair of vectors in the sequence, producing a correlation matrix of size $n^2$:
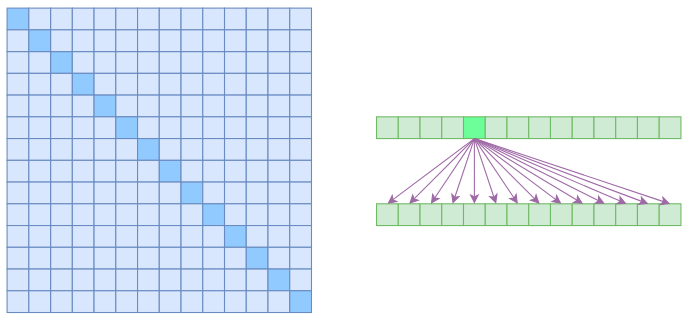 Attention matrix (left) and connectivity diagram (right) of standard Self Attention
In the figure above, the left side shows the attention matrix, and the right side shows the connectivity, illustrating that every element is connected to all other elements in the sequence.
So, if we want to save GPU memory and speed up computation, one basic idea is to reduce the number of correlation computations — that is, to assume that each element is only related to a subset of the elements in the sequence. This is the basic principle behind sparse Attention. The sparse Attention introduced in this post originates from OpenAI's paper Generating Long Sequences with Sparse Transformers, but rather than following the original paper's presentation, I'll introduce it in what I believe is a more natural way.
Atrous Self Attention
The first concept to introduce is Atrous Self Attention, which in Chinese could be called "dilated self-attention" or "hole self-attention." This name, like Local Self Attention introduced later, is one I coined myself based on its characteristics — these two terms do not appear as such in the original paper Generating Long Sequences with Sparse Transformers, but I think it's meaningful to single them out.
Clearly, Atrous Self Attention is inspired by "dilated convolution" (Atrous Convolution). As shown in the figure on the right below, it constrains the correlations by forcibly requiring that each element only relates to elements at relative distance $k,2k,3k,\dots$, where $k > 1$ is a preset hyperparameter. From the attention matrix on the left below, this means forcibly setting to zero the attention weights whose relative distance is not a multiple of $k$ (white represents 0):
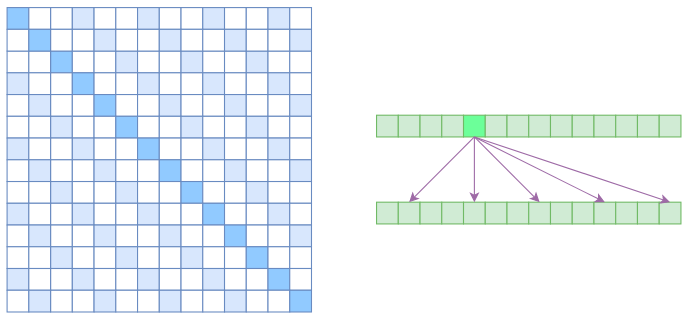 Attention matrix (left) and connectivity diagram (right) of Atrous Self Attention
Since the attention computation now "skips" over elements, each element effectively only computes correlations with about $n/k$ other elements. This means that, ideally, both the running time and memory usage become $\mathcal{O}(n^2/k)$, that is, they can be directly reduced to $1/k$ of the original.
Local Self Attention
Another transitional concept to introduce is Local Self Attention, which can be called "local self-attention" in Chinese. In fact, in the CV field, the self-attention mechanism is collectively referred to as "Non Local," and Local Self Attention obviously has to give up global correlation and reintroduce local correlation instead. Specifically, this is simple: we constrain each element to only be related to the $k$ elements before and after it, as well as itself, as shown below:
 Attention matrix (left) and connectivity diagram (right) of Local Self Attention
Looking at the attention matrix, this means that all attention weights with relative distance exceeding $k$ are directly set to 0.
Actually, Local Self Attention is quite similar to ordinary convolution — both preserve a window of size $2k+1$ and perform some computation within that window. The difference is that ordinary convolution flattens the window and then applies a fully-connected layer to get the output, whereas here, within the window, a weighted average is computed via attention. For Local Self Attention, each element only computes correlations with $2k+1$ other elements, so ideally the running time and memory usage both become $\mathcal{O}((2k+1)n)\sim \mathcal{O}(kn)$, meaning they grow linearly with $n$ — a very desirable property, though it directly sacrifices long-range correlation.
Sparse Self Attention
At this point, we can quite naturally introduce OpenAI's Sparse Self Attention. Notice that Atrous Self Attention has some "holes" in it, and Local Self Attention happens to fill in those holes. So a simple approach is to alternate between Local Self Attention and Atrous Self Attention. Accumulated together, they can in principle learn global correlations while still saving memory.
(A quick sketch would make this clear: suppose the first layer uses Local Self Attention, so each output vector fuses information from a few nearby input vectors. Then the second layer uses Atrous Self Attention — although it skips over elements, since the first layer's output already fuses local input information, the second layer's output can, in principle, be related to any input vector, i.e., long-range correlation is achieved.)
However, OpenAI did not do it this way. Instead, they directly merged Atrous Self Attention and Local Self Attention into one, as shown below:
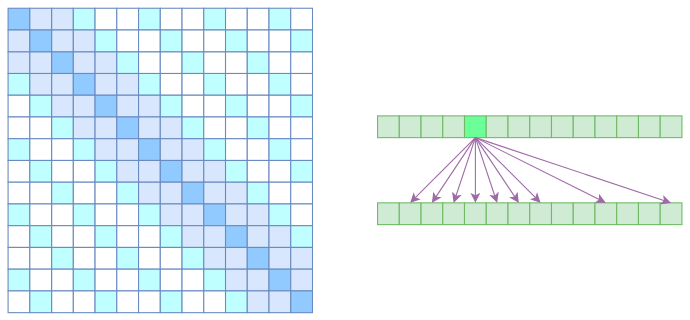 Attention matrix (left) and connectivity diagram (right) of Sparse Self Attention
Looking at the attention matrix, this is easy to understand: apart from relative distances not exceeding $k$, the attention weights at relative distance $k,2k,3k,\dots$ are set to 0. This gives Attention the property of "densely correlated locally, sparsely correlated at long range," which is likely a good prior for many tasks, since tasks that truly require dense long-range correlation are actually quite rare.
Code Implementation
The Atrous Self Attention, Local Self Attention, and Sparse Self Attention described above are all forms of sparse Attention — intuitively, the attention matrix becomes very sparse. So how do we implement them? If we directly mask the zero entries in the attention matrix, this is mathematically (functionally) correct, but it doesn't actually speed things up or save memory.
Official Implementation
OpenAI has open-sourced their own implementation, available at: https://github.com/openai/sparse_attention
This is based on TensorFlow, and also uses their own sparse matrix library blocksparse. However, this seems to be wrapped in a rather unusual way — I don't know how to port it to Keras, and it uses many Python 3 features, so it can't be directly used with Python 2. If you're using Python 3 with pure TensorFlow, feel free to give it a try.
Another issue is that OpenAI's original paper mainly uses sparse Attention to generate very long sequences, so both in the paper and in the code, the entire upper triangular part of the attention matrix is masked (to avoid using future information). But not everyone who uses sparse Attention is working on generation tasks, and for the purpose of introducing the basic concepts, this masking is unnecessary — this is one reason I chose not to follow the original paper's presentation.
Keras Implementation
For Keras, I implemented the three types of sparse Attention described above based on my own design, and standardized them together with the Attention code I had written before. It's still located at the same place:
https://github.com/bojone/attention/blob/master/attention_keras.py
After experimentation, I found that with my implementation, all three sparse Attention variants do save some memory compared to full Attention. Unfortunately, though, except for Atrous Self Attention, the other two Attention implementations don't actually speed things up — in fact, they're slightly slower. This is because the implementation doesn't fully exploit the sparsity, whereas OpenAI's blocksparse is highly optimized and written directly in CUDA — there's no comparison there. But regardless of speed, all three sparse Attention variants should be functionally correct.
Summary
There isn't much more to summarize — this post introduced and implemented three types of sparse Attention. Besides saving GPU memory, sparse Attention should also be better suited to certain tasks, since for most tasks the correlations are mainly local, following a pattern that goes from local to global. In particular, the "densely correlated locally, sparsely correlated at long range" property embodied by the final Sparse Self Attention should satisfy the characteristics of most tasks. If you have a relevant task, feel free to give it a try.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.