EAE: Autoencoder + BN + Maximum Entropy = Generative Model
Generative models have always been a topic I follow closely, whether in NLP or CV. In this post, we'll introduce a novel generative model from the paper Batch norm with entropic regularization turns deterministic autoencoders into generative models, which the authors call EAE (Entropic AutoEncoder). What it sets out to do is basically the same as a variational autoencoder (VAE), and the final results are actually quite similar (slightly better). Calling it "novel" isn't about how good its generation quality is, but rather about the freshness of the idea — it has a distinctly unusual flavor. Along the way, we'll also learn about a method for estimating a statistical quantity — the $k$-nearest-neighbor method, which is a very useful non-parametric estimation technique.
Autoencoder vs. Generative Model
An ordinary autoencoder is an "encode-decode" reconstruction process, as shown below:
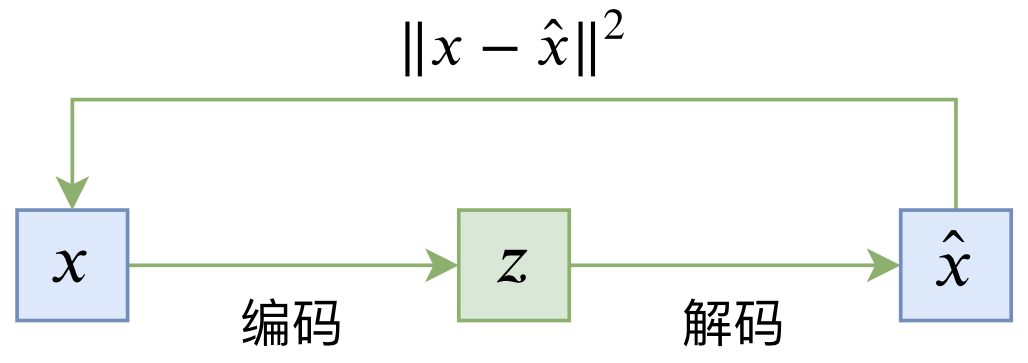 Typical autoencoder diagram
Its loss is generally
\begin{equation}L_{AE} = \mathbb{E}_{x\sim \tilde{p}(x)}\left[\left\Vert x - \hat{x}\right\Vert^2\right] = \mathbb{E}_{x\sim \tilde{p}(x)}\left[\left\Vert x - D(E(x))\right\Vert^2\right]\end{equation}more
Once training is complete, for any image $x$ we can naturally obtain its code $z=E(x)$ and its reconstruction $\hat{x}=D(z)$, and when $x$ and $\hat{x}$ are sufficiently close, we can consider $z$ to be an effective representation of $x$ — one that already fully captures the information in $x$.
So what does it take to be a generative model? "Generative" here means random generation, i.e., we want to be able to randomly construct an image. For the autoencoder's decoder $D(z)$, not every $z$ decoded into $D(z)$ will produce a meaningful image, so an ordinary autoencoder cannot be regarded as a generative model. If we could know in advance the distribution formed by all the codes $z=E(x)$ obtained by encoding $x$, and if that distribution were easy to sample from, then we could achieve random-sampling generation.
So, the one step missing between an autoencoder and a generative model is determining the distribution of the latent variable $z$ — more precisely, forcing the latent variable $z$ to follow some simple, easily sampled distribution, such as the standard normal distribution. VAE achieves this by introducing a KL-divergence term. So how does EAE achieve it?
The Normal Distribution and Maximum Entropy
As we know, the maximum entropy principle is a fairly universal principle, representing the most objective knowledge we can have about an unknown event. One consequence of the maximum entropy principle is:
Among all distributions with mean 0 and variance 1, the standard normal distribution has the maximum entropy.
If readers aren't yet familiar with maximum entropy, they can refer to my earlier post "Entropy" Doesn't Give Up: From Entropy, the Maximum Entropy Principle, to Maximum Entropy Models (Part 2). The conclusion above tells us that if we have some means of guaranteeing that the latent variable has mean 0 and variance 1, then we only need to simultaneously maximize the entropy of the latent variable to achieve the goal that "the latent variable follows a standard normal distribution," i.e.
\begin{equation}\begin{aligned}&L_{EAE} = \mathbb{E}_{x\sim \tilde{p}(x)}\left[\left\Vert x - D(E(x))\right\Vert^2 \right] - \lambda H(Z)\\ &\text{s.t.}\,\,\text{avg}(E(x))=0,\,\text{std}(E(x))=1 \end{aligned}\end{equation}
where $\lambda > 0$ is a hyperparameter, and
\begin{equation}H(Z)=\mathbb{E}_{z\sim p(z)}[-\log p(z)]\end{equation}
is the entropy corresponding to the latent variable $z=E(x)$. Minimizing $- \lambda H(Z)$ amounts to maximizing $\lambda H(Z)$, i.e., maximizing entropy.
The question is: how do we enforce these two constraints? And how do we compute the entropy of the latent variable?
Mean-Variance Constraint and BN
Let's first tackle the first problem: how do we achieve — or at least approximately achieve — the constraint that "the latent variable has mean 0 and variance 1"? Only under this constraint is the maximum-entropy distribution actually the standard normal. The solution to this problem is the familiar batch normalization, i.e. BN (Batch Normalization).
During the training phase of BN, we directly subtract the batch mean from each variable and divide by the batch standard deviation, which guarantees that within each training batch, the variable's mean really is 0 and its variance really is 1. It then keeps a running average of the batch means and variances, cached for use during inference. In short, applying BN to the latent variable causes the latent variable to (approximately) satisfy the corresponding mean-variance constraint. One clarification: the BN layer discussed in this post excludes the two trainable parameters $\beta,\gamma$; in Keras, this means passing the appropriate argument scale=False, center=False when initializing the BN layer.
At this point, we obtain
\begin{equation}L_{EAE} = \mathbb{E}_{x\sim \tilde{p}(x)}\left[\left\Vert x - D(\mathcal{N}(E(x)))\right\Vert^2\right] - \lambda H(Z)\label{eq:eae}\end{equation}
where $\mathcal{N}(\cdot)$ denotes the BN layer.
Sample-Based Nearest-Neighbor Estimation of Entropy
Now we come to the final — and also the most technically demanding — part of the entire EAE model: how to estimate the entropy $H(Z)$. In theory, to compute $H(Z)$ we'd need to know $p(z)$, but here we only have samples $z_1, z_2, \dots, z_n$ and don't know the expression for $p(z)$. Estimating $H(Z)$ under these conditions is called non-parametric estimation.
Let's state the conclusion first:
Nearest-neighbor estimate of entropy. Let $z_1,z_2,\dots,z_n\in\mathbb{R}^d$ be $n$ samples drawn from $p(z)$, and let $\varepsilon(i)$ denote the distance from $z_i$ to its nearest neighboring sample, i.e. $\varepsilon(i) = \min\limits_{j\neq i} \Vert z_i - z_j \Vert$. Let $B_d$ be the volume of the $d$-dimensional unit ball, and let $\gamma=0.5772\dots$ be Euler's constant. Then
\begin{equation}H(Z)\approx \frac{d}{n}\sum_{i=1}^n \log \varepsilon(i) + \log B_d + \log (n - 1) + \gamma \label{eq:1nn}\end{equation}
Setting aside constants irrelevant to optimization, the conclusion above really just says $H(Z)\sim \sum\limits_{i=1}^n \log \varepsilon(i)$, which is the term we need to add to the loss.
How was this strange-looking (and admittedly not-so-easy-to-understand) result obtained? In fact, it's a classic example of an important estimation method — the $k$-nearest-neighbor method. Below we'll give the derivation, following the paper A non-parametric k-nearest neighbour entropy estimator.
Let's consider a particular sample $z_i$, and let $z_{i(k)}$ be its $k$-th nearest neighbor sample, i.e., if we sort all the $z_j (j\neq i)$ in increasing order of $\Vert z_j - z_i\Vert$, the $k$-th one is $z_{i(k)}$. Write $\varepsilon_k(i) = \left\Vert z_i - z_{i(k)}\right\Vert$, and let's consider the probability distribution of $\varepsilon_k(i)$.
Suppose $\varepsilon \leq \varepsilon_k(i) \leq \varepsilon + d\varepsilon$; this means that among the remaining $n-1$ samples, $k-1$ of them fall inside the ball "centered at $z_i$ with radius $\varepsilon$", $n-k-1$ of them fall outside the ball "centered at $z_i$ with radius $\varepsilon+d\varepsilon$", and one is sandwiched between the two balls. It's not hard to show that the probability of this happening is
\begin{equation}\binom{n-1}{1}\binom{n-2}{k-1}P_i(\varepsilon)^{k-1}(1 - P_i(\varepsilon + d\varepsilon))^{n-k-1}(P_i(\varepsilon + d\varepsilon) - P_i(\varepsilon))\label{eq:dp-1}\end{equation}
where $\binom{n-1}{1}$ is the number of ways to choose $1$ samples out of $n-1$ to be sandwiched between the two balls, and $\binom{n-2}{k-1}$ is the number of ways to choose $k-1$ samples from the remaining $n-2$ to be placed inside the ball (the remaining $n-k-1$ automatically land outside the ball); $P_i(\varepsilon)$ is the probability that a single sample falls inside the ball, i.e.
\begin{equation}P_i(\varepsilon) = \int_{\Vert z - z_i\Vert \leq \varepsilon} p(z)dz\end{equation}
So $P_i(\varepsilon)^{k-1}$ is the probability that all $k-1$ chosen samples are inside the ball, $(1 - P_i(\varepsilon + d\varepsilon))^{n-k-1}$ is the probability that $n-k-1$ samples are all outside the ball, and $P_i(\varepsilon + d\varepsilon) - P_i(\varepsilon)$ is the probability that a sample lies between the two balls. Multiplying all these terms together gives equation $\eqref{eq:dp-1}$, which, expanded and keeping only the first-order term, gives the approximation:
\begin{equation}\binom{n-1}{1}\binom{n-2}{k-1}P_i(\varepsilon)^{k-1}(1 - P_i(\varepsilon))^{n-k-1}dP_i(\varepsilon)\label{eq:dp-2}\end{equation}
Note that the expression above describes a valid probability distribution, so its integral must equal 1.
Now we can make an approximation assumption — and it's worth noting that this is the only assumption in the entire derivation, and the reliability of the final result depends on how well this assumption holds:
\begin{equation}p(z_i) \approx \frac{1}{B_d \varepsilon_k(i)^d}\int_{\Vert z - z_i\Vert \leq \varepsilon} p(z)dz = \frac{P_i(\varepsilon)}{B_d \varepsilon_k(i)^d}\end{equation}
where $B_d \varepsilon_k(i)^d$ is the volume of a ball of radius $\varepsilon_k(i)$. Based on this approximation we have $p(z_i) B_d \varepsilon_k(i)^d \approx P_i(\varepsilon)$, which may look unreasonable, since the left side is essentially a constant while the right side is a function of $\varepsilon$ — how can the two remain approximately equal throughout? In fact, when $n$ is large enough, the sampled points become dense enough that $\varepsilon$ will be concentrated in a fairly narrow range, while $\varepsilon_k(i)$ is the value of $\varepsilon$ for one particular draw, so we can consider $\varepsilon$ to be concentrated near $\varepsilon_k(i)$. Although $P_i(\varepsilon)$ does vary with $\varepsilon$, since we're later going to integrate over $\varepsilon$, we only need the approximation to be good in the neighborhood of $\varepsilon_k(i)$ for $P_i(\varepsilon)$ — it doesn't need to hold well everywhere (i.e., when $\varepsilon \gg \varepsilon_k(i)$, $\eqref{eq:dp-2}$ is nearly 0). And near $\varepsilon_k(i)$ we can assume the probability varies smoothly, so $p(z_i) B_d \varepsilon_k(i)^d \approx P_i(\varepsilon)$.
Now we can write
\begin{equation}\log p(z_i) \approx \log P_i(\varepsilon) - \log B_d - d \log \varepsilon_k(i) \end{equation}
Multiplying both sides of the equation above by $\eqref{eq:dp-2}$ and integrating over $\varepsilon$ (with integration range $[0,+\infty)$, or equivalently, integrating over $P_i$ at $[0,1]$). Except for $\log P_i(\varepsilon)$, all the other terms are independent of $\varepsilon$, so after integration they remain unchanged, and
\begin{equation}\begin{aligned}&\int_0^1 \binom{n-1}{1}\binom{n-2}{k-1}P_i(\varepsilon)^{k-1}(1 - P_i(\varepsilon))^{n-k-1} \log P_i(\varepsilon) d P_i(\varepsilon) \\ > =&\psi(k)-\psi(n)\end{aligned}\end{equation}
where $\psi$ denotes the digamma function. (Don't ask me how these integrals were computed — I don't know either, but I do know that Mathematica can crunch through them!)
This gives us the approximation
\begin{equation}\log p(z_i) \approx \psi(k)-\psi(n) - \log B_d - d \log \varepsilon_k(i) \end{equation}
So the final approximation for the entropy is:
\begin{equation}\begin{aligned}H(Z)=&\, \mathbb{E}_{z\sim p(z)}[-\log p(z)]\\ > \approx&\, -\frac{1}{n}\sum_{i=1}^n \log p(z_i)\\ > \approx&\, \frac{d}{n}\sum_{i=1}^n \log \varepsilon_k(i) + \log B_d + \psi(n)-\psi(k) > \end{aligned}\label{eq:knn}\end{equation}
This is a more general result than equation $\eqref{eq:1nn}$. In fact, equation $\eqref{eq:1nn}$ is the special case of $k=1$ when $\psi(1)=-\gamma$, because $\psi(n)= \sum\limits_{m=1}^{n-1}\frac{1}{m}-\gamma\approx \log(n-1)$ — and these transformation formulas can all be found on Wikipedia.
As mentioned at the outset, the $k$-nearest-neighbor method is a very useful non-parametric estimation technique, and it's also related to the IMLE model I introduced previously. That said, I'm not myself deeply familiar with the $k$-nearest-neighbor method and still have much to learn; the reference I found is Lectures on the Nearest Neighbor Method. For more on entropy estimation, readers can also check out this Stanford material, Theory and Practice of Differential Entropy Estimation.
Further Thoughts and Analysis
With $\eqref{eq:1nn}$ or $\eqref{eq:knn}$ in hand, the EAE loss described by equation $\eqref{eq:eae}$ is complete, and so the introduction to the EAE model is finished. What remains are the experimental results, which I won't go into in detail — the gist is that the generated images look about on par with those of VAE, but the metrics come out slightly better.
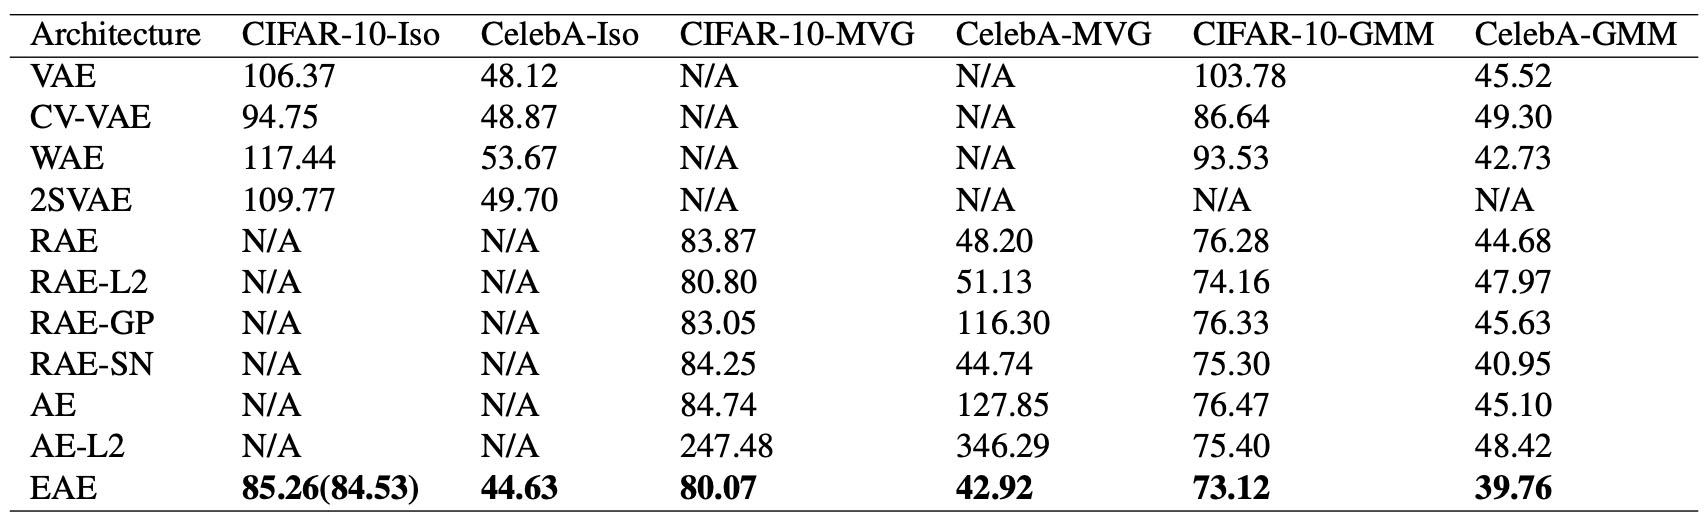 Experimental comparison from the EAE paper
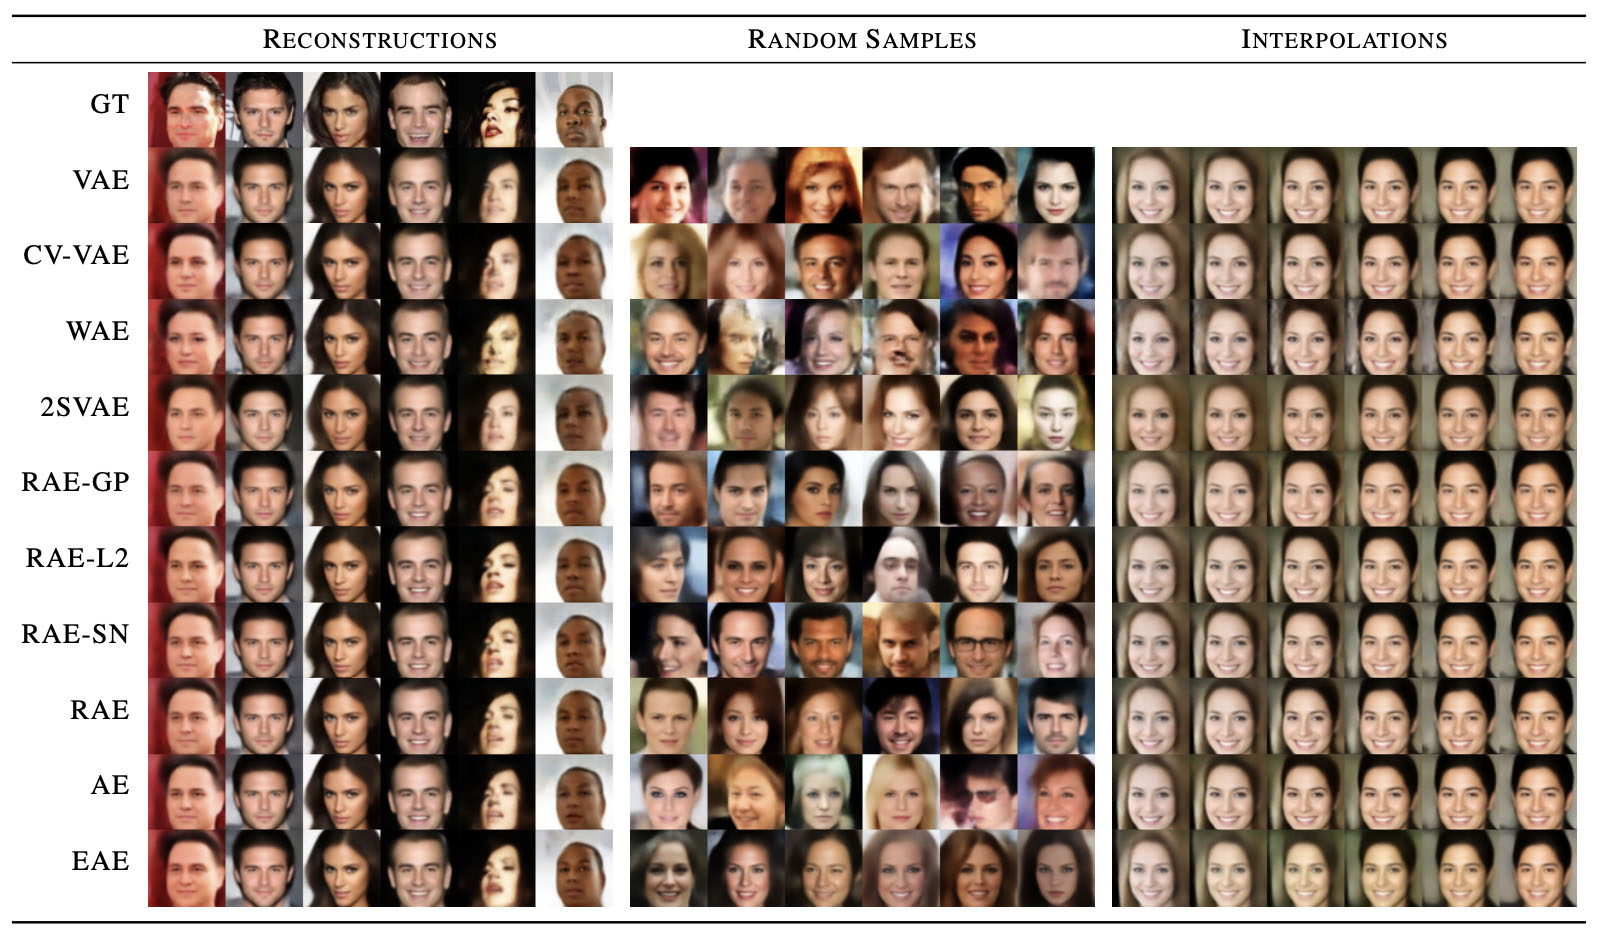 Example results from the EAE paper
So where does EAE's advantage over VAE actually lie? In VAE, the crucial step is reparameterization (see my earlier post Variational Autoencoders (Part 1): So That's What It Is), which is exactly what reduces the variance of the training gradient (compared to REINFORCE, which has much higher variance — see my post A Ramble on Reparameterization: From the Normal Distribution to Gumbel-Softmax), allowing VAE to train effectively. However, although reparameterization reduces the variance, the variance is still not negligible in practice — put simply, the reparameterization step introduces considerable noise (especially early in training), which prevents the decoder from making good use of the information from the encoder. A typical manifestation of this is the "KL vanishing" phenomenon seen when applying VAE to NLP.
EAE largely avoids this problem, because at its core EAE is basically just an ordinary autoencoder: the added BN layer doesn't meaningfully affect the autoencoding performance, and the added entropy regularization term, in principle, only increases the diversity of the latent variable without creating any obvious difficulty in exploiting the encoded information for reconstruction. In my view, this is precisely where EAE's advantage over VAE lies. Of course, I haven't yet run extensive experiments with EAE myself, and the analysis above is largely speculative — readers should judge for themselves. If I obtain further experimental findings, I'll share them on the blog.
A Brief Summary to Close
This post introduced a model called EAE, which essentially inserts a BN layer and a maximum-entropy term into an ordinary autoencoder, giving it the capability of a generative model. The original paper's numerous experiments show that EAE outperforms VAE, making it a model well worth learning about and trying out. Additionally, the key component of EAE — estimating entropy via the $k$-nearest-neighbor method — is quite technically demanding, but genuinely valuable, and well worth careful reading for anyone interested in statistical estimation.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.