Rambling on Reparameterization: From the Normal Distribution to Gumbel Softmax
Recently, while using VAEs to handle some text-related problems, I ran into the issue of taking an expectation over a discrete posterior distribution. Following this thread of "discrete distribution + reparameterization," I eventually searched my way to Gumbel Softmax. In the process of learning about Gumbel Softmax, I ended up going through all the related material on reparameterization, and picked up some new knowledge about gradient estimation along the way, so I'm recording it all here.
The article starts from the continuous case to introduce reparameterization, with the main example being reparameterization of the normal distribution; then it introduces reparameterization for discrete distributions, which brings us to Gumbel Softmax, including some proofs and discussion of it; finally, we'll talk about some of the backstory behind reparameterization, which mainly has to do with gradient estimation.
Basic Concepts
Reparameterization is essentially a technique for handling objective functions that take the form of the following expectation:
\begin{equation}L_{\theta}=\mathbb{E}_{z\sim p_{\theta}(z)}[f(z)]\label{eq:base}\end{equation}
Objectives like this show up in VAEs, in text GANs, and also in reinforcement learning (where $f(z)$ corresponds to the reward function), so if you dig deep enough, you'll frequently run into objective functions of this form. Depending on whether $z$ is continuous, it takes different forms:
\begin{equation}\int p_{\theta}(z) f(z)dz\,\,\,\text{(continuous case)}\qquad\qquad \sum_{z} p_{\theta}(z) f(z)\,\,\,\text{(discrete case)}\end{equation}
Of course, in the discrete case we prefer to replace the notation $z$ with $y$ or $c$. more
To minimize $L_{\theta}$, we need to write $L_{\theta}$ out explicitly, which means we need to implement sampling from $p_{\theta}(z)$. But $p_{\theta}(z)$ carries the parameter $\theta$, and if we sample directly, we lose the information (gradient) of $\theta$, and thus cannot update the parameter $\theta$. Reparameterization provides exactly this kind of transformation: it lets us sample directly from $p_{\theta}(z)$ while preserving the gradient of $\theta$. (Note: in the most general form, $f(z)$ should also carry the parameter $\theta$, but this doesn't add any essential difficulty.)
The Continuous Case
For simplicity, let's first consider the continuous case
\begin{equation}L_{\theta}=\int p_{\theta}(z) f(z)dz\label{eq:lianxu}\end{equation}
where $p_{\theta}(z)$ is a distribution with an explicit probability density expression; in Variational Autoencoders, the normal distribution $p_{\theta}(z)=\mathcal{N}\left(z;\mu_{\theta},\sigma_{\theta}^2\right)$ is the common choice.
Form
From equation $\eqref{eq:lianxu}$ we know that in the continuous case, $L_{\theta}$ is really just an integral. So, to write $L_{\theta}$ out explicitly, there are two routes: the most direct way is to compute the integral $\eqref{eq:lianxu}$ exactly and get a closed-form expression, but this is usually impossible; so the only option is to convert it into a sampling form $\eqref{eq:base}$, and try to preserve the gradient of $\theta$ during the sampling process.
Reparameterization is exactly this kind of technique. It assumes that sampling from the distribution $p_{\theta}(z)$ can be decomposed into two steps: (1) sample $\varepsilon$ from a parameter-free distribution $q(\varepsilon)$; (2) apply a transformation $z=g_{\theta}(\varepsilon)$ to generate $z$. Then equation $\eqref{eq:base}$ becomes
\begin{equation}L_{\theta}=\mathbb{E}_{\varepsilon\sim q(\varepsilon)}[f(g_{\theta}(\varepsilon))]\label{eq:reparam}\end{equation}
At this point, the distribution being sampled from no longer has any parameters — everything has been moved inside $f$ — so we can sample a number of points and write things down just like an ordinary loss.
An Example
The simplest example is the normal distribution: for the normal distribution, reparameterization turns "sample a $z$ from $\mathcal{N}\left(z;\mu_{\theta},\sigma_{\theta}^2\right)$" into "sample a $\varepsilon$ from $\mathcal{N}\left(\varepsilon;0, 1\right)$, then compute $\varepsilon\times \sigma_{\theta} + \mu_{\theta}$." So
\begin{equation}\mathbb{E}_{z\sim \mathcal{N}\left(z;\mu_{\theta},\sigma_{\theta}^2\right)}\big[f(z)\big] = \mathbb{E}_{\varepsilon\sim \mathcal{N}\left(\varepsilon;0, 1\right)}\big[f(\varepsilon\times \sigma_{\theta} + \mu_{\theta})\big]\end{equation}
How should we understand the fact that direct sampling has no gradient, while after reparameterization it does? It's actually quite simple. Suppose I say I'm going to sample a number from $\mathcal{N}\left(z;\mu_{\theta},\sigma_{\theta}^2\right)$, and then you tell me the sample came out to be 5 — I can't see any relationship at all between 5 and $\theta$ (the gradient can only be computed as 0). But if instead we first sample a number from $\mathcal{N}\left(\varepsilon;0, 1\right)$, say $0.2$, and then compute $0.2 \sigma_{\theta} + \mu_{\theta}$, then I do know how the sampled result relates to $\theta$ (a valid gradient can be obtained).
Summary
Let's put the preceding material together. Overall, reparameterization in the continuous case is fairly simple: in the continuous case, the $L_{\theta}$ we need to handle is really equation $\eqref{eq:lianxu}$. Since we can't write the exact integral out explicitly, we need to convert it into a sampling form, and in order to obtain a valid gradient during sampling, we need reparameterization.
Viewed from a mathematical standpoint, reparameterization is a kind of change of variables in an integral: originally we were integrating with respect to $z$, and after the transformation $z=g_{\theta}(\varepsilon)$ we get a new integral form.
The Discrete Case
To emphasize "discreteness," we'll replace the random variable $z$ with $y$, so the objective function we need to face in the discrete case is
\begin{equation}L_{\theta}=\mathbb{E}_{y\sim p_{\theta}(y)}[f(y)]=\sum_y p_{\theta}(y) f(y)\label{eq:lisan}\end{equation}
Here, discreteness generally means $y$ is enumerable, in other words $p_{\theta}(y)$ is at this point a $k$-way classification model:
\begin{equation}p_{\theta}(y)=softmax\big(o_1,o_2,\dots,o_k\big)=\frac{1}{\sum\limits_{i=1}^k e^{o_i}}\left(e^{o_1}, e^{o_2}, \dots, e^{o_k}\right)\label{eq:softmax}\end{equation}
where each $o_i$ is a function of $\theta$.
Analysis
Seeing the sum in $\eqref{eq:lisan}$, a reader's first reaction might be: "A sum? Just sum it then, it's not like we can't."
Indeed, that was my own first reaction too. Unlike the continuous case $\eqref{eq:lianxu}$, if we tackle equation $\eqref{eq:lianxu}$ head-on, we'd need to compute an integral (which can also be viewed as a sum over infinitely many points), and that's something we can't do. But for a discrete $\eqref{eq:lisan}$, it's merely a finite sum, and in principle we really could compute the sum exactly and then run gradient descent.
But what if $k$ is extremely large? For example, suppose $y$ is a 100-dimensional vector, with each element being either 0 or 1 (a binary variable). Then the total number of distinct values of $y$ is $2^{100}$, and summing over $2^{100}$ terms is computationally intractable. Another typical example is the decoder side of seq2seq (which you must face if you want to build a text GAN): the total number of categories there is $|V|^l$, where $|V|$ is the vocabulary size and $l$ is the sentence length. In cases like this, even computing an exact sum is infeasible.
Form
So we still need to fall back on sampling: if we can sample a number of points to get a valid estimate of $\eqref{eq:lisan}$ without losing gradient information, that would be ideal. To this end, we first need to introduce Gumbel Max, which provides a way to sample from a categorical distribution.
Suppose the probability of each category is $p_1,p_2,\dots,p_k$. Then the following procedure gives a way to sample a category with the correct probability, called Gumbel Max:
\begin{equation}\mathop{\text{argmax}}_i \Big(\log p_i - \log(-\log \varepsilon_i)\Big)_{i=1}^k,\quad \varepsilon_i\sim U[0, 1]\end{equation}
That is, we first compute the log of each probability, $\log p_i$, then sample $k$ random numbers $\varepsilon_1,\dots,\varepsilon_k$ from the uniform distribution $U[0,1]$, add $-\log(-\log \varepsilon_i)$ to $\log p_i$, and finally take the category corresponding to the maximum value.
Later we'll prove that this procedure is exactly equivalent to sampling a category with probability $p_1,p_2,\dots,p_k$. In other words, in Gumbel Max, the probability of output $i$ is precisely $p_i$. Since all the randomness has now been shifted onto $U[0,1]$, and $U[0,1]$ carries no unknown parameters, Gumbel Max is a reparameterization process for discrete distributions.
However, we want reparameterization that doesn't lose gradient information, and Gumbel Max fails to deliver that, because $\mathop{\text{argmax}}$ isn't differentiable. So we need a further approximation. First, note that in neural networks, the standard way to handle discrete inputs is to convert them to one-hot form (and indeed the essence of an embedding layer is a one-hot fully-connected layer — see Word Vectors and Embeddings: What's Really Going On?). So $\mathop{\text{argmax}}$ is really $\text{onehot}(\mathop{\text{argmax}}))$, and then we look for a smooth approximation of $\text{onehot}(\mathop{\text{argmax}}))$, which turns out to be $softmax$ (see Smoothing Non-Differentiable Functions: A Ramble).
From this we obtain the smooth approximation of Gumbel Max — Gumbel Softmax:
\begin{equation}softmax \Big(\big(\log p_i - \log(-\log \varepsilon_i)\big)\big/\tau\Big)_{i=1}^k,\quad \varepsilon_i\sim U[0, 1]\end{equation}
Here the parameter $\tau > 0$ is called the annealing temperature: the smaller it is, the closer the output gets to one-hot form (but at the same time, vanishing gradients become more severe). Here's a little trick: if $p_i$ is the output of a softmax, i.e. of the form $\eqref{eq:softmax}$, then there's no need to first compute $p_i$ and then take the log — you can just replace $\log p_i$ with $o_i$ directly:
\begin{equation}softmax \Big(\big(o_i - \log(-\log \varepsilon_i)\big)\big/\tau\Big)_{i=1}^k,\quad \varepsilon_i\sim U[0, 1]\end{equation}
Proof of Gumbel Max:
The form of Gumbel Max looks a bit complicated, nowhere near as simple as reparameterization of the normal distribution, but in fact, if you work up the courage to look at it closely, even the proof isn't hard. We want to show that Gumbel Max outputs category $i$ with probability $p_i$; without loss of generality, let's prove that the probability of outputting 1 is $p_1$.
Note that outputting 1 means that $\log p_1 - \log(-\log \varepsilon_1)$ is the largest, which in turn means:
\begin{equation}\begin{aligned} > &\log p_1 - \log(-\log \varepsilon_1) > \log p_2 - \log(-\log \varepsilon_2) \\ > &\log p_1 - \log(-\log \varepsilon_1) > \log p_3 - \log(-\log \varepsilon_3) \\ > &\qquad \vdots\\ > &\log p_1 - \log(-\log \varepsilon_1) > \log p_k - \log(-\log \varepsilon_k) > \end{aligned} > \end{equation}
Note that each inequality here is independent — that is, whatever the relationship between $\log p_1 - \log(-\log \varepsilon_1)$ and $\log p_2 - \log(-\log \varepsilon_2)$, it doesn't affect the relationship with $\log p_3 - \log(-\log \varepsilon_3)$. So we only need to analyze the probability of each inequality separately. Without loss of generality, let's analyze the first inequality; simplifying, we get:
\begin{equation}\varepsilon_2 < \varepsilon_1^{p_2 / p_1}\leq 1 \end{equation}
Since $\varepsilon_2\sim U[0,1]$, the probability of $\varepsilon_2 < \varepsilon_1^{p_2 / p_1}$ is $\varepsilon_1^{p_2 / p_1}$ — this is the probability that the first inequality holds, given fixed $\varepsilon_1$. So the probability that all the inequalities hold simultaneously is
\begin{equation}\varepsilon_1^{p_2 / p_1}\varepsilon_1^{p_3 / p_1}\dots \varepsilon_1^{p_k / p_1}=\varepsilon_1^{(p_2 + p_3 + \dots + p_k) / p_1}=\varepsilon_1^{(1/p_1)-1}\end{equation}
Then averaging over all $\varepsilon_1$ gives
\begin{equation}\int_0^1 \varepsilon_1^{(1/p_1)-1}d\varepsilon_1 = p_1\end{equation}
This is the probability that category 1 occurs, and it equals $p_1$. This completes the proof of the Gumbel Max sampling procedure.
An Example
Just as in the continuous case, Gumbel Softmax is used when we need to compute $\mathbb{E}_{y\sim p_{\theta}(y)}[f(y)]$ but cannot directly complete the sum over $y$. In that case, we compute $p_{\theta}(y)$ (or $o_i$), pick a value of $\tau > 0$, use Gumbel Softmax to compute a random vector $\tilde{y}$, and plug it in to get $f(\tilde{y})$, which is a good approximation of $\mathbb{E}_{y\sim p_{\theta}(y)}[f(y)]$ that preserves gradient information.
Note that Gumbel Softmax is not an exact equivalent of categorical sampling — Gumbel Max is. Gumbel Softmax can be viewed as the limit of Gumbel Max as $\tau \to 0$. So when applying Gumbel Softmax, you can start with a larger $\tau$ (say, 1), and then gradually anneal it down to a value close to 0 (say, 0.01), in order to get good results.
Below is an example VAE with discrete latent variables that I implemented myself:
https://github.com/bojone/vae/blob/master/vae_keras_cnn_gs.py
Result:
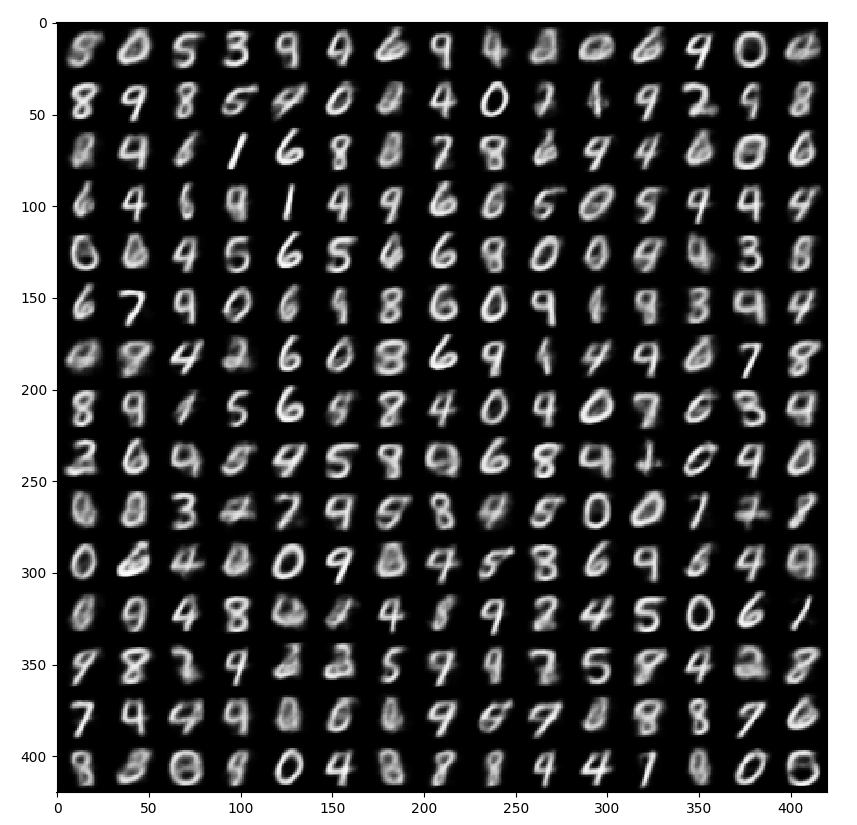 Discrete-latent-variable VAE generation based on Gumbel Softmax reparameterization
Origins
Gumbel Max has a long history, but the first paper to propose and apply Gumbel Softmax was Categorical Reparameterization with Gumbel-Softmax, which mainly explores variational inference problems where some latent variables are discrete, such as VAE-based semi-supervised learning (methodologically somewhat similar to Variational Autoencoders (IV): A One-Shot Clustering Solution). Later, in the paper GANs for Sequences of Discrete Elements with the Gumbel-Softmax Distribution, Gumbel Softmax was applied for the first time to discrete sequence generation — though not yet text generation, but rather relatively simple synthetic character sequences.
Later still, SeqGAN was proposed, and from then on text GAN models have largely been built around combination with reinforcement learning, while the purely deep-learning, gradient-descent-based approach using Gumbel Softmax remained relatively quiet — until the arrival of RelGAN. RelGAN is a model proposed at ICLR 2019, which introduced new generator and discriminator architectures, such that a text GAN trained directly with Gumbel Softmax substantially outperformed previous text GAN models. We'll leave a deeper discussion of RelGAN for another time.
Summary
This part mainly introduced Gumbel Softmax, which is a reparameterization technique for $\eqref{eq:base}$-type losses in the discrete case.
In principle, $\eqref{eq:base}$ in the discrete case is just a finite sum, and doesn't necessarily require reparameterization. But in practice, "finite" can still mean an astronomically large number, so exhaustive summation may be infeasible, and we still need to convert to sampling form — hence the need for the reparameterization trick, which is Gumbel Softmax, arising from smoothing Gumbel Max.
Besides the perspective above, there's another complementary way to view it: Gumbel Softmax gradually approaches one-hot via annealing of $\tau\to 0$. Compared with directly annealing the plain softmax, the difference is that annealing plain softmax can only ever converge to a one-hot vector at the position of the maximum value, whereas Gumbel Softmax has some probability of landing on a one-hot vector at a non-maximal position, adding extra randomness that makes sampling-based training more thorough.
The Backstory
Is that all there is to reparameterization? Far from it. Behind reparameterization lies a whole family of techniques known as "gradient estimators," and reparameterization is merely one member of that family. Search for keywords like "gradient estimator" or "REINFORCE" at any year's ICLR, ICML, and other top conferences, and you'll find plenty of papers — a sign that this is a topic people are still actively researching.
To really get to the bottom of reparameterization, we need to tell some of the story of gradient estimation too.
The SF Estimator
Earlier, we discussed both the continuous and discrete cases of reparameterization at the "loss level" — that is, we tried to explicitly define the loss, and left the rest (automatic differentiation, automatic optimization) to the framework. But in fact, even when we can't write the loss function explicitly, that doesn't stop us from differentiating it, and it certainly doesn't stop us from using gradient descent. For example,
\begin{equation}\begin{aligned}\frac{\partial}{\partial\theta}\int p_{\theta}(z) f(z)dz=&\int f(z) \frac{\partial}{\partial\theta} p_{\theta}(z) dz\\ =&\int p_{\theta}(z)\times\frac{f(z)}{p_{\theta}(z)}\frac{\partial}{\partial\theta} p_{\theta}(z) dz\\ =&\mathbb{E}_{z\sim p_{\theta}(z)}\left[\frac{f(z)}{p_{\theta}(z)}\frac{\partial}{\partial\theta} p_{\theta}(z)\right]\\ =&\mathbb{E}_{z\sim p_{\theta}(z)}\Big[f(z)\frac{\partial}{\partial\theta} \log p_{\theta}(z)\Big] \end{aligned}\label{eq:sf}\end{equation}
We now have an estimator for the gradient, called the "SF estimator," short for Score Function Estimator. This is the most naive estimate of the original loss function's gradient. In reinforcement learning, where $z$ represents the policy, the above equation is essentially the most basic policy gradient, which is why this estimator is sometimes simply called REINFORCE. Note that if we re-derive this for the discrete case, we get the same result — that is, the result above is general and doesn't distinguish whether $z$ is continuous or discrete. Now we can directly sample a number of points from $p_{\theta}(z)$ to estimate the value of equation $\eqref{eq:sf}$, with no need to worry about whether there's a gradient, because equation $\eqref{eq:sf}$ is itself already the gradient.
Gradient Variance
This looks great — we've obtained an estimator that applies to both continuous and discrete variables. So why do we still need reparameterization?
The main reason is: the SF estimator has very high variance. Equation $\eqref{eq:sf}$ is the expectation of the function $f(z) \frac{\partial}{\partial\theta} \log p_{\theta}(z)$ under the distribution $p_{\theta}(z)$, and we need to sample a few points to compute it (ideally, we'd like to sample just one point). In other words, we want to use the approximation
\begin{equation}\mathbb{E}_{z\sim p_{\theta}(z)}\Big[f(z) \frac{\partial}{\partial\theta} \log p_{\theta}(z)\Big]\approx f(\tilde{z}) \frac{\partial}{\partial\theta} \log p_{\theta}(\tilde{z}),\quad \tilde{z}\sim p_{\theta}(z)\end{equation}
And here's where the trouble starts: this kind of gradient estimate has very high variance.
What does "high variance" mean, and what effect does it have? Let's take a simple example. Suppose $\alpha = avg([4, 5, 6]) = avg([0, 5, 10])$ — that is, our target $\alpha$ is the average of three numbers, which are either $4,5,6$ or $0,5,10$. Under an exact estimate, the two are equivalent, but what if each group can only randomly pick one of the numbers? The first group might pick 4, which isn't a big deal — it's only slightly off from the true value 5. But the second group might pick 0, which is quite far from the true value 5. In other words, if you randomly pick one, the estimate from the second group fluctuates (has variance) much more. Similarly, the gradient estimated via SF has this same kind of behavior, which is precisely why gradient descent based on it tends to be quite unstable, and prone to collapse.
Reducing Variance
Formally, equation $\eqref{eq:sf}$ is quite elegant: it's not complicated in form, it works for both discrete and continuous variables, and it places no special requirements on $f$ (in contrast, reparameterization requires $f$ to be differentiable, which is hard to guarantee in settings like reinforcement learning, where $f(z)$ corresponds to a reward function that's rarely smooth and differentiable). So a lot of papers explore variance-reduction tricks based on equation $\eqref{eq:sf}$. The paper Categorical Reparameterization with Gumbel-Softmax lists a few of them, and there have been further developments in recent years. As always, if you search keywords like "gradient estimator" and "REINFORCE," you'll find no shortage of papers.
Reparameterization is another variance-reduction trick. To see this, let's write down the gradient expression for $\eqref{eq:reparam}$ after reparameterization:
\begin{equation}\begin{aligned}\frac{\partial}{\partial\theta}\mathbb{E}_{\varepsilon\sim q(\varepsilon)}[f(g_{\theta}(\varepsilon))]=&\mathbb{E}_{\varepsilon\sim q(\varepsilon)}\left[\frac{\partial}{\partial\theta}f(g_{\theta}(\varepsilon))\right]\\ =&\mathbb{E}_{\varepsilon\sim q(\varepsilon)}\left[\frac{\partial f}{\partial g} \frac{\partial g_{\theta}(\varepsilon)}{\partial\theta}\right] \end{aligned}\end{equation}
Comparing this with the SF estimator, equation $\eqref{eq:sf}$, we can get an intuitive sense of why the above has lower variance:
1. The SF estimator involves $\log p_{\theta}(z)$. We know that, for any reasonable probability distribution, as we go to infinity (i.e., $\Vert z\Vert \to \infty$), $p_{\theta}(z)\to 0$ tends to zero, and taking $\log$ of it actually makes it tend to negative infinity. In other words, the term $\log p_{\theta}(z)$ effectively amplifies fluctuations at infinity, which increases variance to some extent;
2. The SF estimator involves $f$, whereas after reparameterization this becomes $\frac{\partial f}{\partial g}$. $f$ is typically a neural network, and the neural network models we usually define are, in effect, $\mathcal{O}(z)$-level models, so we'd expect their gradients to be on the order of $\mathcal{O}(1)$ (this doesn't hold strictly, but it's roughly true on average), so it tends to be more stable — meaning that the variance of $f$ tends to be larger than the variance of $\frac{\partial f}{\partial g}$.
Given these two reasons, we can conclude that, in general, the variance of the gradient estimate after reparameterization will be smaller than that of the SF estimator. Note that we still need to stress "in general" — in other words, the claim "reparameterization reduces the variance of gradient estimation" is not an absolute truth. Both reasons above hold for the general case (i.e., the majority of models we deal with), but if you really wanted to be difficult about it, you could always construct an example where reparameterization actually increases variance.
Summary
After a long-winded discussion, we've finally worked through the story of reparameterization in a reasonably thorough way. Understanding the reparameterization trick more deeply is an essential step toward better understanding VAEs and text GANs.
From the loss perspective, we need to distinguish between the continuous and discrete cases: in the continuous case, reparameterization is a way to write down the loss in sampled form without losing gradient information; in the discrete case, reparameterization serves the same purpose as in the continuous case, but the more fundamental motivation is reducing computational cost (otherwise, exhaustive summation would work too). From the gradient-estimation perspective, reparameterization is an effective way to reduce the variance of the gradient estimate, though it's far from the only such technique being studied by researchers.
In any case, however you look at it, this is not something you can just set and forget.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.