The Mighty NVAE: Never Say VAE-Generated Images Are Blurry Again
Yesterday morning, while doing my daily scroll through arXiv, I was blown away by a newly posted paper called NVAE: A Deep Hierarchical Variational Autoencoder. As the name suggests, it's an improved VAE variant, introducing a new model called NVAE. Honestly, I clicked into it without much expectation, since I consider myself reasonably well-versed in VAEs and had long believed that VAEs' generative capability was fundamentally limited. But then the paper opened, and this is what greeted me:
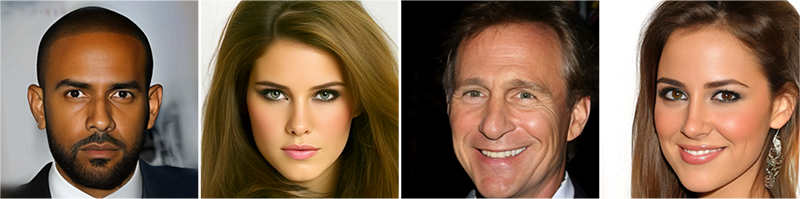 NVAE face generation results
My first reaction was:
W!T!F! This is really generated by a VAE?! Is this still the VAE I know? I guess my understanding of VAEs has been way too shallow. I can never again say that VAE-generated images are blurry...
Then I checked the affiliation of the authors — turns out it's NVIDIA, which made it a bit more understandable. In recent years, people may have noticed that NVIDIA tends to drop a breakthrough in generative models toward the end of each year: PGGAN at the end of 2017, StyleGAN at the end of 2018, StyleGAN2 at the end of 2019. This time it seems to be a bit earlier, and there's also been more activity than usual — just last month they released a method called ADA that pushed Cifar-10 generation to a new height, and now here comes NVAE.
So what exactly is special about NVAE that lets it achieve such a leap forward in VAE generation quality?
A VAE Recap
Careful readers might say:
It still looks a bit fake though — the faces are too smooth, like they've been through a beauty filter. It's still not as good as StyleGAN...
That's a fair assessment — the traces of generation are still quite noticeable. But if you're not impressed, it's probably because you haven't seen what VAE generation used to look like. Typical VAE-generated images look like this:
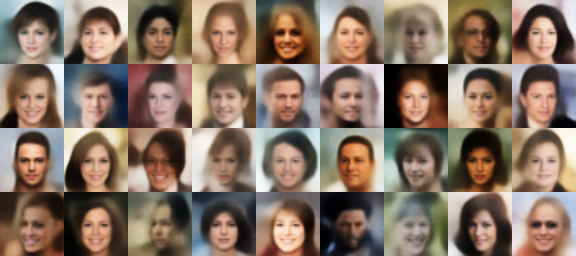 Typical random samples from a VAE
So, do you still think this isn't a breakthrough?
So what was it that limited the expressive power of (previous) VAEs? And what exactly did this breakthrough improve? Let's dig in.
Basic Introduction
VAE, or Variational Auto-Encoder, has already been covered in quite a few posts on this blog — search "Variational Autoencoder" (变分自编码器) in the search bar on the right to find many related posts. Here's a brief recap and analysis.
In my derivation of VAE, we start with a batch of samples representing a real (but unknown) distribution $\tilde{p}(x)$. We then construct a parameterized posterior distribution $p(z|x)$, and together these form a joint distribution $p(x,z)=\tilde{p}(x)p(z|x)$. Next, we define a prior distribution $q(z)$ and a generative distribution $q(x|z)$, forming another joint distribution $q(x,z)=q(z)q(x|z)$. Finally, our goal is to bring $p(x,z),q(x,z)$ close to each other, so we optimize the KL divergence between them:
\begin{equation}\begin{aligned} KL\big(p(x,z)\big\Vert q(x,z)\big)=&\iint p(x,z)\log \frac{p(x,z)}{q(x,z)} dzdx\\ =&\mathbb{E}_{x\sim \tilde{p}(x)} \Big[\mathbb{E}_{z\sim p(z|x)}\big[-\log q(x|z)\big]+KL\big(p(z|x)\big\Vert q(z)\big)\Big] + \text{const} \end{aligned}\end{equation}
This is the VAE's optimization objective.
Analysis of the Difficulty
The requirements for $p(z|x),q(z),q(x|z)$ are: (1) it must have an analytic expression; (2) it must be easy to sample from. However, in the world of continuous distributions, there aren't many distributions satisfying both, and the most commonly used one is the Gaussian — in particular, the "Gaussian with independent components" is the simplest. So in typical VAEs, $p(z|x),q(z),q(x|z)$ are all set to be Gaussians with independent components: $p(z|x)=\mathcal{N}(z;\mu_1(x),\sigma_1^2(x))$, $q(z)=\mathcal{N}(z;0,1)$, and $q(x|z)=\mathcal{N}(x;\mu_2(z),\sigma_2^2(z))$.
The problem is that a "Gaussian with independent components" cannot fit an arbitrarily complex distribution. Once we fix the form of $p(z|x)$, it may be that no matter how we tune its parameters, $\int \tilde{p}(x)p(z|x)dx$ and $\frac{\tilde{p}(x)p(z|x)}{\int \tilde{p}(x)p(z|x)dx}$ can never actually become Gaussian. This means $KL\big(p(x,z)\big\Vert q(x,z)\big)$ can theoretically never reach zero, so trying to bring $p(x,z),q(x,z)$ close to each other can only yield a rough, averaged-out result — which is exactly why images generated by conventional VAEs tend to be blurry.
Related Improvements
One classic direction for improving VAEs is combining them with GANs, such as CVAE-GAN and AGE; the current state of the art along this line is probably IntroVAE. Theoretically, this line of work implicitly abandons the assumption that $q(x|z)$ is Gaussian, replacing it with a more general distribution, which is why it improves generation quality. That said, I feel that bringing GANs into VAEs is a bit like "borrowing the tiger's skin" — you gain performance from the GAN, but also inherit its downsides (unstable training, etc.), and even with the boost, VAE generation still lags behind pure GANs. Another direction is combining VAEs with flow models, such as IAF-VAE and my own earlier f-VAE — this line of work uses flow models to enhance the expressive power of $p(z|x)$ or $q(x|z)$.
Yet another direction is introducing discrete latent variables, the classic example being VQ-VAE — see my post A Concise Introduction to VQ-VAE: The Quantized Autoencoder for details. VQ-VAE encodes images into a discrete sequence using a specific encoding trick, and then uses PixelCNN to model the corresponding prior distribution $q(z)$. As mentioned above, when $z$ is continuous, the choices for $p(z|x),q(z)$ are few, and the approximation precision is limited; but if $z$ is a discrete sequence, then $p(z|x),q(z)$ corresponds to a discrete distribution, and by using autoregressive models (called language models in NLP, and PixelRNN/PixelCNN etc. in CV) we can approximate any discrete distribution to arbitrary precision. This allows for a much more accurate overall approximation, improving generation quality. The subsequent upgrade, VQ-VAE-2, further confirmed the effectiveness of this path. But overall, the VQ-VAE pipeline has already diverged quite a bit from a conventional VAE, and it's sometimes hard to view it as a VAE variant at all.
Dissecting NVAE
After all that preamble, we can finally get to NVAE. NVAE stands for Nouveau VAE (not Nvidia VAE, surprisingly?). It incorporates many recent advances from the CV field, including multi-scale architectures, separable convolutions, the swish activation function, and flow models — a synthesis of the best of everything, resulting in the strongest VAE currently available.
(A note: the notation in this post differs from the original paper and from most common VAE introductions, but is consistent with the rest of this blog. Readers shouldn't try to memorize the symbols verbatim, but should understand the article based on the actual meaning of each symbol.)
Autoregressive Distributions
As analyzed above, the difficulty with VAEs stems from $p(z|x),q(z),q(x|z)$ not being expressive enough, so the improvement strategy is to strengthen them. First, NVAE leaves $q(x|z)$ unchanged, mainly to preserve the parallelism of generation, and instead strengthens the prior $q(z)$ and posterior $p(z|x)$ through autoregressive models. Specifically, it groups the latent variables into $z=\{z_1,z_2,\dots,z_L\}$, where each $z_l$ is still a vector (rather than a scalar), and then sets
\begin{equation}q(z)=\prod_{l=1}^L q(z_l|z_{< l}),\quad p(z|x)=\prod_{l=1}^L p(z_l|z_{< l},x)\label{eq:arpq}\end{equation}
The distribution $q(z_l|z_{< l}),p(z_l|z_{< l},x)$ for each group is still built as a Gaussian, so overall $q(z),p(z|x)$ is constructed as an autoregressive Gaussian model. In this case, the KL divergence term for the posterior becomes
\begin{equation}KL\big(p(z|x)\big\Vert q(z)\big)=KL\big(p(z_1|x)\big\Vert q(z_1)\big)+\sum_{l=2}^L \mathbb{E}_{p(z_{< l}|x)}\Big[KL\big(p(z_l|z_{< l}, x)\big\Vert q(z_l|z_{< l})\big)\Big]\end{equation}
Of course, this idea alone is just a straightforward generalization, not something NVAE originated — it traces back to 2015 models like DRAW and HVM. NVAE's contribution is proposing a "relative" design for formula $\eqref{eq:arpq}$:
\begin{equation}\begin{aligned}&q(z_l|z_{< l})=\mathcal{N}\left(z_l;\mu(z_{< l}),\sigma^2(z_{< l})\right)\\ &p(z_l|z_{< l},x)=\mathcal{N}\left(z_l;\mu(z_{< l})+\Delta\mu(z_{< l},x),\sigma^2(z_{< l})\otimes \Delta\sigma^2(z_{< l}, x)\right) \end{aligned}\end{equation}
That is, instead of directly modeling the mean and variance of the posterior $p(z_l|z_{< l},x)$, it models their values relative to the mean and variance of the prior. In this case we have (dropping the argument notation for simplicity, but it's not hard to figure out what corresponds to what):
\begin{equation}KL\big(p(z_l|z_{< l}, x)\big\Vert q(z_l|z_{< l})\big)=\frac{1}{2} \sum_{i=1}^{|z_l|} \left(\frac{\Delta\mu_{(i)}^2}{\sigma_{(i)}^2} + \Delta\sigma_{(i)}^2 - \log \Delta\sigma_{(i)}^2 - 1\right)\end{equation}
The original paper points out that this makes training more stable.
Multi-Scale Design
Now that the latent variables are split into $L$ groups $z=\{z_1,z_2,\dots,z_L\}$, a natural question arises: (1) how does the encoder generate $z_1,z_2,\dots,z_L$ one by one? (2) how does the decoder use $z_1,z_2,\dots,z_L$ one by one? In other words, how are the encoder and decoder architectures designed?
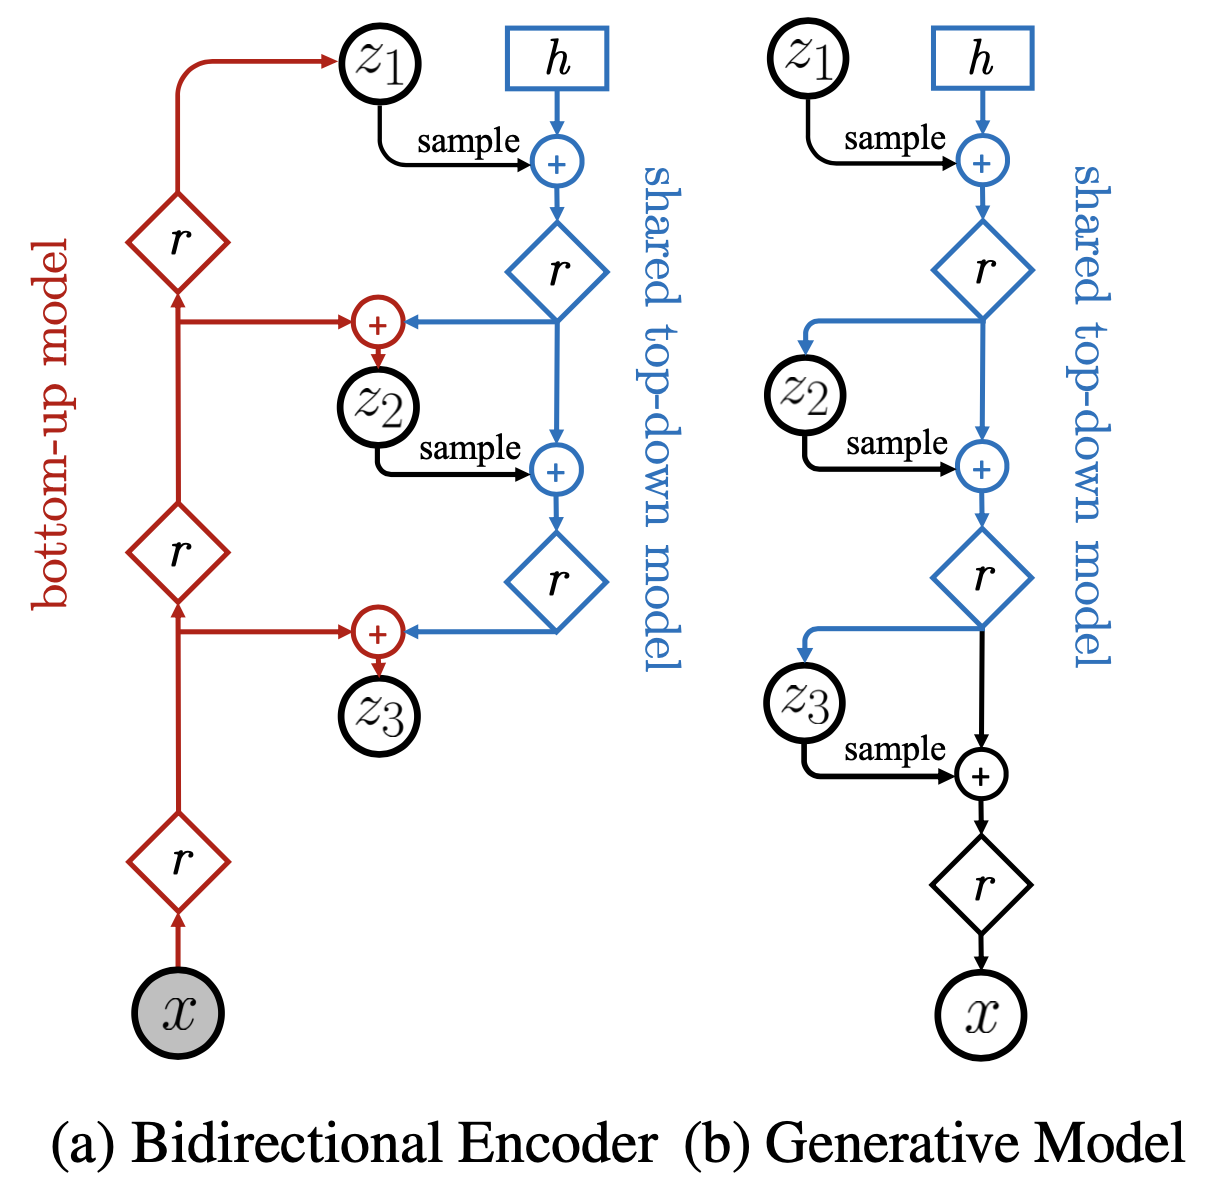 The encoder and decoder architecture in NVAE. Here r denotes a residual block, h denotes trainable parameters, and the blue parts share parameters
NVAE cleverly designs a multi-scale encoder and decoder, as shown in the figure above. First, the encoder is encoded layer by layer to get the topmost encoding vector $z_1$, and then it gradually works its way down from the top, progressively obtaining the lower-level features $z_2,\dots,z_L$. As for the decoder, it is naturally a top-down process that makes use of $z_1,z_2,\dots,z_L$, and this part happens to overlap with the process by which the encoder generates $z_1,z_2,\dots,z_L$. So NVAE simply shares the corresponding parameters between them, which saves on parameter count while also improving generalization through the mutual constraint between the two.
This kind of multi-scale design shows up in essentially all current state-of-the-art generative models, such as StyleGAN, BigGAN, and VQ-VAE-2, which suggests that the effectiveness of multi-scale design has been fairly thoroughly validated. In addition, to ensure performance, NVAE carefully filtered through many candidate designs for the residual block before finally settling on the following one — talk about painstaking model tuning:
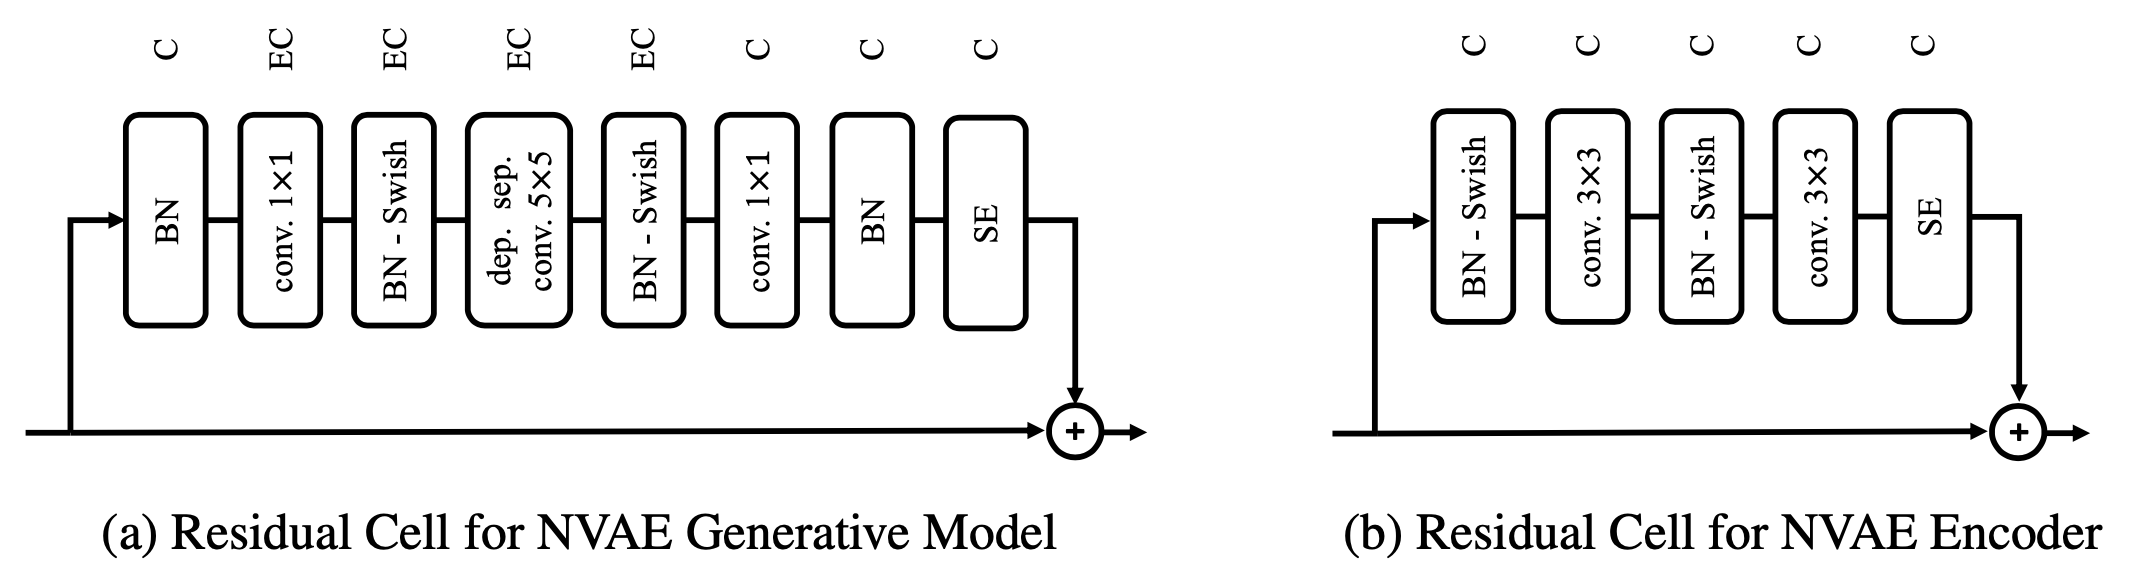 The residual block used in NVAE
Other Improvement Tricks
Besides these two fairly prominent features, NVAE also incorporates many tricks that provide incremental performance gains. Here's a brief rundown of a few.
Improvements to BN layers. Many current generative models have already abandoned BN (Batch Normalization), mostly switching to IN (Instance Normalization) or WN (Weight Normalization), because BN was found to hurt performance. NVAE found through experiments that BN actually does help training, but hurts inference — the reason being that the running-average mean and variance used at inference time aren't good enough. So after training, NVAE re-estimates the mean and variance by sampling many batches of the same batch size, which fixes BN's inference performance. In addition, to ensure training stability, NVAE adds a regularization term on the norm of BN's $\gamma$.
Application of spectral regularization. We know that the KL divergence between two arbitrary distributions is unbounded, so the KL term in a VAE is also unbounded, and optimizing such an unbounded objective is "dangerous" — training could diverge at any time. So, again for the sake of training stability, NVAE adds spectral regularization to every convolutional layer; for background on this concept, see my earlier post Lipschitz Constraints in Deep Learning: Generalization and Generative Models. Adding spectral normalization reduces the model's Lipschitz constant, making the overall loss landscape smoother and thus more conducive to stable training.
Enhancing distributions with flow models. By using an autoregressive model, NVAE strengthens the model's ability to fit distributions. However, this autoregression is only applied across groups; within a group, the individual distributions $p(z_l|z_{< l}, x)$ and $q(z_l|z_{< l})$ are still assumed to be Gaussians with independent components, meaning there's still room for improvement in fitting power. A more thorough solution would be to treat each component within a group as autoregressive too, but that would make sampling extremely slow (since all components would need to be sampled sequentially, one after another). NVAE offers an alternative: modeling the within-group distribution as a flow model, which enhances expressive power while preserving parallelism in within-group sampling. Experimental results show this does help, but I personally feel that introducing flow models greatly increases model complexity, and the gain isn't especially significant — better to avoid it if possible.
Memory-saving tricks. Even though NVIDIA presumably isn't short on GPUs, NVAE still puts real effort into saving GPU memory in its implementation. On one hand, it uses mixed-precision training, which conveniently also gives the paper a chance to plug NVIDIA's own APEX library. On the other hand, it enables gradient checkpointing (i.e., recomputation) for the BN layers, reportedly saving 18% of GPU memory with almost no impact on speed. In short — even teams with more GPUs than you are still better than you at saving memory.
More Sample Images
At this point, the main technical points of NVAE have basically been covered. If you're still not satisfied, here are a few more sample images to give you a deeper appreciation of just how impressive NVAE is.
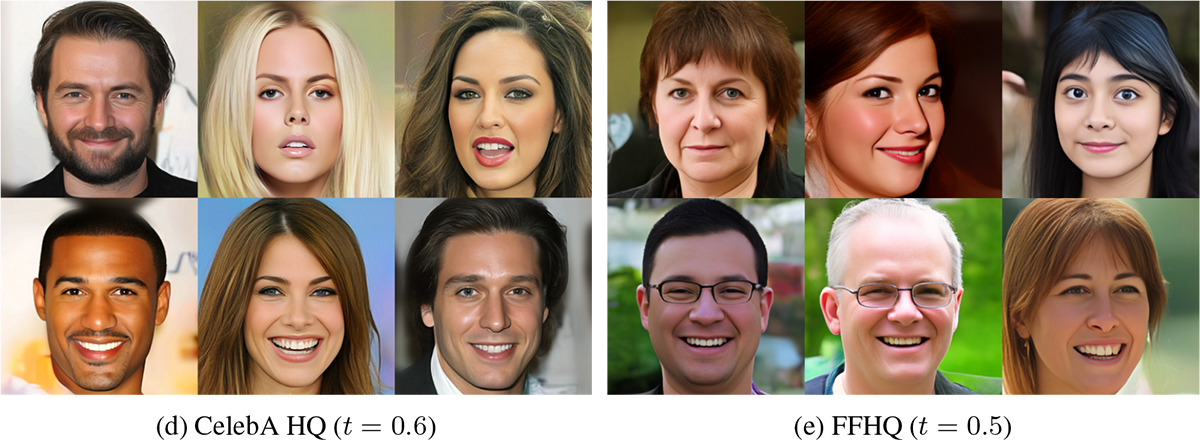 NVAE's generation results on CelebA HQ and FFHQ. Notably, NVAE is the first VAE-family model to be tested on the FFHQ dataset, and it made an impressive debut
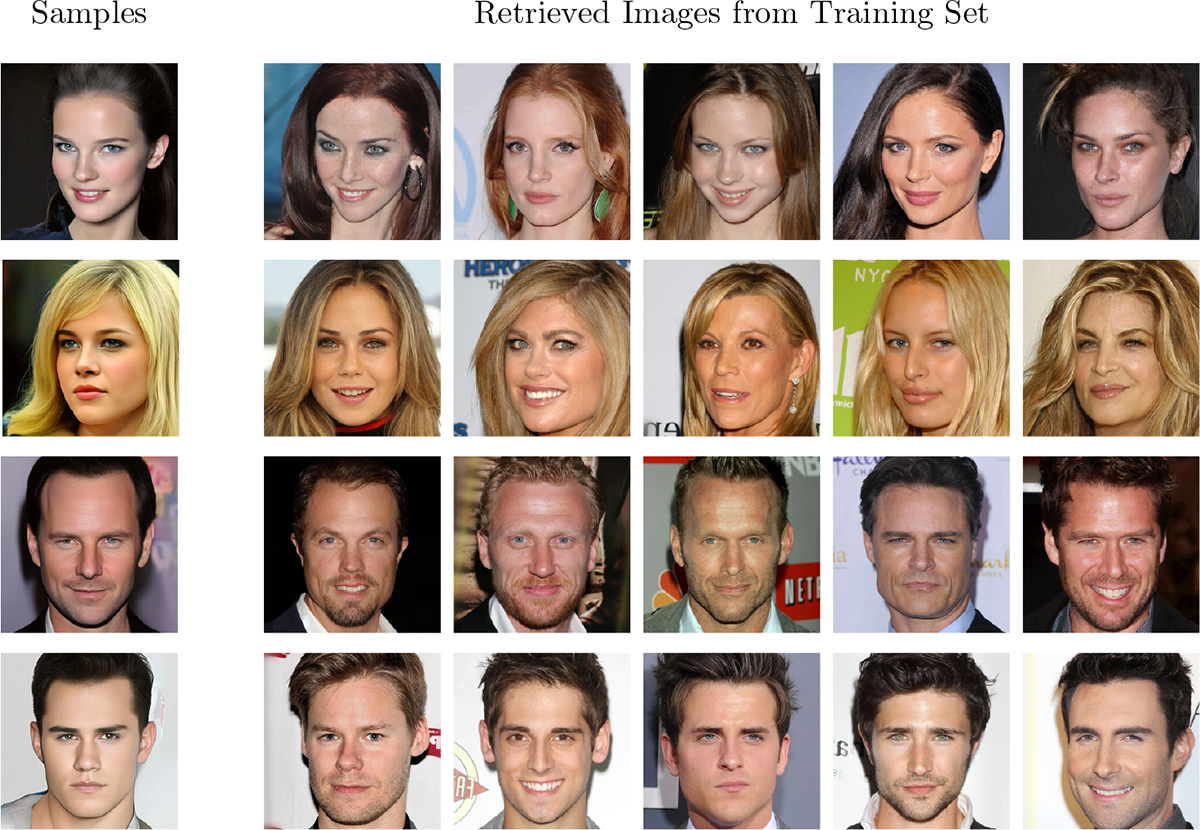 Image retrieval experiments based on NVAE. Left: randomly generated samples. Right: the most similar samples from the training set — mainly meant to check whether the model has simply memorized the training set
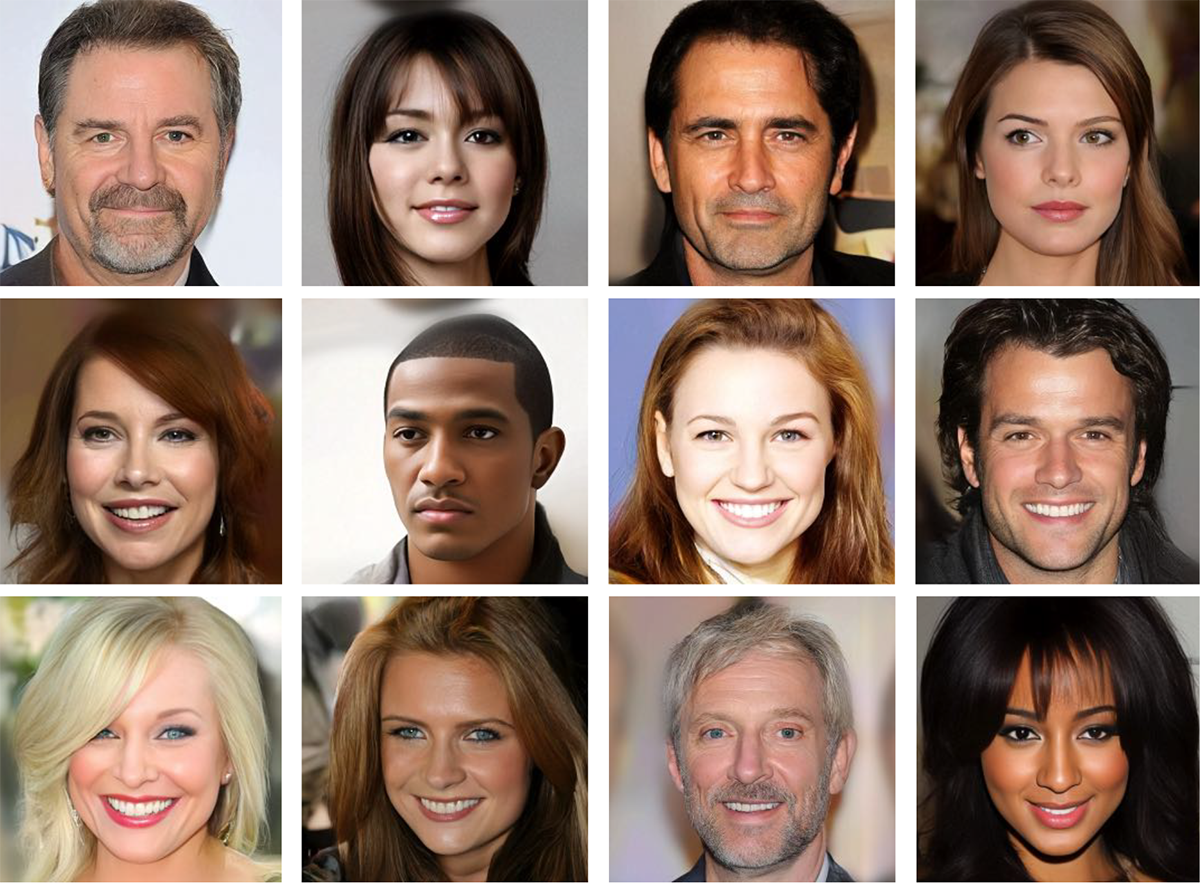 More generation results on CelebA HQ
Personal Takeaways
Looking at the training table below, we can see that the training cost is still quite large — larger even than a StyleGAN at the same resolution. And going through the whole paper, there are countless training tricks, big and small (and there are probably even more that didn't make it into the paper — though to be fair, StyleGAN and BigGAN also involve plenty of similar tricks, so this isn't really a shortcoming specific to NVAE). As a result, it's probably not easy for an individual to reproduce NVAE. So, for us ordinary folks with just a modest interest in generative models (like myself), what can we take away from NVAE?
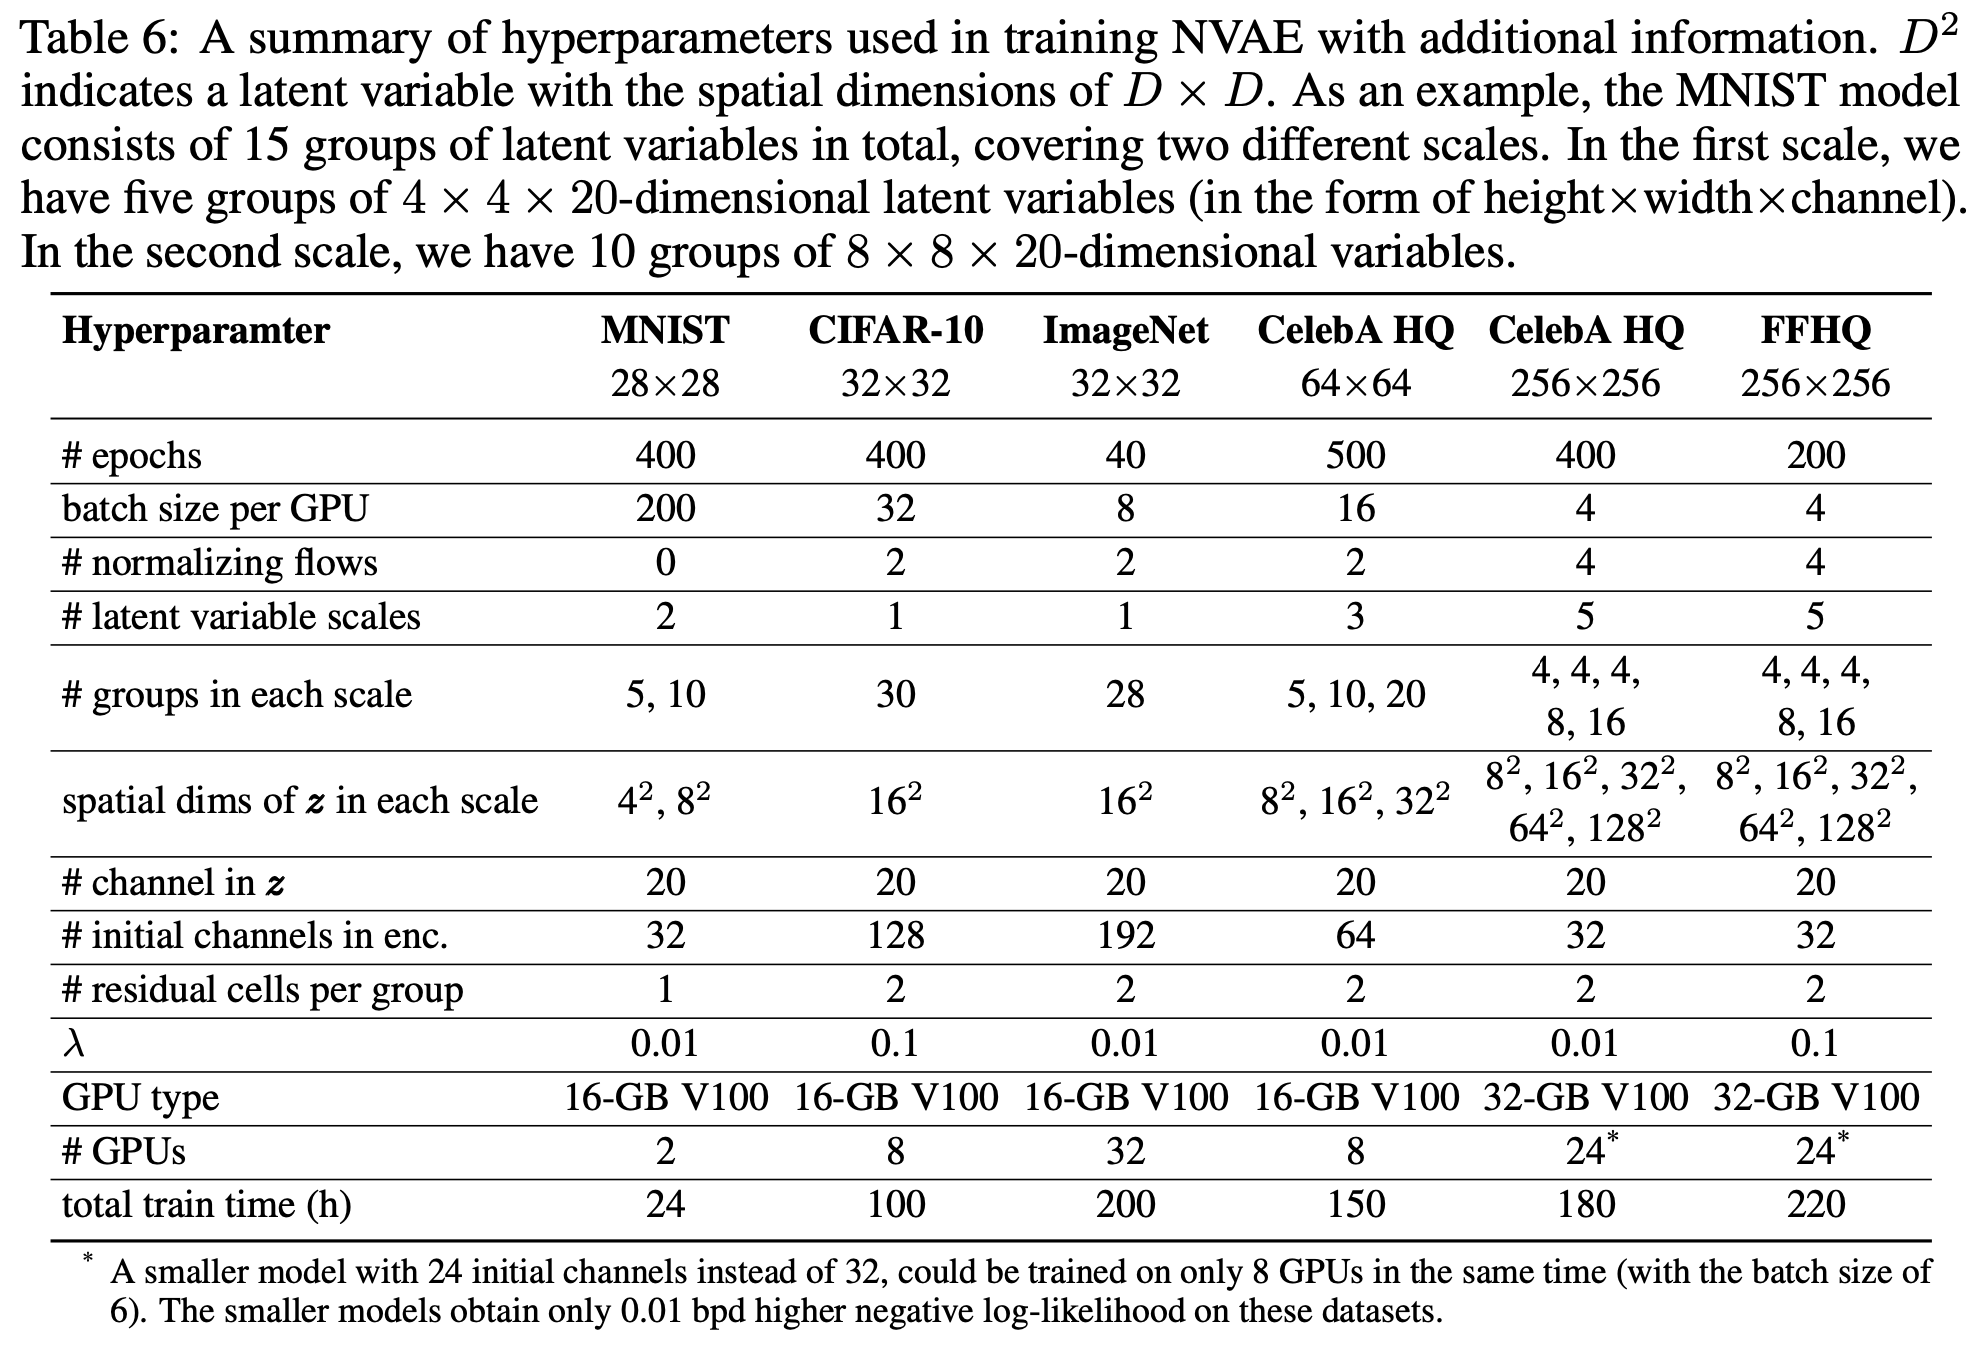 NVAE's training configuration and cost
Personally, NVAE brought me two main conceptual shocks.
First, autoregressive Gaussian models can powerfully fit complex continuous distributions. I used to think that only discrete distributions could be fit using autoregressive models, and so I believed that when encoding, one had to preserve a discrete encoding space — that is, the VQ-VAE route. But NVAE proves that even when the latent variables are continuous, autoregressive Gaussian distributions can still fit them very well. So we don't necessarily need to go down the discretized VQ-VAE path after all — continuous latent variables are, after all, easier to train than discrete ones.
Second, a VAE's latent variables don't have to be a single vector — they can be multiple, hierarchically organized groups. Look again at the table above, say the FFHQ column: regarding the latent variable $z$, there are $4+4+4+8+16=36$ groups in total, and the sizes of these groups aren't uniform — they are $\left\{8^2,16^2,32^2,64^2,128^2\right\}\times 20$. Adding this up, generating a $256\times 256$ FFHQ image requires a random vector with total dimensionality
\begin{equation}\left(4\times 8^2 + 4\times 16^2 + 4\times 32^2 + 8\times 64^2 + 16\times 128^2 \right)\times 20=6005760\end{equation}
In other words, you sample a roughly six-million-dimensional vector to generate a $256\times 256\times 3 = 196608$-dimensional vector (under 200,000 dimensions). This is quite different from a conventional VAE, which typically only encodes an image into a single vector of a few hundred dimensions — here the encoding vector is far larger, reminiscent of a fully convolutional autoencoder. So the improvement in image sharpness makes sense.
What Does "Nouveau" Mean?
Finally, out of curiosity, I looked up the meaning of "Nouveau." Here's the explanation from Wikipedia:
Nouveau (/nuːˈvoʊ/) is a free and open-source graphics device driver for Nvidia video cards and the Tegra family of systems-on-chip, written by a group of independent software engineers, with some assistance from Nvidia employees.
The project aims to create a high-quality, open-source driver for Nvidia cards through reverse engineering of Nvidia's proprietary Linux driver. It is managed by the freedesktop.org-hosted X.Org Foundation, and distributed as part of Mesa 3D. It originated as a fork of the free and open-source "nv" driver, which had support only for 2D acceleration, and its codebase was found to have been obfuscated by Red Hat developer Matthew Garrett and others. Nouveau is licensed under the MIT License.
The project's name comes from the French word "nouveau," meaning "new." The name was suggested by an autocomplete feature of the original author's IRC client, which suggested "nouveau" when they typed "nv."
So does that mean Nouveau VAE and Nvidia VAE are basically synonyms after all? Turns out our original interpretation wasn't wrong after all.
Summary
This post introduced NVIDIA's newly published upgraded VAE variant called NVAE, which pushes VAE-based generation to a new height. As we've seen, NVAE raises the theoretical ceiling by using an autoregressive form for the latent variable distributions, designs a clever encoder-decoder structure, and pulls together almost every state-of-the-art technique from current generative models — making it, currently, the strongest VAE around.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.