Lipschitz Constraints in Deep Learning: Generalization and Generative Models
Foreword: Last year I wrote an introductory piece on WGAN-GP, The Art of Mutual Trolling: Straight to WGAN-GP, which mentioned using gradient penalty to impose a Lipschitz constraint (abbreviated "L-constraint" below) on the WGAN discriminator. A few days ago, while musing, I thought about WGAN again, and I kept feeling that WGAN's gradient penalty wasn't elegant enough. I'd also heard that WGAN is hard to work with in conditional generation (because random interpolation between different classes ends up being a mess...), so I started wondering whether I could come up with a new scheme for imposing the L-constraint on the discriminator.
After mulling it over behind closed doors for a few days, I found that whatever I came up with, someone had already done it — truly, there's nothing you can think of that someone else hasn't already done. It's mainly covered in these two papers: Spectral Norm Regularization for Improving the Generalizability of Deep Learning and Spectral Normalization for Generative Adversarial Networks.
So this post will give a brief introduction to L-constraint-related content, following my own line of understanding. Note that the theme here is the L-constraint itself, not just WGAN — it can be used in generative models as well as in ordinary supervised learning.
L-Constraints and Generalization
Sensitivity to Perturbations
Let the input be $x$, the output $y$, and the model $f$ with parameters $w$, written as
$$\begin{equation}y = f_w(x)\end{equation}$$
Often we want to obtain a "robust" model. What does robustness mean? Generally it has two senses: one is stability with respect to parameter perturbations — for instance, if the model becomes $f_{w+\Delta w}(x)$, can it still achieve similar performance? In a dynamical system, we'd also want to know whether the model can eventually recover to $f_w(x)$. The other is stability with respect to input perturbations — for instance, if the input changes from $x$ to $x+\Delta x$, does $f_w(x+\Delta x)$ still give a similar prediction? Readers may have heard of "adversarial examples" for deep learning models, such as images where changing just one pixel produces a completely different classification result — this is a case of the model being overly sensitive to its input. more
The L-Constraint
So, most of the time we want the model to be insensitive to input perturbations, which typically improves the model's generalization performance. That is, when $\Vert x_1 - x_2 \Vert$ is small, we want
$$\begin{equation}\Vert f_w(x_1) - f_w(x_2)\Vert\end{equation}$$
to be as small as possible too. Of course, no one can say precisely what "as small as possible" should mean. This is where Lipschitz's idea comes in: a more concrete constraint requiring that there exists some constant $C$ (depending only on the parameters, not on the input) such that the following holds identically:
$$\begin{equation}\Vert f_w(x_1) - f_w(x_2)\Vert\leq C(w)\cdot \Vert x_1 - x_2 \Vert\label{eq:l-cond}\end{equation}$$
In other words, we want the entire model to be "dominated" by a linear function. This is the L-constraint.
In other words, here we regard a model satisfying the L-constraint as a good model. And for a specific model, we want to derive an expression for $C(w)$, and we want $C(w)$ to be as small as possible — the smaller it is, the less sensitive the model is to input perturbations, and the better its generalization.
Neural Networks
Let's now analyze a specific neural network to see under what conditions it satisfies the L-constraint.
For simplicity, consider a single fully-connected layer $f(Wx+b)$, where $f$ is the activation function and $W,b$ is the parameter matrix/vector. In this case $\eqref{eq:l-cond}$ becomes
$$\begin{equation}\Vert f(Wx_1+b) - f(Wx_2+b)\Vert\leq C(W,b)\cdot \Vert x_1 - x_2 \Vert\end{equation}$$
Letting $x_1,x_2$ be sufficiently close, we can approximate the left-hand side with a first-order term, giving
$$\begin{equation}\left\Vert \frac{\partial f}{\partial y}W(x_1 - x_2)\right\Vert\leq C(W,b)\cdot \Vert x_1 - x_2 \Vert\end{equation}$$
where $y=Wx_2 + b$. Clearly, for the left-hand side not to exceed the right-hand side, the absolute value of every element of $\partial f / \partial y$ must not exceed some constant. This requires us to use an activation function with "bounded derivative"; fortunately the activation functions we commonly use, such as sigmoid, tanh, and relu, all satisfy this condition. Assuming the gradient of the activation function is bounded — and for our commonly-used relu, this bound is in fact 1 — the term $\partial f / \partial y$ only contributes a constant factor, which we can ignore for now, leaving us to consider only $\Vert W(x_1 - x_2)\Vert$.
A multi-layer network can be analyzed recursively layer by layer, ultimately reducing to the single-layer case, and since CNNs, RNNs, etc. are essentially special forms of fully-connected structures, the same fully-connected result applies. So for neural networks, the problem becomes: if
$$\begin{equation}\Vert W(x_1 - x_2)\Vert\leq C\Vert x_1 - x_2 \Vert\label{sec:l-cond-nn}\end{equation}$$
holds identically, what value can $C$ take? Once we find an expression for C, we can try to make $C$ as small as possible, giving rise to a regularization term $C^2$ on the parameters.
Matrix Norms
Definition
At this point, we've reduced the problem to a matrix norm problem (a matrix norm plays the same role for matrices as magnitude does for vectors). It's defined as
$$\begin{equation}\Vert W\Vert_2 = \max_{x\neq 0}\frac{\Vert Wx\Vert}{\Vert x\Vert}\label{eq:m-norm}\end{equation}$$
If $W$ is a square matrix, this norm is also called the "spectral norm" or "spectral radius"; in this post, even when it isn't square, we'll still call it the "spectral norm." Note that $\Vert Wx\Vert$ and $\Vert x\Vert$ both refer to vector norms — the ordinary vector magnitude. The matrix norm on the left wasn't explicitly defined beforehand, but is instead defined via this limit involving vector norms, which is why this kind of matrix norm is called a "matrix norm induced by a vector norm."
Enough with the formalities — now that we have the concept of vector norm, we get
$$\begin{equation}\Vert W(x_1 - x_2)\Vert\leq \Vert W\Vert_2\cdot\Vert x_1 - x_2 \Vert\end{equation}$$
Well, we haven't really accomplished much, just changed notation; we still haven't worked out what $\Vert W\Vert_2$ equals.
Frobenius Norm
Actually, the precise definition and computation of the spectral norm $\Vert W\Vert_2$ require quite a bit of linear algebra. Let's set that aside for now and instead study a simpler norm first: the Frobenius norm, abbreviated F-norm.
The name sounds intimidating, but it's actually extremely simple to define:
$$\begin{equation}\Vert W\Vert_F = \sqrt{\sum_{i,j}w_{ij}^2}\end{equation}$$
In plain terms, it just treats the matrix as one long vector and computes its Euclidean magnitude.
Using the Cauchy–Schwarz inequality, it's straightforward to show
$$\begin{equation}\Vert Wx\Vert\leq \Vert W\Vert_F\cdot\Vert x \Vert\end{equation}$$
Clearly $\Vert W\Vert_F$ provides an upper bound for $\Vert W\Vert_2$ — that is, you can think of $\Vert W\Vert_2$ as the most precise value of $\eqref{sec:l-cond-nn}$ satisfying equation $C$ (the smallest $C$ among all those satisfying $\eqref{sec:l-cond-nn}$), but if you don't care too much about precision, you can simply take $C=\Vert W\Vert_F$, which will also make $\eqref{sec:l-cond-nn}$ hold — after all, $\Vert W\Vert_F$ is easy to compute.
The l2 Regularization Term
As mentioned earlier, in order for the neural network to satisfy the L-constraint as well as possible, we want $C=\Vert W\Vert_2$ to be as small as possible, and we can add $C^2$ as a regularization term to the loss function. We haven't yet computed the spectral norm $\Vert W\Vert_2$, but we've derived a larger upper bound $\Vert W\Vert_F$, so let's use that for now. The loss becomes
$$\begin{equation}loss = loss(y, f_w(x)) + \lambda \Vert W\Vert_F^2\label{eq:l2-regular}\end{equation}$$
where the first term is the model's original loss. Now let's go back and look at the expression for $\Vert W\Vert_F$, and we find that the regularization term we've added is
$$\begin{equation}\lambda\left(\sum_{i,j}w_{ij}^2\right)\end{equation}$$
Isn't this just l2 regularization?
At last, after all this tinkering, we get something out of it: we've revealed the connection between l2 regularization (also known as weight decay) and the L-constraint, showing that l2 regularization helps the model better satisfy the L-constraint, thereby reducing the model's sensitivity to input perturbations and improving its generalization performance.
Spectral Norm
The Dominant Eigenvalue
Now let's face the spectral norm $\Vert W\Vert_2$ head-on — this is linear algebra content and is fairly theoretical.
In fact, the spectral norm $\Vert W\Vert_2$ equals the square root of the largest eigenvalue (the dominant eigenvalue) of $W^{\top}W$; if $W$ is square, then $\Vert W\Vert_2$ equals the absolute value of the largest eigenvalue of $W$.
Note: for readers interested in the theoretical proof, here's a rough sketch. By definition $\eqref{eq:m-norm}$, we have
$$\Vert W\Vert_2^2 = \max_{x\neq 0}\frac{x^{\top}W^{\top} Wx}{x^{\top} x} = \max_{\Vert x\Vert=1}x^{\top}W^{\top} Wx$$
Suppose $W^{\top} W$ is diagonalized as $\text{diag}(\lambda_1,\dots,\lambda_n)$, i.e. $W^{\top} W=U^{\top}\text{diag}(\lambda_1,\dots,\lambda_n)U$, where $\lambda_i$ are its eigenvalues, all non-negative, and $U$ is an orthogonal matrix. Since an orthogonal matrix maps unit vectors to unit vectors, we have
$$\begin{aligned}\Vert W\Vert_2^2 =& \max_{\Vert x\Vert=1}x^{\top}\text{diag}(\lambda_1,\dots,\lambda_n) x \\ > =& \max_{\Vert x\Vert=1} \lambda_1 x_1^2 + \dots + \lambda_n x_n^2\\ > \leq & \max\{\lambda_1,\dots,\lambda_n\} (x_1^2 + \dots + x_n^2)\quad(\text{note}\Vert x\Vert=1)\\ > =&\max\{\lambda_1,\dots,\lambda_n\}\end{aligned}$$
from which it follows that $\Vert W\Vert_2^2$ equals the largest eigenvalue of $W^{\top} W$.
Power Iteration
Some readers are probably getting impatient by now: who cares whether it equals the eigenvalue — what I want to know is how to actually compute this darn norm!!
In fact, although the discussion above may seem abstract, it lays the foundation for computing $\Vert W\Vert_2$. The previous section tells us that $\Vert W\Vert_2^2$ is the largest eigenvalue of $W^{\top}W$, so the problem becomes finding the largest eigenvalue of $W^{\top}W$, which can be solved via the "power iteration" method.
So-called "power iteration" works via the following iterative scheme:
$$\begin{equation}u \leftarrow \frac{(W^{\top}W)u}{\Vert (W^{\top}W)u\Vert}\end{equation}$$
After several iterations, the norm is finally obtained (i.e., an approximation of the largest eigenvalue is obtained) via
$$\begin{equation}\Vert W\Vert_2^2\approx u^{\top}W^{\top}Wu\end{equation}$$
This can equivalently be rewritten as
$$\begin{equation}v\leftarrow \frac{W^{\top}u}{\Vert W^{\top}u\Vert},\,u\leftarrow \frac{Wv}{\Vert Wv\Vert},\quad \Vert W\Vert_2 \approx u^{\top}Wv\label{eq:m-norm-iter}\end{equation}$$
This way, after initializing $u,v$ (which can be initialized with an all-ones vector), we can iterate a few times to get $u,v$, and then plug it into $u^{\top}Wv$ to compute an approximation of $\Vert W\Vert_2$.
Note: for readers interested in the proof, here's a simple argument for why this iteration works.
Denote $A=W^{\top}W$, initialized as $u^{(0)}$, and again assume $A$ can be diagonalized, and further assume that among the eigenvalues $\lambda_1,\dots,\lambda_n$ of $A$, the largest eigenvalue is strictly greater than the rest (if this condition fails, it means the largest eigenvalue is repeated, which is more complex to discuss — interested readers should consult a rigorous proof; this is just meant to spark discussion. In practice, numerically, it's rare for two values to be exactly equal, so we can assume this degenerate case doesn't arise experimentally). Then the eigenvectors $\eta_1,\dots,\eta_n$ of $A$ form a complete basis, so we can write
$$u^{(0)} = c_1 \eta_1 + \dots + c_n \eta_n$$
Each iteration step is $Au/\Vert Au\Vert$, where the denominator only changes the magnitude — let's set that aside and handle it at the end, and just look at the repeated action of $A$:
$$A^r u^{(0)} = c_1 A^r \eta_1 + \dots + c_n A^r \eta_n$$
Note that for eigenvectors we have $A\eta = \lambda \eta$, so
$$A^r u^{(0)} = c_1 \lambda_1^r \eta_1 + \dots + c_n \lambda_n^r \eta_n$$
Without loss of generality, let $\lambda_1$ be the largest eigenvalue, so
$$\frac{A^r u^{(0)}}{\lambda_1^r} = c_1 \eta_1 + c_2 \left(\frac{\lambda_2}{\lambda_1}\right)^r \eta_2 + \dots + c_n \left(\frac{\lambda_n}{\lambda_1}\right)^r \eta_n$$
By assumption, all the $\lambda_2/\lambda_1,\dots,\lambda_n /\lambda_1$ are less than 1, so as $r\to\infty$, they all tend to zero — or rather, when $r$ is large enough they become negligible, giving
$$\frac{A^r u^{(0)}}{\lambda_1^r} \approx c_1 \eta_1$$
Ignoring magnitude for the moment, this result shows that when $r$ is large enough, $A^r u^{(0)}$ gives an approximation of the direction of the eigenvector corresponding to the largest eigenvalue; the normalization at each step is really just there to prevent overflow. Thus $u = A^r u^{(0)}/\Vert A^r u^{(0)}\Vert$ is the corresponding unit eigenvector, i.e.
$$Au=\lambda_1 u$$
and therefore
$$u^{\top}Au=\lambda_1 u^{\top}u=\lambda_1$$
which gives us the square of the spectral norm.
Spectral Regularization
Earlier we showed the connection between the Frobenius norm and l2 regularization, and we noted that the Frobenius norm gives a stronger (cruder) bound, while the more precise norm should be the spectral norm. Although the spectral norm isn't as easy to compute as the Frobenius norm, it can still be approximated by a few iterations of $\eqref{eq:m-norm-iter}$.
So, we can propose the concept of "Spectral Norm Regularization": using the square of the spectral norm as an additional regularization term, replacing the simple l2 term. That is, equation $\eqref{eq:l2-regular}$ becomes
$$\begin{equation}loss = loss(y, f_w(x)) + \lambda \Vert W\Vert_2^2\end{equation}$$
Spectral Norm Regularization for Improving the Generalizability of Deep Learning presents a number of experiments showing that "spectral regularization" improves model performance across multiple tasks.
In Keras, the spectral norm can be computed with the following code:
def spectral_norm(w, r=5):
    w_shape = K.int_shape(w)
    in_dim = np.prod(w_shape[:-1]).astype(int)
    out_dim = w_shape[-1]
    w = K.reshape(w, (in_dim, out_dim))
    u = K.ones((1, in_dim))
    for i in range(r):
        v = K.l2_normalize(K.dot(u, w))
        u = K.l2_normalize(K.dot(v, K.transpose(w)))
    return K.sum(K.dot(K.dot(u, w), K.transpose(v)))
Generative Models
WGAN
Whereas in ordinary supervised training the L-constraint is only "icing on the cake," in the WGAN discriminator the L-constraint is an indispensable, crucial step. This is because the optimization objective of the WGAN discriminator is
$$\begin{equation}W(P_r,P_g)=\sup_{|f|_L = 1}\mathbb{E}_{x\sim P_r}[f(x)] - \mathbb{E}_{x\sim P_g}[f(x)]\end{equation}$$
Here $P_r,P_g$ are the real distribution and the generated distribution respectively, and $|f|_L = 1$ means that a specific L-constraint $|f(x_1) - f(x_2)| \leq \Vert x_1 - x_2\Vert$ (that $C=1$) must be satisfied. So the objective above means: among all functions satisfying this L-constraint, pick the $f$ that maximizes $\mathbb{E}_{x\sim P_r}[f(x)] - \mathbb{E}_{x\sim P_g}[f(x)]$ — that is the ideal discriminator. Written as a loss, this is
$$\begin{equation}\min_{|f|_L = 1} \mathbb{E}_{x\sim P_g}[f(x)] - \mathbb{E}_{x\sim P_r}[f(x)]\end{equation}$$
Gradient Penalty
One reasonably effective scheme currently is the gradient penalty: since $\Vert f'(x)\Vert = 1$ is a sufficient condition for $|f|_L = 1$, we add this term to the discriminator's loss as a penalty, i.e.
$$\begin{equation}\min_{f} \mathbb{E}_{x\sim P_g}[f(x)] - \mathbb{E}_{x\sim P_r}[f(x)] + \lambda (\Vert f'(x_{inter})\Vert-1)^2\end{equation}$$
Actually, I think it's better to add a $relu(x)=\max(x,0)$:
$$\begin{equation}\min_{f} \mathbb{E}_{x\sim P_g}[f(x)] - \mathbb{E}_{x\sim P_r}[f(x)] + \lambda \max(\Vert f'(x_{inter})\Vert-1, 0)^2\end{equation}$$
where $x_{inter}$ is obtained via random interpolation:
$$\begin{equation}\begin{aligned}&x_{inter} = \varepsilon x_{real} + (1 - \varepsilon) x_{fake}\\ &\varepsilon\sim U[0,1],\quad x_{real}\sim P_r,\quad x_{fake}\sim P_g \end{aligned}\end{equation}$$
Gradient penalty doesn't guarantee $\Vert f'(x)\Vert = 1$, but intuitively it will fluctuate around 1, so $|f|_L$ will also theoretically fluctuate around 1, approximately achieving the L-constraint.
This scheme works reasonably well in many cases, but performs poorly when there are many classes among the real samples (especially in conditional generation). The problem lies in the random interpolation: in principle, the L-constraint needs to hold over the entire space, but the gradient penalty via linear interpolation can only guarantee it holds in a small subregion of space. If that small subregion happens to roughly coincide with the region between real and generated samples, it's barely sufficient — but if there are many classes, interpolating between different classes often lands somewhere unpredictable, causing the L-constraint to be violated exactly where it needs to hold, and the discriminator breaks down.
A thought: could the gradient penalty be used directly as a regularization term for supervised models? Readers who are interested might want to experiment with this.
Spectral Normalization
The problem with gradient penalty is that it's just a penalty, only effective locally. The truly elegant approach is a constructive one: build a special $f$ such that, no matter what the parameters inside $f$ are, $f$ always satisfies the L-constraint.
In fact, the original WGAN paper used weight clipping — clipping the absolute value of all parameters to not exceed some constant — so that the Frobenius norm of the parameters doesn't exceed some constant, and hence $|f|_L$ doesn't exceed some constant. Although this doesn't precisely achieve $|f|_L=1$, it only scales the loss by a constant factor and thus doesn't affect the optimization result. Weight clipping is one kind of constructive approach, though it isn't very friendly to optimization.
Roughly speaking, there's a lot of room to improve on this clipping scheme — for instance, clipping the Frobenius norm of all the parameters to not exceed some constant instead, which gives the model more flexibility than direct weight clipping. If clipping feels too crude, one could instead use a parameter penalty, imposing a large penalty on any parameters whose norm exceeds the Frobenius norm bound; I've tried this too, and it's basically effective, though convergence is slower.
However, all of the above are just approximations. Now that we have the spectral norm, we can use the most precise scheme: replace every parameter in $f$ with $w/\Vert w\Vert_2$. This is Spectral Normalization, proposed and tested in Spectral Normalization for Generative Adversarial Networks. This way, if the activation functions used in $f$ all have derivatives whose absolute value doesn't exceed 1, then we have $|f|_L\leq 1$, achieving the required L-constraint via the most precise scheme available.
Note: "the absolute value of the derivative of the activation function doesn't exceed 1" is usually satisfied, but if the discriminator uses a residual structure, then the effective activation function becomes $x + relu(Wx+b)$, and in that case its derivative isn't necessarily bounded by 1. Either way, though, it will still be bounded by some constant, so it doesn't affect the optimization result.
I've personally tried using spectral normalization in WGAN (without gradient penalty; see the reference code below), and found that the final convergence speed (number of epochs needed to reach the same quality) was even faster than WGAN-GP, with somewhat better results too. There's also another factor affecting speed: the per-epoch runtime. Gradient penalty takes longer than spectral normalization, because using gradient penalty effectively requires computing a second-order gradient during gradient descent, requiring the entire forward pass to be run twice — hence the slower speed.
Keras Implementation
In Keras, implementing spectral normalization can be described as either simple or not-so-simple.
The simple part: you just need to pass a kernel_constraint argument to every convolutional and fully-connected layer in the discriminator, and a gamma_constraint argument to the BN layer. The constraint is written as
def spectral_normalization(w):
    return w / spectral_norm(w)
Reference code:
https://github.com/bojone/gan/blob/master/keras/wgan_sn_celeba.py
The not-so-simple part is that in the current version of Keras (2.2.4), kernel_constraint doesn't actually modify the kernel directly — it only adjusts the kernel's value after gradient descent, which is different from how spectral_normalization is applied in the paper. If you use it this way, you'll find that gradients become inaccurate later in training, and the generation quality suffers. To truly modify the kernel, we'd either need to redefine every layer (convolution, fully-connected, BN, and any other layer involving matrix multiplication), or else modify the source code directly — modifying the source is the simplest option. We modify the add_weight method of the Layer object in keras/engine/base_layer.py (currently starting at line 222), which originally reads:
    def add_weight(self,
                   name,
                   shape,
                   dtype=None,
                   initializer=None,
                   regularizer=None,
                   trainable=True,
                   constraint=None):
        """Adds a weight variable to the layer.
        # Arguments
            name: String, the name for the weight variable.
            shape: The shape tuple of the weight.
            dtype: The dtype of the weight.
            initializer: An Initializer instance (callable).
            regularizer: An optional Regularizer instance.
            trainable: A boolean, whether the weight should
                be trained via backprop or not (assuming
                that the layer itself is also trainable).
            constraint: An optional Constraint instance.
        # Returns
            The created weight variable.
        """
        initializer = initializers.get(initializer)
        if dtype is None:
            dtype = K.floatx()
        weight = K.variable(initializer(shape),
                            dtype=dtype,
                            name=name,
                            constraint=constraint)
        if regularizer is not None:
            with K.name_scope('weight_regularizer'):
                self.add_loss(regularizer(weight))
        if trainable:
            self._trainable_weights.append(weight)
        else:
            self._non_trainable_weights.append(weight)
        return weight
and change it to:
    def add_weight(self,
                   name,
                   shape,
                   dtype=None,
                   initializer=None,
                   regularizer=None,
                   trainable=True,
                   constraint=None):
        """Adds a weight variable to the layer.
        # Arguments
            name: String, the name for the weight variable.
            shape: The shape tuple of the weight.
            dtype: The dtype of the weight.
            initializer: An Initializer instance (callable).
            regularizer: An optional Regularizer instance.
            trainable: A boolean, whether the weight should
                be trained via backprop or not (assuming
                that the layer itself is also trainable).
            constraint: An optional Constraint instance.
        # Returns
            The created weight variable.
        """
        initializer = initializers.get(initializer)
        if dtype is None:
            dtype = K.floatx()
        weight = K.variable(initializer(shape),
                            dtype=dtype,
                            name=name,
                            constraint=None)
        if regularizer is not None:
            with K.name_scope('weight_regularizer'):
                self.add_loss(regularizer(weight))
        if trainable:
            self._trainable_weights.append(weight)
        else:
            self._non_trainable_weights.append(weight)
        if constraint is not None:
            return constraint(weight)
        return weight
That is, we change K.variable's constraint to None, and apply the constraint at the very end instead. Note: don't jump to complaining that Keras is too rigidly encapsulated or inflexible just because we had to modify the source — if you tried this in another framework, it would basically take you many times more effort (relative to the changes needed for a GAN without spectral_normalization).
(Update: a new implementation that doesn't require modifying the source code is available here.)
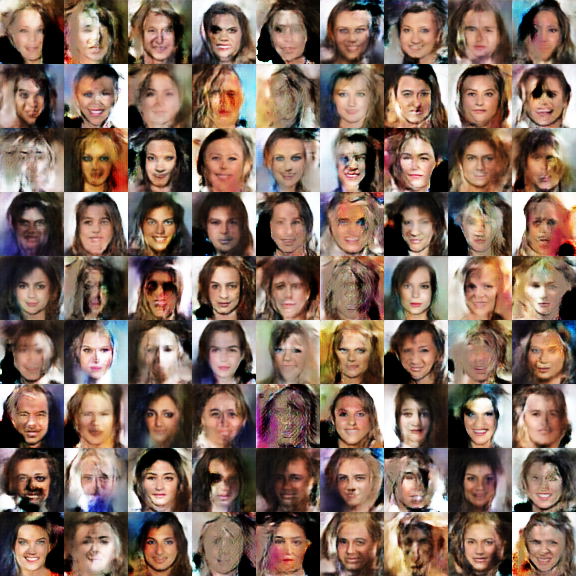 wgan-sn results before modifying the source code
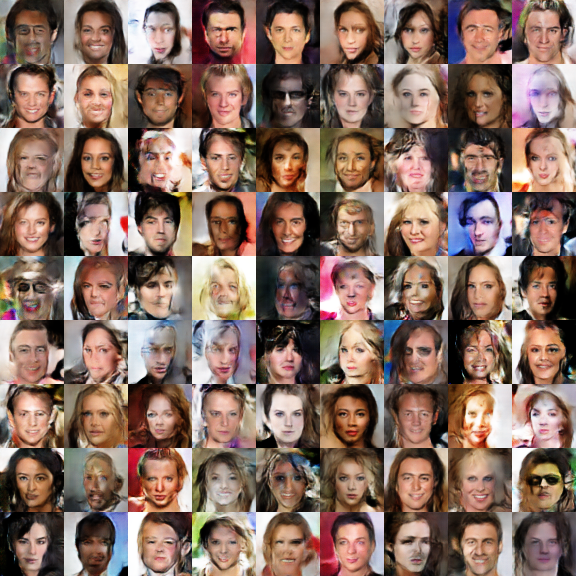 wgan-sn results after modifying the source code
Summary
This post is a summary of the Lipschitz constraint, focusing mainly on how to make models better satisfy the Lipschitz constraint, which relates directly to a model's generalization ability. The trickiest concept involved is the spectral norm, which requires quite a bit of theory and formal machinery.
Overall, the material related to the spectral norm is quite elegant, and the results here further show just how tightly linear algebra is connected to machine learning — many "advanced" topics in linear algebra turn out to have corresponding applications in machine learning.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.