Newton-Schulz Iteration for the msign Operator (Part 1)
In earlier posts such as Appreciating the Muon Optimizer: A Leap in Essence from Vectors to Matrices and Muon Sequel: Why Did We Choose to Try Muon?, we introduced a highly promising emerging optimizer that has the potential to replace Adam — "Muon". As research on this topic keeps deepening, Muon is receiving more and more attention.
Readers already familiar with Muon know that its core operation is the $\newcommand{msign}{\mathop{\text{msign}}}\msign$ operator, and finding more efficient ways to compute it has become an ongoing goal of the academic community. This post summarizes the latest progress on this front.
Preliminaries
The definition of $\msign$ is closely tied to SVD. Suppose the matrix $\boldsymbol{M}\in\mathbb{R}^{n\times m}$, then
\begin{equation}\boldsymbol{U},\boldsymbol{\Sigma},\boldsymbol{V}^{\top} = \text{SVD}(\boldsymbol{M}) \quad\Rightarrow\quad \msign(\boldsymbol{M}) = \boldsymbol{U}_{[:,:r]}\boldsymbol{V}_{[:,:r]}^{\top}\end{equation}
where $\boldsymbol{U}\in\mathbb{R}^{n\times n},\boldsymbol{\Sigma}\in\mathbb{R}^{n\times m},\boldsymbol{V}\in\mathbb{R}^{m\times m}$, and $r$ is the rank of $\boldsymbol{M}$. In simple terms, $\msign$ is the new matrix obtained by turning every nonzero singular value of the matrix into 1. Based on SVD, we can also prove that
\begin{equation}\text{msign}(\boldsymbol{M}) = (\boldsymbol{M}\boldsymbol{M}^{\top})^{-1/2}\boldsymbol{M}= \boldsymbol{M}(\boldsymbol{M}^{\top}\boldsymbol{M})^{-1/2}\end{equation}
Here $^{-1/2}$ is the $-1/2$-th power of the matrix. This form is quite similar to the scalar $\mathop{\text{sign}}(x) = x / \sqrt{x^2}$, which is why the author named it $\msign$. Note, however, that this is not exactly the same as Wikipedia's "Matrix Sign", which only applies to square matrices — though the two coincide when $\boldsymbol{M}$ is a symmetric matrix.
When $m=n=r$, $\text{msign}(\boldsymbol{M})$ also has the meaning of being the "optimal orthogonal approximation":
\begin{equation}\text{msign}(\boldsymbol{M}) = \mathop{\text{argmin}}_{\boldsymbol{O}^{\top}\boldsymbol{O} = \boldsymbol{I}}\Vert \boldsymbol{M} - \boldsymbol{O}\Vert_F^2\end{equation}
The proof can be found in Appreciating the Muon Optimizer: A Leap in Essence from Vectors to Matrices. Because of this property, $\msign$ is also called "symmetric orthogonalization", a name that first appeared in On the Nonorthogonality Problem (see also the "Orthogonalization" entry on Wikipedia).
Finally, in Higher-Order MuP: A Simpler yet Smarter Spectral Condition Scaling, the author also regarded $\msign$ as the limiting case of "singular value clipping".
Iterative Computation
Since $\msign$ is defined via SVD, it can naturally be computed exactly by performing SVD directly. However, exact SVD computation is fairly expensive, so in practice it is usually approximated via the "Newton-Schulz iteration".
The Newton-Schulz iteration is a common iterative algorithm for computing matrix functions. For $\msign$, its iteration scheme is
\begin{equation}\boldsymbol{X}_0 = \frac{\boldsymbol{M}}{\Vert\boldsymbol{M}\Vert_F},\qquad \boldsymbol{X}_{t+1} = a\boldsymbol{X}_t + b\boldsymbol{X}_t(\boldsymbol{X}_t^{\top}\boldsymbol{X}_t) + c\boldsymbol{X}_t(\boldsymbol{X}_t^{\top}\boldsymbol{X}_t)^2+\cdots\end{equation}
where $\Vert\boldsymbol{M}\Vert_F$ is the $F$-norm of $\boldsymbol{M}$, i.e., the square root of the sum of squares of all its elements, and $(a,b,c,\cdots)$ are coefficients to be determined. In practice we need to truncate to a finite number of terms — commonly 2 or 3 terms, i.e., one of the following two choices:
\begin{gather}\boldsymbol{X}_{t+1} = a\boldsymbol{X}_t + b\boldsymbol{X}_t(\boldsymbol{X}_t^{\top}\boldsymbol{X}_t) \\[8pt] \boldsymbol{X}_{t+1} = a\boldsymbol{X}_t + b\boldsymbol{X}_t(\boldsymbol{X}_t^{\top}\boldsymbol{X}_t) + c\boldsymbol{X}_t(\boldsymbol{X}_t^{\top}\boldsymbol{X}_t)^2\label{eq:power-5}\end{gather}
Finally, after $T$ iteration steps, $\boldsymbol{X}_T$ is returned as the approximation to $\msign(\boldsymbol{M})$. This way, the coefficients $(a,b,c)$ and the number of iteration steps $T$ together constitute all the hyperparameters of the Newton-Schulz iteration. Muon's author KellerJordan gives the following reference choice:
\begin{equation}(a,b,c)=(3.4445, -4.7750, 2.0315),\qquad T = 5\end{equation}
Our task in what follows is to understand this choice, and then try to improve it.
Reference Implementation
Here is a minimal reference implementation:
def msign(x, steps=5, eps=1e-20):
    a, b, c, y = 3.4445, -4.7750, 2.0315, x.astype('bfloat16')
    y = y.mT if x.shape[-2] > x.shape[-1] else y
    y /= ((y**2).sum(axis=(-2, -1), keepdims=True) + eps)**0.5
    for _ in range(steps):
        y = a * y + (b * (y2 := y @ y.mT) + c * y2 @ y2) @ y
    return y.mT if x.shape[-2] > x.shape[-1] else y
This implementation already supports batched execution (only the last two dims undergo $\msign$), and runs directly in Jax; changing x.astype('bfloat16') to x.to(torch.bfloat16) makes it run in Torch, and simply changing x.astype('bfloat16') to x makes it run in Numpy.
Analysis of the Principle
To understand why the Newton-Schulz iteration works, let's analyze its steps one by one. First, $\boldsymbol{X}_0 = \boldsymbol{M}/\Vert\boldsymbol{M}\Vert_F$: substituting the SVD of $\boldsymbol{M}$ gives
\begin{equation}\boldsymbol{X}_0 = \frac{\boldsymbol{M}}{\Vert\boldsymbol{M}\Vert_F} = \boldsymbol{U}_{[:,:r]}\left(\frac{\boldsymbol{\Sigma}_{[:r,:r]}}{\Vert\boldsymbol{M}\Vert_F}\right)\boldsymbol{V}_{[:,:r]}^{\top} = \boldsymbol{U}_{[:,:r]}\underbrace{\left(\frac{\boldsymbol{\Sigma}_{[:r,:r]}}{\Vert\boldsymbol{\Sigma}_{[:r,:r]}\Vert_F}\right)}_{\boldsymbol{S}_0}\boldsymbol{V}_{[:,:r]}^{\top}\end{equation}
The last equality holds because the square of the $F$-norm equals both the sum of squares of all entries and the sum of squares of all singular values. The result shows that $\boldsymbol{S}_0$ is a diagonal matrix whose entries all lie in $[0,1]$, in other words, all singular values of $\boldsymbol{X}_0=\boldsymbol{U}_{[:,:r]}\boldsymbol{S}_0\boldsymbol{V}_{[:,:r]}^{\top}$ do not exceed 1 — this is exactly the purpose of the first step, $\boldsymbol{X}_0 = \boldsymbol{M}/\Vert\boldsymbol{M}\Vert_F$.
Next, substituting $\boldsymbol{U}_{[:,:r]}\boldsymbol{S}_t\boldsymbol{V}_{[:,:r]}^{\top}$ into equation $\eqref{eq:power-5}$ gives
\begin{equation}\boldsymbol{X}_{t+1} = \boldsymbol{U}_{[:,:r]}\left(a\boldsymbol{S}_t + b\boldsymbol{S}_t^3 + c\boldsymbol{S}_t^5\right)\boldsymbol{V}_{[:,:r]}^{\top}\end{equation}
That is, the iteration does not change the left and right factors $\boldsymbol{U}_{[:,:r]}$ and $\boldsymbol{V}_{[:,:r]}^{\top}$; in essence it is an iteration on the diagonal matrix
\begin{equation}\boldsymbol{S}_{t+1} = a\boldsymbol{S}_t + b\boldsymbol{S}_t^3 + c\boldsymbol{S}_t^5\end{equation}
and since powers of a diagonal matrix are equivalent to taking powers of each diagonal entry individually, this in turn is equivalent to the scalar iteration on $x_t$:
\begin{equation}x_{t+1} = a x_t + b x_t^3 + c x_t^5\end{equation}
Since $\boldsymbol{X}_0 = \boldsymbol{M}/\Vert\boldsymbol{M}\Vert_F$ has already compressed all singular values into $(0,1]$, we want that, starting from any $x_0\in(0,1]$, after $T$ iteration steps $x_T$ gets as close to 1 as possible, so that the iterate $\eqref{eq:power-5}$ is a sufficiently good approximation to $\msign$. In this way, we've reduced the analysis of the matrix iteration to the analysis of a scalar iteration, which greatly simplifies things.
Solving via Optimization
The problem of solving for $a,b,c$ was already briefly discussed in Appreciating the Muon Optimizer: A Leap in Essence from Vectors to Matrices, when Muon was first introduced. The basic idea is to treat $a,b,c$ as optimizable parameters, build a loss from the difference between $x_T$ and $1$, and optimize with SGD.
The approach in this post is largely the same, but with some adjustments. Clearly the optimization result will depend on the distribution of singular values. Previously the author's approach was to simulate a realistic singular-value distribution using the SVD of random matrices, but SVD is costly, and the results also end up depending on the matrix shape. On reflection this seems unnecessary, so instead we sample points uniformly within $[0,1]$, and then pick the $k$ points with the largest $|x_T-1|$ to construct the loss. This turns the problem into a $\min\text{-}\max$ problem, minimizing the influence of the singular-value distribution as much as possible:
import jax
import jax.numpy as jnp
from tqdm import tqdm

def loss(w, x, k=50):
    for a, b, c in [w] * iters:
        x = a * x + b * x**3 + c * x**5
    return jnp.abs(x - 1).sort()[-k:].mean()

@jax.jit
def grad(w, x, tol=0.1):
    G = lambda w, x: (g := jax.grad(loss)(w, x)) / jnp.fmax(jnp.linalg.norm(g), 1)
    return 0.6 * G(w, x) + 0.2 * (G(w + tol / 2, x) + G(w - tol / 2, x))

iters = 5
x = jnp.linspace(0, 1, 10001)[1:]
w = jnp.array([1.5, -0.5, 0])
m, v = jnp.zeros_like(w), jnp.zeros_like(w)
lr = 1e-3
pbar = tqdm(range(20000), ncols=0, desc='Adam')

for i in pbar:
    l, g = loss(w, x), grad(w, x)
    m = 0.9 * m + 0.1 * g
    v = 0.999 * v + 0.001 * g**2
    w = w - lr * m / jnp.sqrt(v + 1e-20)
    pbar.set_description(f'Loss: {l:.6f}, LR: {lr:.6f}')
    if i in [10000]:
        lr *= 0.1
In addition, we switch the optimizer from SGD to Adam, which makes it easier to control the magnitude of parameter updates. To also improve robustness to noise in the solution, we add some perturbation to $a,b,c$ and mix the gradient computed on the perturbed version in as well. The optimization result from the above script is:
\begin{equation}(a,b,c)=(3.3748, -4.6969, 2.1433)\end{equation}
This is fairly close to KellerJordan's solution. Let's compare the two more closely with a plot:
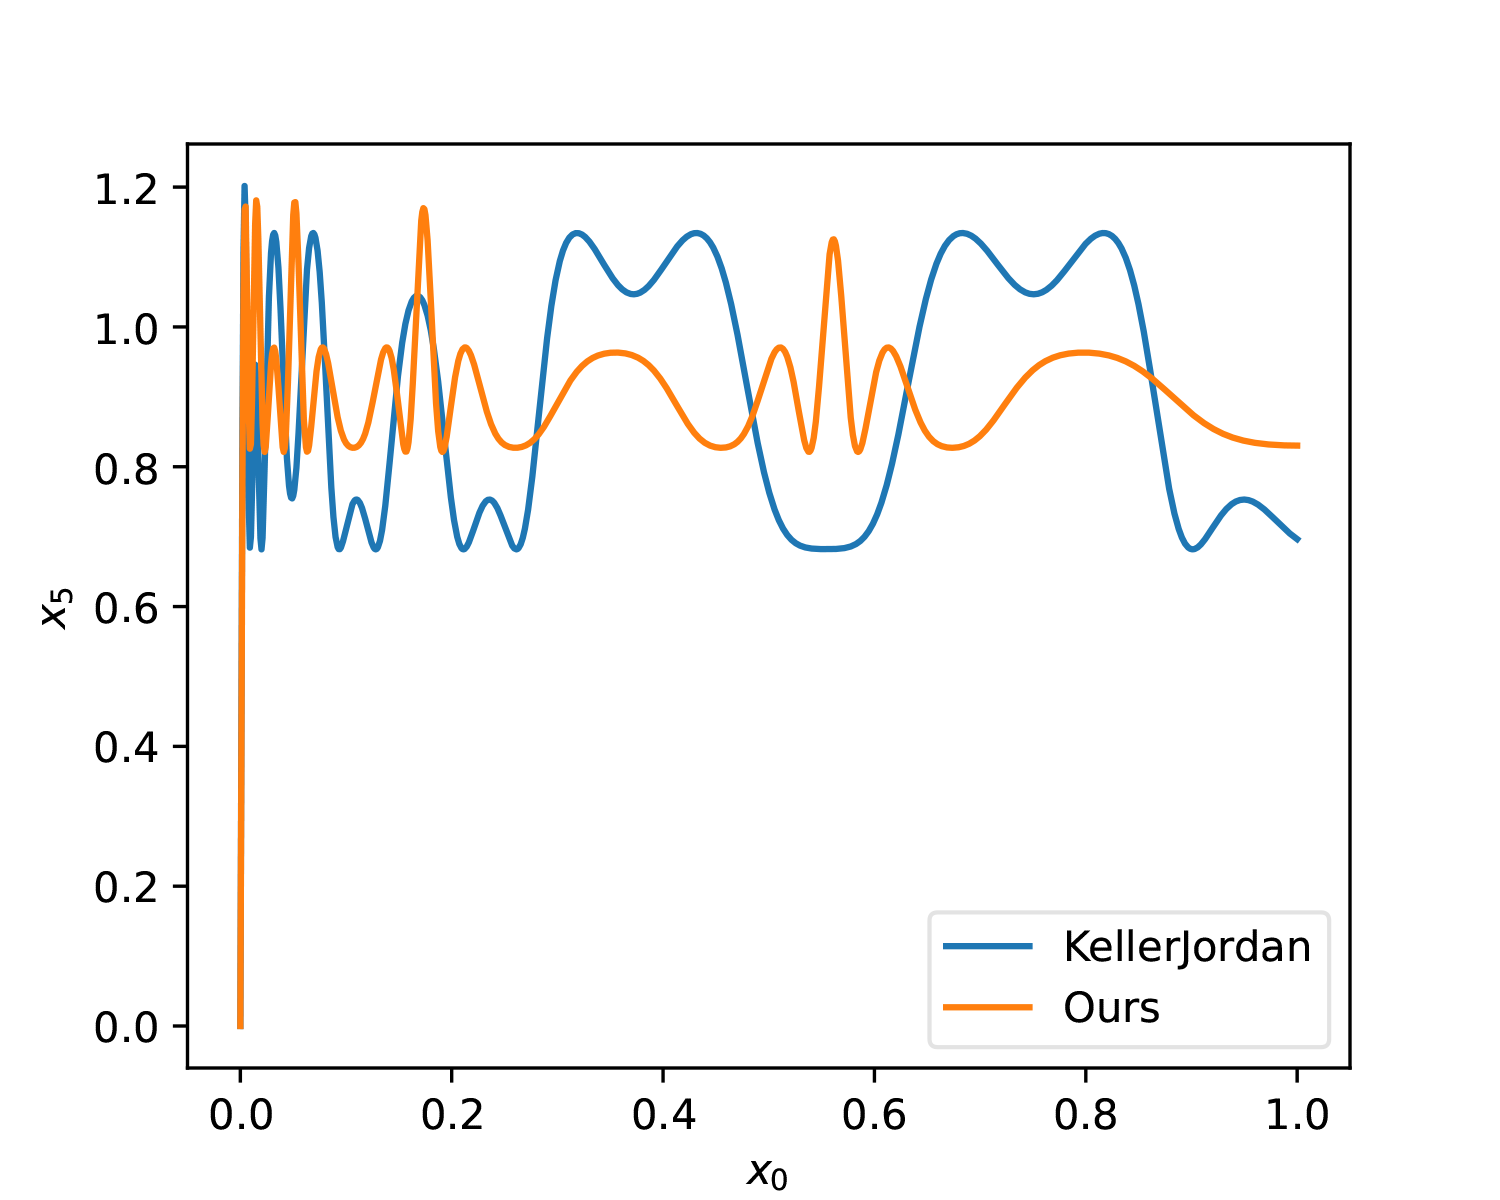 Approximation over [0, 1]
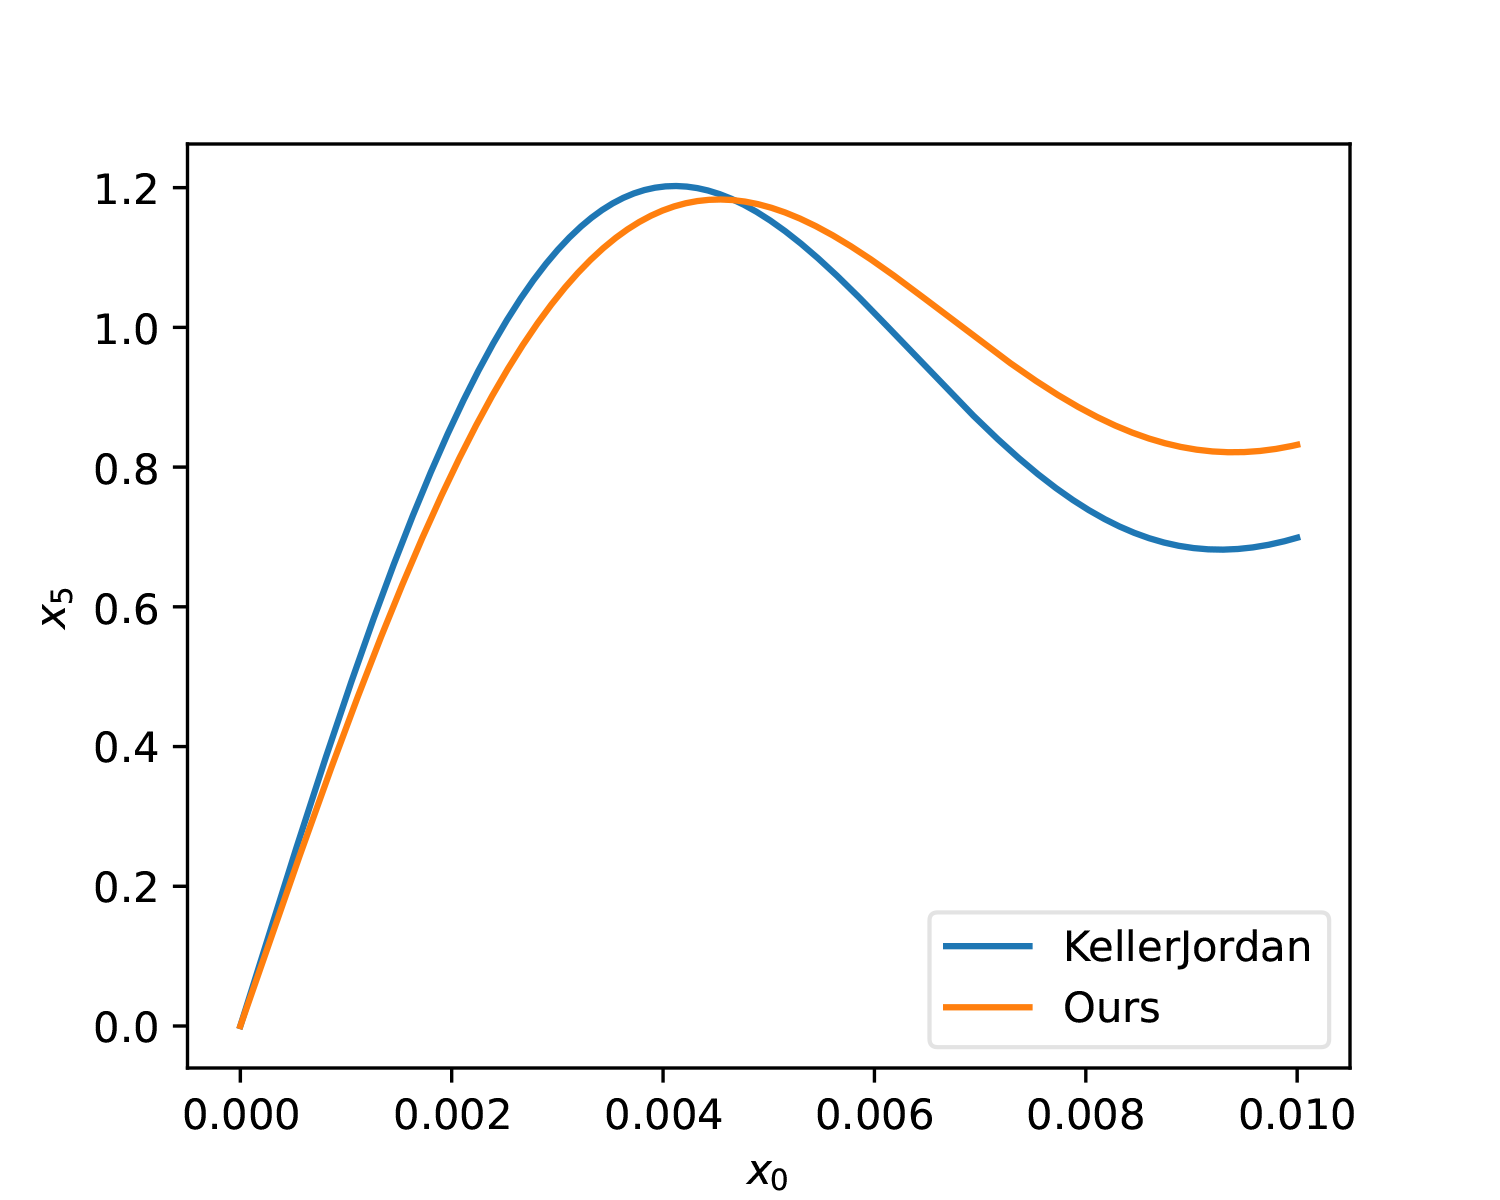 Approximation over [0, 0.01]
We can see that, globally, the solution found here has a slightly smaller average error, whereas the advantage of KellerJordan's solution is a somewhat steeper slope in the $[0, 0.01]$ range, which means it is more favorable for smaller singular values.
The Distribution of Initial Values
Before going further, we need to clarify a question: exactly how small a singular value do we actually need to care about? This comes back to the distribution of $\boldsymbol{S}_0$. Since $\boldsymbol{S}_0$ is normalized by the $F$-norm, $\mathop{\text{diag}}(\boldsymbol{S}_0)$ is essentially a unit vector of dimension $r$. If all singular values were equal, each singular value would work out to be $1/\sqrt{r}$.
By the pigeonhole principle, then, in the non-uniform case there must exist singular values smaller than $1/\sqrt{r}$. To be safe, we can consider some multiple of this, say 10×, meaning we should at least account for singular values of magnitude $0.1/\sqrt{r}$. In practice, the probability that a matrix is strictly low-rank (i.e., has singular values exactly equal to 0) is very small, so we generally assume the matrix is full rank, i.e., $r = \min(n,m)$, and hence must account at minimum for singular values of magnitude $0.1/\sqrt{\min(n,m)}$.
Given that the largest LLMs today have hidden sizes on the order of $8192\sim 100^2$, this estimate implies that a general-purpose Muon optimizer's $\msign$ algorithm needs to account for singular values as small as $0.001$, i.e., it needs to be able to map $0.001$ to a value close to 1. By this standard, neither the KellerJordan solution nor our newly derived solution is quite good enough.
Note: for further discussion of the distribution of initial values, see Iterative Orthogonalization Scaling Laws.
Removing the Constraint
At this point, @YouJiacheng (one of the main drivers of Muon) on Twitter proposed a very clever idea: we can use a different set of coefficients at each iteration step! That is, we change the iteration to
\begin{equation}\boldsymbol{X}_{t+1} = a_{t+1}\boldsymbol{X}_t + b_{t+1}\boldsymbol{X}_t(\boldsymbol{X}_t^{\top}\boldsymbol{X}_t) + c_{t+1}\boldsymbol{X}_t(\boldsymbol{X}_t^{\top}\boldsymbol{X}_t)^2\end{equation}
The nice thing about this change is that, once $T$ is fixed, the total computational cost doesn't change at all, but from a fitting perspective, whereas before we only had $3$ trainable parameters, now we have $3T$, greatly increasing the fitting capacity. He himself gives a reference solution for a 6-step iteration:
$$\begin{array}{c|ccc} \hline t & a & b & c \\ \hline \quad 1\quad & 3955/1024 & -8306/1024 & 5008/1024 \\ 2 & 3735/1024 & -6681/1024 & 3463/1024 \\ 3 & 3799/1024 & -6499/1024 & 3211/1024 \\ 4 & 4019/1024 & -6385/1024 & 2906/1024 \\ 5 & 2677/1024 & -3029/1024 & 1162/1024 \\ 6 & 2172/1024 & -1833/1024 & 682/1024 \\ \hline \end{array}$$
Let's plot it for comparison:
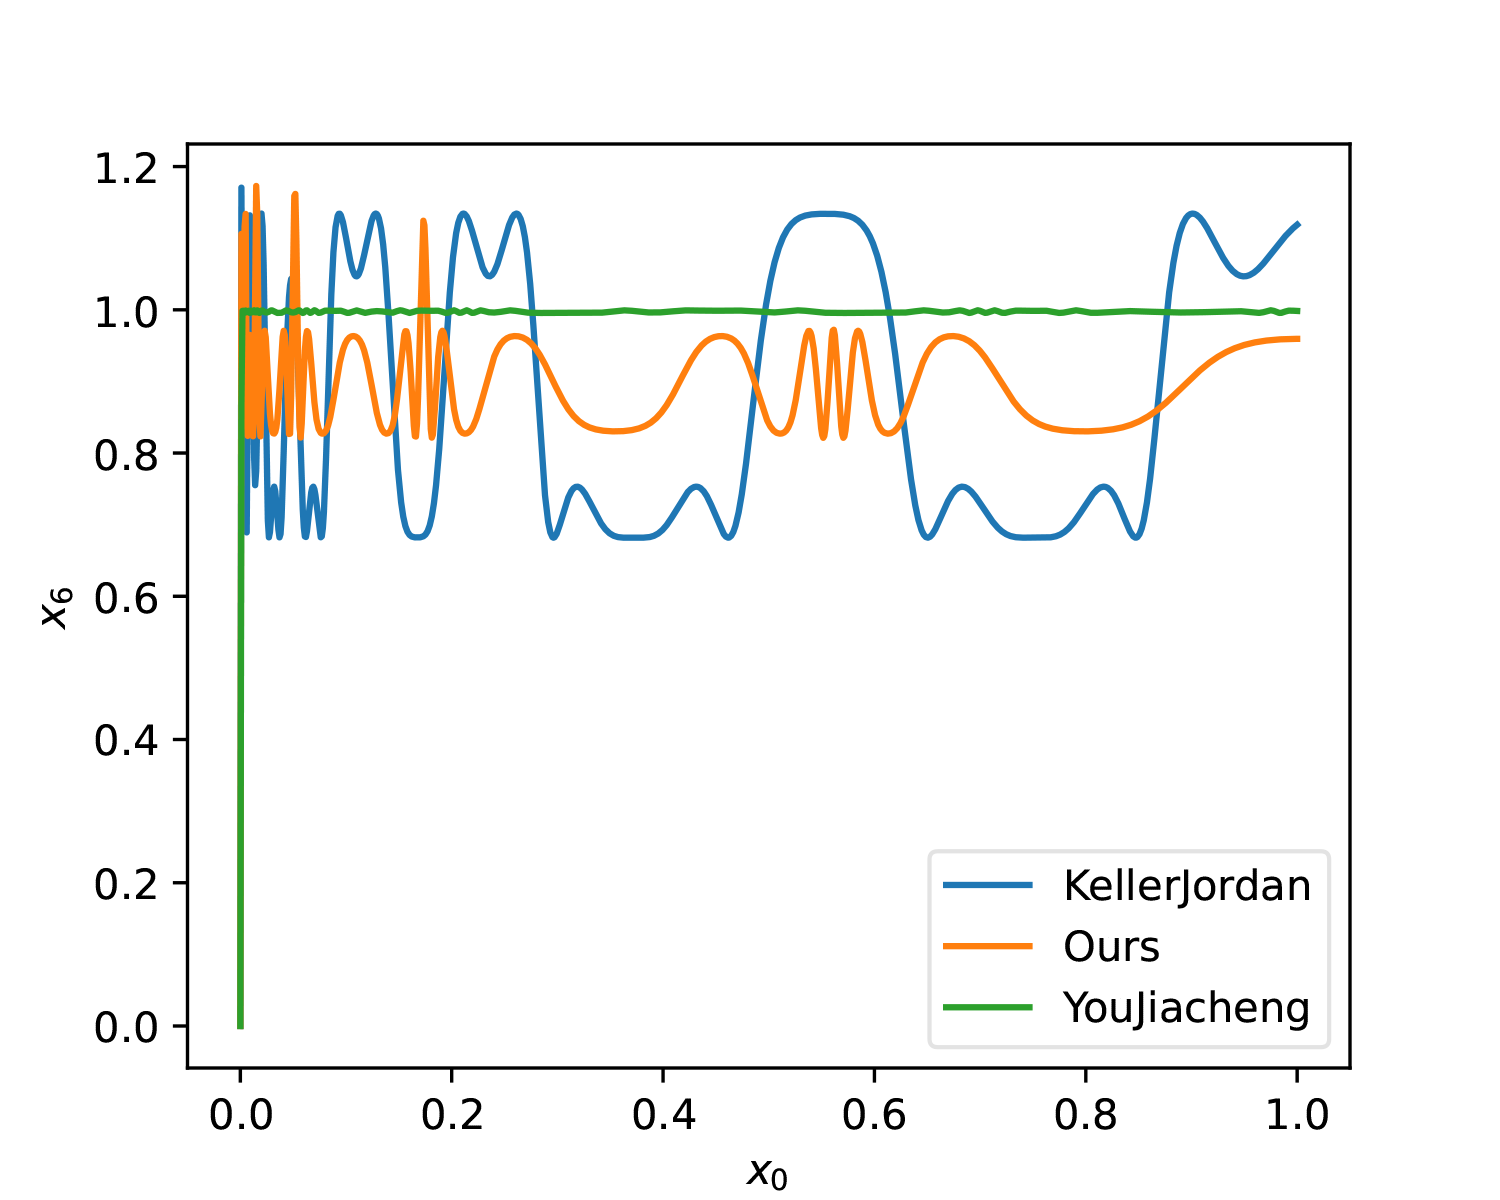 Approximation over [0, 1]
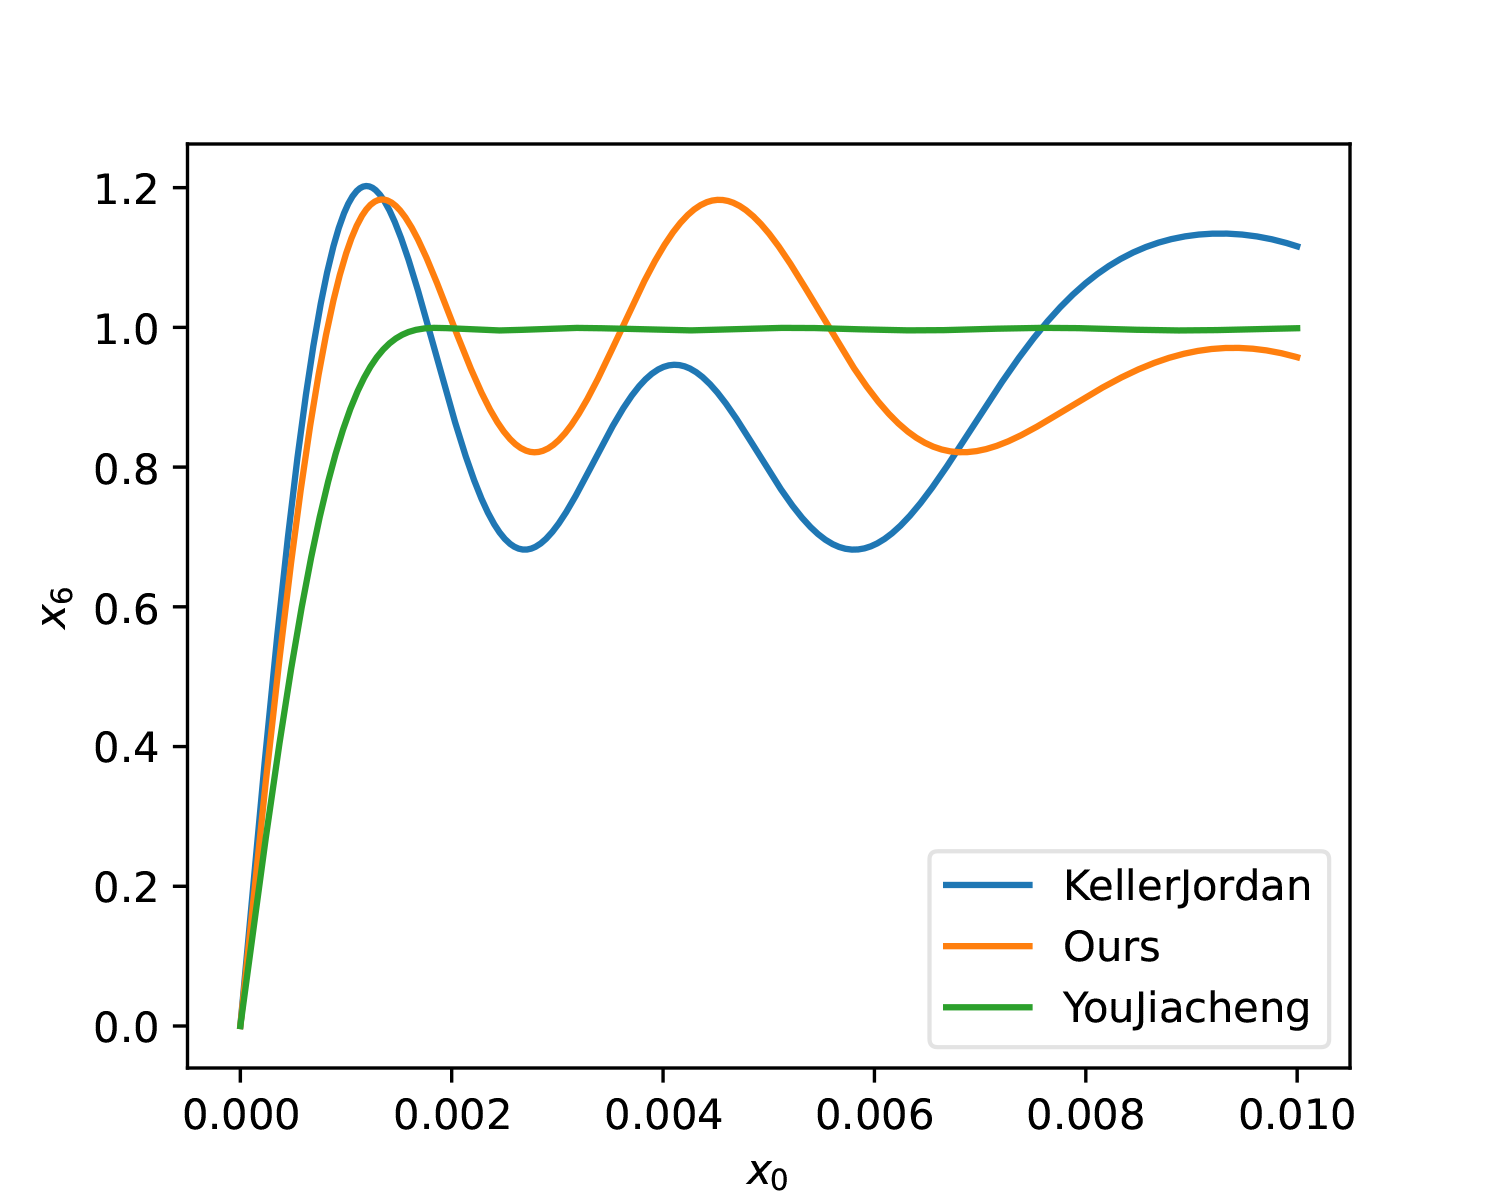 Approximation over [0, 0.01]
To be fair, the KellerJordan and Ours solutions were also both changed to use $T=6$. It's clear that, whether judged by smoothness or overall approximation quality, YouJiacheng's solution shows a clear improvement, which really demonstrates the "full power" unlocked once parameter sharing is removed.
Try It Yourself
How was YouJiacheng's solution obtained? The author shared his code here; the idea is likewise to solve with Adam, but it involves many different loss terms and is a bit tricky to follow. In fact, using our script from before together with his initialization, we can get equally good results:
$$\begin{array}{c|ccc} \hline t & a & b & c \\ \hline \quad 1\quad & 4140/1024 & -7553/1024 & 3571/1024 \\ 2 & 3892/1024 & -6637/1024 & 2973/1024 \\ 3 & 3668/1024 & -6456/1024 & 3021/1024 \\ 4 & 3248/1024 & -6211/1024 & 3292/1024 \\ 5 & 2792/1024 & -5759/1024 & 3796/1024 \\ 6 & 3176/1024 & -5507/1024 & 4048/1024 \\ \hline \end{array}$$
Reference code:
import jax
import jax.numpy as jnp
from tqdm import tqdm

def loss(w, x, k=50):
    for a, b, c in w:
        x = a * x + b * x**3 + c * x**5
    return jnp.abs(x - 1).sort()[-k:].mean()

@jax.jit
def grad(w, x, tol=0.1):
    G = lambda w, x: (g := jax.grad(loss)(w, x)) / jnp.fmax(jnp.linalg.norm(g), 1)
    return 0.6 * G(w, x) + 0.2 * (G(w + tol / 2, x) + G(w - tol / 2, x))

iters = 6
x = jnp.linspace(0, 1, 10001)[1:]
w = jnp.array([[3.5, -6.04444444444, 2.84444444444]] * iters)
m, v = jnp.zeros_like(w), jnp.zeros_like(w)
lr = 1e-3
pbar = tqdm(range(20000), ncols=0, desc='Adam')

for i in pbar:
    l, g = loss(w, x), grad(w, x)
    m = 0.9 * m + 0.1 * g
    v = 0.999 * v + 0.001 * g**2
    w = w - lr * m / jnp.sqrt(v + 1e-20)
    pbar.set_description(f'Loss: {l:.6f}, LR: {lr:.6f}')
    if i in [10000]:
        lr *= 0.1
Comparison below (labeled "Ours-X"):
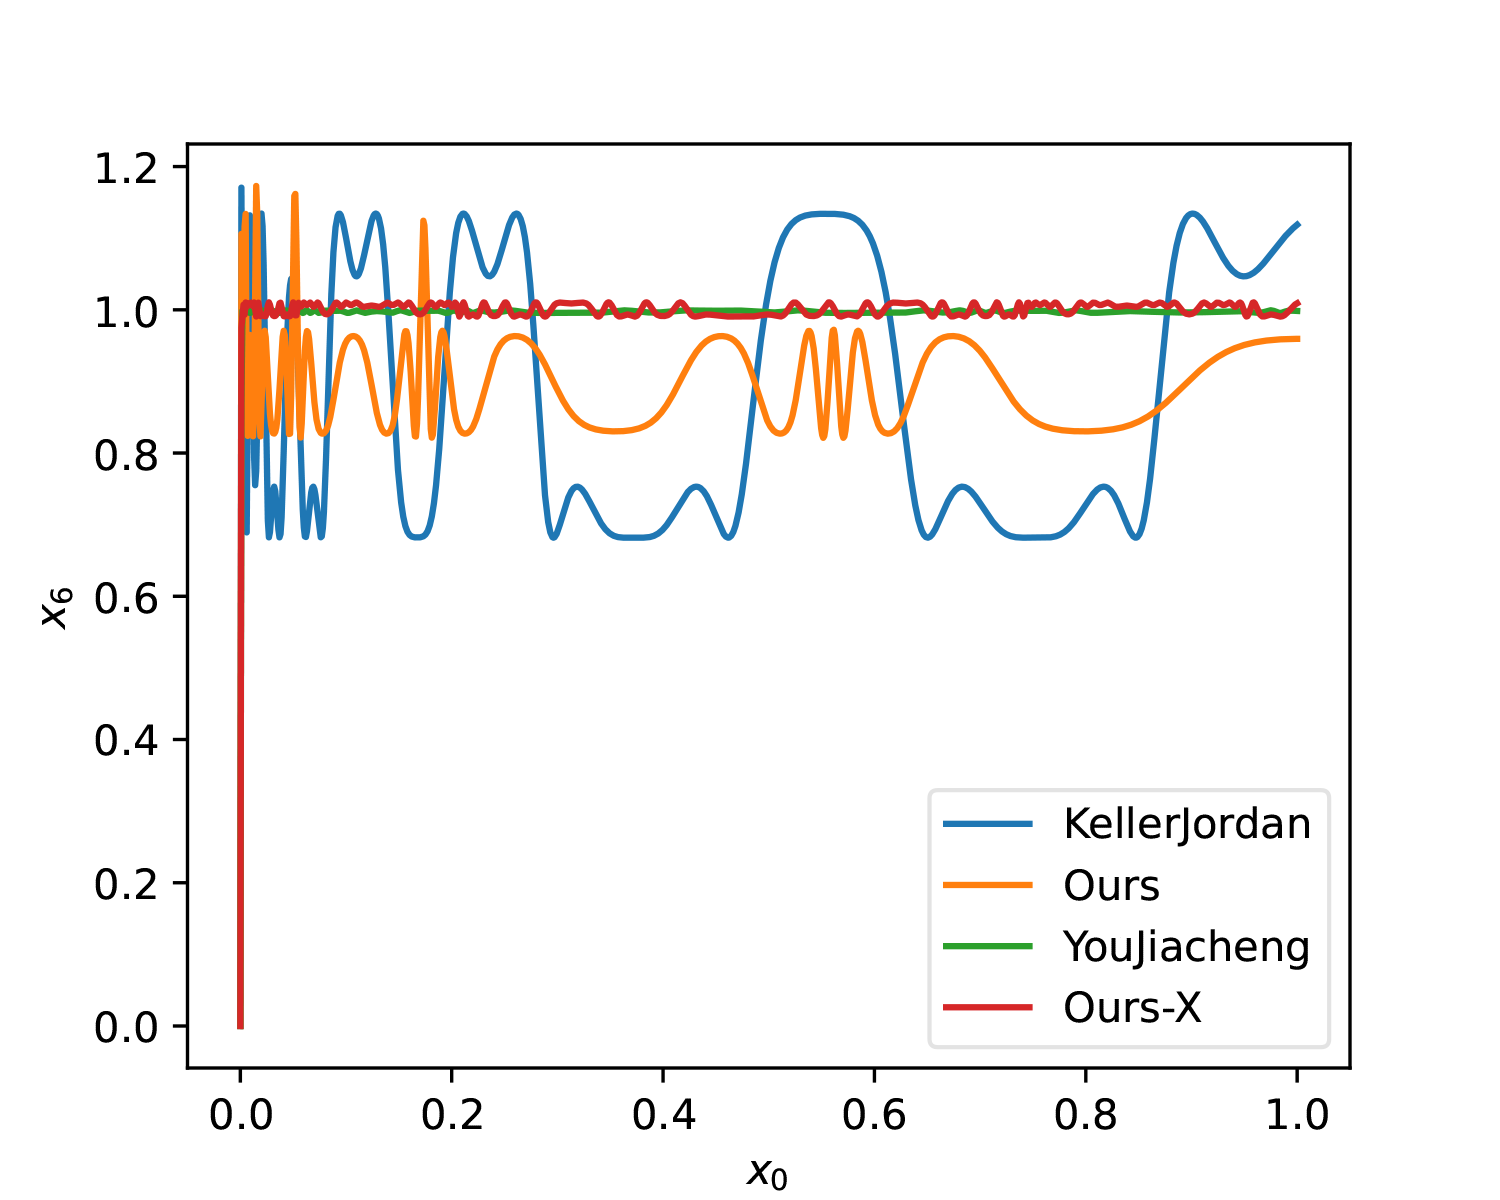 Approximation over [0, 1]
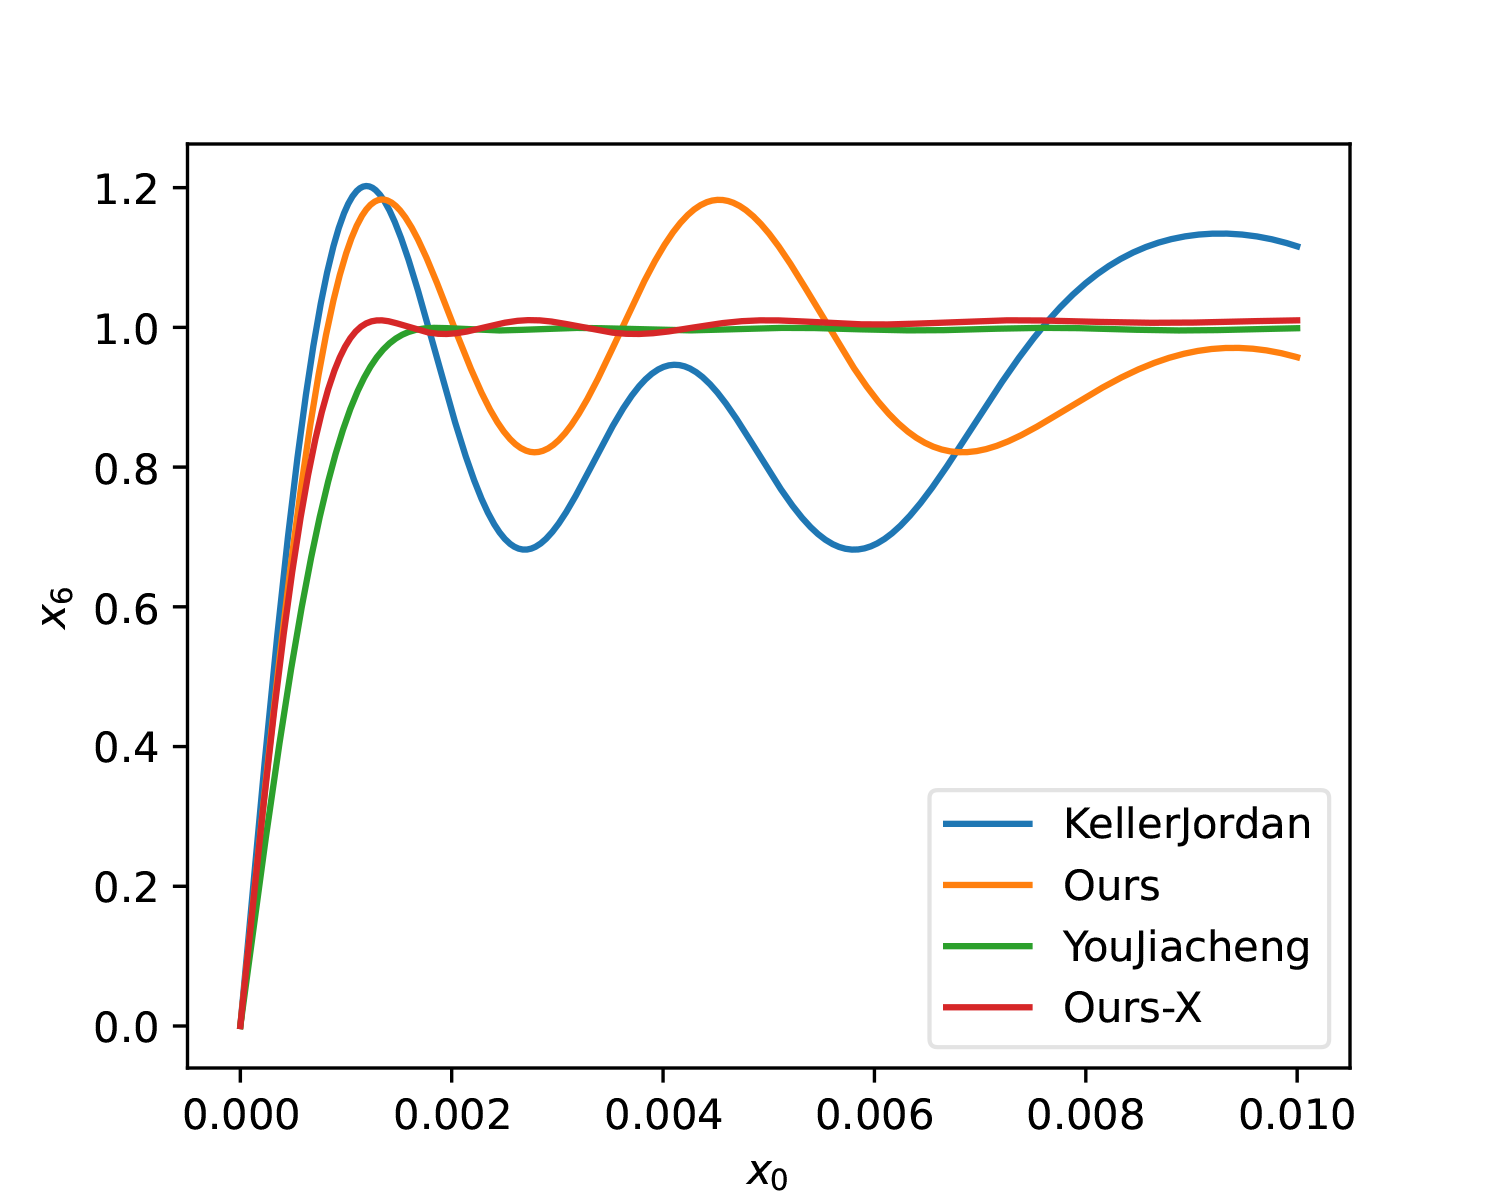 Approximation over [0, 0.01]
As the figure shows, compared to YouJiacheng's solution, our result oscillates a bit more, but in exchange achieves a larger slope near $[0,0.001]$.
Other Solutions
If readers would prefer a solution with less oscillation, they simply need to increase the value of $k$. For example, the result for $k=200$ is:
$$\begin{array}{c|ccc} \hline t & a & b & c \\ \hline \quad 1\quad & 4059/1024 & -7178/1024 & 3279/1024 \\ 2 & 3809/1024 & -6501/1024 & 2925/1024 \\ 3 & 3488/1024 & -6308/1024 & 3063/1024 \\ 4 & 2924/1024 & -5982/1024 & 3514/1024 \\ 5 & 2439/1024 & -5439/1024 & 4261/1024 \\ 6 & 3148/1024 & -5464/1024 & 4095/1024 \\ \hline \end{array}$$
which is now very close to YouJiacheng's solution (Ours-X2):
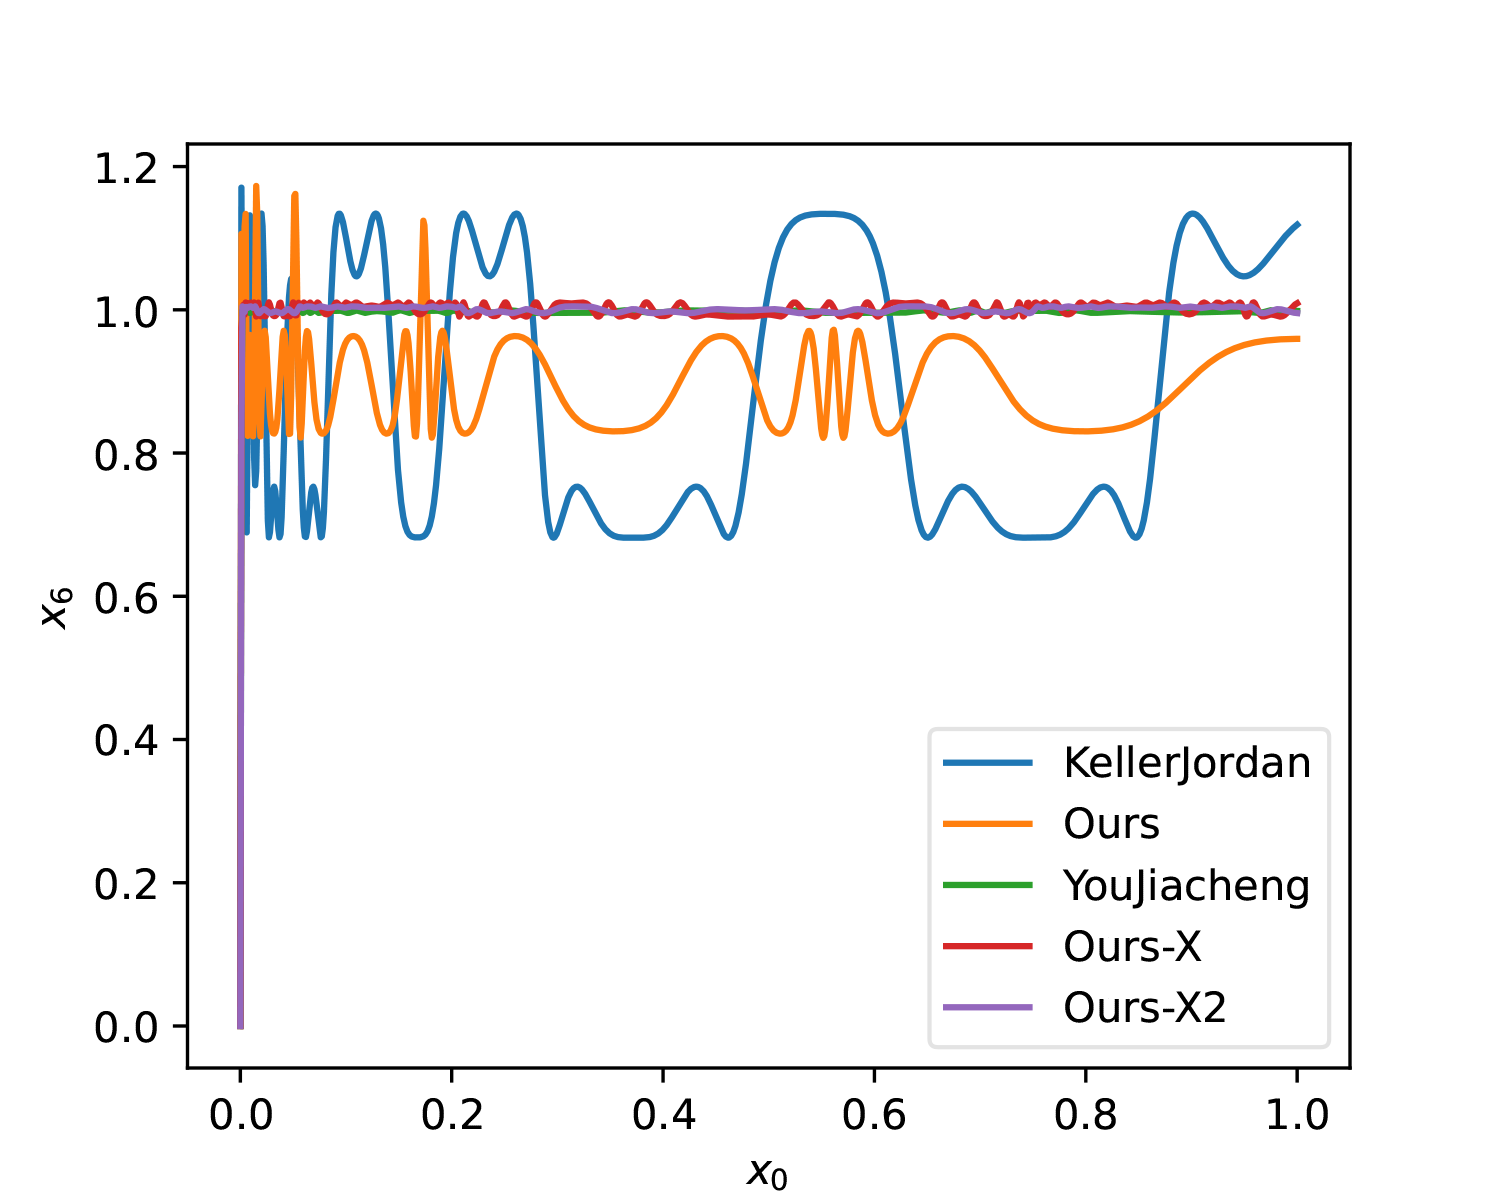 Approximation over [0, 1]
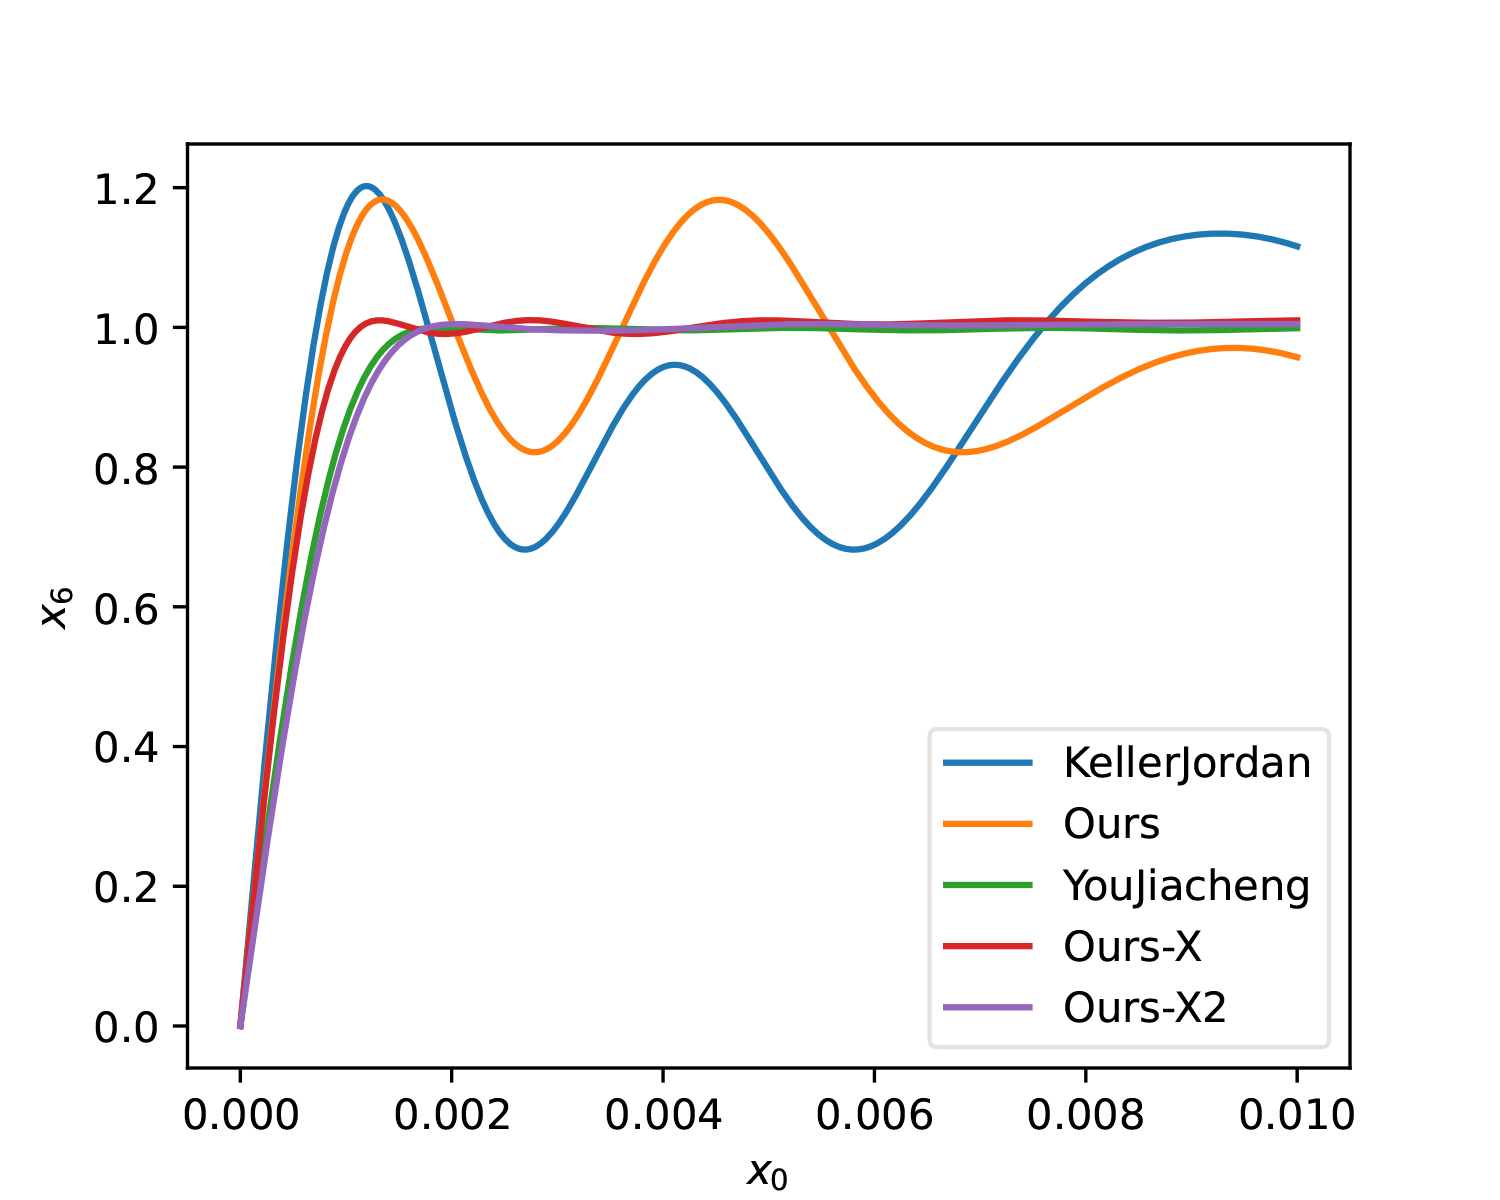 Approximation over [0, 0.01]
For comparison with the original solution, here is also a 5-step solution:
$$\begin{array}{c|ccc} \hline t & a & b & c \\ \hline \quad 1\quad & 4.6182 & -12.9582 & 9.3299 \\ 2 & 3.8496 & -7.9585 & 4.3052 \\ 3 & 3.5204 & -7.2918 & 4.0606 \\ 4 & 3.2067 & -6.8243 & 4.2802 \\ 5 & 3.2978 & -5.7848 & 3.8917 \\ \hline \end{array}$$
Result plot (Ours-X3):
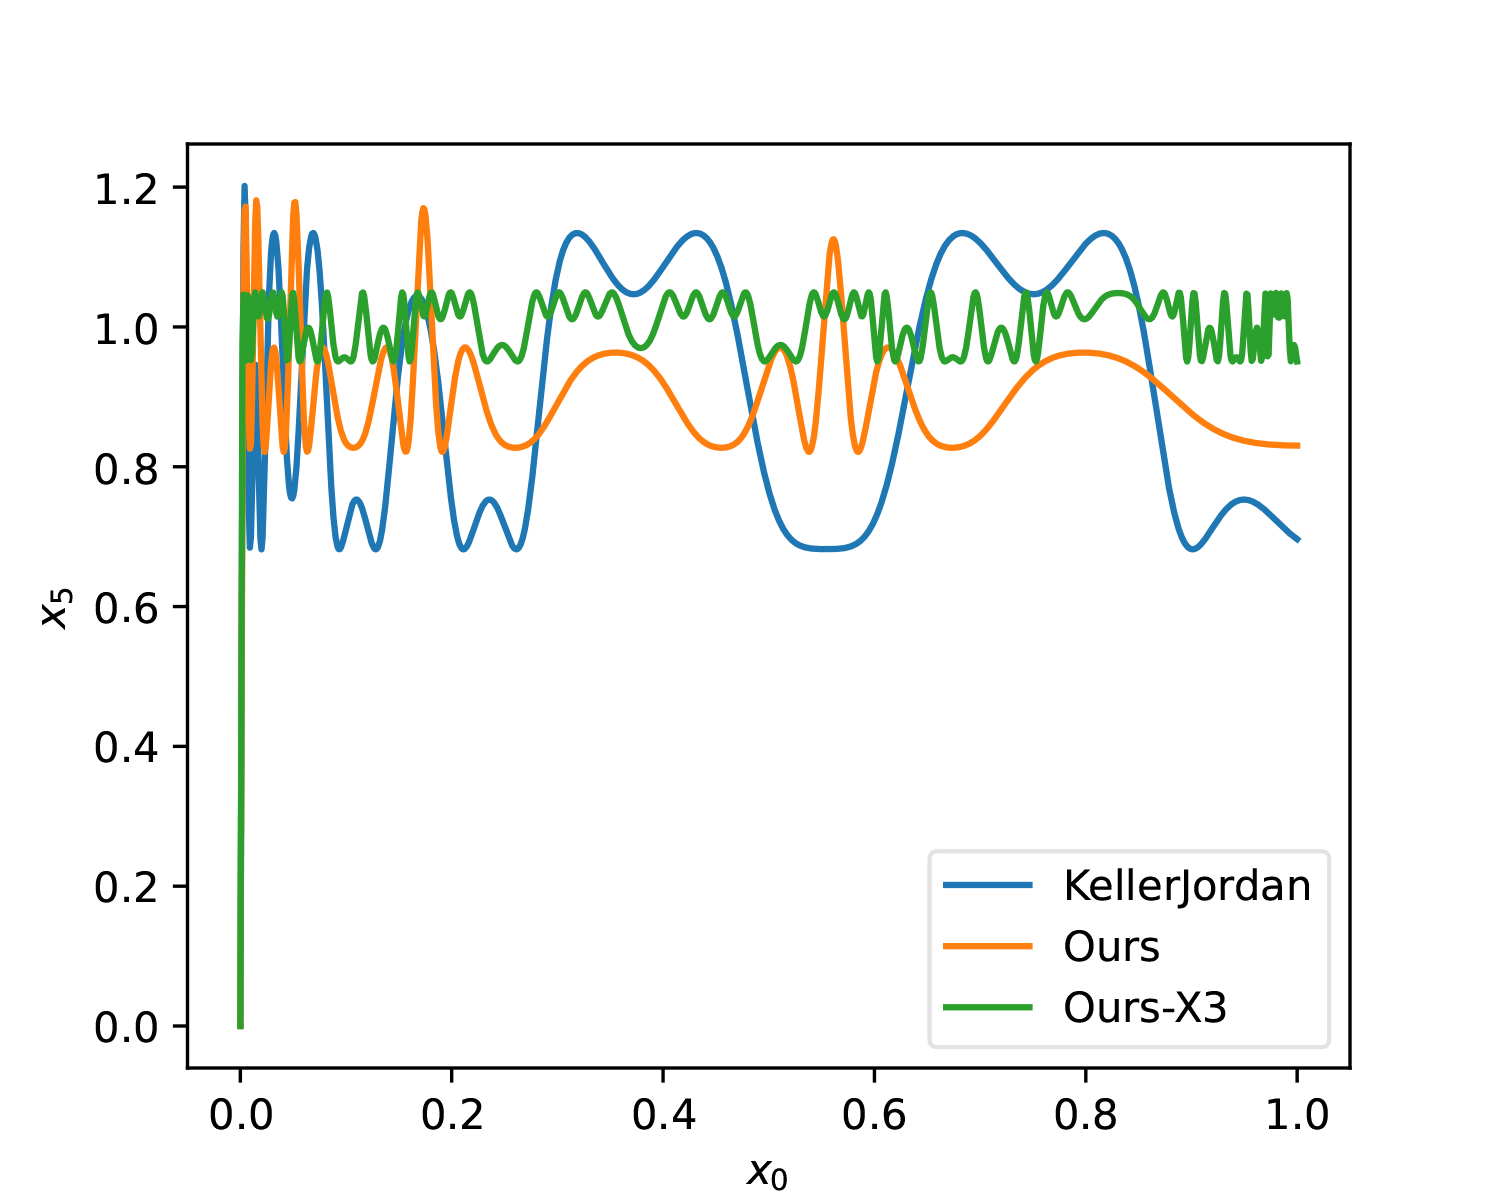 Approximation over [0, 1]
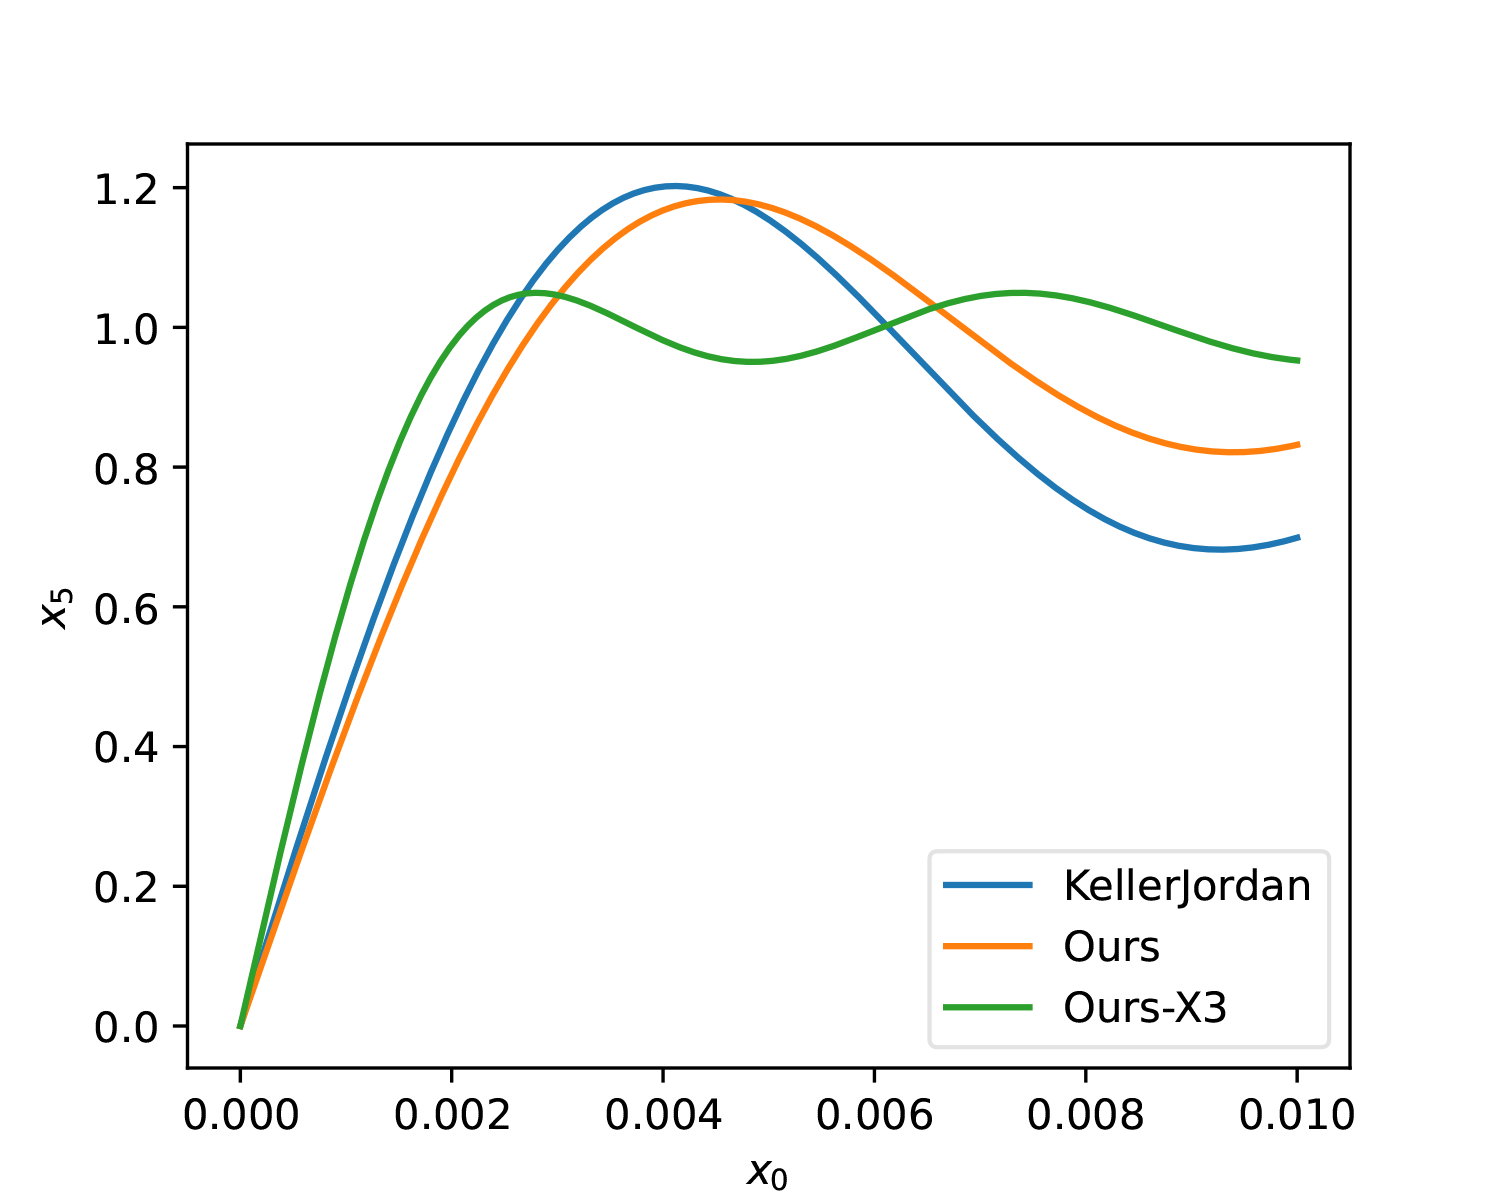 Approximation over [0, 0.01]
Improving the Initial Value
This concludes our discussion of solving for $a,b,c$. In summary, using different $a,b,c$ coefficients at each step really can substantially improve the convergence properties of the Newton-Schulz iteration, without any additional computational cost — a genuine free lunch.
Beyond optimizing the coefficients of the Newton-Schulz iteration, is there any other way to improve its convergence properties? As it turns out, yes. @johanwind, @YouJiacheng, @ZhangRuichong and others found that we can exploit certain characteristics of the Newton-Schulz iteration to improve the quality of the initial value almost for free, thereby speeding up convergence. @leloykun provides a reference implementation here.
Specifically, current efforts to improve the Newton-Schulz iteration can be summarized as: "while guaranteeing convergence, push the convergence speed of near-zero singular values as high as possible." If we could enlarge these near-zero singular values in advance, we could speed up convergence without changing the iteration algorithm itself. Currently, to compress the singular values into $[0,1]$, we use $F$-norm normalization of $\boldsymbol{M}/\Vert\boldsymbol{M}\Vert_F$, which compresses the singular values to
\begin{equation}\sigma_i \quad\to\quad \frac{\sigma_i}{\Vert\boldsymbol{M}\Vert_F} = \frac{\sigma_i}{\sqrt{\sum\limits_{j=1}^r \sigma_i^2}} \in [0, 1]\end{equation}
This does achieve the goal, but it also over-compresses. The tightest possible compression would be $\sigma_i\to \sigma_i/\sigma_1$, i.e., spectral normalization. The problem is that the spectral norm is not as easy to compute as the $F$-norm, which is why we settled for the $F$-norm instead. However, we have
\begin{equation}\sigma_1 \quad\leq\quad \underbrace{\sqrt[\uproot{10}8]{\sum_{j=1}^r \sigma_i^8}}_{\sqrt[4]{\Vert(\boldsymbol{M}^{\top}\boldsymbol{M})^2\Vert_F}}\quad\leq\quad \underbrace{\sqrt[\uproot{10}4]{\sum_{j=1}^r \sigma_i^4}}_{\sqrt{\Vert\boldsymbol{M}^{\top}\boldsymbol{M}\Vert_F}} \quad\leq\quad \underbrace{\sqrt{\sum_{j=1}^r \sigma_i^2}}_{\Vert\boldsymbol{M}\Vert_F} \end{equation}
which means that using $\sqrt[4]{\Vert(\boldsymbol{M}^{\top}\boldsymbol{M})^2\Vert_F}$ or $\sqrt{\Vert\boldsymbol{M}^{\top}\boldsymbol{M}\Vert_F}$ as the normalization factor is, in theory, always better than using $\Vert\boldsymbol{M}\Vert_F$. Very neatly, under the Newton-Schulz iteration, these quantities are almost free to compute! To see why, let's write out the first iteration step:
\begin{equation}\boldsymbol{X}_0 = \frac{\boldsymbol{M}}{\Vert\boldsymbol{M}\Vert_F},\qquad \boldsymbol{X}_1 = a\boldsymbol{X}_0 + b\boldsymbol{X}_0(\boldsymbol{X}_0^{\top}\boldsymbol{X}_0) + c\boldsymbol{X}_0(\boldsymbol{X}_0^{\top}\boldsymbol{X}_0)^2\end{equation}
We can see that $\boldsymbol{X}_0^{\top}\boldsymbol{X}_0$ and $(\boldsymbol{X}_0^{\top}\boldsymbol{X}_0)^2$ have to be computed anyway, so we can just use them to compute the $F$-norm and re-normalize accordingly. Reference code:
def msign(x, steps=5, eps=1e-20):
    a, b, c, y = 3.4445, -4.7750, 2.0315, x.astype('bfloat16')
    y = y.mT if x.shape[0] > x.shape[1] else y
    y /= ((y**2).sum(axis=[-2, -1], keepdims=True) + eps)**0.5
    for i in range(steps):
        y4 = (y2 := y @ y.mT) @ y2
        if i == 0:
            n = ((y4**2).sum(axis=[-2, -1], keepdims=True) + eps)**0.125
            y, y2, y4 = y / n, y2 / n**2, y4 / n**4
        y = a * y + (b * y2 + c * y4) @ y
    return y.mT if x.shape[0] > x.shape[1] else y
Empirically, for a random Gaussian matrix of shape $100\times 100$, the smallest singular value after this improvement is, in most cases, more than double what it was before, and the average singular value is also closer to 1. That said, Muon's author has noted that this may introduce additional instability, so it hasn't been adopted into the official code yet.
Summary
This post introduced an optimization approach for computing $\msign$ via the Newton-Schulz iteration. The resulting solutions noticeably improve both the convergence speed and the approximation quality compared to Muon's official solution.
Finally, it's worth pointing out that, for Muon, small-scale experimental results suggest there doesn't seem to be a necessary link between the computational precision of $\msign$ and the model's final performance — improving the precision of $\msign$ in small models seems only to speed up convergence somewhat in the early stages, without changing the final outcome. It's currently unclear whether this conclusion still holds at larger model scales.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.