I Heard That Attention Gets Along Better with Softmax~
I wonder if anyone else has noticed this detail: the current mainstream pretraining paradigm in NLP is to train on a fixed length (say 512), and then directly apply the pretrained model to tasks of different lengths. It seems nobody has ever really questioned this practice, as if it were "obviously" a given that a model should be able to generalize automatically across different lengths.
Of course, I myself never had any such doubts before either — not until a few days ago, when I ran experiments on the Base version of GAU and discovered that GAU's length generalization ability wasn't as good as one might expect. After digging further, I came to realize that this kind of length generalization ability is not something we should simply take for granted...
Revisiting the Model
In Quotes "FLASH: Perhaps the Most Interesting Efficient Transformer Design in Recent Times", we introduced the "Gated Attention Unit (GAU)," a novel design that fuses GLU and attention.
Beyond its performance, GAU brought us two conceptual shocks in terms of design: first, it showed that single-head attention need not be inferior to multi-head attention, which underlies its reputation for being "fast" and "cheap"; second, it showed that attention doesn't necessarily need Softmax normalization — it can instead be replaced with a simple $\text{relu}^2$ divided by the sequence length:
\begin{equation}\boldsymbol{A}=\frac{1}{n}\text{relu}^2\left(\frac{\mathcal{Q}(\boldsymbol{Z})\mathcal{K}(\boldsymbol{Z})^{\top}}{\sqrt{s}}\right)=\frac{1}{ns}\text{relu}^2\left(\mathcal{Q}(\boldsymbol{Z})\mathcal{K}(\boldsymbol{Z})^{\top}\right)\end{equation}more
This form leads to an interesting question: if, during pretraining, we try to arrange our samples to all have the same length (say 512), then throughout pretraining $n$ is almost always 512, meaning $n$ is effectively a constant. If we then fine-tune on a different length (say 64 or 128), should this $n$ automatically adapt to the sample length, or should it stay fixed at 512?
Intuitively, it seems more adaptive to set it equal to the sample length, but the answer turns out to be quite counterintuitive: fine-tuning performance with $n$ fixed at 512 is noticeably better than with $n$ set to the sample length! This calls for deeper thought...
Pinpointing the Problem
Looking purely at GAU's pretraining performance, it outperforms standard attention, so GAU's own fitting capability shouldn't be the issue — the problem must lie in $\frac{1}{n}\text{relu}^2(\cdot)$'s poor transferability with respect to sample length. To confirm this, I also tried mixing samples of different lengths for GAU pretraining, and found the results improved noticeably.
So what exactly is going wrong with GAU? Actually, this isn't hard to guess. GAU's overall computation can be abbreviated as $\boldsymbol{O}=(\boldsymbol{U}\odot\boldsymbol{A}\boldsymbol{V})\boldsymbol{W}_o$, where $\boldsymbol{U},\boldsymbol{V},\boldsymbol{W}_o$ are all token-wise operations — meaning they're completely unaffected by changes in length. So the problem can only lie in $\boldsymbol{A}$.
In the past, when we used standard attention, we never ran into a similar issue, to the point that we unconsciously took this as an "obvious" property. So we need to look for the source of the problem by comparing GAU's attention to standard attention. As mentioned, the two differ in two respects: one is that multi-head attention becomes single-head attention, but this would at most cause some fluctuation in performance, whereas what we measured was a substantial drop. So the problem must lie in the other difference, namely the normalization method — that is, it comes from replacing attention's $softmax$ with $\frac{1}{n}\text{relu}^2(\cdot)$.
Verifying this guess is simple: I switched GAU's attention normalization back to Softmax, retrained a GAU model, and then fine-tuned and tested it on tasks of different lengths. The results were noticeably better than with $\frac{1}{n}\text{relu}^2(\cdot)$. So we can conclude: attention still gets along better with Softmax~
Analyzing the Cause
Why does the more intuitive, length-adaptive $n$ perform worse than the fixed $n$? Since we already know Softmax doesn't have this problem, let's take some inspiration from Softmax. The Softmax operation is:
\begin{equation}a_{i,j} = \frac{1}{Z_i}\exp\left(\frac{\boldsymbol{q}_i\cdot\boldsymbol{k}_j}{\sqrt{d}}\right),\quad Z_i = \sum_{j=1}^n \exp\left(\frac{\boldsymbol{q}_i\cdot\boldsymbol{k}_j}{\sqrt{d}}\right)\end{equation}
An immediate question is: what is the relationship between $Z_i$ and $n$? If indeed $Z_i=\mathcal{O}(n)$ holds, then theoretically replacing $Z_i$ with $n$ should achieve similar results — at least it shouldn't be dramatically worse.
However, we know that the whole point of attention is to "attend" — it should be able to "focus" on the handful of tokens it deems important. At the same time, previous experimental results on efficient Transformers have shown that replacing standard attention with local attention doesn't cause a noticeable performance drop. So we can expect that the attention at position $i$ is essentially concentrated on a limited number of tokens near $i$, and becomes essentially zero beyond a certain distance. Indeed, many post-hoc visualizations have shown that trained attention matrices are actually quite sparse.
Putting these observations together, we can conclude that there exists some constant $k$ such that when $|j-i|\geq k$, $\exp\left(\frac{\boldsymbol{q}_i\cdot\boldsymbol{k}_j}{\sqrt{d}}\right)$ is quite close to zero. This means $Z_i$ should be closer to $\mathcal{O}(k)$ than to $\mathcal{O}(n)$, which in turn implies that $Z_i$ is likely unrelated to $n$, or at least its order of magnitude relative to $n$ is smaller than $\mathcal{O}(n)$! Therefore, if we want to replace $Z_i$ with something else, it should be a lower-order function than the first power of $n$ — potentially even a constant.
Now let's look back at GAU: when its activation function is switched to $\text{relu}^2(\cdot)$, its attention behaves similarly, or is even sparser. This is because the $\text{relu}$ operation directly zeroes things out, unlike $\exp(\cdot)$ which is always positive. At the same time, GAU is "standard-equipped" with rotary position embedding (RoPE), and as we derived in Quotes "Transformer Upgrade Road: 2. Rotary Position Embedding That Draws on Many Strengths", RoPE itself has a built-in long-range decay effect. Combining all these factors, GAU's normalization factor should also be of an order lower than $\mathcal{O}(n)$, possibly even constant-level.
Entropy Invariance
From this, we can summarize three possible solutions for GAU: first, use the same fixed $n$ for both pretraining and fine-tuning; second, continue using the dynamic sample length $n$, but mix samples of different lengths during pretraining rather than using only a single length; third, add back a normalization factor, as Softmax does, and let the model learn it on its own:
\begin{equation}a_{i,j} = \frac{1}{Z_i}\text{relu}^2\left(\frac{\boldsymbol{q}_i\cdot\boldsymbol{k}_j}{\sqrt{d}}\right),\quad Z_i = \sum_{i=1}^n \text{relu}^2\left(\frac{\boldsymbol{q}_i\cdot\boldsymbol{k}_j}{\sqrt{d}}\right)\end{equation}
Given these solutions exist, why do we still say that "attention gets along better with Softmax"? Where exactly does GAU's $\text{relu}^2(\cdot)$ fall short? First, let's look at the ablation experiments in the original GAU paper, which show that replacing $\text{relu}^2(\cdot)$ with Softmax yields essentially consistent performance:
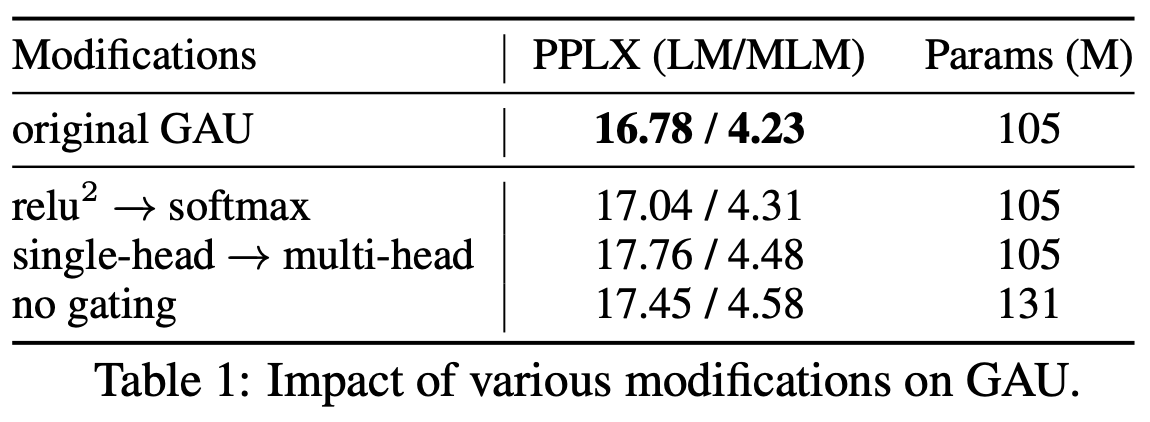 Replacing GAU's squared_relu with softmax gives similar performance
With this basic guarantee in hand, we can now examine where Softmax has an edge over $\text{relu}^2(\cdot)$. Looking at the three solutions for GAU mentioned above: solution one always feels insufficiently adaptive; solution two, requiring training with multiple lengths, feels inelegant; and solution three, after adding back the normalization factor, ends up formally looking even more "bloated" than Softmax. So overall, using Softmax is still the more elegant and effective choice.
Moreover, generalization ability can be roughly divided into "interpolation" and "extrapolation" — here interpolation (extrapolation) refers to test lengths shorter (longer) than the training length. What we said earlier about the normalization factor being constant-order applies mainly within the interpolation range. For extrapolation, if the length is long enough, $\boldsymbol{q}_i,\boldsymbol{k}_j$ all get "squeezed" together, so it becomes hard to maintain the property that things beyond a certain distance are close to zero. But if we use Softmax, we can derive an "entropy-invariant" version to enhance the model's extrapolation ability:
\begin{equation}Attention(Q,K,V) = softmax\left(\frac{\log_{512} n}{\sqrt{d}}QK^{\top}\right)V\end{equation}
In Quotes "Looking at Attention's Scale Operation Through Entropy Invariance", we ran a simple comparative experiment showing that this version indeed improves model performance beyond the training length.
So, can $\text{relu}^2(\cdot)$ be extended to an "entropy-invariant" version? The answer is no, because this relies on adjusting the entropy of the distribution via a temperature parameter, which requires the activation function to not have positive homogeneity. For instance, for power functions we have $(\lambda \boldsymbol{q}_i\cdot\boldsymbol{k}_j)^n=\lambda^n (\boldsymbol{q}_i\cdot\boldsymbol{k}_j)^n$, and after normalization, $\lambda^n$ just cancels out and has no effect. The activation function ideally needs to be one order higher than a power function for this kind of adjustment to work properly, and the most common function that's higher-order than a power function is the exponential function — and exponential normalization is exactly Softmax.
Summary
In this post, we analyzed why GAU underperforms after fine-tuning, and found that attention's normalization factor should be close to constant order. This is why GAU performs poorly when using $n$ or $n^2$ as the normalization factor. All in all, I still believe attention gets along better with Softmax — it's a solid baseline, and one that can be further extended via "entropy invariance" to enhance extrapolation ability even more.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.