CoSENT (I): A More Effective Sentence Embedding Approach than Sentence-BERT
Approaches for learning sentence embeddings can broadly be divided into unsupervised and supervised categories. Among the supervised approaches, the mainstream method is Facebook's "InferSent", and later "Sentence-BERT" further confirmed its effectiveness on top of BERT. However, whether it's InferSent or Sentence-BERT, they remain rather puzzling in theory: although they work well in practice, there is a mismatch between training and prediction, and if one directly optimizes the cosine similarity that is actually used at prediction time, the results tend to be particularly poor.
Recently I revisited this issue again, and after roughly a week of analysis and experimentation, I've largely pinned down why InferSent works while directly optimizing cosine similarity does not, and I propose a new scheme for optimizing cosine similarity called CoSENT (Cosine Sentence). Experiments show that CoSENT generally outperforms both InferSent and Sentence-BERT in terms of both convergence speed and final performance.
The Naive Approach
The setting in this article is building a sentence embedding model using labeled text-matching data, where the labeled data typically consists of sentence-pair samples, i.e., each sample has the format "(sentence 1, sentence 2, label)". These can broadly be classified into "binary type", "NLI type", and "scoring type", see the section "Categorizing the data" in Augmenting RoFormer-Sim with Open-Source Human-Annotated Data.
Cosine Similarity That Fails
For simplicity, let's first consider only "binary type" data, i.e., samples of the form "(sentence 1, sentence 2, whether they are similar)". Suppose the two sentences, after being encoded by the model, yield vectors $u,v$ respectively. Since at retrieval time we compute cosine similarity $\cos(u,v)=\frac{\langle u,v\rangle}{\Vert u\Vert \Vert v\Vert}$, a fairly natural idea is to design a loss function based on $\cos(u,v)$, such as
\begin{align}t\cdot (1 - \cos(u, v)) + (1 - t) \cdot (1 + \cos(u,v))\label{eq:cos-1}\\ t\cdot (1 - \cos(u, v))^2 + (1 - t) \cdot \cos^2(u,v)\label{eq:cos-2} \end{align}more
where $t\in\{0,1\}$ indicates whether the pair is similar. There are many similar losses one could write down, all roughly aiming to make the similarity of positive pairs as large as possible and that of negative pairs as small as possible. However, directly optimizing these objectives in experiments often yields particularly poor results (at least noticeably worse than InferSent), and in some cases even worse than a randomly initialized model.
The Thorny Issue of Thresholds
This is because negative pairs annotated in typical text-matching corpora are usually "hard negatives" — commonly, pairs with different semantics but a large amount of literal overlap. In this case, if we use equation $\eqref{eq:cos-1}$ as the loss function, the target for positive pairs is 1 and for negative pairs is -1; if we use equation $\eqref{eq:cos-2}$, the target for positive pairs is 1 and for negative pairs is 0. Either way, the target for negative pairs is set "too low", because for "hard negatives", although the semantics differ, they are still "similar" — the similarity shouldn't be pushed all the way down to 0 or even -1. Forcibly pushing them toward 0 or -1 usually results in overfitting, losing generalization ability, or makes optimization so difficult that the model simply fails to learn.
It's easy to verify this conclusion: just replace the negative samples in the training set with randomly sampled pairs (treated as weaker negatives), then train with the loss above — you'll find that performance actually improves. If we don't want to change the negative pairs, one way to alleviate this issue is to set a higher threshold for negative pairs, for example
\begin{equation}t\cdot (1 - \cos(u, v)) + (1 - t) \cdot \max(\cos(u,v),0.7)\end{equation}
This way, as long as the similarity of a negative pair is below 0.7, it won't be optimized further, making overfitting less likely. But this is only a palliative measure and rarely achieves optimal performance, and choosing this threshold remains a difficult problem.
InferSent
What's remarkably surprising is that InferSent and Sentence-BERT, despite their training-prediction mismatch, perform well on this exact problem. Taking Sentence-BERT as an example: during training, it concatenates $u,v,|u−v|$ (where $|u−v|$ refers to the vector formed by taking the absolute value of each element of $u−v$) as features, followed by a fully connected layer for binary classification (or 3-way classification if using the NLI dataset). At prediction time, however, it operates just like an ordinary sentence embedding model: it computes sentence vectors first, then calculates the cosine similarity. As shown below:
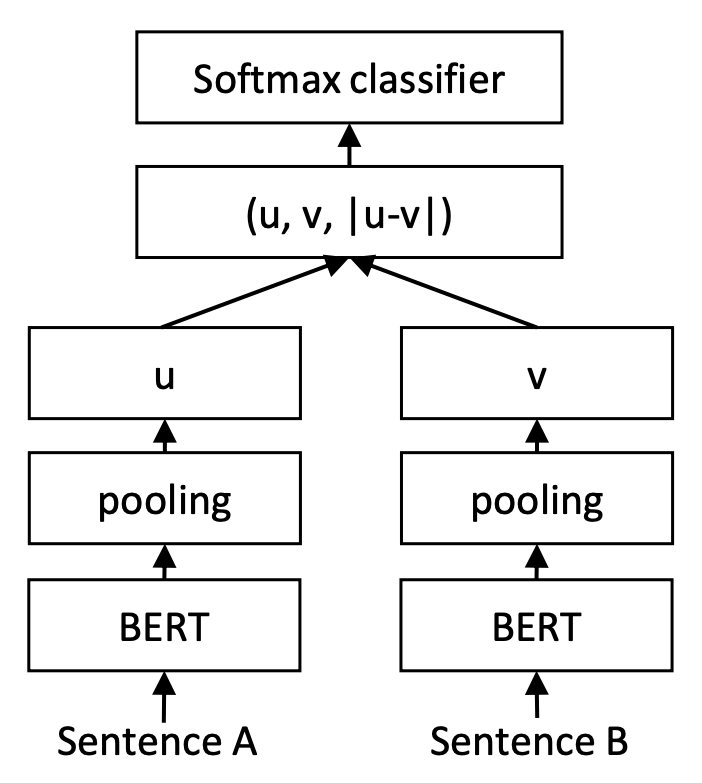 Sentence-BERT during training
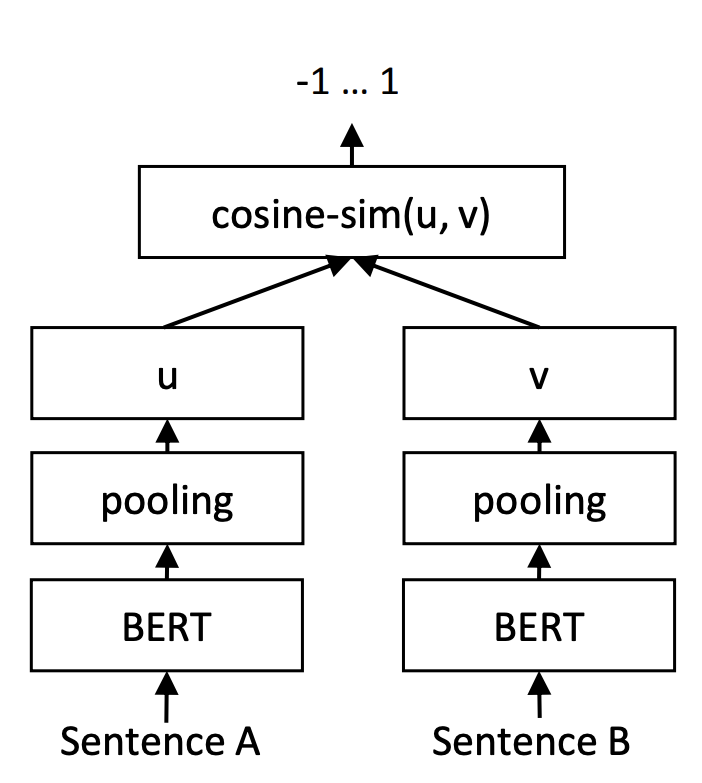 Sentence-BERT during prediction
Reasoning It Out Once More
Why do InferSent and Sentence-BERT work? In the section "Reasoning It Out" of Augmenting RoFormer-Sim with Open-Source Human-Annotated Data, I gave an explanation based on error tolerance. After further reflection during this period, I've arrived at a new understanding of the issue, which I'd like to share here.
Generally speaking, even when negative pairs are "hard negatives", positive pairs overall still tend to have higher literal similarity than negative pairs. As a result, even for the initial (untrained) model, the discrepancy $\Vert u-v\Vert$ for positive pairs tends to be small overall, while the discrepancy $\Vert u-v\Vert$ for negative pairs tends to be large overall. We can picture the $u-v$ of positive pairs as being distributed mainly near a sphere of small radius, and the $u-v$ of negative pairs as being distributed near a sphere of large radius. In other words, $u-v$ already exhibits a tendency toward clustering right from the start, and all we need to do afterward is reinforce this clustering tendency using label information, so that $u-v$ for positive pairs stays smaller and $u-v$ for negative pairs stays larger. A direct way to do this is to attach a Dense classifier after $u-v$; however, an ordinary classifier is based on inner products, and it cannot distinguish between two classes distributed on different spheres. So we add the absolute value to get $|u-v|$, turning the sphere into a local spherical cap (or, equivalently, turning the sphere into a cone), at which point a Dense classification layer becomes usable. This, I believe, is where $|u-v|$ comes from.
As for the concatenation of $u,v$, I believe its purpose is to eliminate anisotropy. Sentence embedding models like "BERT + [CLS]" exhibit severe anisotropy in their initial state, which has a fairly serious negative impact on sentence embedding quality, and $|u-v|$, being merely the relative discrepancy between vectors, cannot noticeably improve this anisotropy. But when $u,v$ is concatenated and fed into a Dense layer, since the class vectors of the Dense layer are randomly initialized, this effectively gives $u,v$ a random optimization direction, forcing them to "spread apart" from each other, moving away from the current anisotropic state.
Potential Issues
Although InferSent and Sentence-BERT are effective, they also have fairly obvious problems.
For instance, as mentioned above, the reason they work is that there's already a clustering tendency at initialization, and label-based training merely reinforces this clustering information. This means that "having a clustering tendency at initialization" is quite important, implying that their effectiveness is heavily dependent on the initial model. For example, "BERT + mean pooling" ultimately outperforms "BERT + [CLS]", because the former already has better discriminability at initialization.
Moreover, InferSent and Sentence-BERT are, after all, schemes with a training-prediction mismatch, so there's some probability of "training collapse" — specifically, the training loss keeps decreasing and training accuracy keeps increasing, but cosine-based evaluation metrics (like the Spearman coefficient) drop noticeably, even on the training set itself. This indicates that training is proceeding normally in one sense, but it has drifted away from the classification criterion of "positive pairs having smaller $u-v$ and negative pairs having larger $u-v$", causing the cosine-based metric to collapse.
InferSent and Sentence-BERT are also hard to tune, again due to the training-prediction mismatch, which makes it difficult to determine which adjustments to the training process will actually benefit the prediction results.
CoSENT
In short, InferSent and Sentence-BERT are usable schemes but come with a lot of uncertainty. So is optimizing cosine similarity directly really a dead end? Certainly not. The earlier SimCSE actually has a supervised variant that also directly optimizes cosine similarity, but it requires triplet data in the format "(original sentence, similar sentence, dissimilar sentence)". The CoSENT proposed in this article further improves upon this idea, so that the training process only needs sentence-pair samples.
The New Loss Function
Let $\Omega_{pos}$ denote the set of all positive pairs and $\Omega_{neg}$ the set of all negative pairs. What we actually want is that for any positive pair $(i,j)\in \Omega_{pos}$ and any negative pair $(k,l)\in \Omega_{neg}$,
\begin{equation}\cos(u_i,u_j) > \cos(u_k, u_l)\end{equation}
holds, where $u_i,u_j,u_k,u_l$ are their respective sentence vectors. In other words, we only require that the similarity of positive pairs be greater than that of negative pairs — how much greater is left for the model to decide on its own. In fact, this matches how the common semantic similarity metric, Spearman's coefficient, works too — it only depends on the relative order of the predictions, not their exact values.
In Generalizing "Softmax + Cross-Entropy" to Multi-Label Classification, we introduced an effective approach for handling this kind of requirement, namely equation (1) from the Circle Loss theory:
\begin{equation}\log \left(1 + \sum\limits_{i\in\Omega_{neg},j\in\Omega_{pos}} e^{s_i-s_j}\right)\end{equation}
In short, if you want to ultimately achieve $s_i < s_j$, then add the term $e^{s_i-s_j}$ into $\log$. Applying this to our scenario here, we get the loss function
\begin{equation}\log \left(1 + \sum\limits_{(i,j)\in\Omega_{pos},(k,l)\in\Omega_{neg}} e^{\lambda(\cos(u_k, u_l) - \cos(u_i, u_j))}\right)\label{eq:cosent}\end{equation}
where $\lambda > 0$ is a hyperparameter, set to 20 in the experiments below. This is the core of CoSENT — a new loss function for optimizing cosine similarity directly.
Ranking in General
Some readers might object: even if equation $\eqref{eq:cosent}$ works here, doesn't it only apply to binary classification data? What about 3-class data like NLI?
In fact, equation $\eqref{eq:cosent}$ is fundamentally a loss function designed for ranking, and it can be written more generally as:
\begin{equation}\log \left(1 + \sum\limits_{\text{sim}(i,j) \gt \text{sim}(k,l)} e^{\lambda(\cos(u_k, u_l) - \cos(u_i, u_j))}\right)\label{eq:cosent-2}\end{equation}
That is, as long as we believe the true similarity of pair $(i,j)$ should be greater than that of pair $(k,l)$, we can add the term $e^{\lambda(\cos(u_k, u_l) - \cos(u_i, u_j))}$ into $\log$; in other words, as long as we can define an ordering over the sample pairs, we can use equation $\eqref{eq:cosent-2}$.
For NLI data, which has three labels — "entailment", "neutral", and "contradiction" — we can naturally assume that two "entailment" sentences have higher similarity than two "neutral" sentences, and that two "neutral" sentences have higher similarity than two "contradiction" sentences. Based on these three labels, we can thus order NLI sentence pairs. Once we have this ordering, NLI data can also be trained with CoSENT. Similarly, for STS-B-style data that already consists of similarity scores, CoSENT is even more directly applicable, since the score labels themselves already encode an ordering.
Of course, if there's no such ordering relationship among multiple categories, then CoSENT cannot be used. However, for multi-category sentence-pair data where no ordering relationship can be constructed, I'm also skeptical about whether InferSent or Sentence-BERT can produce a reasonable sentence embedding model. Since I haven't seen a dataset like that, there's no way to verify this for now.
Excellent Results
I ran experiments with CoSENT on several Chinese datasets, comparing two schemes: training on the original training set, and training on the NLI dataset. Most experimental results show that CoSENT clearly outperforms Sentence-BERT. The test datasets are the same as those in Which Unsupervised Semantic Similarity Method Is Best? A Fairly Comprehensive Evaluation; each dataset is split into train, valid, and test sets, and the evaluation metric is the Spearman coefficient between predictions and labels.
Experiment code: https://github.com/bojone/CoSENT
Below are the results on the test set after training with each dataset's own train set:
$$\begin{array}{c|ccccc|c} \hline & \text{ATEC} & \text{BQ} & \text{LCQMC} & \text{PAWSX} & \text{STS-B} & \text{Avg}\\ \hline \text{BERT+CoSENT} & \textbf{49.74} & \textbf{72.38} & 78.69 & \textbf{60.00} & \textbf{80.14} & \textbf{68.19}\\ \text{Sentence-BERT} & 46.36 & 70.36 & \textbf{78.72} & 46.86 & 66.41 & 61.74\\ \hline \text{RoBERTa+CoSENT} & \textbf{50.81} & \textbf{71.45} & \textbf{79.31} & \textbf{61.56} & \textbf{81.13} & \textbf{68.85}\\ \text{Sentence-RoBERTa} & 48.29 & 69.99 & 79.22 & 44.10 & 72.42 & 62.80\\ \hline \end{array}$$
Below are the results on the test set for each task after training on the open-source NLI dataset:
$$\begin{array}{c|ccccc|c} \hline & \text{ATEC} & \text{BQ} & \text{LCQMC} & \text{PAWSX} & \text{STS-B} & \text{Avg}\\ \hline \text{BERT+CoSENT} & \textbf{28.93} & 41.84 & \textbf{66.07} & \textbf{20.49} & 73.91 & \textbf{46.25} \\ \text{Sentence-BERT} & 28.19 & \textbf{42.73} & 64.98 & 15.38 & \textbf{74.88} & 45.23 \\ \hline \text{RoBERTa+CoSENT} & 31.84 & \textbf{46.65} & \textbf{68.43} & \textbf{20.89} & \textbf{74.37} & \textbf{48.43}\\ \text{Sentence-RoBERTa} & \textbf{31.87} & 45.60 & 67.89 & 15.64 & 73.93 & 46.99\\ \hline \end{array}$$
As you can see, CoSENT shows a fairly clear improvement on most tasks, and the drops on a few individual tasks are quite small (within 1%). The average improvement when training on the native datasets exceeds 6%, while the average improvement when training on NLI data is around 1%.
Additionally, CoSENT converges faster. For example, in native training, "BERT+CoSENT+ATEC" reaches a valid score of 48.78 after just the first epoch, whereas the corresponding "Sentence-BERT+ATEC" only reaches 41.54; "RoBERTa+CoSENT+PAWSX" in native training reaches 57.66 on valid after the first epoch, while the corresponding "Sentence-RoBERTa+PAWSX" only reaches 10.84; and so on.
Relation to Other Methods and Differences
Some readers might ask how equation $\eqref{eq:cosent}$ or equation $\eqref{eq:cosent-2}$ differs from SimCSE or contrastive learning in general. Looking purely at the form of the loss function, there is indeed some resemblance, but the meaning is entirely different.
Standard SimCSE only needs positive pairs (constructed via dropout or human annotation), and it treats all other samples within the batch as negatives. The supervised version of SimCSE, on the other hand, requires triplet data — essentially, it supplements standard SimCSE with hard negatives, so the negatives are not just all the other samples within the batch but also include annotated hard negatives; meanwhile positive pairs are still indispensable, hence the need for "(original sentence, similar sentence, dissimilar sentence)" triplets.
As for CoSENT, it only uses annotated positive and negative pairs and does not involve the process of randomly sampling other examples within the batch to construct negatives. We can also understand it as a form of contrastive learning, but it's contrastive learning over "sample pairs" rather than over "samples" as in SimCSE — that is, its fundamental "unit" is a pair of sentences, not a single sentence.
Summary
This article proposes a new supervised sentence embedding scheme, CoSENT (Cosine Sentence). Compared to InferSent and Sentence-BERT, its training process is more closely aligned with prediction, and experiments show that CoSENT generally outperforms both InferSent and Sentence-BERT in terms of convergence speed and final performance.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.