Multi-Task Learning Ramblings (III): Ranking Priorities
Multi-task learning is a very broad topic, and the goals of multi-task learning differ considerably across different scenarios. In Multi-Task Learning Ramblings (I): In the Name of Loss and Multi-Task Learning Ramblings (II): The Way of the Gradient, we understood the goal of multi-task learning as "doing well on every task," which manifests concretely as "treating every task as equally as possible" — we might call this "parallel-type multi-task learning." However, not every multi-task learning goal is like this. In many scenarios, what we really want is to learn one primary task well, with the other tasks serving merely as auxiliaries — the hope being that adding learning signal from these other tasks will improve the performance of the primary task. We can call this kind of scenario "primary-auxiliary-type multi-task learning."
Under this setting, if we still adopt the parallel-type multi-task learning scheme of "doing well on every task," this could noticeably degrade the performance of the primary task. So this post continues along the "way of the gradient" line of thinking, exploring a training scheme for primary-auxiliary-type multi-task learning.
Formulating the Objective
In this post, we assume the reader has already read and basically understood the ideas and methods in Multi-Task Learning Ramblings (II): The Way of the Gradient. From the gradient perspective, the necessary condition for keeping a loss function decreasing is that the update vector's angle with its gradient must be greater than 90 degrees — this idea runs throughout the whole post.more
Constrained Optimization
Now suppose that in the primary-auxiliary-type multi-task learning setting we have $n+1$ task loss functions, denoted $\mathcal{L}_0,\mathcal{L}_1,\cdots,\mathcal{L}_n$, where $\mathcal{L}_0$ is the primary task loss, which we want to be as small as possible; and $\mathcal{L}_1,\cdots,\mathcal{L}_n$ are auxiliary losses, which act like regularization terms — we merely want them not to move in the increasing direction during training, without necessarily needing them to "shrink desperately."
Following the notation of Multi-Task Learning Ramblings (II): The Way of the Gradient, we denote the update at each step as $\Delta\boldsymbol{\theta}=-\eta\boldsymbol{u}$. Since we treat $\mathcal{L}_0$ as the primary task, we naturally want to maximize the inner product between $\boldsymbol{u}$ and $\boldsymbol{g}_0$, so we can design the optimization objective as
\begin{equation}\max_{\boldsymbol{u}} \langle\boldsymbol{u},\boldsymbol{g}_0\rangle - \frac{1}{2}\Vert\boldsymbol{u}\Vert^2\end{equation}
Here $\boldsymbol{g}_i = \nabla_{\boldsymbol{\theta}}\mathcal{L}_i$ is the gradient of the corresponding loss. Without any other constraints, the solution would simply be $\boldsymbol{u} = \boldsymbol{g}_0$, i.e., ordinary gradient descent. But in fact we also have the auxiliary tasks $\mathcal{L}_1,\cdots,\mathcal{L}_n$, and we want them not to move in the increasing direction, so we must additionally ensure $\langle\boldsymbol{u},\boldsymbol{g}_1\rangle\geq 0,\cdots,\langle\boldsymbol{u},\boldsymbol{g}_n\rangle\geq 0$. These serve as the optimization constraints, so the overall objective is
\begin{equation}\max_{\boldsymbol{u}} \langle\boldsymbol{u},\boldsymbol{g}_0\rangle - \frac{1}{2}\Vert\boldsymbol{u}\Vert^2\quad\text{s.t.}\,\, \langle\boldsymbol{u},\boldsymbol{g}_1\rangle\geq 0,\cdots,\langle\boldsymbol{u},\boldsymbol{g}_n\rangle\geq 0\end{equation}
Solving this constrained optimization problem gives us an update vector satisfying the conditions.
Lagrange Multipliers
The standard approach for solving this kind of constrained optimization problem is the method of Lagrange multipliers, or "Lagrangian multipliers" for short. It folds the constraints into the objective function, converting the problem into a min-max problem:
\begin{equation}\max_{\boldsymbol{u}} \min_{\lambda_i\geq 0}\langle\boldsymbol{u},\boldsymbol{g}_0\rangle - \frac{1}{2}\Vert\boldsymbol{u}\Vert^2 + \sum_i \lambda_i \langle\boldsymbol{u},\boldsymbol{g}_i\rangle\label{eq:q-1}\end{equation}
Here, by convention, the sum over $i$ runs from $1$ to $n$. How should we understand this conversion? Suppose $\langle\boldsymbol{u},\boldsymbol{g}_i\rangle > 0$; then the step $\min\limits_{\lambda_i\geq 0}$ can only produce $\lambda_i=0$, since only $\lambda_i=0$ can make it attain its minimum, and in this case $\lambda_i \langle\boldsymbol{u},\boldsymbol{g}_i\rangle=0$; if $\langle\boldsymbol{u},\boldsymbol{g}_i\rangle=0$, then naturally $\lambda_i \langle\boldsymbol{u},\boldsymbol{g}_i\rangle=0$; if $\langle\boldsymbol{u},\boldsymbol{g}_i\rangle < 0$, then the step $\min\limits_{\lambda_i\geq 0}$ would give $\lambda_i\to\infty$, at which point $\lambda_i \langle\boldsymbol{u},\boldsymbol{g}_i\rangle\to -\infty$. But don't forget, the optimization over $\boldsymbol{u}$ takes the $\max$, so between $0$ and $-\infty$ it will naturally choose $0$ — that is, once this min-max optimization is complete, we automatically have both $\langle\boldsymbol{u},\boldsymbol{g}_i\rangle \geq 0$ and $\lambda_i \langle\boldsymbol{u},\boldsymbol{g}_i\rangle=0$. This means the result of the min-max optimization is exactly equivalent to the original constrained max optimization.
To facilitate the derivation below, we introduce notation similar to that of the previous post:
\begin{equation}\mathbb{Q}^n=\left\{(\lambda_1,\cdots,\lambda_n)\left|\lambda_1,\cdots,\lambda_n\geq 0\right.\right\},\quad\tilde{\boldsymbol{g}}(\lambda) = \sum_i \lambda_i \boldsymbol{g}_i\end{equation}
Then equation $\eqref{eq:q-1}$ can be written as
\begin{equation}\max_{\boldsymbol{u}} \min_{\lambda\in\mathbb{Q}^n}\langle\boldsymbol{u},\boldsymbol{g}_0 + \tilde{\boldsymbol{g}}(\lambda)\rangle - \frac{1}{2}\Vert\boldsymbol{u}\Vert^2\label{eq:q-2}\end{equation}
Solving Algorithm
At this point, we have reduced the problem of finding the update direction for primary-auxiliary-type multi-task learning to a min-max problem $\eqref{eq:q-2}$. Next, following an approach similar to the previous post, we first use the Minimax theorem to swap the order of $\max$ and $\min$, and then further apply the Frank-Wolfe algorithm to derive a solution. Finally, we will compare this result with that of the previous post, noting the similarities and differences.
Swapping the Order
Notice that in problem $\eqref{eq:q-2}$, $\max$ and $\min$ have an inherent ordering: normally we would need to complete step $\min$ before performing step $\max$, and swapping the order rashly might give the wrong result. However, step $\min$ is a constrained optimization, while step $\max$ is unconstrained, so $\max$ is indeed comparatively simpler. If we could swap the order and perform step $\max$ first, the problem would be simplified.
So we need to first determine whether the two operations can be swapped. Fortunately, von Neumann proposed the elegant Minimax theorem, which tells us that if the feasible domains of the parameters for $\min$ and $\max$ are both convex sets, and the objective function is convex with respect to the parameters of $\min$ and concave with respect to the parameters of $\max$, then the order of $\min$ and $\max$ can be swapped. Even more fortunately, it's easy to see that problem $\eqref{eq:q-2}$ satisfies the conditions of the Minimax theorem, so it is equivalent to
\begin{equation}\min_{\lambda\in\mathbb{Q}^n}\max_{\boldsymbol{u}} \langle\boldsymbol{u},\boldsymbol{g}_0 + \tilde{\boldsymbol{g}}(\lambda)\rangle - \frac{1}{2}\Vert\boldsymbol{u}\Vert^2 =\min_{\lambda\in\mathbb{Q}^n}\frac{1}{2}\Vert\boldsymbol{g}_0 + \tilde{\boldsymbol{g}}(\lambda)\Vert^2\label{eq:q-3}\end{equation}
This reduces the problem to one involving only the $\min$ operation, where the right-hand side of the equality follows because the objective function on the left is simply a quadratic function of $\boldsymbol{u}$, whose maximum is attained at $\boldsymbol{u}^* = \boldsymbol{g}_0 + \tilde{\boldsymbol{g}}(\lambda)$; substituting this in gives the result on the right.
The Simple Case
The problem now becomes finding the weighted combination of $\boldsymbol{g}_0$ and $\boldsymbol{g}_1,\cdots,\boldsymbol{g}_n$ with minimum norm. As usual, let's first try to solve the simplest case, namely $\min\limits_{\gamma\geq 0}\Vert\boldsymbol{g}_0 + \gamma\boldsymbol{g}_1\Vert^2$ when $n=1$, which has a nice geometric interpretation and a simple closed-form solution.
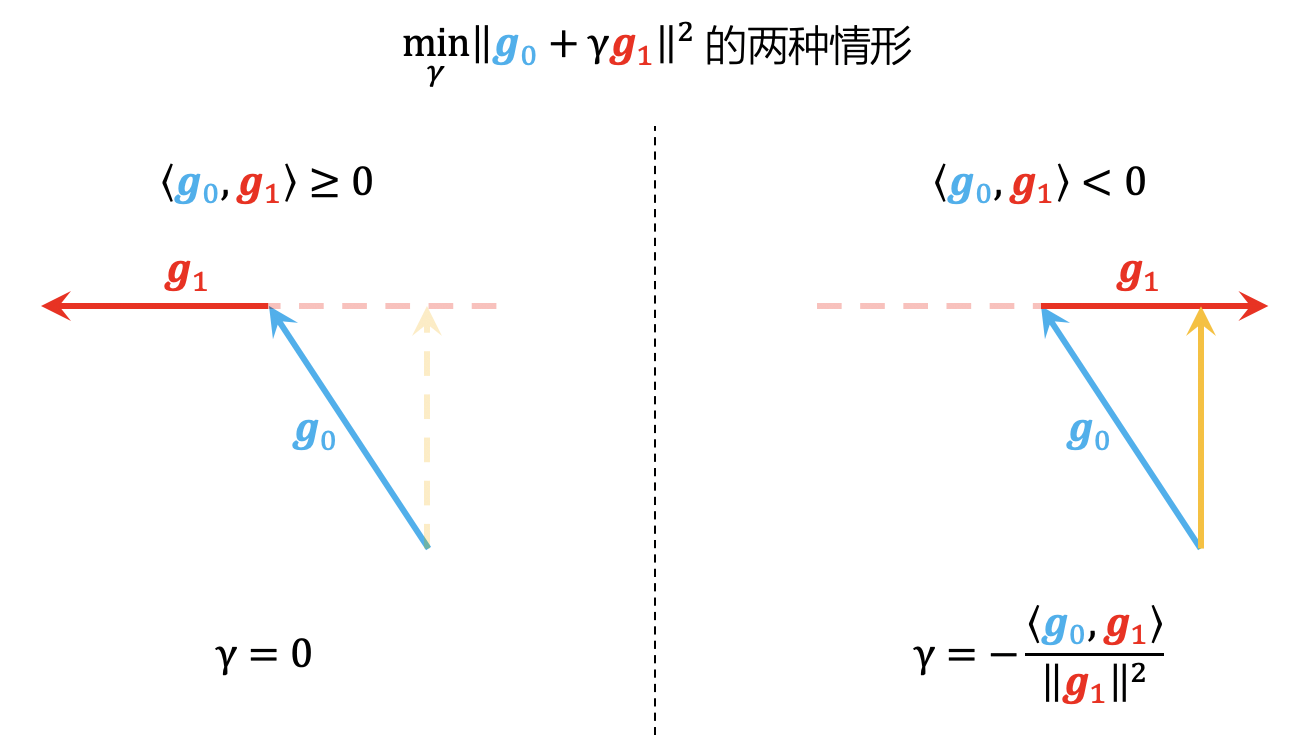 Exact solution for a simple example
As shown in the figure above, there are two cases. In the first case, $\langle\boldsymbol{g}_0,\boldsymbol{g}_1\rangle\geq 0$, which means $\boldsymbol{g}_0$ and $\boldsymbol{g}_1$ are not in conflict to begin with, so we simply take $\gamma=0$. In the second case, $\langle\boldsymbol{g}_0,\boldsymbol{g}_1\rangle < 0$: as we can see from the right-hand figure above, the minimum of $\Vert\boldsymbol{g}_0 + \gamma\boldsymbol{g}_1\Vert^2$ is attained when $\boldsymbol{g}_0 + \gamma\boldsymbol{g}_1$ is perpendicular to $\boldsymbol{g}_1$, so solving $\langle \boldsymbol{g}_0 + \gamma\boldsymbol{g}_1,\boldsymbol{g}_1\rangle=0$ gives $\gamma = -\frac{\langle \boldsymbol{g}_0,\boldsymbol{g}_1\rangle}{\Vert\boldsymbol{g}_1\Vert^2}$. Finally, when $\Vert\boldsymbol{g}_1\Vert\neq 0$, we can also write this uniformly as
\begin{equation}\gamma = \frac{\text{relu}(-\langle \boldsymbol{g}_0,\boldsymbol{g}_1\rangle)}{\Vert\boldsymbol{g}_1\Vert^2}\label{eq:gamma}\end{equation}
Iterative Solution
Next we handle the general case, whose underlying idea still comes from the Frank-Wolfe algorithm.
First, we find the feasible direction $e_{\tau}$ for the next update via $\tau = \mathop{\text{argmin}}\limits_i \langle \boldsymbol{g}_i, \boldsymbol{g}_0 + \tilde{\boldsymbol{g}}(\lambda^{(k)})\rangle$. Then we perform a one-dimensional search — but unlike before, this time we don't interpolate-search between $\lambda^{(k)}$ and $e_{\tau}$; instead, we directly re-determine the coefficient corresponding to $\boldsymbol{g}_{\tau}$. That is, we directly remove the $\boldsymbol{g}_{\tau}$ part from $\tilde{\boldsymbol{g}}(\lambda^{(k)})$, and then recompute the coefficient corresponding to $\boldsymbol{g}_{\tau}$ using the algorithm from the $n=1$ case.
This gives us the following iterative procedure:
\begin{equation}\left\{\begin{aligned} &\tau = \mathop{\text{argmin}}_i \langle \boldsymbol{g}_i, \boldsymbol{g}_0+\tilde{\boldsymbol{g}}(\lambda^{(k)})\rangle\\ &\gamma = \mathop{\text{argmin}}_{\gamma} \left\Vert\boldsymbol{g}_0 + \tilde{\boldsymbol{g}}(\lambda^{(k)} - \lambda^{(k)}_{\tau} e_{\tau} + \gamma e_{\tau})\right\Vert^2 = \mathop{\text{argmin}}_{\gamma} \left\Vert\boldsymbol{g}_0 + \tilde{\boldsymbol{g}}(\lambda^{(k)}) - \lambda^{(k)}_{\tau}\boldsymbol{g}_{\tau} + \gamma \boldsymbol{g}_{\tau}\right\Vert^2\\ &\lambda^{(k+1)} = \lambda^{(k)} - \lambda^{(k)}_{\tau} e_{\tau} + \gamma e_{\tau} \end{aligned}\right.\end{equation}
Comparing the Two
At this point, we have finished working through the solution to the primary-auxiliary-type multi-task learning problem studied in this post. For readers who have carefully worked through the mathematical results of both posts, it will surely feel like the methods and results for the parallel-type and primary-auxiliary-type cases are very similar. Indeed they are — they share many similarities, though they differ in subtle details.
To deepen everyone's understanding, we can compare the similarities and differences between these two types of multi-task learning as follows:
$$\small \begin{array}{c|c|c} \hline & \text{parallel multi-task learning (above)} & \text{primary-secondary multi-task learning (this paper)} \\ \hline \text{objective overview} & \text{learn every task well} & \text{learn main task well without worsening aux task} \\ \hline \text{incremental form} & \Delta\boldsymbol{\theta} = -\eta\boldsymbol{u} & \Delta\boldsymbol{\theta} = -\eta\boldsymbol{u} \\ \hline \text{mathematical definition} & \max\limits_{\boldsymbol{u}}\min\limits_i \langle \boldsymbol{g}_i, \boldsymbol{u}\rangle - \frac{1}{2}\Vert \boldsymbol{u}\Vert^2 & {\begin{array}{l}\max\limits_{\boldsymbol{u}} \langle\boldsymbol{u},\boldsymbol{g}_0\rangle - \frac{1}{2}\Vert\boldsymbol{u}\Vert^2 \\ \text{s.t.}\,\, \langle\boldsymbol{u},\boldsymbol{g}_1\rangle\geq 0,\cdots,\langle\boldsymbol{u},\boldsymbol{g}_n\rangle\geq 0\end{array}} \\ \hline \text{dual result} & \min\limits_{\alpha\in\mathbb{P}^n}^{\,^\,}\Vert\tilde{\boldsymbol{g}}(\alpha)\Vert^2 & \min\limits_{\lambda\in\mathbb{Q}^n}\Vert\boldsymbol{g}_0 + \tilde{\boldsymbol{g}}(\lambda)\Vert^2 \\ \hline \text{direction vector} & \boldsymbol{u}=\tilde{\boldsymbol{g}}(\alpha)=\sum\limits_i^{\,^\,} \alpha_i \boldsymbol{g}_i & \boldsymbol{u}=\boldsymbol{g}_0+\tilde{\boldsymbol{g}}(\lambda)=\boldsymbol{g}_0 + \sum\limits_i \lambda_i \boldsymbol{g}_i \\ \hline \text{feasible space} & \mathbb{P}^n = \left\{(\alpha_1,\cdots,\alpha_n)\left|\forall\alpha_i\geq 0, \sum\limits_i \alpha_i = 1\right.\right\} & \mathbb{Q}^n=\left\{(\lambda_1,\cdots,\lambda_n)\left|\forall\lambda_i\geq 0\right.\right\} \\ \hline \text{iteration step} & \left\{\begin{aligned} &\tau = \mathop{\text{argmin}}_i \langle \boldsymbol{g}_i, \tilde{\boldsymbol{g}}(\alpha^{(k)})\rangle\\ &\gamma = \mathop{\text{argmin}}_{\gamma} \left\Vert(1-\gamma)\tilde{\boldsymbol{g}}(\alpha^{(k)}) + \gamma \boldsymbol{g}_{\tau}\right\Vert^2\\ &\alpha^{(k+1)} = (1-\gamma)\alpha^{(k)} + \gamma e_{\tau} \end{aligned}\right. & \left\{\begin{aligned} &\tau = \mathop{\text{argmin}}_i \langle \boldsymbol{g}_i, \boldsymbol{g}_0+\tilde{\boldsymbol{g}}(\lambda^{(k)})\rangle\\ &\gamma = \mathop{\text{argmin}}_{\gamma} \left\Vert\boldsymbol{g}_0 + \tilde{\boldsymbol{g}}(\lambda^{(k)}) - \lambda^{(k)}_{\tau}\boldsymbol{g}_{\tau} + \gamma \boldsymbol{g}_{\tau}\right\Vert^2\\ &\lambda^{(k+1)} = \lambda^{(k)} - \lambda^{(k)}_{\tau} e_{\tau} + \gamma e_{\tau} \end{aligned}\right. \\ \hline \end{array}$$
With this comparison in hand, it's not hard to further generalize the result to a mixed-type multi-task learning setting with $n$ primary tasks and $m$ auxiliary tasks, whose dual result is:
\begin{equation}\min_{\alpha\in\mathbb{P}^n,\lambda\in\mathbb{Q}^m}\Vert\tilde{\boldsymbol{g}}(\alpha) + \tilde{\boldsymbol{g}}(\lambda)\Vert^2\end{equation}
As for the specific iterative algorithm, I leave that for readers to work out themselves~
Some Applications to Think About
In this section, we use several examples to show that many common problems can be mapped onto this kind of primary-auxiliary multi-task learning. In some sense, primary-auxiliary-type multi-task learning may actually be more common than parallel-type multi-task learning.
Regularization Losses
Perhaps the most common example is the regularization term added to a task's loss function, such as L2 regularization:
\begin{equation}\mathcal{L}(\boldsymbol{\theta}) + \frac{\lambda}{2}\Vert\boldsymbol{\theta}\Vert^2\end{equation}
If we regard $\mathcal{L}(\boldsymbol{\theta})$ and $\frac{1}{2}\Vert\boldsymbol{\theta}\Vert^2$ as the losses of two tasks, this too can be viewed as a multi-task learning problem. Clearly, we don't actually want $\frac{1}{2}\Vert\boldsymbol{\theta}\Vert^2$ to be as small as possible — we only hope that adding $\frac{1}{2}\Vert\boldsymbol{\theta}\Vert^2$ will improve the generalization performance of $\mathcal{L}(\boldsymbol{\theta})$. So this doesn't correspond to parallel-type multi-task learning, but rather fits much more naturally with primary-auxiliary-type multi-task learning.
The gradient of the L2 regularization term $\frac{1}{2}\Vert\boldsymbol{\theta}\Vert^2$ is quite simple — it's just $\boldsymbol{\theta}$. So, applying the result of this post $\eqref{eq:gamma}$, we can modify the optimizer by changing the gradient term to
\begin{equation}\boldsymbol{g} + \frac{\text{relu}(-\langle \boldsymbol{g},\boldsymbol{\theta}\rangle)}{\Vert\boldsymbol{\theta}\Vert^2}\end{equation}
This way, we can incorporate L2 regularization into the model without needing to tune the regularization coefficient $\lambda$. Of course, we could also, as AdamW does, directly process the original update to achieve a decoupled form of weight decay (Decoupled Weight Decay).
Beyond this kind of direct regularization on parameters, there are of course many other forms of auxiliary losses — for instance, adding a contrastive learning loss to a classification model, or adding a length penalty to a generative model, and so on. These practices can, to varying degrees, be mapped onto primary-auxiliary-type multi-task learning, so it's worth trying to apply the results of this post to them. If computing the full gradient feels too expensive, one can also, as in the previous post, approximate the "shared encoder" case to reduce the computational cost.
Learning with Noisy Data
There is also a common training scenario that people may not realize is actually a multi-task learning problem, but which can indeed essentially be understood as one — namely, "learning with noisy data."
Suppose that for a given task, we only have a small amount of cleanly labeled data, but also a large amount of noisy data. Since the noisy data is much more abundant, we tend to train primarily on it — say the corresponding loss is $\mathcal{L}_0$. However, because the data contains noise, purely minimizing $\mathcal{L}_0$ may not produce an ideal model; it might end up memorizing the incorrect labels as well. This is where the clean data can come in handy: we can compute a loss $\mathcal{L}_1$ on the clean data. Since the clean data has much less noise, we can consider $\mathcal{L}_1$ to be a better reflection of the model's true performance than $\mathcal{L}_0$, so we can add a constraint:
No matter how we minimize $\mathcal{L}_0$, we must not let $\mathcal{L}_1$ increase. In other words, you may train on noisy data, but you cannot allow the performance on clean data to get worse.
This is exactly a primary-auxiliary-type multi-task learning problem with $\mathcal{L}_0$ as primary and $\mathcal{L}_1$ as auxiliary!
Coincidentally, a Google paper from last year, Gradient-guided Loss Masking for Neural Machine Translation, presented a similar approach, though the details differ slightly. It computes, for each noisy sample, its gradient with respect to the parameters, and keeps only those samples whose gradient forms an angle less than 90 degrees with the clean-data gradient $\nabla_{\boldsymbol{\theta}} \mathcal{L}_1$ (i.e., inner product greater than 0). In other words, both approaches use the inner product with the clean-data gradient as the criterion. The difference is that in primary-auxiliary-type multi-task learning, when the inner product is negative, the update is corrected, whereas in the Google paper, the corresponding sample is simply discarded.
Summary
This post extends the results of the previous post on parallel-type multi-task learning to "primary-auxiliary"-type multi-task learning, where the goal of multi-task learning is no longer to do well on all tasks simultaneously, but rather to treat one task as primary and the rest as auxiliary. The results share quite a few similarities with those of parallel-type multi-task learning, yet differ in subtle ways. Finally, we introduced some classic examples of primary-auxiliary-type multi-task learning, such as regularization terms and learning with noisy data.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.