SquarePlus: Perhaps the Simplest-to-Compute Smooth Approximation of ReLU
The ReLU function, i.e. $\max(x,0)$, is one of the most common activation functions, yet its non-differentiability at $x=0$ is usually seen as one of its "pain points." To address this, various smooth approximations have been proposed, such as SoftPlus, GeLU, Swish, etc. However, without exception, these smooth approximations all involve at least an exponential operation $e^x$ (and SoftPlus also uses a logarithm), which, from a "penny-pinching" point of view, is not a negligible amount of computation (although with GPU acceleration nowadays, we rarely notice this cost). A recent paper, Squareplus: A Softplus-Like Algebraic Rectifier, proposes an even simpler approximation called SquarePlus, which we'll discuss here.
Before we begin, I should point out that I don't recommend spending too much time on the choice and design of activation functions. So although I'm sharing this paper, it's mainly to provide a reference result and to serve as an "exercise" for practice.
Definition
SquarePlus has a very simple form, using only addition, multiplication, division, and square roots:
\begin{equation}\text{SquarePlus}(x)=\frac{x+\sqrt{x^2+b}}{2}\end{equation}more
where $b > 0$. When $b=0$, it degenerates exactly to $\text{ReLU}(x)=\max(x,0)$. The intuition behind SquarePlus roughly comes from
\begin{equation}\max(x,0)=\frac{x+|x|}{2}=\frac{x+\sqrt{x^2}}{2}\end{equation}
so, to fix up the differentiability at $x=0$, a constant $b$ greater than 0 is added inside the square root (to prevent the derivative from involving division by zero).
The original paper points out that, since it only uses addition, multiplication, division, and square roots, SquarePlus is faster (mainly on CPUs) than functions like SoftPlus:
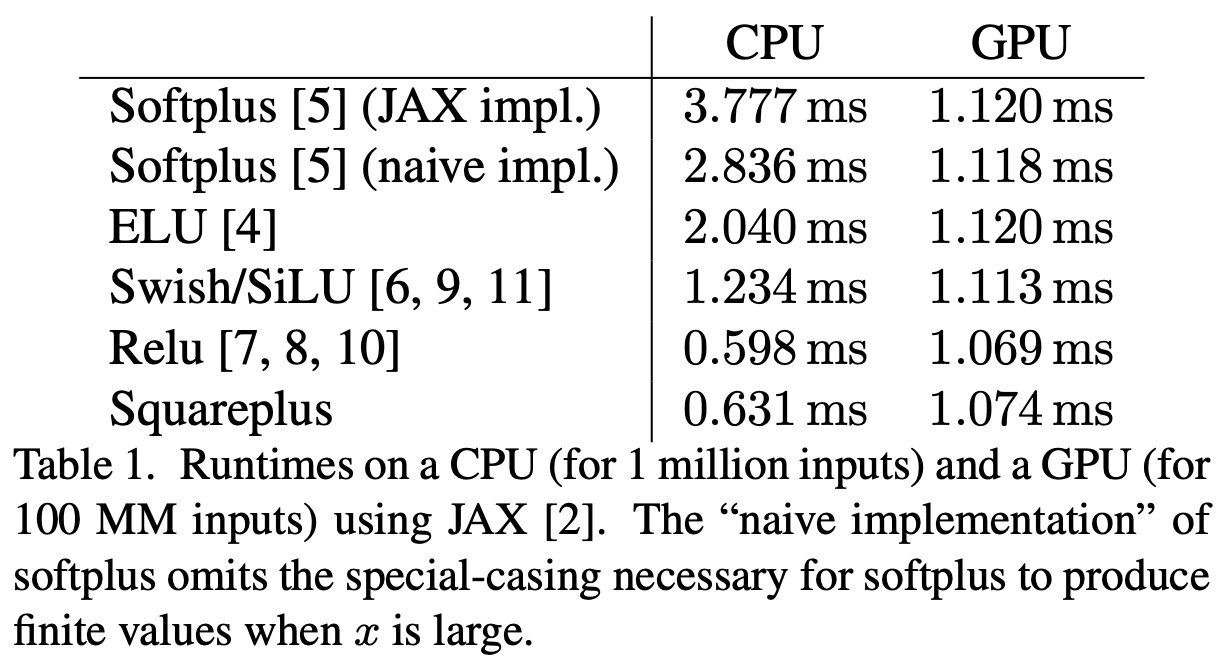 Speed comparison between SquarePlus and other similar functions
Of course, if you don't care about this speedup, then as mentioned at the start of the article, feel free to just treat this as a math exercise.
Behavior
Like the SoftPlus function ($\log(e^x+1)$), SquarePlus is also globally monotonically increasing, and is always greater than ReLU, as shown in the figure below (in the figure, SquarePlus's $b=1$):
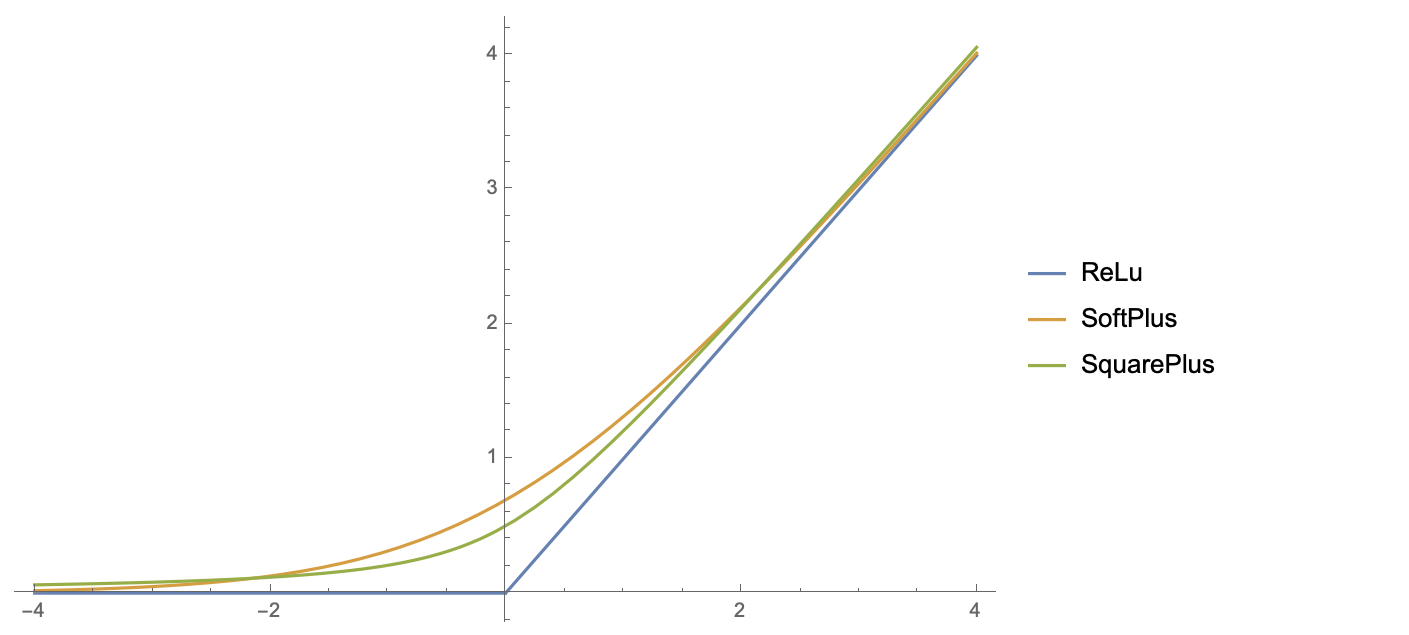 ReLU, SoftPlus, SquarePlus function plots (1)
We can also see the monotonicity directly by computing its derivative:
\begin{equation}\frac{d}{dx}\text{SquarePlus}(x)=\frac{1}{2}\left(1+\frac{x}{\sqrt{x^2+b}}\right) > 0\end{equation}
As for the second derivative
\begin{equation}\frac{d^2}{dx^2}\text{SquarePlus}(x)=\frac{b}{2(x^2+b)^{3/2}}\end{equation}
it is also always greater than 0, so SquarePlus is also a convex function.
Approximation
Now we have two exercises to work through:
1. For what values of $b$ is SquarePlus always greater than SoftPlus?
2. For what value of $b$ is the error between SquarePlus and SoftPlus minimized?
For the first question, solving directly from $\text{SquarePlus}(x)\geq \text{SoftPlus}(x)$ gives:
\begin{equation}b\geq 4\log(e^x+1)\left[\log(e^x+1) - x\right]=4\log(e^x+1)\log(e^{-x}+1)\end{equation}
For this inequality to hold everywhere, $b$ must be greater than or equal to the maximum value of the right-hand side, and we can show that the maximum of the right-hand side is attained at $x=0$, so $b\geq 4\log^2 2=1.921812\cdots$. This settles the first question.
Proof: Notice that
\begin{equation} > \frac{d^2}{dx^2}\log\log(e^x+1)=\frac{e^x(\log(e^x+1)-e^x)}{(e^x+1)^2\log^2(e^x+1)} < 0\end{equation}
so $\log\log(e^x+1)$ is a concave function, and thus by Jensen's inequality
\begin{equation} > \frac{1}{2}\left(\log\log(e^x+1) + \log\log(e^{-x}+1)\right)\leq \log\log(e^{(x+(-x))/2}+1)=\log\log 2\end{equation}
that is, $\log\left(\log(e^x+1)\log(e^{-x}+1)\right)\leq 2\log\log 2$, or $\log(e^x+1)\log(e^{-x}+1)\leq \log^2 2$; multiplying both sides by 4 gives the desired result. The equality holds when $x=-x$, i.e., $x=0$.
As for the second question, we need a criterion for "error." As in the earlier post Where Do the Two Elementary-Function Approximations of GELU Come From?, we convert this into a parameter-free $\min\text{-}\max$ problem:
\begin{equation}\min_{b} \max_x \left|\frac{x+\sqrt{x^2+b}}{2} - \log(e^x+1)\right|\end{equation}
I haven't been able to find an analytical solution to this problem, so for now it can only be solved numerically:
import numpy as np
from scipy.special import erf
from scipy.optimize import minimize

def f(x, a):
    return np.abs((x + np.sqrt(x**2 + a**2)) / 2 - np.log(np.exp(x) + 1))

def g(a):
    return np.max([f(x, a) for x in np.arange(-2, 4, 0.0001)])

options = {'xtol': 1e-10, 'ftol': 1e-10, 'maxiter': 100000}
result = minimize(g, 0, method='Powell', options=options)
b = result.x**2
print(b)
The final computed result is $b=1.52382103\cdots$, with a maximum error of $0.075931\cdots$. The comparison is shown below:
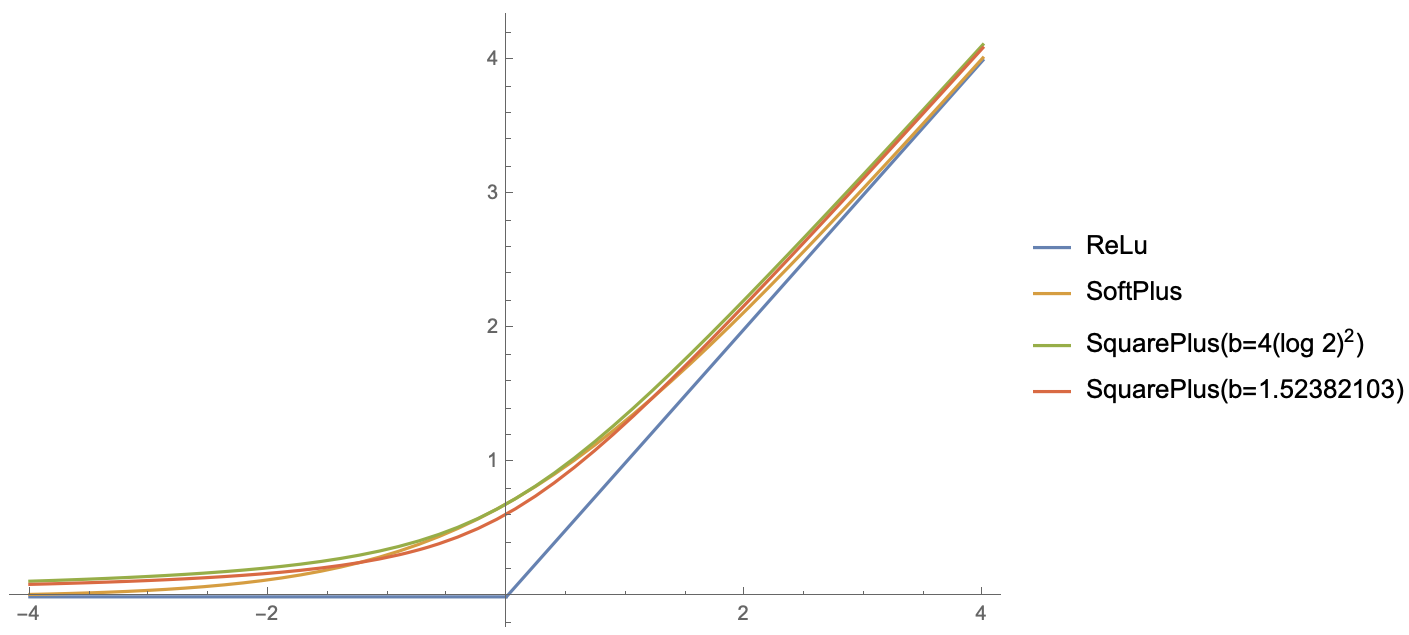 ReLU, SoftPlus, SquarePlus function plots (2)
Summary
There isn't really much to summarize here — this post just introduced a smooth approximation of ReLU, along with two simple functional exercises to go with it.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.