Where do GELU's two elementary-function approximations come from?
GELU, short for Gaussian Error Linear Unit, can be regarded as a variant of ReLU—an activation function that has no elementary closed form. It was proposed in the paper Gaussian Error Linear Units (GELUs), and was subsequently used in GPT, then in BERT, and then in quite a few later pretrained language models as well. As BERT and other pretrained language models rose to prominence, GELU rode along with them, and somehow ended up becoming a popular activation function.
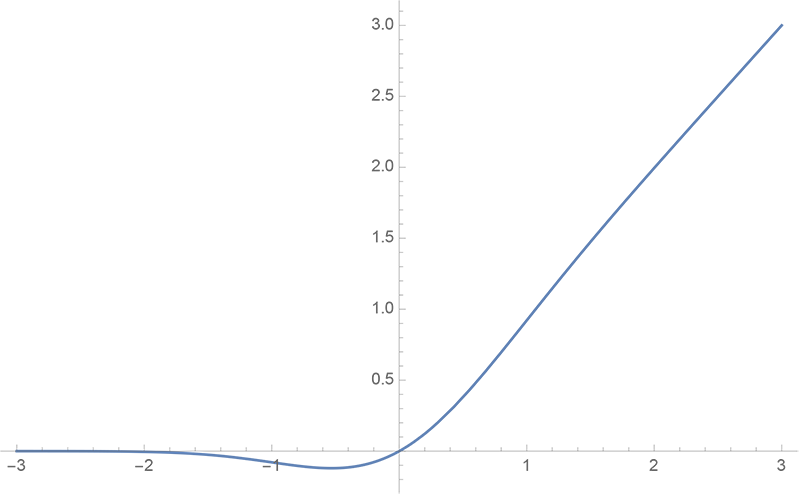 GELU function plot
In the original GELU paper, the authors not only give the exact form of GELU, but also provide two elementary-function approximations. This post discusses how these approximations were derived.more
The GELU function
The GELU function has the form
\begin{equation}\text{GELU}(x)=x \Phi(x)\end{equation}
where $\Phi(x)$ is the cumulative distribution function of the standard normal distribution, i.e.
\begin{equation}\Phi(x)=\int_{-\infty}^x \frac{e^{-t^2/2}}{\sqrt{2\pi}}dt=\frac{1}{2}\left[1 + \text{erf}\left(\frac{x}{\sqrt{2}}\right)\right]\end{equation}
with $\text{erf}(x)=\frac{2}{\sqrt{\pi}}\int_0^x e^{-t^2}dt$ here. The original paper then proposed two approximations:
\begin{equation}x\Phi(x)\approx x\sigma(1.702 x)\label{eq:x-sigma}\end{equation}
and
\begin{equation}x\Phi(x)\approx \frac{1}{2} x \left[1 + \tanh\left(\sqrt{\frac{2}{\pi}}\left(x + 0.044715 x^3\right)\right)\right]\label{eq:x-phi}\end{equation}
Even now, quite a few implementations of Transformer architectures use approximation $\eqref{eq:x-phi}$ as their implementation of the GELU function. That said, many frameworks already provide exact computation of $\text{erf}$, so the value of these elementary-function approximations may not be all that large in practice—so let's just treat this as a mathematical-analysis exercise.
What should we use to approximate it?
Clearly, finding an approximation for GELU is equivalent to finding an approximation for $\Phi(x)$, which is in turn equivalent to finding an approximation for $\text{erf}\left(\frac{x}{\sqrt{2}}\right)$.
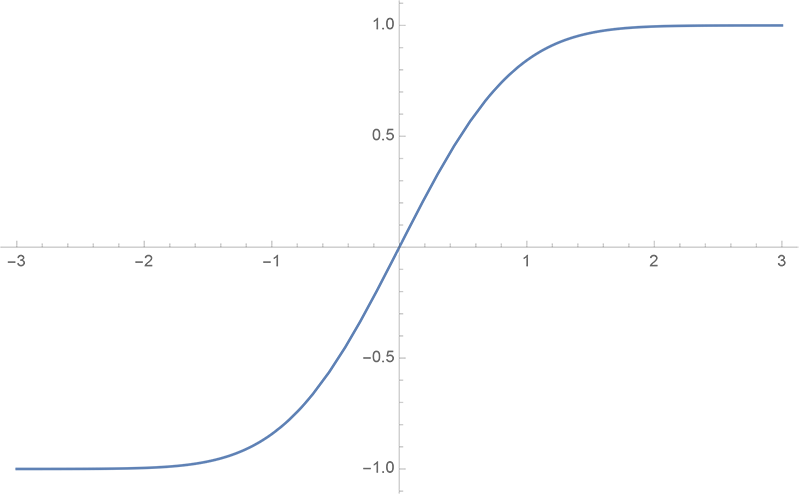 erf function plot
First, we need to settle the first question: what kind of function should we use for the approximation? Looking at the plot of $\text{erf}(x)$, we can identify its characteristic features:
1. It is an odd function, i.e. $\text{erf}(x)=-\text{erf}(-x)$;
2. It is monotonically increasing, and $\lim\limits_{x\to -\infty}\text{erf}(x)=-1, \lim\limits_{x\to +\infty}\text{erf}(x)=1$.
There are plenty of odd functions available—$x^{2n+1},\sin x, \tan x, \tanh x$, for instance—and sums or compositions of odd functions remain odd, e.g. $\sin\left(x + x^3\right)$. A function that is odd, monotonically increasing, and bounded is something we would most readily think of as $\tanh x$; and indeed, $\tanh x$ does look quite similar to $\text{erf}(x)$.
So we can start from $\tanh x$ and construct some candidate forms for fitting, such as
\begin{equation}\left\{\begin{aligned} &\tanh\left(a x + b x^3 + c x^5\right)\\ &a\tanh x + b \tanh^3 x + c \tanh^5 x\\ &a\tanh bx + c \tanh dx + e \tanh fx\\ &\vdots \end{aligned}\right.\end{equation}
How do we do the approximation?
Having settled on a form to fit, the next question is how to fit it and by what criterion—in plain terms, how do we work out the coefficients? Generally speaking, there are two approaches: local fitting and global fitting.
Local fitting
Local fitting is based on Taylor expansion. For example, consider the approximate form $\tanh\left(a x + b x^3\right)$; expanding around $x=0$ gives
\begin{equation}\text{erf}\left(\frac{x}{\sqrt{2}}\right) - \tanh\left(a x + b x^3\right)=\left(\sqrt{\frac{2}{\pi }}-a\right) x + \left(\frac{a^3}{3}-b-\frac{1}{3 \sqrt{2 \pi }}\right)x^3 + \dots\end{equation}
Setting the first two terms to zero gives us exactly two equations, and solving them yields
\begin{equation}a=\sqrt{\frac{2}{\pi}},\quad b=\frac{4-\pi }{3 \sqrt{2} \pi ^{3/2}}\end{equation}
Substituting into $x\Phi(x)$ and converting to numerical form gives
\begin{equation}x\Phi(x)\approx \frac{1}{2} x\left[1 + \tanh\left(\sqrt{\frac{2}{\pi}}\left(x + 0.0455399 x^3\right)\right)\right]\label{eq:x-phi-local}\end{equation}
Global fitting
Equation $\eqref{eq:x-phi-local}$ is already very close to equation $\eqref{eq:x-phi}$, but the second coefficient is still a bit off. This is because $\eqref{eq:x-phi-local}$ is purely a result of local approximation—as the name suggests, a local approximation is very accurate locally (in this case, the derivation above is based on a Taylor expansion around $x=0$, so it is quite accurate near $x=0$), but the error grows larger further away from 0. So we also need to take global error into account.
The most natural notion of global error is one in integral form—for example, when using $g(x,\theta)$ to approximate $f(x)$, we could compute
\begin{equation}\min_{\theta} \int [f(x)-g(x,\theta)]^2 dx \quad\text{or}\quad \min_{\theta} \int |f(x)-g(x,\theta)| dx \end{equation}
But the importance of the error at each point $x$ may not be uniform, so to keep things general we should multiply by a weight $\lambda(x)$, giving
\begin{equation}\min_{\theta} \int \lambda(x)[f(x)-g(x,\theta)]^2 dx \quad\text{or}\quad \min_{\theta} \int \lambda(x)|f(x)-g(x,\theta)| dx \end{equation}
Different choices of $\lambda(x)$ lead to different solutions, and it's not at all obvious which $\lambda(x)$ is the "right" one.
So instead of optimizing this kind of integral-form error, let's optimize a more intuitive error in $\min-\max$ form:
\begin{equation}\min_{\theta} \max_x |f(x)-g(x,\theta)|\end{equation}
This expression is easy to understand: it says "find a suitable $\theta$ such that the largest $|f(x)-g(x,\theta)|$ is as small as possible." This matches our intuition well, and it sidesteps the issue of choosing a weight altogether.
Hybrid fitting
Building on this idea, we fix $a=\sqrt{\frac{2}{\pi}}$ and then re-solve for $\tanh\left(a x + b x^3\right)$. We fix this $a$ because it comes from the first-order local approximation, and we want to retain some degree of local approximation while letting $b$ help reduce the global error as much as possible—thereby achieving a hybrid of local and global approximation. So now we need to solve
\begin{equation}\min_{b} \max_x \left|\text{erf}\left(\frac{x}{\sqrt{2}}\right)-\tanh\left(a x + b x^3\right)\right|\end{equation}
This is easily solved with scipy:
import numpy as np
from scipy.special import erf
from scipy.optimize import minimize

def f(x, b):
    a = np.sqrt(2 / np.pi)
    return np.abs(erf(x / np.sqrt(2)) - np.tanh(a * x + b * x**3))

def g(b):
    return np.max([f(x, b) for x in np.arange(0, 4, 0.001)])

options = {'xtol': 1e-10, 'ftol': 1e-10, 'maxiter': 100000}
result = minimize(g, 0, method='Powell', options=options)
print(result.x)
The result is $b=0.035677337314877385$, giving the form:
\begin{equation}x\Phi(x)\approx \frac{1}{2} x\left[1 + \tanh\left(\sqrt{\frac{2}{\pi}}\left(x + 0.04471491123850965 x^3\right)\right)\right]\label{eq:x-phi-global}\end{equation}
The last few significant digits might be slightly off, but the leading part already matches equation $\eqref{eq:x-phi}$ perfectly. As an aside, equation $\eqref{eq:x-phi}$ was actually proposed in the paper Approximations to the Cumulative Normal Function and its Inverse for Use on a Pocket Calculator, a result that's already more than 40 years old.
As for the first approximation, it comes from the paper A logistic approximation to the cumulative normal distribution, and is obtained by directly using $\sigma(\lambda x)$ to globally approximate $\Phi(x)$, i.e.
\begin{equation}\min_{\lambda}\max_{x}\left|\Phi(x) - \sigma(\lambda x)\right|\end{equation}
Solving this gives $\lambda=1.7017449256323682$, i.e.
\begin{equation}\Phi(x)\approx \sigma(1.7017449256323682 x)\end{equation}
which likewise matches equation $\eqref{eq:x-sigma}$ quite well.
Summary
In this post we worked through a little exercise in mathematical analysis together—introducing the GELU activation function and trying to trace the origins of its two approximation formulas. And with that, we've successfully squeezed out another blog post.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.