Linear Models Through a Probabilistic Lens: Does Logistic Regression Have an Analytical Solution?
As we know, linear regression is a relatively simple problem with an analytical solution, while its variant, logistic regression, has no such solution — which is rather a shame. Although logistic regression also has "regression" in its name, it is actually used for classification problems, and for many readers classification is even more common than regression. To be precise, when we say logistic regression has no analytical solution, what we really mean is "under maximum likelihood estimation, logistic regression has no analytical solution." So does this mean that if we abandon maximum likelihood estimation, we might be able to find a usable analytical solution instead?
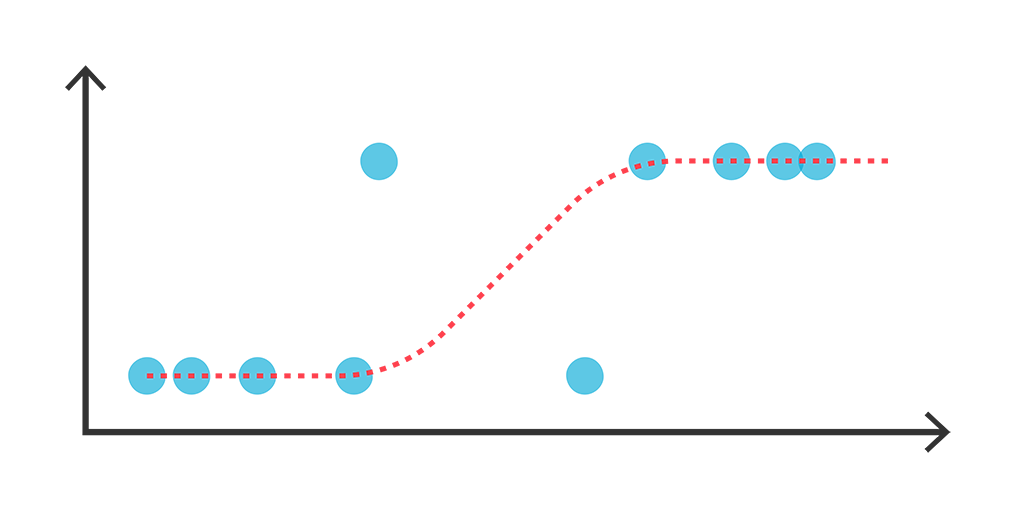 Logistic regression illustration
This post derives an analytical solution for logistic regression from a non-maximum-likelihood perspective. Simple experiments show that its performance is not inferior to the maximum likelihood solution obtained via gradient descent. Moreover, this analytical solution can easily be extended to single-layer Softmax multi-class classification models. more
Linear Regression
Let's first review linear regression. Suppose the training data is $\{(\boldsymbol{x}_i,\boldsymbol{y}_i)\}_{i=1}^N$, where $\boldsymbol{x}\in\mathbb{R}^n,\boldsymbol{y}\in\mathbb{R}^m$; for convenience of alignment with code implementations, we default to treating vectors as row vectors here. Linear regression assumes that $\boldsymbol{x},\boldsymbol{y}$ satisfies the linear relationship $\boldsymbol{y}=\boldsymbol{x}\boldsymbol{W}+\boldsymbol{b}$, where $\boldsymbol{W}\in\mathbb{R}^{n\times m},\boldsymbol{b}\in\mathbb{R}^m$, and the parameters are estimated by minimizing the following mean squared error:
\begin{equation}\frac{1}{N}\sum_{i=1}^N \Vert\boldsymbol{y}_i-\boldsymbol{x}_i\boldsymbol{W}-\boldsymbol{b}\Vert^2\label{eq:loss}\end{equation}
This objective can be solved simply by expanding it and taking derivatives — it's just the minimization of a quadratic function, so it has an analytical solution.
A Probabilistic Perspective
From the perspective of probability distributions, mean squared error implicitly assumes that $p(\boldsymbol{y}|\boldsymbol{x})$ follows a normal distribution with mean $\boldsymbol{\mu}_{y|x}=\boldsymbol{x}\boldsymbol{W}+\boldsymbol{b}$. Now, let's make a stronger assumption:
Assume that the joint distribution $p(\boldsymbol{x},\boldsymbol{y})$ is normal.
Under this assumption, we can directly write down the corresponding conditional distribution:
\begin{equation}\begin{aligned} p(\boldsymbol{y}|\boldsymbol{x}) =&\, \mathcal{N}(\boldsymbol{y};\boldsymbol{\mu}_{y|x},\boldsymbol{\Sigma}_{y|x})\\ \boldsymbol{\mu}_{y|x} =&\, \boldsymbol{\mu}_y + (\boldsymbol{x}-\boldsymbol{\mu}_x)\boldsymbol{\Sigma}_{xx}^{-1}\boldsymbol{\Sigma}_{xy}\\ \boldsymbol{\Sigma}_{y|x} =&\, \boldsymbol{\Sigma}_{yy} - \boldsymbol{\Sigma}_{yx}\boldsymbol{\Sigma}_{xx}^{-1}\boldsymbol{\Sigma}_{xy} \end{aligned}\end{equation}
Here $\boldsymbol{\mu}_x,\boldsymbol{\mu}_y$ is the mean vector of $\boldsymbol{x},\boldsymbol{y}$, and $\begin{pmatrix}\boldsymbol{\Sigma}_{xx} & \boldsymbol{\Sigma}_{xy} \\ \boldsymbol{\Sigma}_{yx} & \boldsymbol{\Sigma}_{yy}\end{pmatrix}$ is the covariance matrix of $\boldsymbol{x},\boldsymbol{y}$. The form of the conditional distribution of a normal distribution can be found directly on Wikipedia; its proof can be found on StackExchange or in relevant probability and statistics textbooks.
Now, comparing this with $\boldsymbol{\mu}_{y|x}=\boldsymbol{x}\boldsymbol{W}+\boldsymbol{b}$, we obtain
\begin{equation}\boldsymbol{W} = \boldsymbol{\Sigma}_{xx}^{-1}\boldsymbol{\Sigma}_{xy}, \quad \boldsymbol{b} = \boldsymbol{\mu}_y - \boldsymbol{\mu}_x\boldsymbol{\Sigma}_{xx}^{-1}\boldsymbol{\Sigma}_{xy}\end{equation}
This is in fact exactly the analytical solution of linear regression.
Reflection and Analysis
Let's walk through the above process again. By default, linear regression only makes the assumption about the conditional distribution $p(\boldsymbol{y}|\boldsymbol{x})$, and the least squares method gives us the analytical solution for linear regression — this is the conventional way of introducing linear regression. Then, above, we made a stronger assumption — "the joint distribution $p(\boldsymbol{x},\boldsymbol{y})$ is normal" — yet still arrived at exactly the same analytical solution.
Why does a stronger assumption yield the same result? In fact, we can see from the loss function $\eqref{eq:loss}$ that it is quadratic in $\boldsymbol{y}$ and quadratic in $\boldsymbol{x}$ as well, which means it only ever uses second-order moment information about $\boldsymbol{x},\boldsymbol{y}$ at most. Therefore, assuming the joint distribution is normal doesn't change the final result, because the normal distribution already preserves all moment information up to second order (mean and covariance).
Going further, we can imagine that for any linear model (linear regression, logistic regression, single-layer neural networks, etc.), the main statistics of the data it relies on should likewise be no higher than second-order moments. Therefore, when dealing with linear models, we can appropriately make a normality assumption depending on the situation; in theory, this should yield an equivalent result, or at least a sufficiently good approximation.
Logistic Regression
Using the idea above, we can derive an analytical solution for logistic regression. This result was first seen by the author in Easy Logistic Regression with an Analytical Solution, and having found it quite enlightening, I'd like to share it here.
Suppose the training data is $\{(\boldsymbol{x}_i,y_i)\}_{i=1}^N$, where $\boldsymbol{x}\in\mathbb{R}^n,y\in\{0,1\}$, meaning this is a binary classification dataset. We build the probabilistic model
\begin{equation}p(y|\boldsymbol{x}) = \left\{\begin{aligned}\sigma\left(\boldsymbol{x}\boldsymbol{w}^{\top}+b\right),\quad (y = 1)\\ 1 - \sigma\left(\boldsymbol{x}\boldsymbol{w}^{\top}+b\right),\quad (y = 0)\end{aligned}\right.\end{equation}
Here $\sigma(t)=1/(1+e^{-t})$. The conventional way of estimating $\boldsymbol{w},b$ is maximum likelihood, i.e., minimizing the following loss:
\begin{equation}-\frac{1}{N}\sum_{i=1}^N \ln p(y_i|\boldsymbol{x}_i)\end{equation}
We can't compute an analytical solution for this. However, if we abandon the maximum likelihood route and design a different solution path, it turns out to be possible to obtain an analytical solution.
A Different Approach
First, it's not hard to verify that for the logistic regression model, we have:
\begin{equation}\frac{p(1|\boldsymbol{x})}{p(0|\boldsymbol{x})} = \exp\left(\boldsymbol{x}\boldsymbol{w}^{\top}+b\right) \quad\Leftrightarrow\quad \ln \frac{p(1|\boldsymbol{x})}{p(0|\boldsymbol{x})} = \boldsymbol{x}\boldsymbol{w}^{\top}+b\label{eq:log}\end{equation}
That is to say, logistic regression is equivalent to a linear regression model with $\ln \frac{p(1|\boldsymbol{x})}{p(0|\boldsymbol{x})}$ as the output. However, directly estimating $\ln \frac{p(1|\boldsymbol{x})}{p(0|\boldsymbol{x})}$ is not easy, so we make use of Bayes' formula:
\begin{equation}p(y|\boldsymbol{x}) = \frac{p(\boldsymbol{x}|y)p(y)}{p(\boldsymbol{x})} \quad\Leftrightarrow\quad \frac{p(1|\boldsymbol{x})}{p(0|\boldsymbol{x})} = \frac{p(\boldsymbol{x}|1)p_1}{p(\boldsymbol{x}|0)p_0}\label{eq:bys}\end{equation}
Here $p_1,p_0$ are the probabilities of the positive and negative classes respectively, which are easy to estimate. $p(\boldsymbol{x}|1),p(\boldsymbol{x}|0)$ is naturally the distribution satisfied by the positive and negative samples, and now we make a normality assumption about them:
Assume that $p(\boldsymbol{x}|1),p(\boldsymbol{x}|0)$ are normal distributions sharing the same covariance matrix.
Readers may find the phrase "sharing the same covariance matrix" somewhat puzzling here — we'll come back to this point later. Under this assumption, let
\begin{equation}p(\boldsymbol{x}|1) = \mathcal{N}(\boldsymbol{x};\boldsymbol{\mu}_1,\boldsymbol{\Sigma}),\quad p(\boldsymbol{x}|0) = \mathcal{N}(\boldsymbol{x};\boldsymbol{\mu}_0,\boldsymbol{\Sigma})\end{equation}
where $\boldsymbol{\mu}_1,\boldsymbol{\mu}_0$ are the mean vectors of the positive and negative samples respectively, and $\boldsymbol{\Sigma}$ can be estimated using the covariance matrix of the full dataset. Recalling the probability density expression of the normal distribution:
\begin{equation}\frac{1}{\sqrt{(2\pi)^n \det(\boldsymbol{\Sigma})}}\exp\left\{-\frac{1}{2}(\boldsymbol{x}-\boldsymbol{\mu})\boldsymbol{\Sigma}^{-1}(\boldsymbol{x}-\boldsymbol{\mu})^{\top}\right\}\end{equation}
substituting into equation $\eqref{eq:bys}$ and expanding and simplifying, we find that the quadratic terms exactly cancel out, giving us
\begin{equation}\ln\frac{p(1|\boldsymbol{x})}{p(0|\boldsymbol{x})} = \ln\frac{p(\boldsymbol{x}|1)p_1}{p(\boldsymbol{x}|0)p_0} = \boldsymbol{x}\boldsymbol{\Sigma}^{-1}(\boldsymbol{\mu}_1 - \boldsymbol{\mu}_0)^{\top} + \frac{1}{2}\left(\boldsymbol{\mu}_0\boldsymbol{\Sigma}^{-1}\boldsymbol{\mu}_0^{\top} - \boldsymbol{\mu}_1\boldsymbol{\Sigma}^{-1}\boldsymbol{\mu}_1^{\top}\right) + \ln\frac{p_1}{p_0}\label{eq:rate}\end{equation}
Comparing this with equation $\eqref{eq:log}$, we obtain:
\begin{equation}\begin{aligned} \boldsymbol{w} =&\, (\boldsymbol{\mu}_1 - \boldsymbol{\mu}_0)\boldsymbol{\Sigma}^{-1}\\ b =&\, \frac{1}{2}\left(\boldsymbol{\mu}_0\boldsymbol{\Sigma}^{-1}\boldsymbol{\mu}_0^{\top} - \boldsymbol{\mu}_1\boldsymbol{\Sigma}^{-1}\boldsymbol{\mu}_1^{\top}\right) + \ln\frac{p_1}{p_0} \end{aligned}\label{eq:sol}\end{equation}
This is an analytical solution for logistic regression. Of course, this isn't a particularly novel idea — its underlying logic is quite consistent with Linear Discriminant Analysis.
Reflection and Analysis
At this point, readers probably have the most doubts about whether the "shared covariance matrix" assumption is too strong. From a technical standpoint, this assumption is made precisely so that the quadratic terms in $\ln\frac{p(\boldsymbol{x}|1)}{p(\boldsymbol{x}|0)}$ cancel out exactly, leaving only linear terms and thereby directly yielding the analytical solution for logistic regression. But from a theoretical standpoint, is there any necessity behind this assumption? In fact, we can argue that logistic regression itself already (approximately) implies the "shared covariance matrix" assumption.
How should we understand this? First, for the logistic regression model, equation $\eqref{eq:log}$ holds naturally, and Bayes' formula always holds as well, so the conclusion is that $\ln\frac{p(\boldsymbol{x}|1)}{p(\boldsymbol{x}|0)}$ must consist of only a linear term and a constant term. And the linear regression example has already told us that making a normality assumption about the data distribution for a linear model generally doesn't lose any information, so assuming $p(\boldsymbol{x}|1),p(\boldsymbol{x}|0)$ is normal is (to some extent) also reasonable. And once we assume they are normal, if we want the result to have no quadratic term, the covariance matrices must be identical.
In other words, from the moment you decide to use a logistic regression model and accept the normality assumption, you've already implicitly made the assumption that "the positive and negative samples share the same covariance matrix"!
Multi-Class Classifier
The analytical solution for logistic regression above can also be conveniently extended to the "fully-connected layer + Softmax" multi-class scenario, where the probability of class $i$ is assumed to be
\begin{equation}p(i|\boldsymbol{x}) = \frac{\exp\left(\boldsymbol{x}\boldsymbol{w}_i^{\top}+b_i\right)}{\sum\limits_{i=1}^k \exp\left(\boldsymbol{x}\boldsymbol{w}_i^{\top}+b_i\right)}\end{equation}
Based on the same reasoning and assumptions, we can obtain a result analogous to equation $\eqref{eq:log}$:
\begin{equation}\ln \frac{p(j|\boldsymbol{x})}{p(i|\boldsymbol{x})} = \boldsymbol{x}(\boldsymbol{w}_j - \boldsymbol{w}_i)^{\top}+(b_j - b_i)\end{equation}
as well as a result analogous to equation $\eqref{eq:rate}$:
\begin{equation}\ln\frac{p(j|\boldsymbol{x})}{p(i|\boldsymbol{x})} = \boldsymbol{x}\boldsymbol{\Sigma}^{-1}(\boldsymbol{\mu}_j - \boldsymbol{\mu}_i)^{\top} + \frac{1}{2}\left(\boldsymbol{\mu}_i\boldsymbol{\Sigma}^{-1}\boldsymbol{\mu}_i^{\top} - \boldsymbol{\mu}_j\boldsymbol{\Sigma}^{-1}\boldsymbol{\mu}_j^{\top}\right) + \ln\frac{p_j}{p_i}\end{equation}
Comparing the two, we find that one solution is:
\begin{equation}\begin{aligned} \boldsymbol{w}_i =&\, \boldsymbol{\mu}_i\boldsymbol{\Sigma}^{-1}\\ b_i =&\, \ln p_i - \frac{1}{2}\boldsymbol{\mu}_i\boldsymbol{\Sigma}^{-1}\boldsymbol{\mu}_i^{\top} \end{aligned}\end{equation}
Parameter Estimation
To close out the theoretical part, let's discuss how to estimate the model parameters. We can see that $\boldsymbol{w}_i,b_i$ is a function of $p_i$, $\boldsymbol{\mu}_i$, and $\boldsymbol{\Sigma}$, so essentially we need to estimate these three quantities.
As mentioned earlier, $p_i$ is fairly simple — just use the frequency of each class directly. $\boldsymbol{\mu}_i$ isn't difficult either — it's just the mean vector of each class. So the difficulty lies in estimating $\boldsymbol{\Sigma}$. Based on our earlier assumptions, the distribution of the full dataset is
\begin{equation}\tilde{p}(\boldsymbol{x}) = \sum_{i=1}^k p_i \mathcal{N}(\boldsymbol{x};\boldsymbol{\mu}_i,\boldsymbol{\Sigma})\end{equation}
Multiplying both sides by $\boldsymbol{x}^{\top}\boldsymbol{x}$ and integrating, we obtain
\begin{equation}\tilde{\boldsymbol{\Sigma}}+\tilde{\boldsymbol{\mu}}^{\top} \tilde{\boldsymbol{\mu}} = \sum_{i=1}^k p_i \left(\boldsymbol{\Sigma}+\boldsymbol{\mu}_i^{\top} \boldsymbol{\mu}_i\right) = \boldsymbol{\Sigma} + \sum_{i=1}^k p_i\, \boldsymbol{\mu}_i^{\top} \boldsymbol{\mu}_i\end{equation}
where $\tilde{\boldsymbol{\mu}},\tilde{\boldsymbol{\Sigma}}$ are the mean vector and covariance matrix of the full dataset. Therefore we have the estimate
\begin{equation}\boldsymbol{\Sigma} = \tilde{\boldsymbol{\Sigma}}+\tilde{\boldsymbol{\mu}}^{\top} \tilde{\boldsymbol{\mu}} - \sum_{i=1}^k p_i\, \boldsymbol{\mu}_i^{\top} \boldsymbol{\mu}_i\end{equation}
In particular, we recommend whitening the raw data before estimation (see You May Not Need BERT-flow: A Linear Transformation That Rivals BERT-flow), so that the full dataset has zero mean and identity covariance, and then performing the estimation. In that case
\begin{equation}\boldsymbol{\Sigma} = \boldsymbol{I} - \sum_{i=1}^k p_i\, \boldsymbol{\mu}_i^{\top} \boldsymbol{\mu}_i\end{equation}
In theory, whitening first and then estimating should give exactly the same result as estimating directly. In practice, however, for high-dimensional data, whitening beforehand makes the numerical computation considerably more stable, so in practice we recommend whitening first and then estimating.
Experimental Evaluation
So how usable is the analytical solution derived above? Can it match the solution found via gradient descent? Here we run several text-classification experiments, all using RoFormer-Sim-FT to extract fixed sentence-vector features, followed by a fully-connected classification layer, comparing the performance gap between the solution obtained via gradient descent and the analytical solution above. The experimental code is open-sourced here:
Github: https://github.com/bojone/analytical-classification
Full Sample Set
The evaluation covers four classification tasks: sentiment classification (SENTIMENT), long-text classification (IFLYTEK), short-news classification (TNEWS), and e-commerce topic classification (SHOPPING), roughly as follows:
$$\begin{array}{c|cccc} \hline & \text{total class count} & \text{num training samples} & \text{num val samples} & \text{number of test samples} \\ \hline \text{SENTIMENT} & 2 & 16883 & 2111 & 2111 \\ \text{IFLYTEK} & 119 & 12133 & 2599 & \text{-}\\ \text{TNEWS} & 15 & 53360 & 10000 & \text{-}\\ \text{SHOPPING} & 10 & 47079 & 15694 & \text{-}\\ \hline \end{array}$$
The evaluation metric throughout is accuracy. Results under the full training set are as follows:
$$\begin{array}{c|ccc} \hline & \text{training accuracy} & \text{val accuracy} & \text{test accuracy} \\ \hline \text{SENTIMENT-gradient descent} & 92.26\% & 91.14\% & 91.14\% \\ \text{SENTIMENT-analytic solution} & 91.79\% & 90.81\% & 91.57\% \\ \hline \text{IFLYTEK-gradient descent} & 93.43\% & 51.14\% & \text{-} \\ \text{IFLYTEK-analytic solution} & 71.70\% & 56.44\% & \text{-} \\ \hline \text{TNEWS-gradient descent} & 59.62\% & 53.35\% & \text{-} \\ \text{TNEWS-analytic solution} & 56.12\% & 54.20\% & \text{-} \\ \hline \text{SHOPPING-gradient descent} & 91.63\% & 86.98\% & \text{-} \\ \text{SHOPPING-analytic solution} & 87.89\% & 86.38\% & \text{-} \\ \hline \end{array}$$
Small Sample Set
From the table above, we can see that in terms of training-set performance, the analytical solution is typically not as good as gradient descent. However, on the validation and test sets its performance is close to, or even exceeds, that of gradient descent. Overall, the gap between training-set and validation-set performance is smaller for the analytical solution, which suggests that the analytical solution may generalize better — it may be more suitable for scenarios with small amounts of data, or where the training and validation distributions don't match well.
To verify this hypothesis, we kept only 1000 training examples from each dataset and reran the experiments:
$$\begin{array}{c|ccc} \hline & \text{training accuracy} & \text{val accuracy} & \text{test accuracy} \\ \hline \text{SENTIMENT-1K-gradient descent} & 99.90\% & 66.08\% & 66.79\% \\ \text{SENTIMENT-1K-analytic solution} & 100.00\% & 72.67\% & 73.24\% \\ \hline \text{IFLYTEK-1K-gradient descent} & 99.47\% & 15.43\% & \text{-} \\ \text{IFLYTEK-1K-analytic solution} & 99.47\% & 15.70\% & \text{-} \\ \hline \text{TNEWS-1K-gradient descent} & 100.00\% & 22.47\% & \text{-} \\ \text{TNEWS-1K-analytic solution} & 100.00\% & 26.74\% & \text{-} \\ \hline \text{SHOPPING-1K-gradient descent} & 100.00\% & 49.82\% & \text{-} \\ \text{SHOPPING-1K-analytic solution} & 100.00\% & 65.49\% & \text{-} \\ \hline \end{array}$$
We can see that with less training data, the training-set gap also shrinks, but the analytical solution now outperforms gradient descent across the board on the validation set, further demonstrating the analytical solution's strong generalization performance in low-resource scenarios.
Overall Discussion
These conclusions aren't hard to understand. Given that both are linear models, the analytical solution adds one extra assumption compared to gradient descent: "the samples of each class follow normal distributions with the same covariance matrix." When there's a lot of data, our estimate of each class's distribution becomes increasingly accurate, and the deviation introduced by this assumption becomes more severe, so it falls behind gradient descent, which adapts freely during training. Conversely, when there's little data, the distribution of each class is itself hard to estimate, and in that case this assumption instead serves as a useful prior, helping the model generalize "from a few points to the whole picture," whereas gradient descent, lacking such a prior, suffers from insufficient generalization.
In other words, with little data, gradient descent essentially just memorizes the few samples it sees, without any ability to "generalize by analogy," whereas the analytical solution effectively "manufactures" more samples through its extra assumption for the model to learn from, so it ends up learning more. With lots of data, gradient descent gets to memorize a great deal and "achieves mastery through repetition," while the analytical solution keeps manufacturing samples according to its own assumption — and at that point, the manufactured samples are actually worse than the real ones, so performance may suffer somewhat.
So, is there room to improve the analytical solution? A fairly direct idea is to try to obtain a more refined estimate of $\ln \frac{p(j|\boldsymbol{x})}{p(i|\boldsymbol{x})}$, and then convert the problem into a linear regression problem to estimate the parameters. As for how to better estimate $\ln \frac{p(j|\boldsymbol{x})}{p(i|\boldsymbol{x})}$, there are quite a few possible approaches — for instance, assuming normal distributions with different covariance matrices, or simply using kernel density estimation — and we'll leave this for readers to explore freely.
Summary
This post introduced an analytical solution for logistic regression and extended it to the single-layer Softmax multi-class classification scenario. Experiments show that, compared with gradient descent, this analytical solution generalizes better, and in particular tends to perform even better in low-resource scenarios.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.