P-tuning: Automatically Constructing Templates to Unleash the Potential of Language Models
In a previous article, Do We Really Need GPT-3? No, BERT's MLM Model Can Also Do Few-Shot Learning, we introduced a method called Pattern-Exploiting Training (PET), which combines manually constructed templates with BERT's MLM model to achieve excellent zero-shot, few-shot, and even semi-supervised learning results. The idea is quite elegant because it unifies the pretraining task with the downstream task. However, constructing such templates by hand can sometimes be quite difficult, and different templates can produce very different results. If we could automatically construct templates from a small number of samples, that would be extremely valuable.
A recent paper on Arxiv, GPT Understands, Too, proposes a method called P-tuning that successfully achieves automatic template construction. Moreover, with the help of P-tuning, GPT's performance on SuperGLUE surpasses that of comparable BERT models for the first time — overturning the long-standing conclusion that "GPT is not good at NLU," which is also where the paper's title comes from. more
What Is a Template
The core idea of PET is to use templates composed of natural language (often called "patterns" or "prompts" in English) to convert a downstream task into a cloze-style task, so that BERT's MLM model can be used for prediction. For example, the figure below shows sentiment classification and topic classification being converted via conditional prefixes:
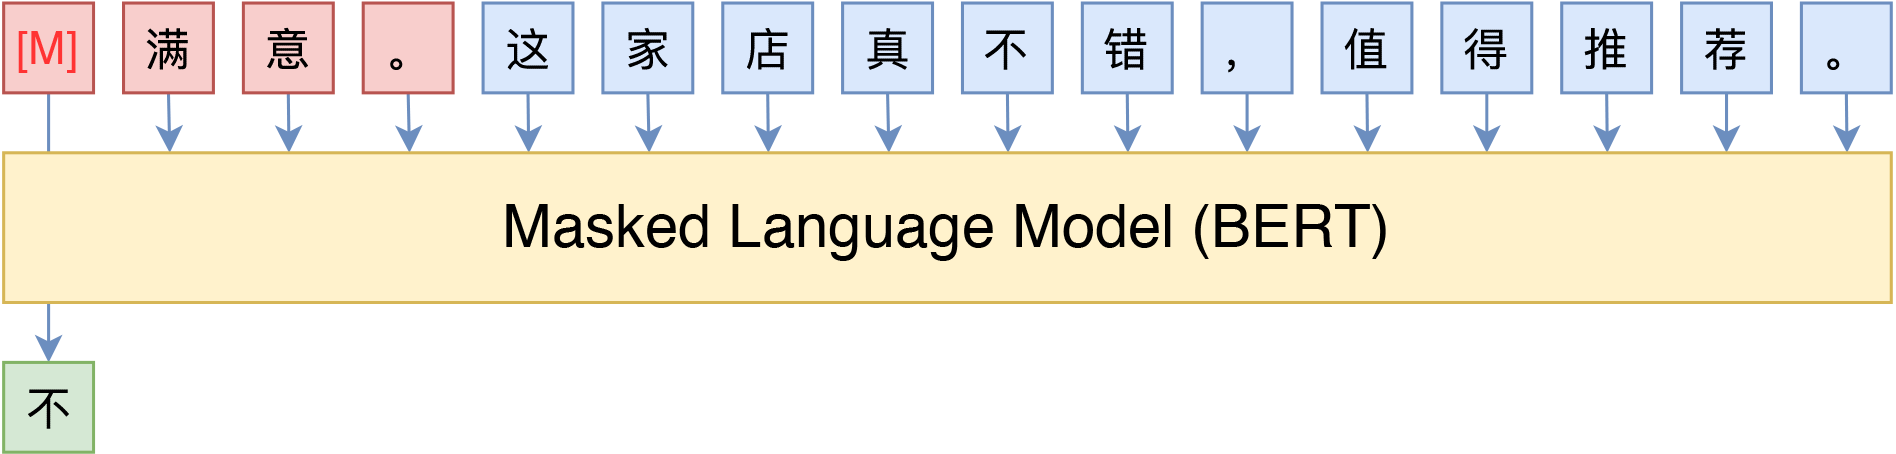 Converting sentiment classification into an MLM task via a specific template
 Converting news classification into an MLM task via a specific template
Of course, this scheme isn't limited to MLM models — it's also quite simple to use with unidirectional language models (LMs) like GPT:
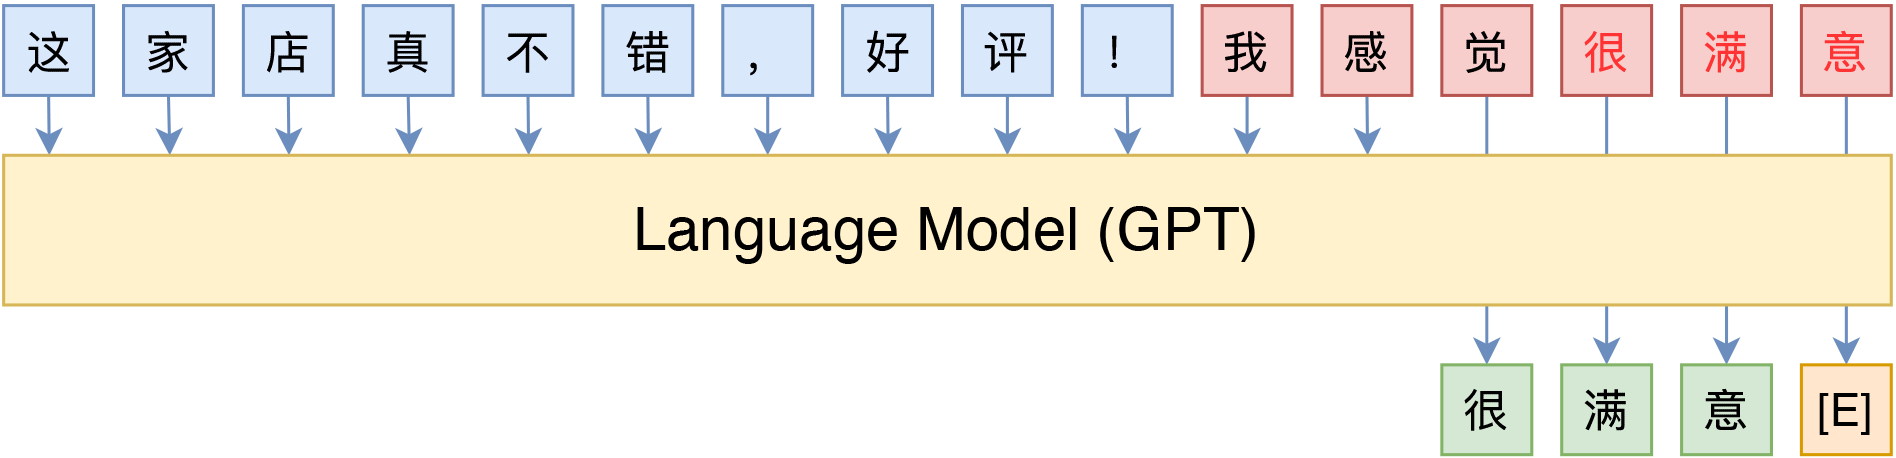 Converting sentiment classification into an LM task via a specific template
 Converting news classification into an LM task via a specific template
Since a language model decodes from left to right, the prediction part can only be placed at the end of the sentence (though a prefix can still be added beforehand, with the prediction part still placed at the very end).
In a sense, these templates act as "probes" into the language model — we can use templates to extract specific knowledge from the language model, achieving decent zero-shot performance, and with a small number of labeled samples, we can further improve results. This was discussed in some detail in Do We Really Need GPT-3? No, BERT's MLM Model Can Also Do Few-Shot Learning.
However, as mentioned earlier, for certain tasks, manually constructing templates is not an easy matter, and it's hard to judge which template is better or worse — the effectiveness of different templates can vary greatly. In such cases, manually labeling some samples might actually be easier than constructing a template. So how to automatically construct templates from existing labeled samples becomes a question worth studying.
P-tuning
P-tuning reconsiders what a template really is, abandoning the conventional requirement that "a template must be composed of natural language," and instead turns template construction into a continuous parameter optimization problem. Simple, yet effective.
Rethinking Templates
First, let's think about "what is a template." Intuitively, a template is a natural-language prefix/suffix that makes the downstream task consistent with the pretraining task, allowing us to make fuller use of the original pretrained model and achieve better zero-shot and few-shot learning performance.
But wait — do we really care whether the template is composed of "natural language"?
Not really. Fundamentally, we don't care what the template looks like. We only need to know which tokens make up the template, where it should be inserted, whether inserting it allows us to accomplish our downstream task, and what the output candidate space is. Whether the template is made of natural language has no effect on us whatsoever. The "natural language" requirement is only there to better achieve "consistency" with pretraining, but it isn't strictly necessary. Based on this, P-tuning considers templates of the following form:
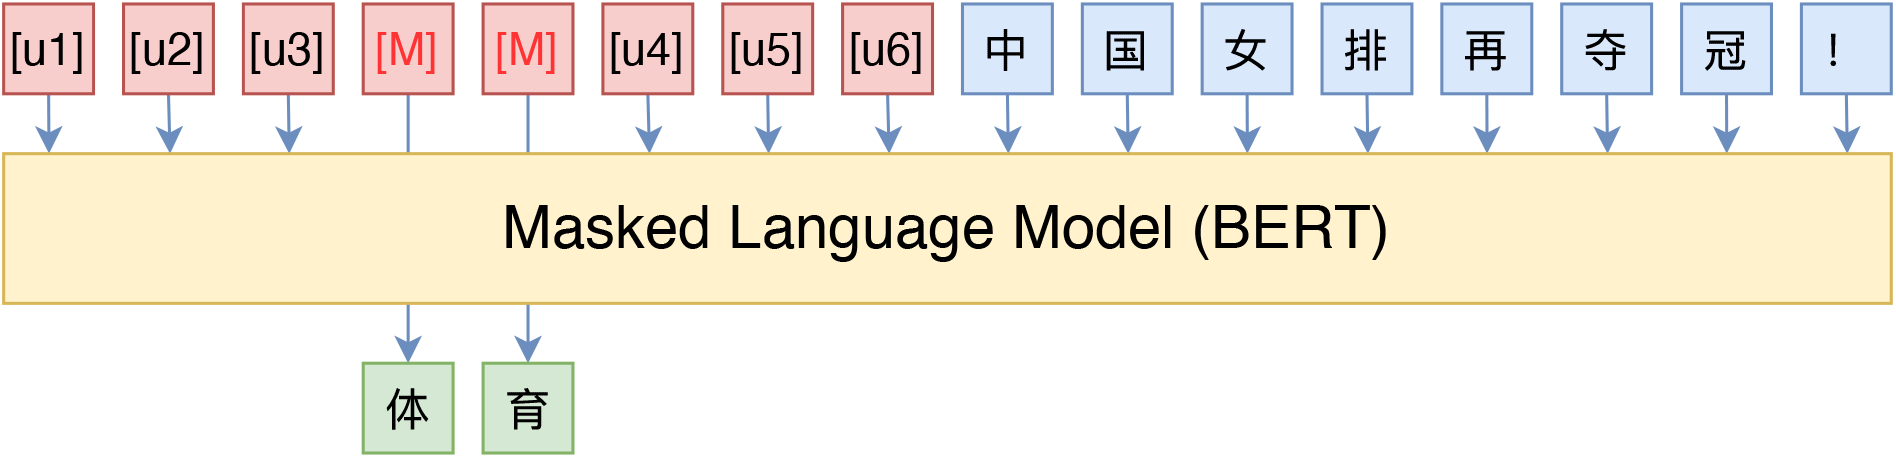 P-tuning directly uses [unused] tokens to construct templates, without caring about the naturalness of the template's language
Here, [u1]~[u6] represent [unused1]~[unused6] in BERT's vocabulary — that is, we use several never-before-seen tokens to build the template. The number of tokens is a hyperparameter, and whether they're placed before or after can also be adjusted. Next, in order to make this "template" actually work, we use labeled data to solve for it.
How to Optimize It
At this point, we need to consider two cases depending on how much labeled data is available.
Case 1: Limited labeled data. In this case, we freeze all the weights of the model and only optimize the embeddings of the [unused1]~[unused6] tokens. In other words, we're essentially learning 6 new embeddings that serve as the template. Since almost all the model's weights are fixed, training is fast, and because there are so few parameters to learn, we can learn the template even with very few labeled samples without overfitting.
Case 2: Abundant labeled data. In this case, if we still follow the approach above, we'll end up underfitting, since having only 6 tokens' worth of optimizable parameters is simply too little. So we can unfreeze all the weights and fine-tune the entire model — this is what the original paper does in its SuperGLUE experiments. Readers might wonder: how is this different from just adding a fully-connected layer and fine-tuning directly? According to the original paper's results, this approach works better, likely because it remains more consistent with the pretraining task.
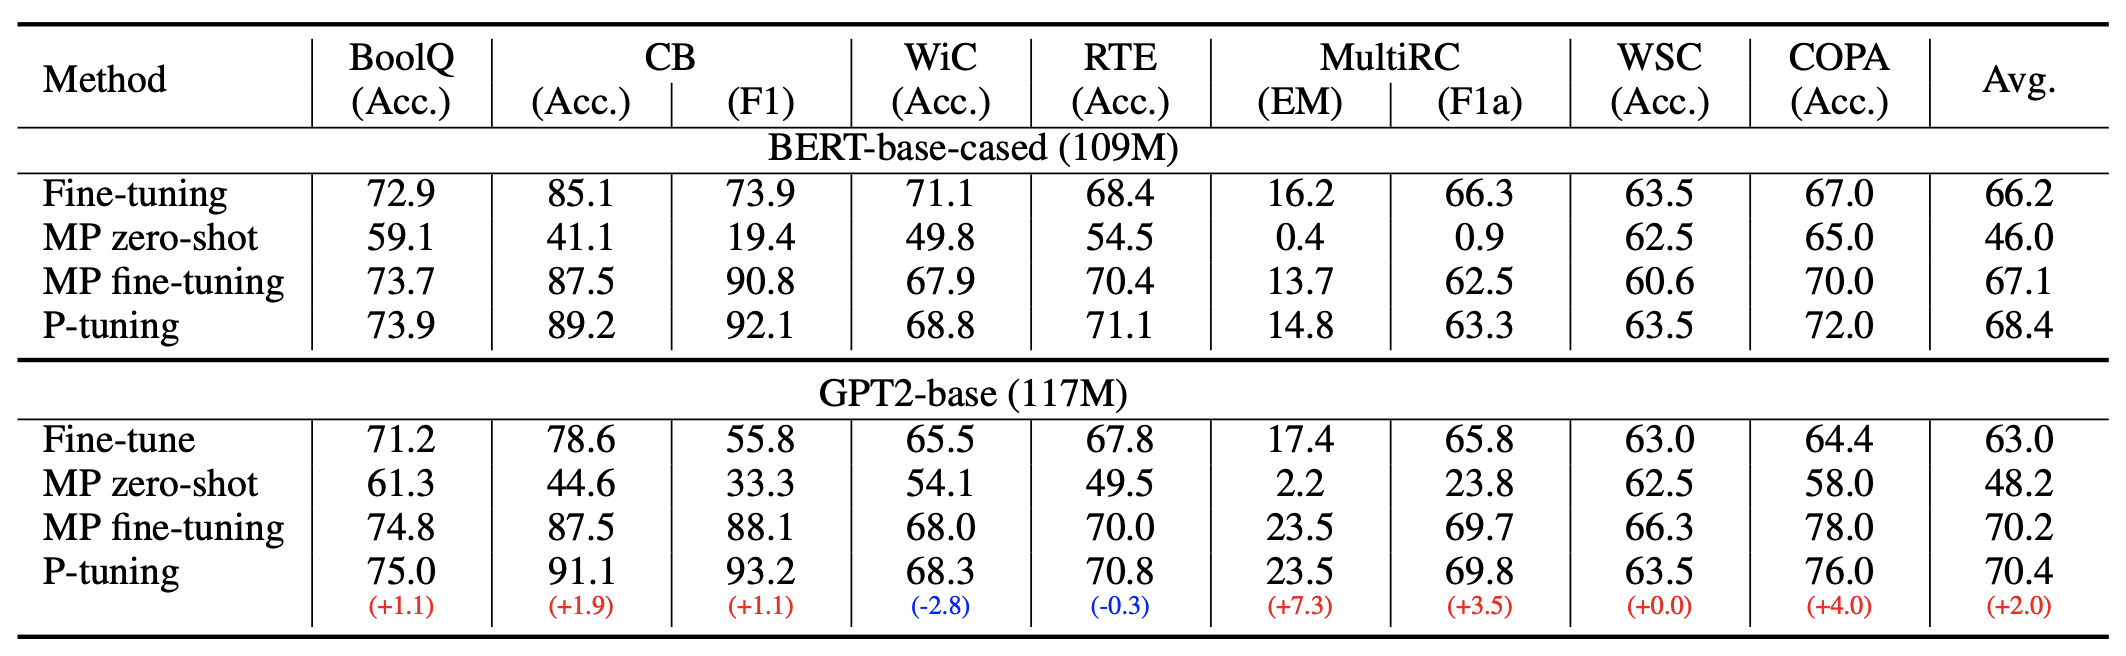 P-tuning's performance on SuperGLUE
Additionally, in the earlier examples, the target tokens like "great" or "sports" were chosen manually — can they also be replaced with [unused] tokens? The answer is yes, but again there are two cases to consider: 1) when labeled data is scarce, manually choosing appropriate target tokens generally works better; 2) when labeled data is abundant, using [unused] tokens as targets works better, since the model then has more room to optimize.
Enhancing Correlation
In the original paper, P-tuning doesn't simply initialize a few new tokens randomly and train them directly. Instead, it computes these embeddings via a small LSTM model, and this LSTM model is itself made learnable. What's the benefit of this extra step? The original paper's reasoning is roughly this: tokens produced by an LSTM exhibit stronger correlations with each other, making them resemble "natural language" more closely in some sense (since natural-language tokens aren't independent of one another), and this also helps avoid local optima. I further confirmed this with the authors on Github (see here): the difference in effect is that going through the LSTM makes the model converge faster and achieve better results.
That said, adding an LSTM always feels a bit awkward, and it's a bit troublesome to implement. According to the authors, the LSTM is meant to help the template's tokens become (to some extent) closer to natural language, but this doesn't necessarily require an LSTM to generate them, and even using an LSTM doesn't guarantee this outcome. In my view, a more natural approach is to also predict other tokens — not just the downstream task's target token (like "great" or "news" in the earlier examples) — during training on the downstream task.
For instance, if it's an MLM model, we can also randomly mask other tokens to predict; if it's an LM model, we can predict the entire sequence rather than just the target word. The rationale is: since both MLM and LM models were pretrained on natural language, we can (confidently) assume that a sequence which can be well reconstructed is necessarily close to natural language. So adding this extra training objective also helps push the model closer to natural language. In my own tests, adding such an auxiliary objective did indeed improve results compared to optimizing only the downstream task's objective.
Experiments and Results
As the saying goes, "talk is cheap, show me the code" — so it's time for the fun part: experiments. Here I'll share P-tuning's experimental results, including my own implementation approach for P-tuning, as well as my experimental results on Chinese-language tasks.
Stopping the Gradient
How can we best implement the P-tuning algorithm described above? If we're unfreezing all the weights for training, that's straightforward and no different from ordinary BERT fine-tuning. The key question is: in the few-shot scenario, how do we implement "optimizing only a few tokens"?
Of course, there are many ways to implement this — for example, building a brand new Embedding layer just for the tokens to be optimized, concatenating it with BERT's original Embedding layer, and then only unfreezing the new Embedding layer's weights during training. But this involves fairly significant changes to the original model. The best approach is to change as little code as possible so that users barely notice anything different. To this end, I devised a scheme that modifies the stop_gradient layer using Embedding with minimal changes, essentially modifying the Embedding layer as follows:
class PtuningEmbedding(Embedding):
    """新定义Embedding层,只优化部分Token
    """
    def call(self, inputs, mode='embedding'):
        embeddings = self.embeddings
        embeddings_sg = K.stop_gradient(embeddings)
        mask = np.zeros((K.int_shape(embeddings)[0], 1))
        mask[1:9] += 1  # 只优化id为1~8的token
        self.embeddings = embeddings * mask + embeddings_sg * (1 - mask)
        return super(PtuningEmbedding, self).call(inputs, mode)
After a variable passes through the stop_gradient operator, its gradient becomes 0 during backpropagation, while the forward pass remains unchanged. So in the code above, the forward-pass result stays the same, but during backpropagation, which tokens get nonzero gradients is controlled by the mask variable, while all other tokens get zero gradient — thereby achieving updates for only a subset of tokens.
The full code is available here:
Github: https://github.com/bojone/P-tuning
By the way, the original paper's code is also open-sourced:
Github: https://github.com/THUDM/P-tuning
Testing and Results
We've already shared the original authors' experimental results on SuperGLUE, which show that with P-tuning: 1) both GPT's and BERT's performance improve compared to direct fine-tuning; 2) GPT's performance can even surpass BERT's. This shows that GPT possesses not only NLG capability but also NLU capability — P-tuning has fully "squeezed out" GPT's potential, so to speak. Of course, BERT combined with P-tuning also shows improvement, indicating that P-tuning's ability to unleash a language model's potential is fairly general-purpose.
The original paper's experiments are quite rich, and I'd recommend readers study it carefully — I'm sure there's a lot to gain from it. One thing worth pointing out specifically is the last column of Table 2 in the original paper: when the pretrained model is large enough that our hardware may not be able to fine-tune the entire model, P-tuning gives us the option of optimizing only a handful of token parameters, since this greatly reduces the memory and compute required for optimization. So P-tuning effectively gives us a way to make use of large pretrained models under limited compute.
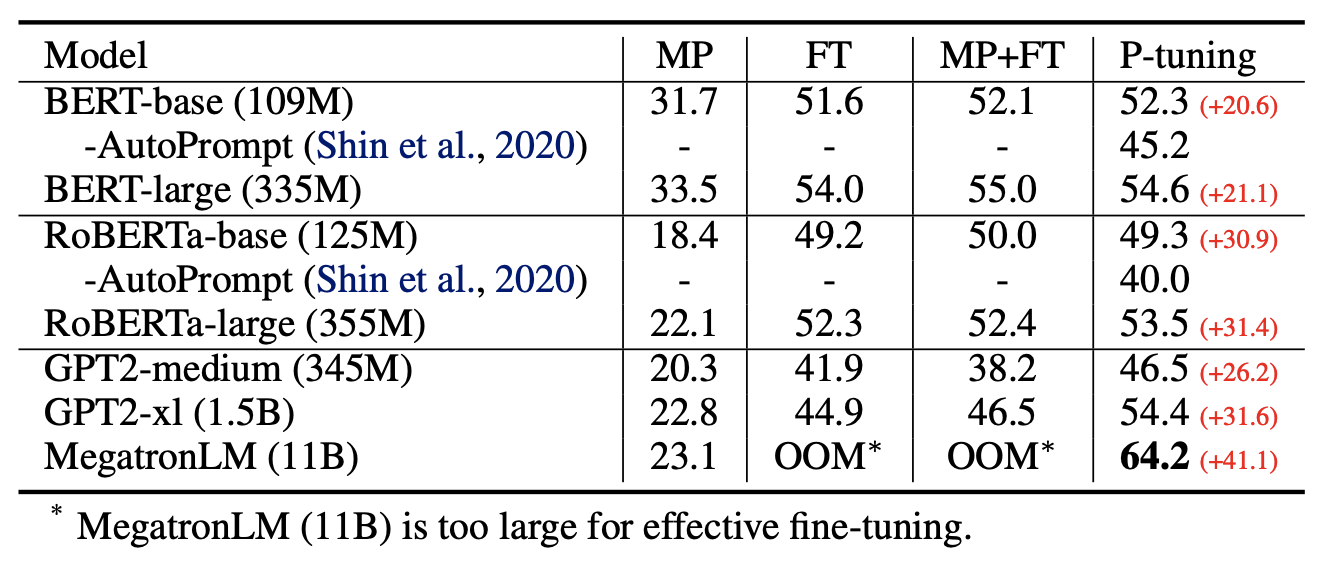 P-tuning's performance across language models of various sizes
Of course, my longstanding view is that "an algorithm that hasn't been tested on Chinese has no soul," so I also ran some simple tests on Chinese tasks. The test task is the same as in Do We Really Need GPT-3? No, BERT's MLM Model Can Also Do Few-Shot Learning — few-shot sentiment classification — and the models tested include BERT and GPT. Their respective candidate templates are shown below:
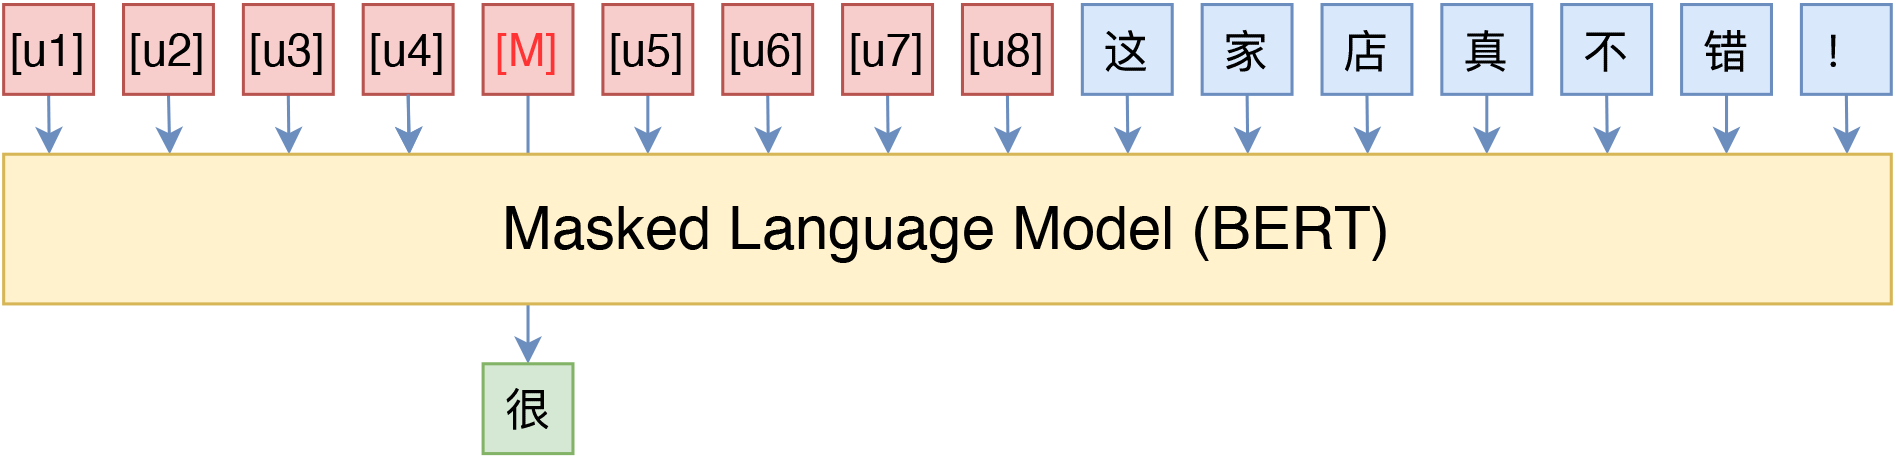 The "BERT+P-tuning" template I used for Chinese sentiment classification
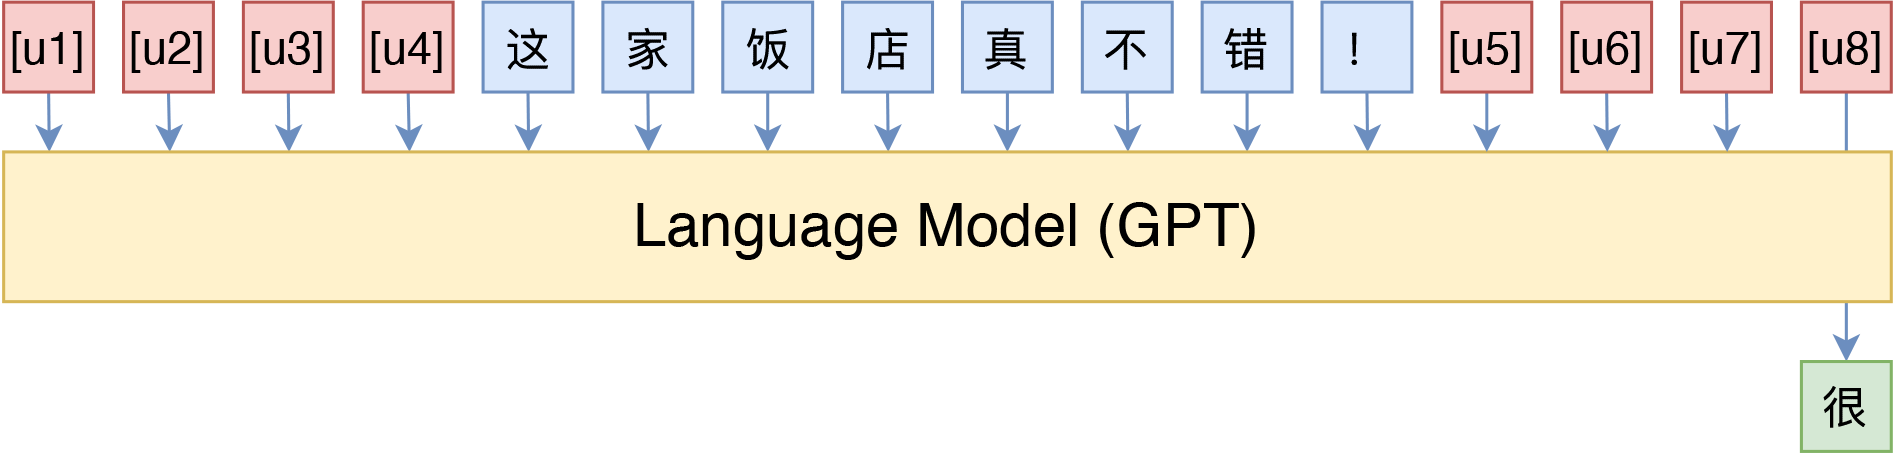 The "GPT+P-tuning" template I used for Chinese sentiment classification
Note that for the LM model, introducing a prefix is very important — using only a suffix results in a noticeably worse performance; for the MLM model, prefixes also generally outperform suffixes. The overall results are shown in the table below:
$$\begin{array}{c|cc} \hline & \text{val set} & \text{test set} \\ \hline \text{few-shot direct fine-tuning} & 88.93\% & 89.34\% \\ \text{VAT semi-supervised learning} & 89.83\% & 90.37\% \\ \hline \text{PET zero-shot} & 85.17\% & 84.27\% \\ \text{PET unsupervised} & 88.05\% & 87.53\% \\ \text{PET few-shot} & 89.29\% & 89.18\% \\ \text{PET semi-supervised} & 90.09\% & 89.76\% \\ \hline \text{BERT + P-tuning} & 89.81\% & 89.75\% \\ \text{GPT + P-tuning} & 89.30\% & 88.51\% \\ \hline \end{array}$$
Here, "few-shot" uses only a "small number of labeled samples," "unsupervised" uses a "large amount of unlabeled data," and "semi-supervised" uses "a small number of labeled samples + a large amount of unlabeled data." All "P-tuning" results are few-shot. For PET, the reported results are for the best-performing manually constructed template among several tasks — there were worse manual templates as well. From a few-shot learning perspective, P-tuning indeed achieves the best few-shot learning performance; from a template-construction perspective, P-tuning is indeed much better than manually constructed templates; and from a model perspective, P-tuning can indeed bring GPT's classification performance up to a level comparable with BERT's, revealing the fact that GPT also possesses strong NLU capability.
Further Understanding
This section will present some further thoughts of mine on P-tuning, in an effort to understand it from multiple angles.
Discrete vs. Continuous
Before P-tuning, there was already some work on automatically constructing templates, such as How Can We Know What Language Models Know? and AutoPrompt: Eliciting Knowledge from Language Models with Automatically Generated Prompts. But these all searched for natural-language templates within a discrete search space, which limited their effectiveness — they didn't achieve particularly outstanding results.
By contrast, P-tuning abandons the requirement that "a template must be composed of natural language," turning the problem into a continuous parameter optimization problem that can simply be solved with gradient descent — and the results are even better. At the same time, this change means P-tuning highlights the true essence of a template — namely, that what matters about a template is how it's used, not what it's made of — giving a sense of cutting through the clutter to reveal the essential truth. It's genuinely admirable work.
(Note: thanks to a reminder from reader @brotherb, a paper from earlier this year, Prefix-Tuning: Optimizing Continuous Prompts for Generation, proposed the Prefix-Tuning method, which is in fact quite close to P-tuning. Both design non-natural-language templates, except that Prefix-Tuning is mainly concerned with NLG applications while P-tuning is more focused on NLU applications.)
Adapter
We can also understand P-tuning from the perspective of Adapters. Not long after BERT was released, Google proposed a fine-tuning method called Adapter in the paper Parameter-Efficient Transfer Learning for NLP. Rather than fine-tuning the entire model directly, it freezes BERT's original weights and adds some residual modules on top of BERT, optimizing only these residual modules. Since the residual modules have far fewer parameters, fine-tuning is cheaper. The idea behind Adapters actually originates from computer vision, in Learning multiple visual domains with residual adapters, though it seems to have become rather rare in recent years — perhaps because although it speeds up training, it slows down inference, and accuracy often suffers as well.
In P-tuning, if we don't think of the newly inserted tokens as a "template" but instead treat them as part of the model, then P-tuning is actually a method quite similar to Adapter: both freeze the original model's weights and insert some new optimizable parameters, optimizing only these new parameters — except that in P-tuning's case, the new parameters are inserted into the Embedding layer. So from this perspective, P-tuning and Adapter share many similarities despite their different approaches.
Why Does It Work
There's another question worth pondering: why is P-tuning better? For instance, with the full dataset, everyone unfreezes all the weights, and yet P-tuning still outperforms direct fine-tuning — why is that?
In fact, anyone asking this question has probably grown "accustomed to" the standard approach of fine-tuning BERT with a fully-connected layer added on top. Clearly, whether it's PET or P-tuning, both are actually closer to the pretraining task, whereas adding a fully-connected layer isn't as close to the pretraining task. So in a sense, it's more "obvious" that P-tuning should work — it's actually the effectiveness of fine-tuning with an added fully-connected layer that deserves more scrutiny.
Last year, a paper titled A Mathematical Exploration of Why Language Models Help Solve Downstream Tasks attempted to answer this question. The general line of argument goes roughly as follows:
1. The pretrained model is essentially some kind of language modeling task;
2. The downstream task can be expressed as a special case of this language modeling task;
3. When the output space is finite, this in turn approximates adding a fully-connected layer;
4. Therefore, fine-tuning by adding a fully-connected layer is effective.
As you can see, the paper's key assumption is point 2 — it essentially just assumes upfront that the downstream task can be expressed in a form similar to PET, and then proceeds to prove things from there. This further shows that PET and P-tuning are actually the more natural way to make use of pretrained models, and that directly fine-tuning with an added fully-connected layer is really just a corollary of them. In other words, PET and P-tuning represent a return to basics, to the essence of the matter — and that's precisely why they're more effective.
Brief Summary
This article introduced P-tuning, a method for automatically constructing templates. Through templates, we can extract knowledge from language models to accomplish zero-shot, few-shot, and other learning tasks, often achieving even better results. With the help of P-tuning, GPT too can achieve excellent NLU performance, even surpassing BERT on SuperGLUE. Beyond that, P-tuning also offers an effective way to make use of large pretrained models under limited computational resources.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.