Must It Be GPT3? No — BERT's MLM Can Do Few-Shot Learning Too
Everyone knows GPT3 is all the rage right now, with mentions of GPT3 popping up everywhere. But do readers remember the actual title of the GPT3 paper? In fact, the GPT3 paper is called Language Models are Few-Shot Learners, and notice the title doesn't even contain the letters G, P, or T anymore — it's just that the model continues the lineage of the original GPT, so people still call it GPT3. As the name suggests, GPT3's main selling point is few-shot learning. Another notable feature of GPT3 is its sheer size: the largest version has as many as 175 billion parameters, over a thousand times more than BERT Base.
Precisely because of this, a paper that appeared on Arxiv a few days ago, It's Not Just Size That Matters: Small Language Models Are Also Few-Shot Learners, caught my attention. Loosely translated, the title says "Who said it has to be big? Small models can do few-shot learning too." The title is clearly aimed squarely at GPT3, so I was intrigued and clicked through to see who had the nerve to challenge GPT3, and what kind of small model could possibly rival it. After reading it, it turns out the authors show that with the right construction, BERT's MLM head can also do few-shot learning — and after finishing the paper I had that "oh, so you can do it this way" moment of revelation. Let me share it with you here. more
The Rising Star: MLM
MLM, short for "Masked Language Model," can be translated as "掩码语言模型" — essentially it's a cloze task: certain words/characters in the text are randomly masked, and the model is asked to predict what was masked. Here's an illustration:
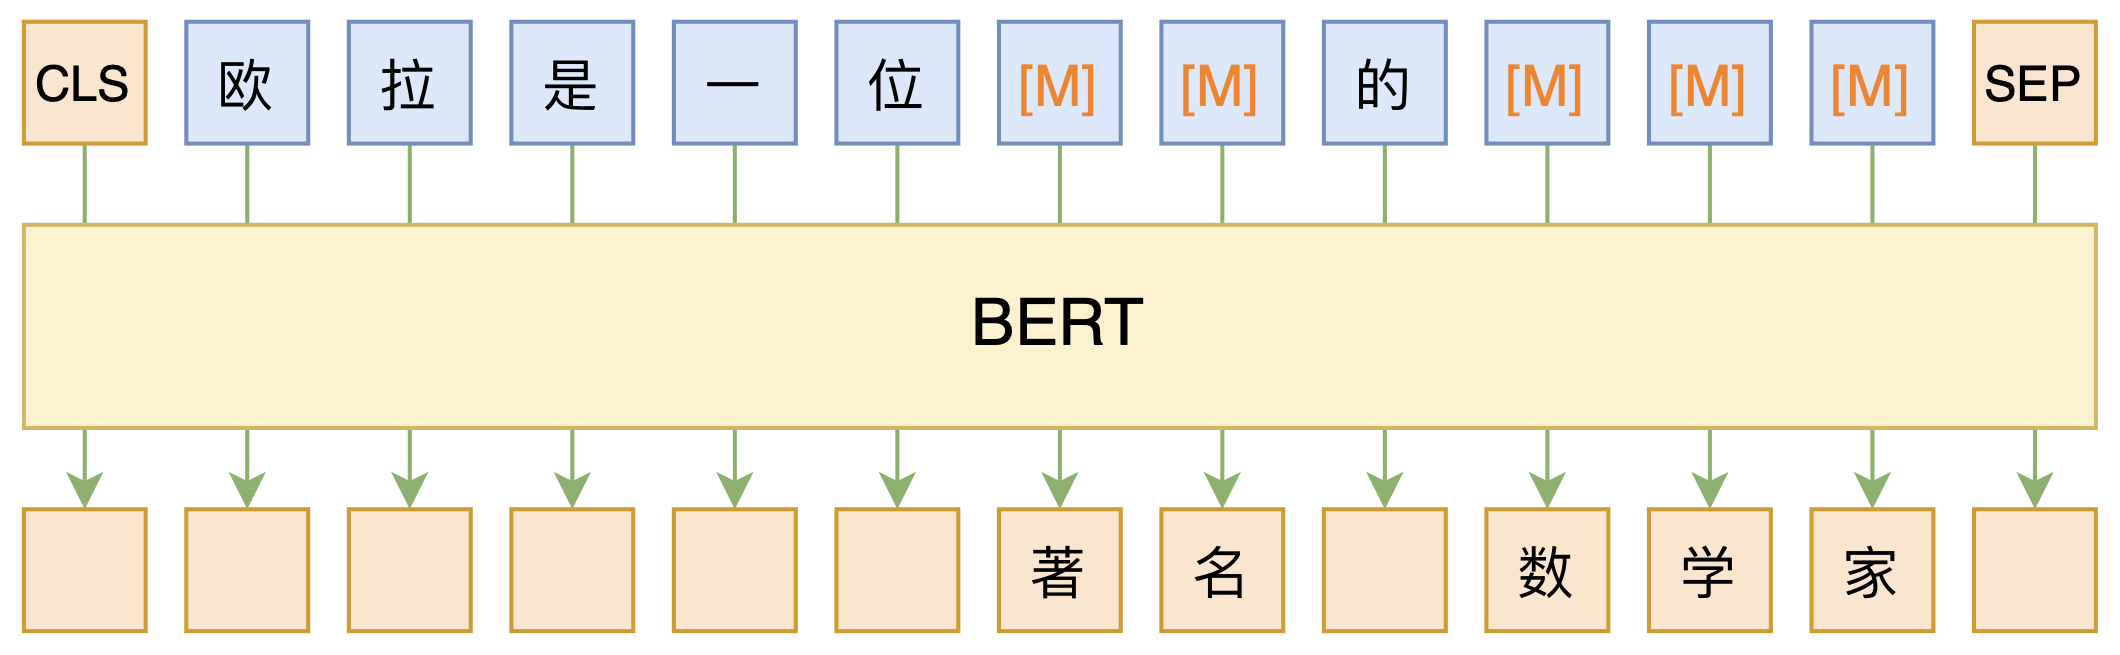 A simple illustration of BERT's MLM
The masked portion can be a directly and randomly chosen token, or a contiguous span of tokens chosen so as to form a whole word — the latter is called WWM (Whole Word Masking).
Initially, MLM was regarded merely as one of BERT's pretraining tasks — something you could throw away once training was done. As a result, some open-source models simply didn't bother keeping the MLM weights, such as the brightmart version and the CLUE version of RoBERTa, while HIT's open-sourced RoBERTa-wwm-ext-large, for whatever reason, randomly initialized the MLM head's weights. So if you want to reproduce the results discussed later in this post, these versions won't work.
However, as research has deepened, people have found that it's not just BERT's encoder that's useful — the MLM head used for pretraining is valuable in its own right too. For example, the paper BERT has a Mouth, and It Must Speak: BERT as a Markov Random Field Language Model points out that MLM can be used as a general-purpose generative model, and the paper Spelling Error Correction with Soft-Masked BERT applies MLM to text error correction. In my earlier experiments in From Language Models to Seq2Seq: Transformer as Theater, All Thanks to Masking, I also showed that the MLM pretrained weights can be repurposed as UniLM for Seq2Seq tasks. There's also Unsupervised Word Segmentation and Parsing! Turns Out BERT Can Be Used This Way Too, which applies the idea of MLM to unsupervised segmentation and syntactic parsing. MLM has really been shining in all sorts of applications.
Turning Tasks into Cloze Questions
In this post, we look at another remarkable application of MLM: using it for few-shot or semi-supervised learning, and in some settings, even zero-shot learning.
How do we combine the task we want to solve with MLM? It's simple: give the task a textual description, then convert it into a cloze question. For example, given the sentence "This trip to Beijing left me feeling pretty good," we add a description and construct the following cloze:
I feel ______ satisfied. This trip to Beijing left me feeling pretty good.
Furthermore, if we restrict the blank to being filled with only "very" or "not," the problem becomes clear: we're asking the model, based on contextual consistency, to judge whether the sentiment is satisfied or not. If the probability of "very" exceeds that of "not," the sentiment is positive; otherwise it's negative. In this way we've converted a sentiment classification problem into a cloze problem, which can be solved with predictions from an MLM model — and since training an MLM doesn't require supervised data, in principle this could enable zero-shot learning.
Multi-class classification problems can be converted similarly. For news topic classification, given the input sentence "Eight months on, we can finally watch our women's volleyball team on the court again," we can construct:
The following is a ______ news report. Eight months on, we can finally watch our women's volleyball team on the court again.
This turns news topic classification into a cloze problem as well, where a good MLM model should be able to predict the word "sports."
Some simple inference tasks can also be reframed this way. A common one is: given two sentences, decide whether they are consistent with each other. For instance, "I went to Beijing" and "I went to Shanghai" contradict each other, while "I went to Beijing" and "I'm at Tiananmen Square" are consistent. The usual approach is to concatenate the two sentences and feed them into the model as a binary classification task. How would we turn this into a cloze problem instead? A fairly natural construction is:
I went to Beijing? ______, I went to Shanghai. I went to Beijing? ______, I'm at Tiananmen Square.
where the candidate words for the blanks are $\{\text{yes}, \text{not}\}$.
Pattern-Exploiting
By this point, readers have probably spotted the underlying pattern: we add a prefix or suffix description to the input text and mask certain tokens, thereby converting it into a cloze problem. In the original paper this transformation is called a Pattern, and it should be constructed so that it reads as naturally as possible together with the original sentence — not too forced — since the pretrained MLM model was trained on natural language. Obviously the same problem can be phrased with many different Patterns. In the sentiment classification example, the description could go at the end instead: "This trip to Beijing left me feeling pretty good. I feel ____ satisfied." Or we could add a few more words: "How do you feel? I feel ____ satisfied. This trip to Beijing left me feeling pretty good."
Next, we need to build a candidate space for the predicted token, and establish a mapping from tokens to actual classes — in the original paper this is called the Verbalizer. In the sentiment classification example, our candidate space is $\{\text{very}, \text{not}\}$, and the mapping is $\text{very}\to\text{positive},\text{not}\to\text{negative}$. The candidate space and actual classes needn't be in a strict one-to-one correspondence — for instance we could also add words like "quite," "very," "hard," and treat $\{\text{very},\text{quite},\text{too}\}\to\text{positive}$ as well as $\{\text{not},\text{hard}\}\to\text{negative}$, and so on. It's not hard to see that quite a few NLP tasks can be transformed this way, but obviously this kind of conversion generally only works for tasks with a bounded candidate space — put plainly, it's only usable for multiple-choice-style problems, the most common example being text classification.
As mentioned, the same task can have several different Patterns. The original paper handles this as follows:
1. For each Pattern, fine-tune a separate MLM model using the training set;
2. Then ensemble the models corresponding to the different Patterns to get a combined model;
3. Use the combined model to predict pseudo-labels for unlabeled data;
4. Use the pseudo-labeled data to fine-tune a regular (non-MLM) model.
I won't go into the details of the ensembling method here — readers can check the paper themselves, since it's not the main point. This training scheme is called Pattern-Exploiting Training (PET). It first appeared in the paper Exploiting Cloze Questions for Few Shot Text Classification and Natural Language Inference, and the paper we're discussing here further confirms and refines the value and results of Pattern-Exploiting Training, and incorporates multi-task learning, such that its few-shot learning performance on the SuperGLUE leaderboard surpasses GPT3. The two papers share the same authors and form a coherent line of work.
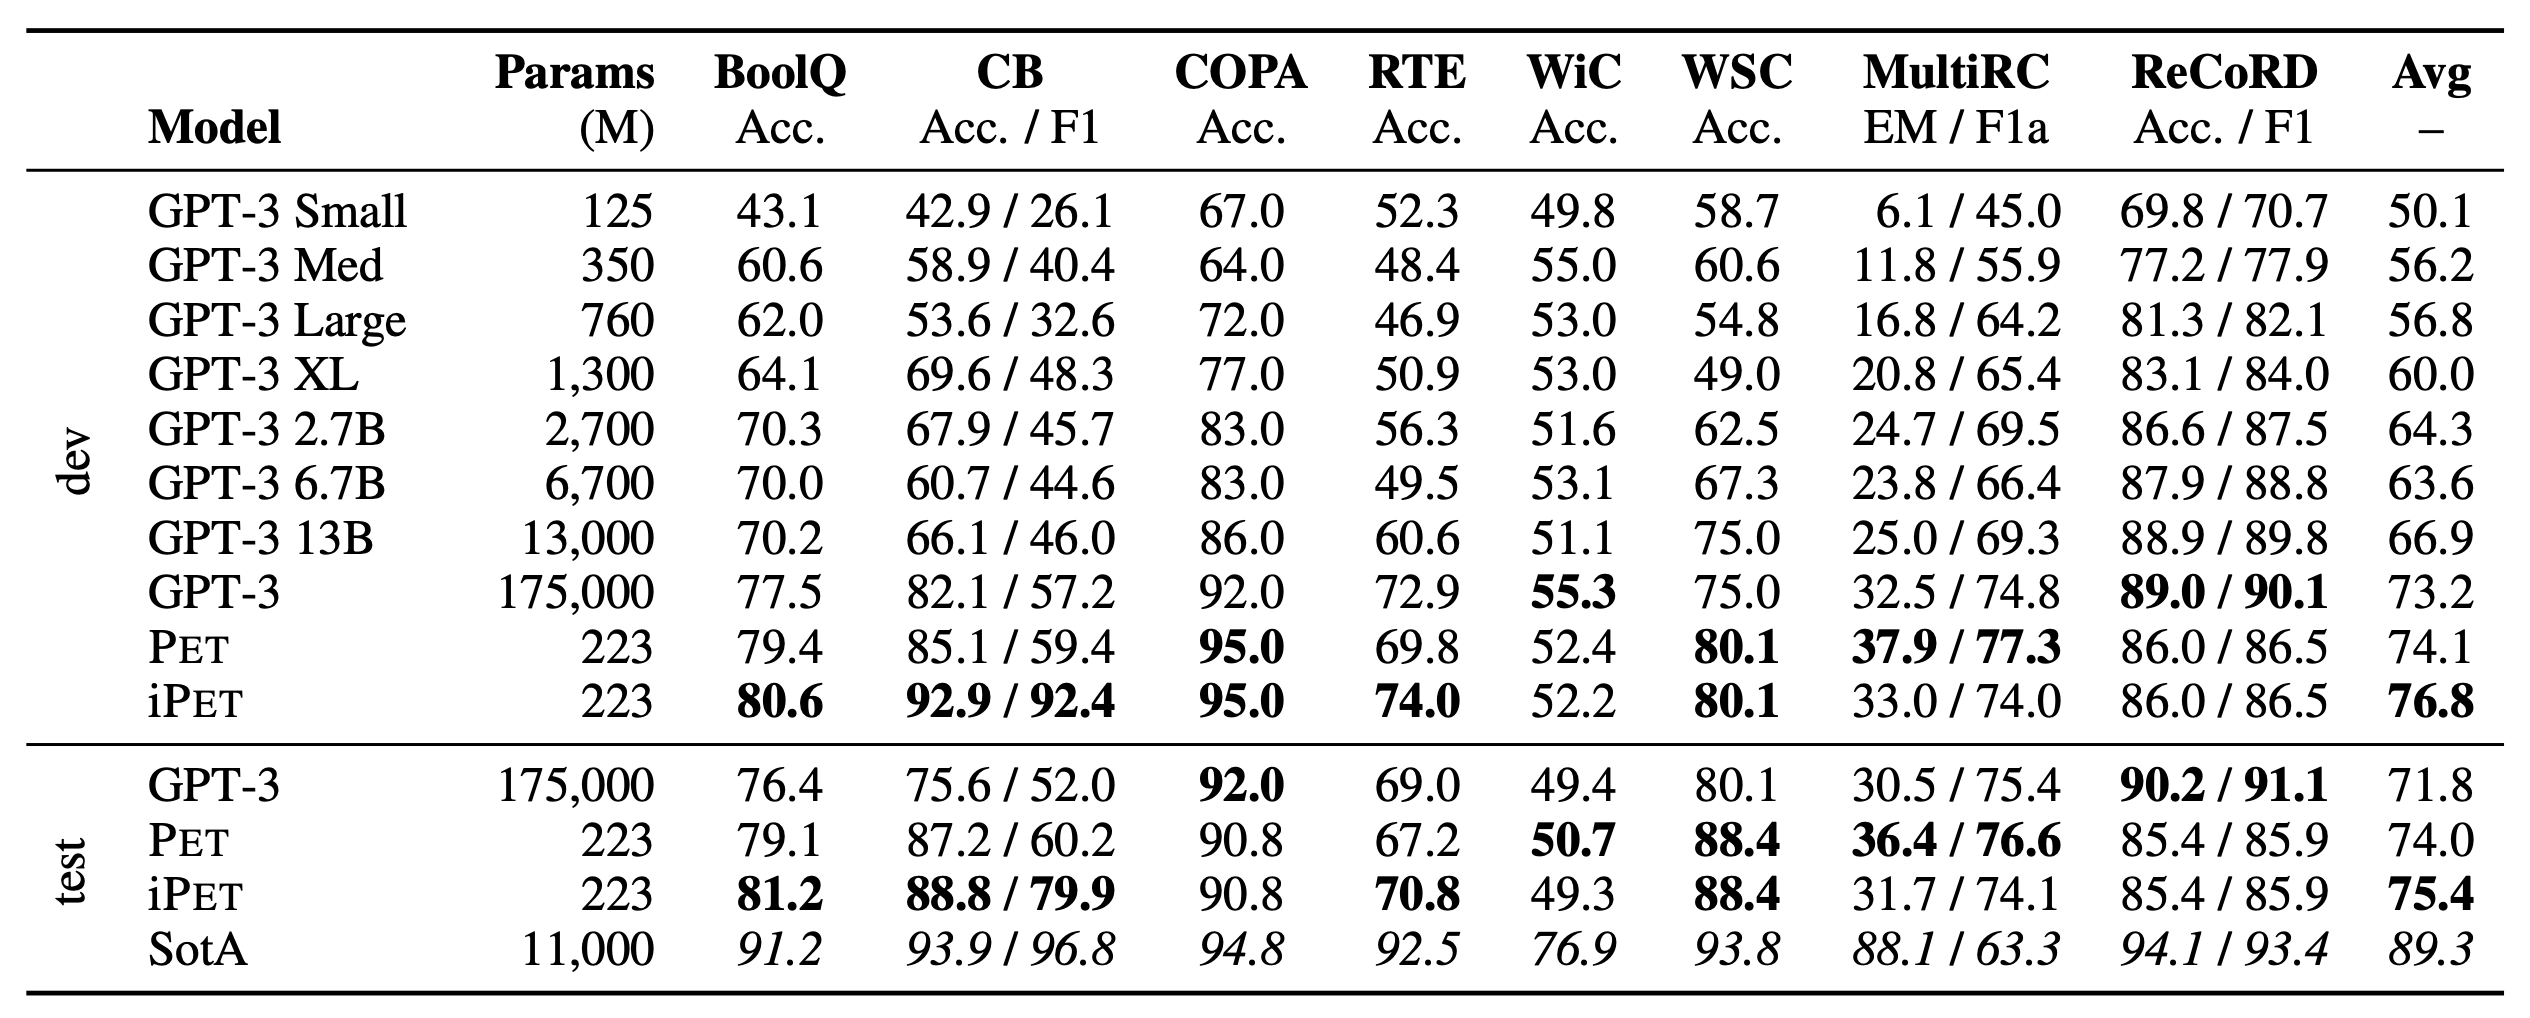 PET's few-shot learning results on SuperGLUE
One thing worth grumbling about, though: in the figure above, PET's "223M parameters" refers to using ALBERT-xxlarge-v2 as the underlying model. Calling ALBERT a "small model" is really a bit of a sleight of hand, because its forward-pass speed hasn't improved at all. ALBERT-xxlarge has 12 layers with shared parameters across layers, but in terms of forward computation it's effectively equivalent to a GPT model with about 2700M (12x) parameters.
Testing It Out on Chinese Data
To really confirm the value of a method or model, reading the experimental tables in a paper isn't enough — nobody can be sure the results are reproducible, and even if they are reproducible in English, that doesn't mean they carry over to Chinese. So the most practical thing is to roll up your sleeves and run the experiments yourself. Below is my experimental code, for readers' reference:
GitHub: https://github.com/bojone/Pattern-Exploiting-Training
We'll examine the feasibility of PET from the following angles:
1. How well does an off-the-shelf MLM model perform directly? (Zero-shot learning 1)
2. How well does an off-the-shelf MLM model perform after fine-tuning it with a "large amount of unlabeled data"? (Zero-shot learning 2)
3. How well does an off-the-shelf MLM model perform after fine-tuning it with "a small amount of labeled data"? (Few-shot learning)
4. How well does an off-the-shelf MLM model perform after fine-tuning it with "a small amount of labeled data + a large amount of unlabeled data"? (Semi-supervised learning)
Below I mainly present results for a binary sentiment classification task. There's also a multi-class news-topic classification experiment whose code is likewise on GitHub, with similar results, so I won't repeat the discussion here.
Zero-shot learning 1
Here we mainly explore what accuracy we get by directly using an off-the-shelf MLM model to make predictions, after appending the corresponding Pattern to the input text. Since the whole process involves no supervised training on labeled data, this counts as a form of "zero-shot learning." We compare performance across different Patterns and different MLM models:
Here are the Patterns used in the experiment, where the candidate words for the blank are always "very" and "not":
P1: I feel ____ satisfied. This trip to Beijing left me feeling pretty good.
P2: This trip to Beijing left me feeling pretty good. I feel ____ satisfied.
P3: ____ good. This trip to Beijing left me feeling pretty good.
P4: ____ ideal. This trip to Beijing left me feeling pretty good.
P5: How do you feel? ____ satisfied. This trip to Beijing left me feeling pretty good.
As for the MLM models, we used the following:
M1: Google's open-sourced Chinese BERT Base (link);
M2: HIT's open-sourced RoBERTa-wwm-ext Base (link);
M3: Tencent UER's open-sourced BERT Base (link);
M4: Tencent UER's open-sourced BERT Large (link).
The experimental results are shown in the table below (validation/test):
$$\begin{array}{c} \text{zero-shot performance of different models and patterns} \\ {\begin{array}{c|ccccc} \hline & \text{P1} & \text{P2} & \text{P3} & \text{P4} & \text{P5} \\ \hline \text{M1} & 66.94\,/\,67.60 & 57.56\,/\,56.13 & 58.83\,/\,59.69 & 83.70\,/\,83.33 & 75.98\,/\,76.13\\ \text{M2} & 85.17\,/\,84.27 & 70.63\,/\,68.69 & 58.55\,/\,59.12 & 81.81\,/\,82.28 & 80.25\,/\,81.62\\ \text{M3} & 66.75\,/\,68.64 & 50.45\,/\,50.97 & 68.97\,/\,70.11 & 81.95\,/\,81.48 & 61.49\,/\,62.58\\ \text{M4} & 83.56\,/\,85.08 & 72.52\,/\,72.10 & 76.46\,/\,77.03 & 88.25\,/\,87.45 & 82.43\,/\,83.56\\ \hline \end{array}} \end{array}$$
The best result actually reaches 88%! In other words, simply loading an off-the-shelf MLM and pairing it with an appropriate Pattern, without any labeled data at all, can already correctly identify the sentiment of most samples. This really makes us take another look at the potential of MLM models.
We can observe some variation across different Patterns and different pretrained models. Overall, the Large versions clearly outperform the Base versions, which suggests — much like the progression from GPT to GPT2 to GPT3 — that making the model bigger still helps. This might also suggest that MLM models in general haven't been fully trained yet — perhaps BERT's training scheme of masking part of the input is simply too inefficient, and the improved MLM variant discussed in Modifying the Transformer Architecture to Design a Faster, Better MLM Model might work better.
Zero-shot learning 2
Having seen the above results, readers might wonder: if I continue pretraining the MLM model on in-domain data, would that improve results? The answer is: yes! Below are our experimental results. Given limited compute, we only compared against RoBERTa-wwm-ext (M2 above; the model after continued pretraining we call "M2 + unsupervised"):
$$\begin{array}{c} \text{zero-shot performance after continued MLM pretraining} \\ {\begin{array}{c|ccccc} \hline & \text{P1} & \text{P2} & \text{P3} & \text{P4} & \text{P5} \\ \hline \text{M2} & 85.17\,/\,84.27 & 70.63\,/\,68.69 & 58.55\,/\,59.12 & 81.81\,/\,82.28 & 80.25\,/\,81.62\\ \text{M2}^{+\text{unsupervised}} & 88.05\,/\,87.53 & 71.01\,/\,68.78 & 81.05\,/\,81.24 & 86.40\,/\,85.65 & 87.26\,/\,87.40\\ \hline \end{array}} \end{array}$$
Note that here we're only continuing MLM training on in-domain data — this process is unsupervised and requires no labeling signal, so it still counts as "zero-shot learning." From the results so far, we can also see that adding a "prefix" to the input text has a slight edge over using a "suffix."
Few-shot learning
We just discussed the improvement from continuing MLM pretraining on unlabeled data. Going back to PET's original target setting, what happens if we directly fine-tune the MLM on a small amount of labeled data combined with a specific Pattern? This is the true "few-shot learning" setup. Here we keep about 200 labeled samples. When constructing the samples, we first append the Pattern to each sentence, and besides the Mask positions that come with the Pattern itself, we also randomly mask some additional tokens to add regularization to the model. The final results are as follows:
$$\begin{array}{c} \text{few-shot learning performance} \\ {\begin{array}{c|ccccc} \hline & \text{P1} & \text{P2} & \text{P3} & \text{P4} & \text{P5} \\ \hline \text{M2} & 85.17\,/\,84.27 & 70.63\,/\,68.69 & 58.55\,/\,59.12 & 81.81\,/\,82.28 & 80.25\,/\,81.62\\ \text{M2}^{+\text{few-shot}} & 89.29\,/\,89.18 & 84.71\,/\,82.76 & 88.91\,/\,89.05 & 89.31\,/\,89.13 & 89.07\,/\,88.75\\ \hline \end{array}} \end{array}$$
The conclusion is that apart from the "suffix-style" P2, all the other results are roughly the same, which further supports the idea that "prefix-style" Patterns are more competitive than "suffix-style" ones. As for absolute performance, directly fine-tuning a regular BERT model on the same data using the conventional method gives roughly 88.93, so the "MLM + Pattern"-based few-shot learning approach may bring a slight performance improvement.
Semi-supervised learning
Having covered unsupervised zero-shot learning and supervised few-shot learning, naturally it's time for "semi-supervised learning," which combines both labeled and unlabeled data. Same task as before, with a labeled-to-unlabeled data ratio of roughly 1:99. Labeled data comes with a Pattern attached; unlabeled data does not. Both types have some tokens masked for MLM pretraining. The final measured results are as follows:
$$\begin{array}{c} \text{semi-supervised learning effect} \\ {\begin{array}{c|ccccc} \hline & \text{P1} & \text{P2} & \text{P3} & \text{P4} & \text{P5} \\ \hline \text{M2} & 85.17\,/\,84.27 & 70.63\,/\,68.69 & 58.55\,/\,59.12 & 81.81\,/\,82.28 & 80.25\,/\,81.62\\ \text{M2}^{+\text{semi-supervised}} & 90.09\,/\,89.76 & 79.58\,/\,79.35 & 90.19\,/\,88.96 & 90.05\,/\,89.54 & 89.88\,/\,89.23\\ \hline \end{array}} \end{array}$$
Once again, "suffix" is clearly worse than "prefix," and results within "prefix" variants are roughly comparable. In terms of absolute performance, this confirms that the extra unlabeled data does help. Intuitively, "prefix" outperforming "suffix" is probably because the Mask position in "prefix" Patterns is relatively fixed, allowing the weak supervision signal to accumulate and reinforce over training. But this doesn't fully explain why "prefix" also wins in the zero-shot setting — it's probably related to how difficult the model finds different parts of the sentence to learn. Perhaps the patterns near the beginning of a sentence are more regular and therefore relatively easier to learn, so the model ends up learning that part more thoroughly? All of this remains speculation for now.
Summary and Conclusions
The results above are summarized in the table below:
$$\begin{array}{c} \text{result comparison summary} \\ {\begin{array}{c|ccccc} \hline & \text{P1} & \text{P2} & \text{P3} & \text{P4} & \text{P5} \\ \hline \text{M2} & 85.17\,/\,84.27 & 70.63\,/\,68.69 & 58.55\,/\,59.12 & 81.81\,/\,82.28 & 80.25\,/\,81.62\\ \text{M2}^{+\text{unsupervised}} & 88.05\,/\,87.53 & 71.01\,/\,68.78 & 81.05\,/\,81.24 & 86.40\,/\,85.65 & 87.26\,/\,87.40\\ \text{M2}^{+\text{few-shot}} & 89.29\,/\,89.18 & 84.71\,/\,82.76 & 88.91\,/\,89.05 & 89.31\,/\,89.13 & 89.07\,/\,88.75\\ \text{M2}^{+\text{semi-supervised}} & 90.09\,/\,89.76 & 79.58\,/\,79.35 & 90.19\,/\,88.96 & 90.05\,/\,89.54 & 89.88\,/\,89.23\\ \hline \end{array}} \end{array}$$
Readers may also want to compare this with our earlier results on semi-supervised learning using Virtual Adversarial Training (VAT) in Random Musings on Generalization: From Random Noise and Gradient Penalty to Virtual Adversarial Training. We can see that whether it's zero-shot learning, few-shot learning, or semi-supervised learning, the MLM-based approach can rival the semi-supervised learning results based on VAT. Our results on the short-news multi-class experiment were similar as well. This confirms that MLM models can indeed serve as excellent zero-shot/few-shot/semi-supervised learners.
Of course, MLM-based approaches do have drawbacks. For example, the independence assumption underlying MLM limits its ability to predict longer stretches of text (put plainly, the blank can't be too long), and its inability to predict answers of variable length also constrains its use cases (so for now it can only be used for multiple-choice-style tasks, not for generation). We look forward to seeing even stronger MLM models emerge — at that point, it might become possible to compete with GPT3 across the board on every task.
Time for the Usual Summary
This post introduced a novel application of BERT's MLM head: converting a task into a cloze question with an appropriate description, and using the MLM model to do zero-shot, few-shot, and semi-supervised learning. In the original paper's SuperGLUE experiments, this approach matched GPT3's performance, and I've also run some experiments on Chinese tasks that further confirm the effectiveness of the idea. The whole approach is quite elegant, giving that "oh, so you can do it this way" feeling of revelation — I'd recommend that everyone take a look at it.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.