BERT that learns to ask questions: building QA pairs end-to-end from passages
Many readers are probably already familiar with the task of machine reading comprehension: in short, it's about finding the answer to a given question within a given passage, i.e. following the pipeline "passage + question → answer." I've written several articles on reading comprehension before, such as A CNN-based extractive QA model for reading comprehension: DGCNN. Constructing QA pairs, on the other hand, is essentially the inverse task of reading comprehension — the pipeline "passage → answer + question." Academically this is usually just called "Question Generation," and because in most cases the answer can be selected via fairly rule-based random sampling, most papers only concern themselves with the step "passage + answer → question."
This post presents a fully end-to-end practice of "passage → answer + question," including a description of the model as well as an implementation based on bert4keras. Readers are welcome to give it a try.
Let's look at the results first
Input passage: The world's second-highest peak is K2, located within China's borders.
Generated QA: What is the name of the world's second-highest peak? K2
What rank does K2 hold among the world's highest peaks? Second
Input passage: On July 28, Thailand will celebrate the 68th birthday of King Maha Vajiralongkorn, Rama X.
Generated QA: Who is Thailand's Rama X? King Maha Vajiralongkorn
How old is Thailand's Rama X, Maha Vajiralongkorn? 68
What day is King Maha Vajiralongkorn's birthday? July 28
Which country is King Maha Vajiralongkorn from? Thailand
Input passage: The Water-Splashing Festival, also known as Songkran, has a history of 700 years and is the grandest traditional festival of the Dai people (in China) and the De'ang people.
Generated QA: What is another name for the Water-Splashing Festival? Songkran
Which ethnic group in our country celebrates the Water-Splashing Festival as its grandest annual festival? The Dai people
How long has the Water-Splashing Festival existed? 700 years
Design considerations
The goal of this post is to achieve "passage → answer + question" in a fully end-to-end fashion, where even the selection of the answer is done automatically by the model, with no manual rules required. Actually it's quite simple: we build a Seq2Seq model in the "BERT + UniLM" fashion (UniLM's attention mask combined with BERT's pretrained weights). If you're not yet familiar with UniLM, I'd recommend first reading From language models to Seq2Seq: Transformers are all about masking.
In an earlier post, The versatile seq2seq: reading comprehension QA based on seq2seq, I already presented an implementation of reading comprehension via a Seq2Seq model — that is, using a Seq2Seq model to directly build $p\big(\text{answer}\big|\text{passage},\text{problem}\big)$, illustrated as follows:
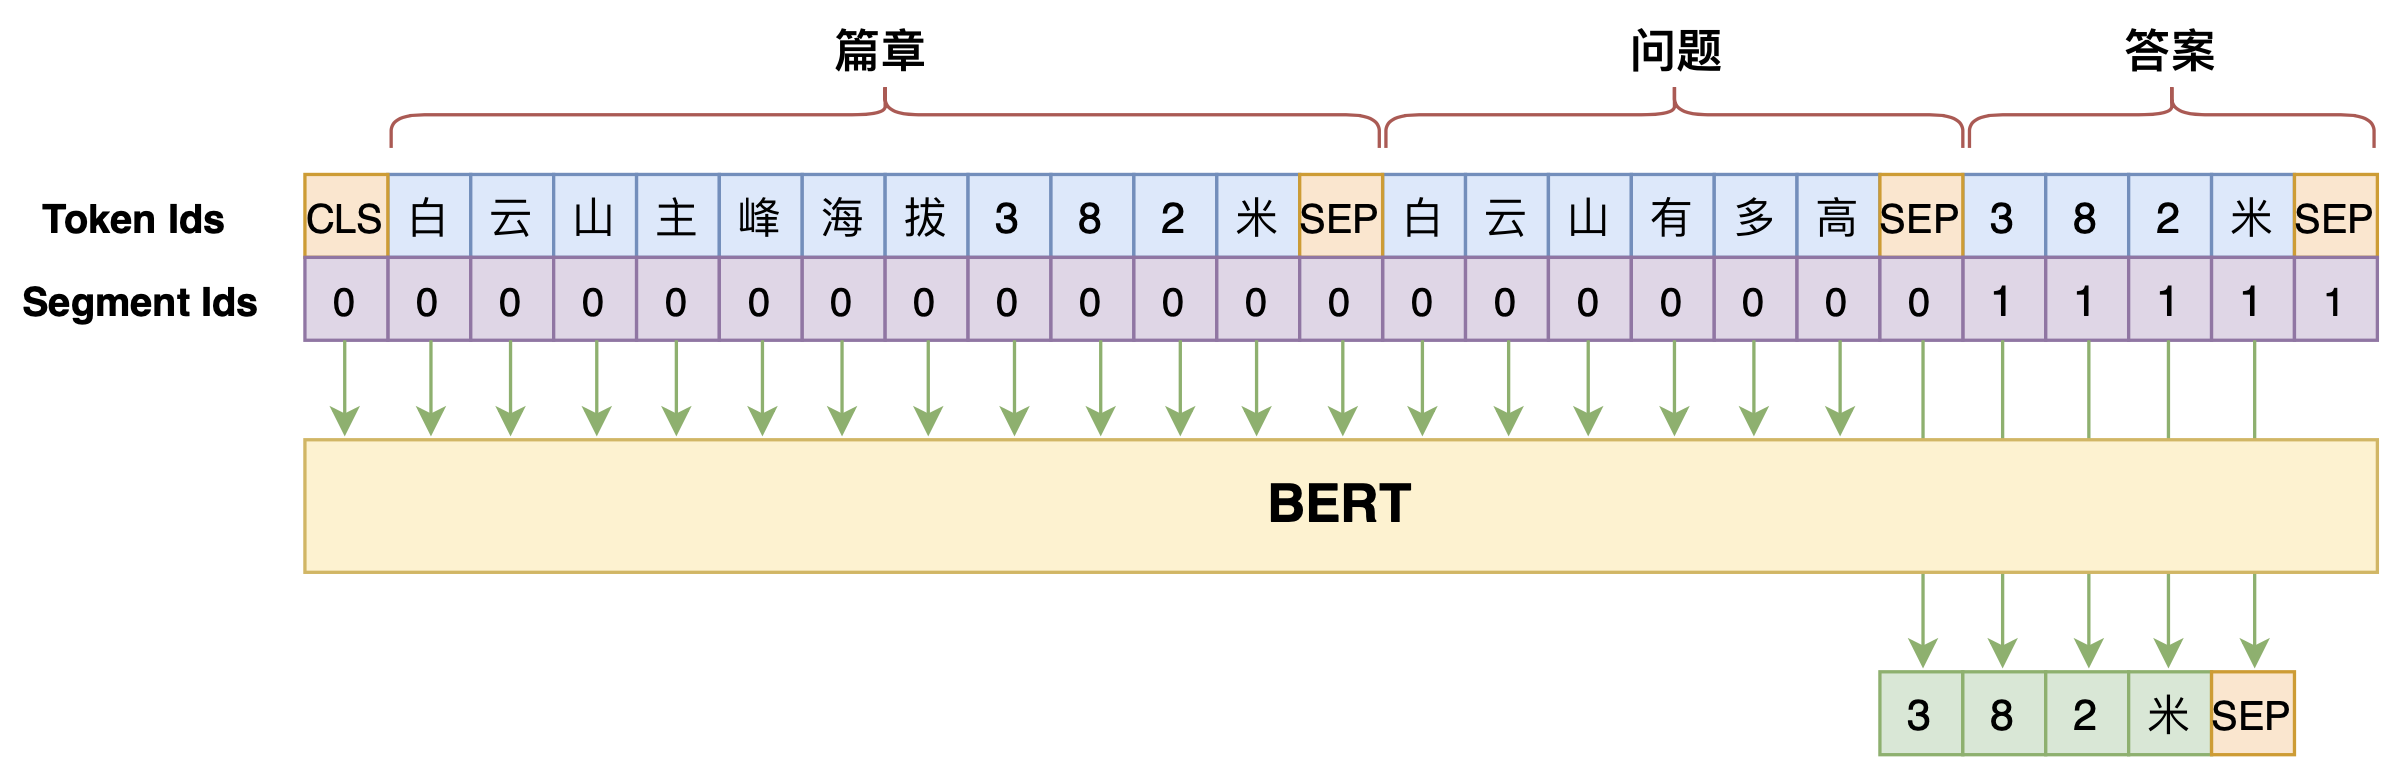 Using the seq2seq approach for reading comprehension
In fact, with a small modification to the above model — bringing the question into the generation target as well — we can achieve QA pair generation, turning the model into $p\big(\text{problem},\text{answer}\big|\text{passage}\big)$, as shown below:
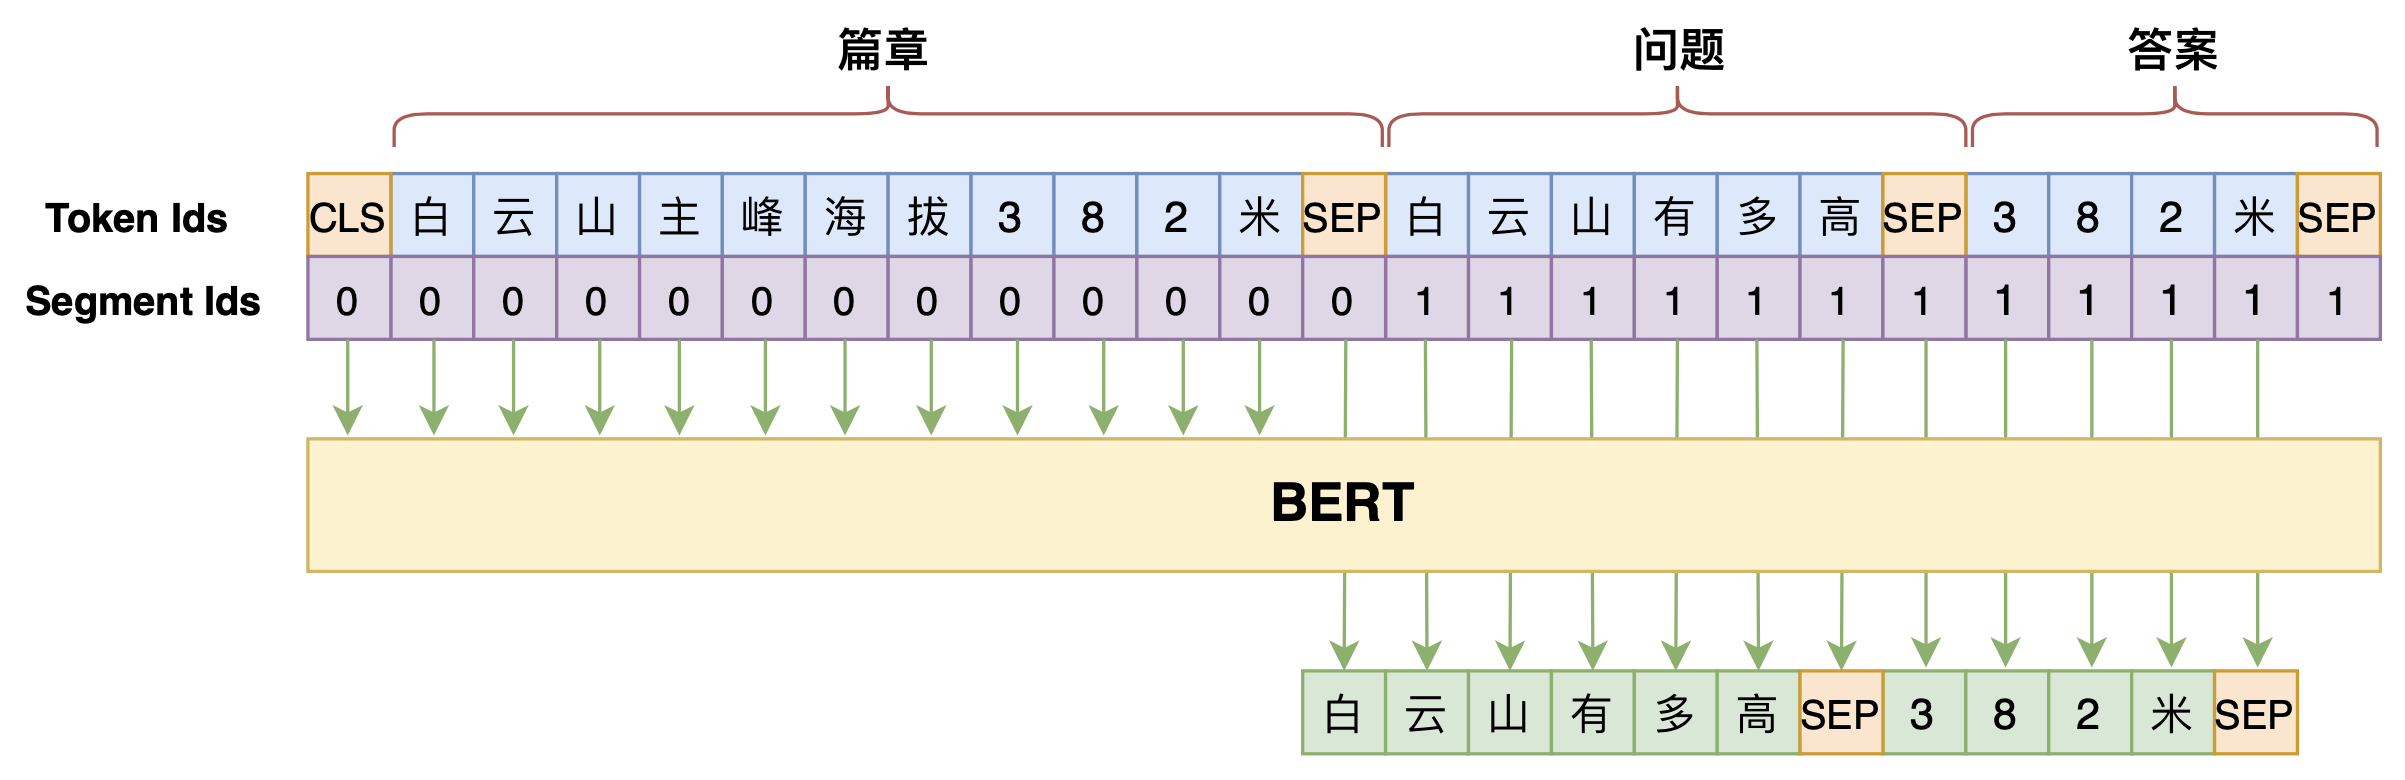 A slight modification, used for QA pair generation
However, it's intuitively clear that "passage → answer" and "passage + answer → question" should both be easier than "passage + question → answer." So we swap the generation order of the question and the answer, turning it into $p\big(\text{answer},\text{problem}\big|\text{passage}\big)$, which ultimately gives better results:
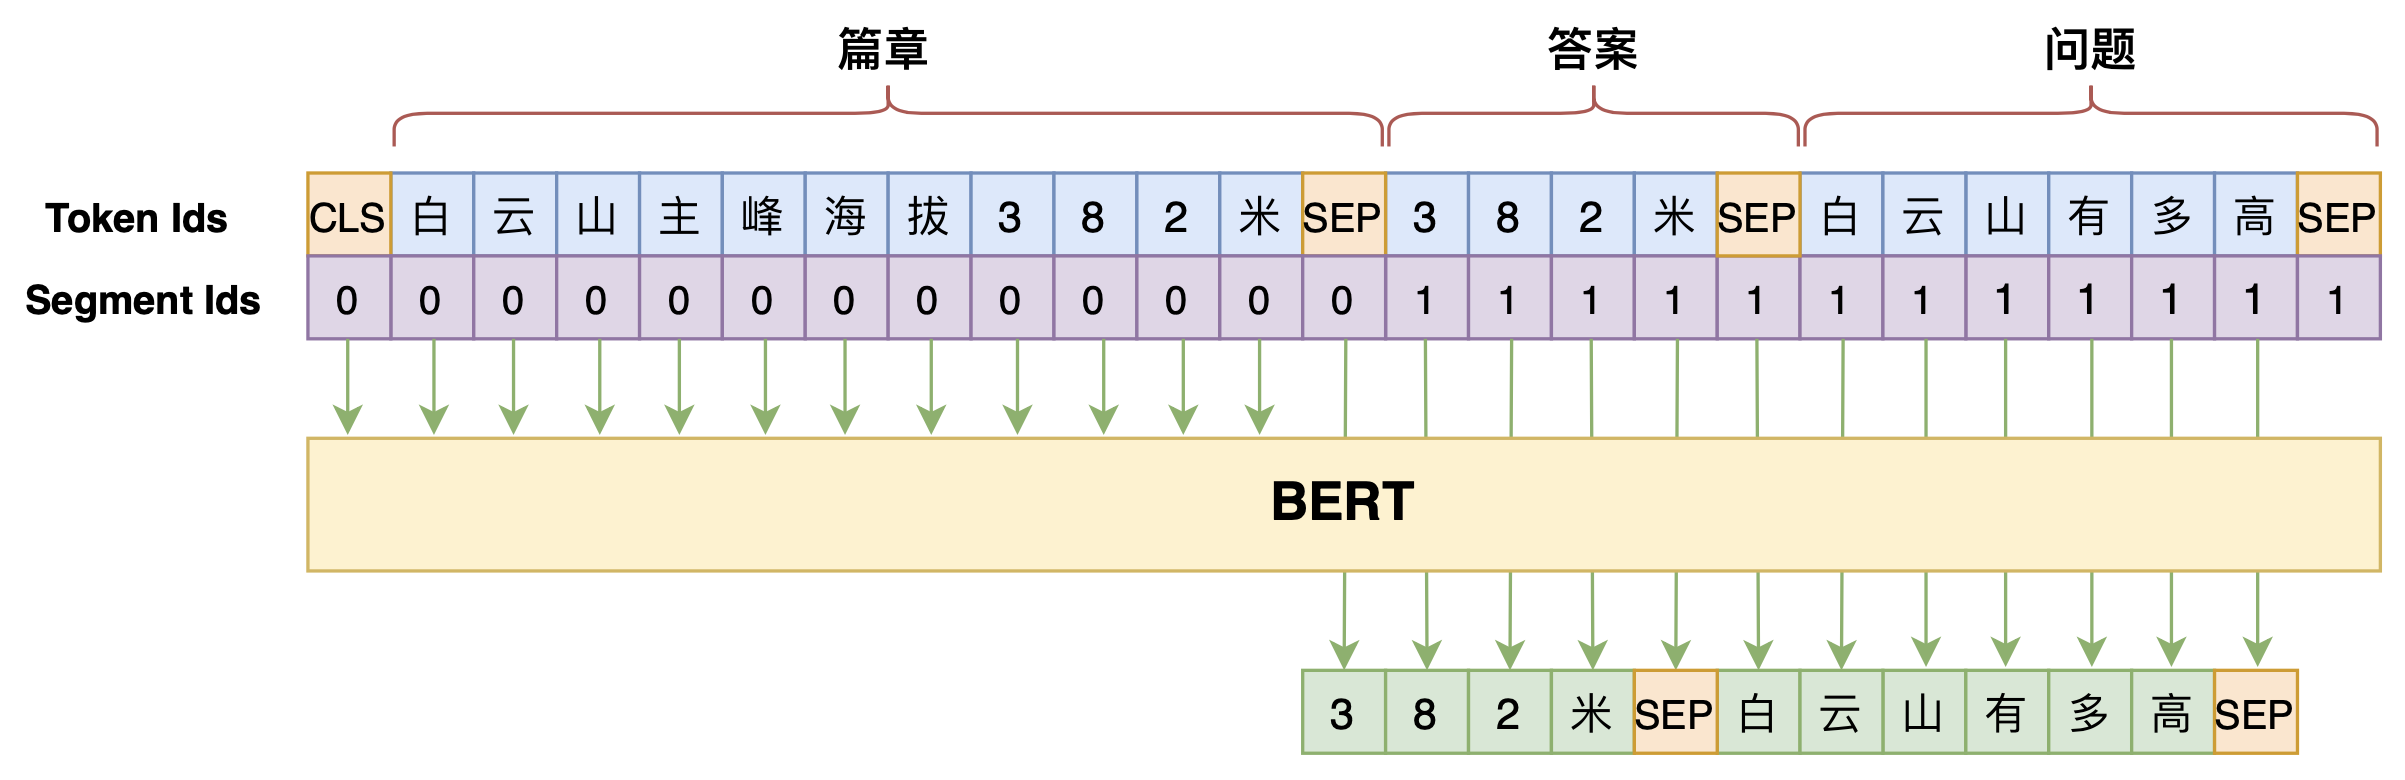 First generate the answer, then the question — this works better
Implementation notes
That's about all there is to say about the model — it really comes down to deciding what counts as input and what counts as output, then applying "BERT + UniLM" on top. Below is my reference implementation:
task_question_answer_generation_by_seq2seq.py
What's worth discussing here is the decoding strategy. In a typical Seq2Seq model, decoding stops once a single [SEP] is produced, but the model in this post needs to decode through two [SEP] tokens before it's done: everything up to the first [SEP] is the answer, and everything between the two [SEP]s is the question. In principle, a given passage can yield many possible QA pairs — in other words, the target is not unique — so we can't use a deterministic decoding algorithm like beam search; instead we need a stochastic decoding algorithm (for related concepts, see the "decoding algorithms" section of How to deal with the "it just won't stop" problem in Seq2Seq?).
The problem, though, is that if we use purely stochastic decoding, the generated questions can end up being too "wildly imaginative" — that is, content unrelated to the passage may show up. For example, if the passage is "China's Mars probe Tianwen-1 was successfully launched," the generated question might be "What was China's first artificial satellite?" — related, sure, but too much of a stretch. So I'd suggest a compromise strategy here: use stochastic decoding to generate the answer, then use deterministic decoding to generate the question, which helps keep the question as reliable as possible. Of course, if you care more about diversity in the generated questions, you could just use stochastic decoding throughout — feel free to tune this to your own needs.
One more thing worth noting: in the reference script above, no constraint is placed on the answer, so the generated answer might not actually be a span taken from the passage. After all, this is just a reference implementation, and there's still some distance to go before it's production-ready — interested readers should feel free to understand and modify the code according to their own needs. Also, since QA pair construction has now become entirely a Seq2Seq problem, any techniques for improving Seq2Seq performance can be applied here too — for instance, the previously discussed A brief look at exposure bias in Seq2Seq and some countermeasures. I'll leave those experiments to you.
Summary
This post presents an end-to-end practice of QA pair generation, built mainly on a "BERT + UniLM" Seq2Seq model that directly generates both the answer and the question from a passage, along with a discussion of decoding strategy. Overall, there's nothing particularly special about the model itself, but thanks to leveraging BERT's pretrained weights, the quality of the resulting QA pairs turns out to be quite commendable.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.