From DCGAN to SELF-MOD: A Survey of GAN Architecture Development
As a matter of fact, the discovery of O-GAN has already reached what I would consider my ideal pursuit of GAN, letting me comfortably climb out of the GAN rabbit hole. So now I'm going to try exploring more, broader research directions—tasks in NLP that haven't been done yet, or graph neural networks, or other interesting things.
But before that, I want to write down what I've learned about GANs so far.
In this post, we'll sort out how GAN architectures have developed—mainly the generator, since the discriminator hasn't changed much over time. Also, this post covers the development of GAN architectures for images; it has nothing to do with SeqGAN in NLP.
Also, I won't be covering the basics of GAN here.
A Word Beforehand
Broadly speaking, of course, any advance in image classification models also counts as progress for the discriminator (since they're both classifiers, and related techniques can often be applied to the discriminator). And image classification models have essentially not changed qualitatively since ResNet, which suggests that the ResNet structure is basically the optimal choice for discriminators.
But the generator is different. Although a relatively standard architecture design for GAN generators did emerge after DCGAN, it's far from settled or proven optimal. Even recently, plenty of work has gone into new generator designs—for example, SAGAN introduced self-attention into the generator (and discriminator), while the famous StyleGAN built on PGGAN by introducing a style-transfer-style generator.
So a lot of work has shown that there's still room to explore GAN generator design, and a good generator architecture can speed up GAN convergence or improve GAN performance.
DCGAN
When talking about the history of GAN architectures, we absolutely have to mention DCGAN—it counts as a landmark event in GAN history.
Background
As we all know, GAN originated from Ian Goodfellow's paper Generative Adversarial Networks, but early GANs were confined to simple datasets like MNIST. This is because when GAN first came out, although it sparked a wave of interest, it was still very much in a trial-and-error phase—issues of model architecture, stability, convergence, and so on were all still being explored. The emergence of DCGAN laid a solid foundation for solving this whole set of problems.
DCGAN comes from the paper Unsupervised Representation Learning with Deep Convolutional Generative Adversarial Networks. What did it actually do? It's simple, in a sense: it proposed a generator and discriminator architecture that greatly stabilized GAN training, so much so that it became the standard GAN architecture for quite a long time.
It sounds simple when put that way, but in fact achieving this was no small feat, because there are many architectures that look "reasonable" on an intuitive level, and picking out something close to optimal from all these combinations obviously requires a huge number of experiments. And precisely because DCGAN more or less established the standard architecture for GAN, once DCGAN was around, GAN researchers could devote more energy to a wider range of tasks, without getting too bogged down in model architecture and stability issues—which ushered in the flourishing development of GAN.
Architecture Description
Alright, enough talk—let's get back to discussing the architecture itself. The model architecture proposed by DCGAN is roughly as follows:
1. Neither the generator nor the discriminator uses pooling layers; instead they use (strided) convolutional layers. The discriminator uses ordinary convolution (Conv2D), while the generator uses deconvolution (DeConv2D);
2. Batch Normalization is used in both the generator and the discriminator;
3. The generator uses the ReLU activation function in all layers except the output layer, and the output layer uses Tanh;
4. The discriminator uses the LeakyReLU activation function in all layers;
5. No fully-connected layers are used after the convolutional layers;
6. No Global Pooling is used after the discriminator's final convolutional layer either—it's flattened directly instead.
Looking back now, this is actually a fairly simple structure, embodying the beauty of "great truths are simple," which further proves that what is truly good is necessarily simple.
The DCGAN architecture diagram is as follows:
 DCGAN's discriminator architecture (left) and generator architecture (right)
Personal Summary
A few key points:
1. The convolution/deconvolution kernel sizes are typically 4×4 or 5×5;
2. The stride for convolution/deconvolution is generally set to 2;
3. For the discriminator, BN is typically not used after the first convolutional layer, while later layers follow a "Conv2D + BN + LeakyReLU" pattern, until the feature map is down to 4×4;
5. For the generator, the first layer is fully connected, then reshaped to 4×4, followed by a "Conv2D + BN + ReLU" pattern; the last convolutional layer skips BN and uses tanh activation instead. Correspondingly, input images should be rescaled to the range −1 to 1 by dividing by 255, multiplying by 2, and subtracting 1.
Although the parameter count might look large, DCGAN is actually fast in practice and doesn't consume that much GPU memory, so it's quite popular. That's why, even though it looks old now, many tasks still use it. At least for rapid experimentation, it's an excellent architecture.
ResNet
As GAN research went deeper, people gradually discovered some shortcomings of the DCGAN architecture.
Problems with DCGAN
The generally accepted explanation is that because DCGAN's generator uses deconvolution, and deconvolution inherently suffers from the "checkerboard artifacts" problem, this checkerboard effect caps DCGAN's generative capacity. For details on the checkerboard effect, see Deconvolution and Checkerboard Artifacts (highly recommended—it has tons of illustrative examples).
 Illustration of checkerboard artifacts, showing an interlaced pattern resembling a chessboard when zoomed in. Image from Deconvolution and Checkerboard Artifacts
To be precise, checkerboard artifacts aren't really a problem specific to deconvolution, but rather an inherent flaw of stride > 1, which prevents convolution from covering the whole image "isotropically," producing an interlaced effect like a chessboard. And since deconvolution is typically paired with stride > 1, it's usually blamed on deconvolution. In fact, besides deconvolution, dilated convolution also exhibits checkerboard artifacts, because we can show that under a certain transformation, dilated convolution is actually equivalent to ordinary convolution with stride > 1.
On the other hand, I suspect there's another reason: DCGAN's nonlinear capacity might simply be insufficient. Readers who have analyzed DCGAN's results will notice that once the input image size is fixed, the entire DCGAN architecture is basically fixed too, including the number of layers. The only thing that seems adjustable is the convolution kernel size (the number of channels can be tweaked slightly too, but there isn't much room). Changing the kernel size can, to some extent, change the model's nonlinear capacity, but changing kernel size only changes the model's width, whereas for deep learning, depth is arguably more important than width. The problem is that for DCGAN, there's no natural, direct way to increase depth.
The ResNet Model
For these reasons, and as ResNet became more deeply entrenched in classification problems, it was natural to consider applying the ResNet structure to GANs. Indeed, the mainstream generator and discriminator architectures in GANs today have essentially shifted to ResNet, illustrated roughly as follows:
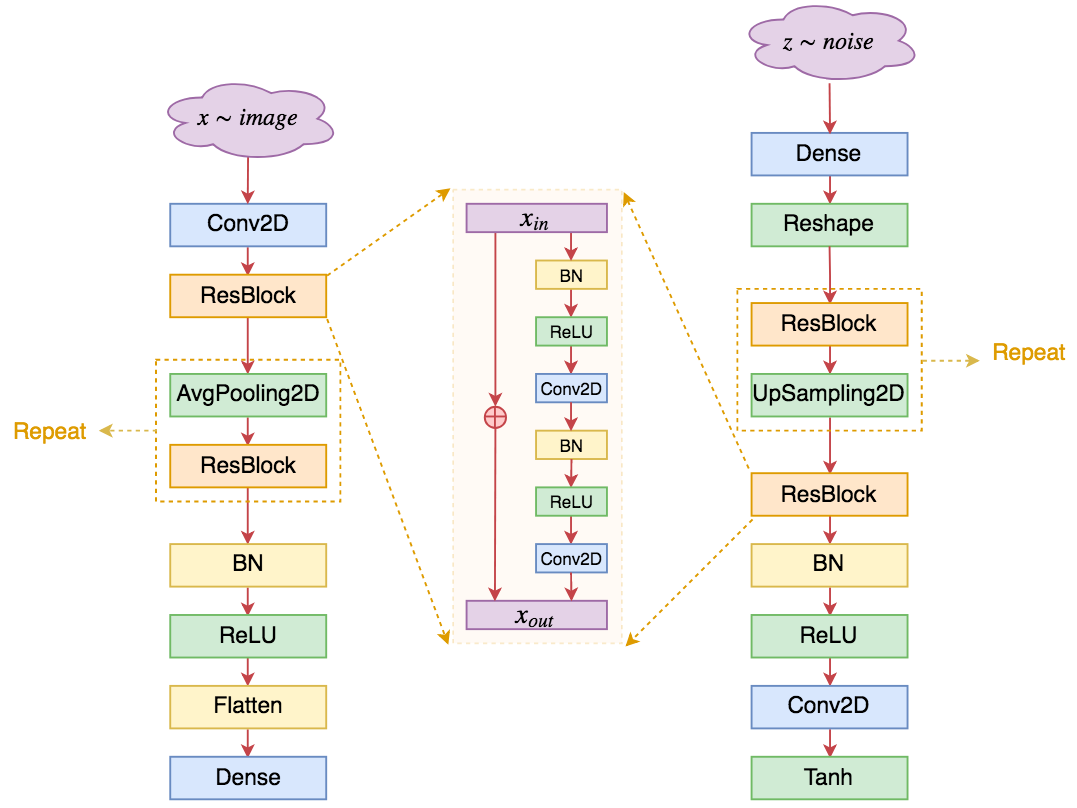 ResNet-based discriminator architecture (left) and generator architecture (right), with the structure of a single ResBlock in the middle
As you can see, ResNet-based GANs are actually not that different from DCGAN in overall structure (which further confirms DCGAN's foundational role). The main features are:
1. Whether in the discriminator or the generator, deconvolution is removed entirely, keeping only ordinary convolutional layers;
2. Convolution kernel sizes are typically standardized to 3×3, and convolutions form residual blocks;
3. Upsampling/downsampling is achieved via AvgPooling2D and UpSampling2D, whereas DCGAN achieved it through convolution/deconvolution with stride > 1; UpSampling2D is equivalent to scaling up the image's height/width by some factor;
4. Since residuals are already present, ReLU can be used uniformly as the activation function; though some models still use LeakyReLU—the difference is minor;
5. By increasing the number of convolutional layers within a ResBlock, one can simultaneously increase both the nonlinear capacity and the depth of the network—this is where ResNet's flexibility lies;
6. Generally the residual form is $x+f(x)$, where $f$ represents a stack of convolutional layers. However, in GANs, model initialization is usually smaller than in conventional classification models, so for the sake of stability, some models simply change this to $x+\alpha\times f(x)$, where $\alpha$ is a number less than 1, such as 0.1, which gives better stability;
7. Some authors believe BN isn't suitable for GANs, and sometimes just remove it, or replace it with something like LayerNorm.
Personal Summary
I haven't carefully looked into which paper was the first to use ResNet in GANs—I only know that well-known GANs like PGGAN, SNGAN, and SAGAN have all adopted ResNet. ResNet's stride is always 1, so it's uniform enough to avoid checkerboard artifacts.
However, ResNet is not without drawbacks. In terms of parameter count, compared to DCGAN, ResNet doesn't actually add parameters—in some cases it even has fewer parameters than DCGAN—but ResNet is much slower than DCGAN and requires much more GPU memory. This is because ResNet has more layers and more connections between layers, leading to more complex gradients and weaker parallelism (convolutions within the same layer can be parallelized, but convolutions across different layers are sequential and can't be parallelized directly). The result is that it's slower and uses more memory.
Also, the checkerboard effect is actually a very subtle effect—you can perhaps only notice the difference when generating high-resolution images. In fact, in my own experiments generating 128×128 or even 256×256 faces or LSUN images, I couldn't visually detect an obvious difference between DCGAN and ResNet in terms of output quality, but DCGAN was over 50% faster than ResNet. In terms of memory, DCGAN can directly handle 512×512 generation (on a single 1080ti), while ResNet struggles even at 256×256.
So unless I'm trying to compete for the current best FID or similar metrics, I wouldn't choose the ResNet architecture.
SELF-MOD
Normally, after covering ResNet, I should introduce models like PGGAN and SAGAN, since in terms of resolution or metrics like IS and FID, they too count as landmark events. However, I don't plan to cover them, because strictly speaking, PGGAN isn't really a new model architecture—it merely provides a progressive training strategy that can be applied on top of either the DCGAN or ResNet architecture. And SAGAN's changes are actually quite minor: the standard SAGAN just inserts a single self-attention layer into the middle of an ordinary DCGAN or ResNet architecture, which hardly counts as a major change to the generator architecture.
Instead, let's cover a relatively new improvement: the Self-Modulated Generator, from the paper On Self Modulation for Generative Adversarial Networks, which I'll just abbreviate here as "SELF-MOD."
Conditional BN
Before introducing SELF-MOD, I need to introduce one more thing: Conditional Batch Normalization (conditional BN).
As we all know, BN is a common operation in deep learning, especially in the image domain. To be honest, I'm not particularly fond of BN, but I have to admit it plays an important role in quite a few GAN models. Ordinary BN is unconditional: for an input tensor $\boldsymbol{x}_{i,j,k,l}$, where $i,j,k,l$ denote the batch, height, width, and channel dimensions of the image respectively, during training we have
\begin{equation}\boldsymbol{x}_{i,j,k,l}^{(out)}=\boldsymbol{\gamma}_l \times \frac{\boldsymbol{x}_{i,j,k,l}^{(in)} - \boldsymbol{\mu}_l}{\boldsymbol{\sigma}_l+\epsilon} + \boldsymbol{\beta}_l\end{equation}
where
\begin{equation}\boldsymbol{\mu}_l = \frac{1}{N}\sum_{i,j,k} \boldsymbol{x}_{i,j,k,l}^{(in)},\quad \boldsymbol{\sigma}^2_l = \frac{1}{N}\sum_{i,j,k} \left(\boldsymbol{x}_{i,j,k,l}^{(in)}-\boldsymbol{\mu}_l\right)^2\end{equation}
are the mean and variance of the input batch, with $N=\text{batch_size}\times \text{length}\times \text{width}$, and $\boldsymbol{\beta},\boldsymbol{\gamma}$ are trainable parameters, and $\epsilon$ is a small positive constant to prevent division by zero. In addition, a set of moving-average variables $\hat{\boldsymbol{\mu}},\hat{\boldsymbol{\sigma}}^2$ is maintained, and the moving-average mean and variance are used at test time.
The reason such BN is called unconditional is that the parameters $\boldsymbol{\beta},\boldsymbol{\gamma}$ are obtained purely through gradient descent and don't depend on the input. Correspondingly, if $\boldsymbol{\beta},\boldsymbol{\gamma}$ depends on some input $\boldsymbol{y}$, it's called conditional BN:
\begin{equation}\boldsymbol{x}_{i,j,k,l}^{(out)}=\boldsymbol{\gamma}_l(\boldsymbol{y}) \times \frac{\boldsymbol{x}_{i,j,k,l}^{(in)} - \boldsymbol{\mu}_l}{\boldsymbol{\sigma}_l+\epsilon} + \boldsymbol{\beta}_l(\boldsymbol{y})\end{equation}
Here $\boldsymbol{\beta}_l(\boldsymbol{y}),\boldsymbol{\gamma}(\boldsymbol{y})$ is the output of some model.
Let's first talk about how to implement this. Actually, in Keras, implementing conditional BN is quite easy—see the reference code below:
def ConditionalBatchNormalization(x, beta, gamma):
    """为了实现条件BN,只需要将Keras自带的BatchNormalization的
    beta,gamma去掉,然后传入外部的beta,gamma即可;为了训练上的稳定,
    beta最好能做到全0初始化,gamma最好能做到全1初始化。
    """
    x = BatchNormalization(center=False, scale=False)(x)
    def cbn(x):
        x, beta, gamma = x
        for i in range(K.ndim(x)-2):
            # 调整beta的ndim,这个根据具体情况改动即可
            beta = K.expand_dims(beta, 1)
            gamma = K.expand_dims(gamma, 1)
        return x * gamma + beta
    return Lambda(cbn)([x, beta, gamma])
SELF-MOD GAN
Conditional BN first appeared in the paper Modulating early visual processing by language, and was later used in cGANs With Projection Discriminator. It has now become the standard approach for conditional GANs (cGAN), and both SAGAN and BigGAN use it. Simply put, cGAN treats the label $\boldsymbol{c}$ as the condition for $\boldsymbol{\beta},\boldsymbol{\gamma}$, forming a conditional BN that replaces the generator's unconditional BN. That is, the generator's main input is still random noise $\boldsymbol{z}$, and then the condition $\boldsymbol{c}$ is fed into every BN layer in the generator.
So with all this talk about conditional BN, what does it have to do with SELF-MOD?
Here's the thing: SELF-MOD noticed that cGAN training is more stable, but in the general case, GANs don't have any label $\boldsymbol{c}$ available. So what to do? Simply use the noise $\boldsymbol{z}$ itself as the label! That's what "self-modulated" means—modulating itself without relying on any external label, yet achieving a similar effect. In formula form:
\begin{equation}\boldsymbol{x}_{i,j,k,l}^{(out)}=\boldsymbol{\gamma}_l(\boldsymbol{z}) \times \frac{\boldsymbol{x}_{i,j,k,l}^{(in)} - \boldsymbol{\mu}_l}{\boldsymbol{\sigma}_l+\epsilon} + \boldsymbol{\beta}_l(\boldsymbol{z})\end{equation}
In the original paper, $\boldsymbol{\beta}(\boldsymbol{z})$ is a two-layer fully-connected network:
\begin{equation}\boldsymbol{\beta}(\boldsymbol{z})=\boldsymbol{W}^{(2)}\max\left(0, \boldsymbol{W}^{(1)}\boldsymbol{z}+\boldsymbol{b}^{(2)}\right)\end{equation}
$\boldsymbol{\gamma}(\boldsymbol{z})$ is defined the same way. Looking at the official source code, I found that the dimension of the intermediate layer can actually be made fairly small—say, 32—so it doesn't noticeably increase the parameter count.
This is the generator with SELF-MOD structure for unconditional GAN.
Personal Summary
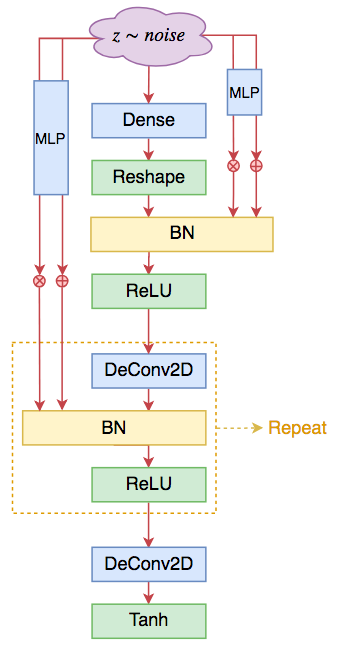 SELF-MOD-style DCGAN generator. The ResNet-based version is similar—both simply replace BN with the SELF-MOD version
I combined the SELF-MOD structure with my own O-GAN experiments and found that convergence speed improved by almost 50%, and the final FID and reconstruction quality were both better. SELF-MOD's excellence is plain to see, and I have a vague feeling that O-GAN and SELF-MOD might actually be a particularly good match (haha, not sure if that's just narcissistic wishful thinking).
Reference Keras code is here:
https://github.com/bojone/o-gan/blob/master/o_gan_celeba_sm_4x4.py
Additionally, even in cGAN, the SELF-MOD structure can be used. Standard cGAN treats the condition $\boldsymbol{c}$ as the input condition for BN, while SELF-MOD treats both $\boldsymbol{z}$ and $\boldsymbol{c}$ as the input condition for BN simultaneously. Reference usage is as follows:
\begin{equation}\begin{aligned}\boldsymbol{\beta}(\boldsymbol{z},\boldsymbol{c}) =& \boldsymbol{W}^{(2)}\max\left(0, \boldsymbol{W}^{(1)}\boldsymbol{z}'+\boldsymbol{b}^{(2)}\right)\\ \boldsymbol{z}' =& \boldsymbol{z}+\text{E}(\boldsymbol{c})+\text{E}'(\boldsymbol{c})\otimes \boldsymbol{z}\end{aligned}\end{equation}
where $\text{E},\text{E}'$ are two embedding layers—when the number of classes is small, you can just think of them as fully-connected layers—and $\boldsymbol{\gamma}$ works the same way.
Other Architectures
Readers might be wondering why I haven't mentioned the famous BigGAN and StyleGAN?
As a matter of fact, BigGAN didn't make any particularly notable improvement to the model architecture, and the authors themselves admit it's basically just "brute force working miracles." As for StyleGAN, it did indeed improve the model architecture, but once you understand SELF-MOD as covered above, StyleGAN isn't hard to understand either—you could even view StyleGAN as a variant of SELF-MOD.
AdaIN
The core of StyleGAN is something called AdaIN (Adaptive Instance Normalization), which comes from the style-transfer paper Arbitrary Style Transfer in Real-time with Adaptive Instance Normalization. It's actually quite similar to conditional BN, even simpler:
\begin{equation}\boldsymbol{x}_{i,j,k,l}^{(out)}=\boldsymbol{\gamma}_l(\boldsymbol{y}) \times \frac{\boldsymbol{x}_{i,j,k,l}^{(in)} - \boldsymbol{\mu}_{i,l}}{\boldsymbol{\sigma}_{i,l}+\epsilon} + \boldsymbol{\beta}_l(\boldsymbol{y})\end{equation}
The difference from conditional BN is: conditional BN uses $\boldsymbol{\mu}_{l}$ and $\boldsymbol{\sigma}_{l}$, while AdaIN uses $\boldsymbol{\mu}_{i,l}$ and $\boldsymbol{\sigma}_{i,l}$. That is, AdaIN only computes statistics within a single sample, rather than needing a batch of samples, so AdaIN doesn't need to maintain moving-average mean and variance—which makes it even simpler than conditional BN.
StyleGAN
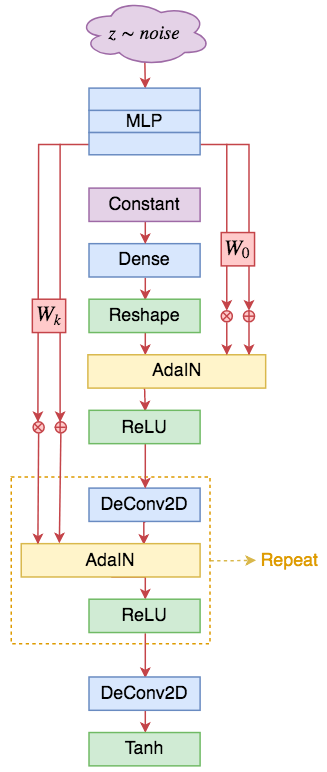 StyleGAN-style DCGAN generator. The ResNet-based version is similar; the main change is replacing conditional BN with AdaIN
With SELF-MOD and AdaIN covered, StyleGAN can now be explained clearly. StyleGAN's main change is also in the generator; compared with SELF-MOD, the differences are:
1. Remove the noise input at the top, replacing it with a trainable constant vector;
2. Replace all conditional BN with AdaIN;
3. The input condition for AdaIN comes from passing noise through a multi-layer MLP, and then projecting it with different transformation matrices into different AdaIN's $\boldsymbol{\beta}$ and $\boldsymbol{\gamma}$.
That's really all there is to it~
Personal Summary
I also experimented with a simplified StyleGAN-style DCGAN, and found that it converges and works reasonably well, but with slight mode collapse. Since the official StyleGAN was trained using the PGGAN paradigm, and I didn't do that, I suspect StyleGAN might need to be paired with PGGAN to train well—there's no clear answer yet. But in my own experiments, SELF-MOD was much easier to train than StyleGAN, and gave better results too.
Summary
This post has briefly sorted through the evolution of GAN model architectures, mainly the transitions from DCGAN to ResNet to SELF-MOD, focusing on fairly obvious changes—some more minor improvements may have been left out.
All along, work that dramatically overhauls GAN model architecture has been relatively rare, and SELF-MOD and StyleGAN have reignited some people's interest in architectural changes. The paper Deep Image Prior also demonstrates a fact: the prior knowledge embedded in the model architecture itself is a key reason image generation models can succeed. Proposing a better model architecture means proposing better prior knowledge, which naturally benefits image generation.
The architectures mentioned in this post have all been tested through my own experiments, and the assessments given are based on my own experiments and aesthetic judgment. If anything is off the mark, I welcome corrections from readers~
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.