From Variational Encoding and Information Bottleneck to the Normal Distribution: On the Importance of Forgetting
This is an "essay" in which we discuss three things that are intricately connected: the variational autoencoder, the information bottleneck, and the normal distribution.
As is well known, the variational autoencoder is a classic generative model, but in fact it carries meaning that goes beyond generative modeling; as for the information bottleneck, readers may be relatively unfamiliar with it, yet it actually caused quite a stir last year; and as for the normal distribution, no need to say more—it has connections, more or less, with almost every corner of machine learning.
So when these three collide, what stories can be told? And what does any of this have to do with "forgetting"?
Variational Autoencoders
On this blog you can search for several articles introducing VAEs. Let's briefly recap below.
Recap of the theoretical form
Briefly, the optimization objective of a VAE is:
\begin{equation}KL(\tilde{p}(x)p(z|x)\Vert q(z)q(x|z))=\iint \tilde{p}(x)p(z|x)\log \frac{\tilde{p}(x)p(z|x)}{q(x|z)q(z)} dzdx\end{equation}
Here $q(z)$ is the standard normal distribution and $p(z|x),q(x|z)$ is a conditional normal distribution, corresponding to the encoder and decoder respectively. For details, see Variational Autoencoders (II): From a Bayesian Perspective. more
This objective can ultimately be simplified to
\begin{equation}\mathbb{E}_{x\sim \tilde{p}(x)} \Big[\mathbb{E}_{z\sim p(z|x)}\big[-\log q(x|z)\big]+KL\big(p(z|x)\big\Vert q(z)\big)\Big]\label{eq:vae}\end{equation}
Clearly, it can be viewed as two parts: the term $\mathbb{E}_{z\sim p(z|x)}\big[-\log q(x|z)\big]$ is equivalent to an ordinary autoencoder loss (with the reparameterization trick added), while $KL\big(p(z|x)\big\Vert q(z)\big)$ is the KL divergence between the posterior and prior distributions. The first term wants the reconstruction loss to be as small as possible, i.e. it wants the latent variable $z$ in the middle to retain as much information as possible; the second term wants the latent-variable space to align with the normal distribution, meaning we want the distribution of the latent variable to be more regular.
Comparison with the autoencoder
So, compared to an ordinary autoencoder, the changes made by the VAE are:
1. Introducing the concepts of mean and variance, adding a reparameterization operation;
2. Adding the KL divergence as an extra loss term.
Information Bottleneck
I feel I've already introduced enough about VAEs on this blog, so I won't belabor it further, and will move straight on to the introduction of the Information Bottleneck (IB).
Unveiling the black box of deep learning?
Last September there was a talk on deep learning and the information bottleneck, claiming to unveil the black box of deep learning (DL); Hinton, upon hearing it, reportedly remarked "this is so interesting I need to watch it another 10,000 times..." (see Unveiling the Deep Learning Black Box: A Hebrew University Computer Science Professor Proposes the "Information Bottleneck"), and that's when the information bottleneck really took off. Not long after, an article came out to challenge this result, showing that the conclusions of the information bottleneck are not universal (see Bursting the Bubble: A Critical Analysis of "Information Bottleneck" Theory), which made things even more lively.
Whether or not the information bottleneck can truly unveil the secrets of deep learning, as pragmatists, what mainly concerns us is whether the information bottleneck can actually extract something of practical value. The so-called information bottleneck is a fairly simple idea: given a task, it tries to accomplish it using the least amount of information possible. This is actually similar to what we discussed earlier in the "minimum entropy series", because information corresponds to learning cost—using the least information to accomplish a task means accomplishing it at the lowest possible cost, which in turn means a model with better generalization.
The principle behind the information bottleneck
Why does lower cost / less information lead to better generalization? This isn't hard to understand. For example, in a company, if we want to design a custom solution for every single customer and assign a dedicated staff member to follow up, the cost would be enormous; but if we can find one general-purpose solution that only needs fine-tuning afterward, the cost is much lower. It's a "general-purpose solution" precisely because we've found the commonalities and patterns in customer needs. So clearly, the lowest-cost solution implies that we've found some universal patterns and characteristics, and that in turn implies generalization ability.
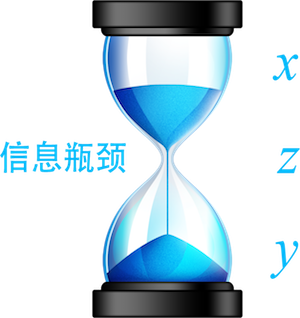 Diagram illustrating the information bottleneck
How do we express this in deep learning? The answer is the "Variational Information Bottleneck" (VIB), which comes from the paper Deep Variational Information Bottleneck.
Suppose we're facing a classification task, with labeled data pairs $(x_1,y_1),\dots,(x_N,y_N)$. We can understand this task as consisting of two steps: encoding, and then classification. The first step encodes $x$ into a latent variable $z$, and then the classifier recognizes $z$ as class $y$.
$$x \quad \to \quad z \quad \to \quad y$$
Now imagine adding a "bottleneck" $\beta$ at $z$. It's like an hourglass: the amount of information flowing in may be large, but the outlet is only as wide as $\beta$, so the effect of this bottleneck is: the amount of information allowed to flow through $z$ cannot exceed $\beta$. Unlike an hourglass, where the sand is done once it passes through the neck, information that passes through the information bottleneck still needs to accomplish whatever task it's meant to complete (classification, regression, etc.). So the model is forced to find a way to let only the most important information through the bottleneck. This is the principle behind the information bottleneck.
Variational Information Bottleneck
How do we formalize this quantitatively? We use "mutual information" as the metric to measure the amount of information passing through:
\begin{equation}\iint p(z|x)\tilde{p}(x)\log \frac{p(z|x)}{p(z)}dxdz\end{equation}
Here $p(z)$ is not an arbitrarily specified distribution but rather the true distribution of the latent variable; in theory, once we know $p(z|x)$, we could compute $p(z)$, since it's formally equal to
\begin{equation}p(z) = \int p(z|x)\tilde{p}(x)dx\end{equation}
Of course this integral is usually intractable, but we'll figure out a workaround later.
We also have a task loss—for a classification task this is typically cross-entropy:
\begin{equation}-\iint p(z|x)\tilde{p}(x)\log p(y|z)dxdz\end{equation}
Written this way, it makes explicit that we have an encoder that first encodes $x$ into $z$, and then classifies based on $z$.
How do we enforce "the amount of information flowing through $z$ must not exceed $\beta$"? We can simply add it as a penalty term, giving the final loss as
\begin{equation}-\iint p(z|x)\tilde{p}(x)\log p(y|z)dxdz + \lambda \iint p(z|x)\tilde{p}(x)\max\left(\log \frac{p(z|x)}{p(z)} - \beta, 0\right)dxdz\end{equation}
That is, once the mutual information exceeds $\beta$, a positive penalty term kicks in. Of course, often we don't know what value to set $\beta$ to, so a more straightforward approach is to drop $\beta$ altogether, giving
\begin{equation}-\iint p(z|x)\tilde{p}(x)\log p(y|z)dxdz + \lambda \iint p(z|x)\tilde{p}(x)\log \frac{p(z|x)}{p(z)}dxdz\end{equation}
This simply expresses the preference for the information content to be as small as possible, without setting a specific threshold.
Now, we have the formula, but as mentioned, $p(z)$ is not computable, so we instead estimate an upper bound for it: assuming $q(z)$ is a distribution of known form, we have
\begin{equation}\begin{aligned}&\iint p(z|x)\tilde{p}(x)\log \frac{p(z|x)}{p(z)}dxdz\\ =&\iint p(z|x)\tilde{p}(x)\log \frac{p(z|x)}{q(z)}\frac{q(z)}{p(z)}dxdz\\ =&\iint p(z|x)\tilde{p}(x)\log \frac{p(z|x)}{q(z)} + \iint p(z|x)\tilde{p}(x)\log \frac{q(z)}{p(z)}dxdz\\ =&\iint p(z|x)\tilde{p}(x)\log \frac{p(z|x)}{q(z)} + \int p(z)\log \frac{q(z)}{p(z)}dz\\ =&\iint p(z|x)\tilde{p}(x)\log \frac{p(z|x)}{q(z)} - \int p(z)\log \frac{p(z)}{q(z)}dz\\ =&\int \tilde{p}(x) KL\big(p(z|x)\big\Vert q(z)\big) dx - KL\big(p(z)\big\Vert q(z)\big)\\ < &\int \tilde{p}(x) KL\big(p(z|x)\big\Vert q(z)\big) dx\end{aligned}\end{equation}
This shows that $\int\tilde{p}(x) KL\big(p(z|x)\big\Vert q(z)\big) dx$ is an upper bound of $\iint p(z|x)\tilde{p}(x)\log \frac{p(z|x)}{p(z)}dxdz$, so if we optimize the former, the latter will not exceed it either. Since the latter can't be computed directly, we settle for optimizing the former. So the final usable loss is
\begin{equation}-\iint p(z|x)\tilde{p}(x)\log p(y|z)dxdz + \lambda \int\tilde{p}(x) KL\big(p(z|x)\big\Vert q(z)\big) dx\end{equation}
or equivalently written as
\begin{equation}\mathbb{E}_{x\sim \tilde{p}(x)} \Big[\mathbb{E}_{z\sim p(z|x)}\big[-\log p(y|z)\big]+\lambda\cdot KL\big(p(z|x)\big\Vert q(z)\big)\Big]\label{eq:vib}\end{equation}
This is the "Variational Information Bottleneck".
Observations and implementation
As you can see, if $q(z)$ is taken to be the standard normal distribution (which, in fact, is what we always do, so this "if" is satisfied), then $\eqref{eq:vib}$ is almost identical to the VAE loss function $\eqref{eq:vae}$. The only difference is that $\eqref{eq:vib}$ deals with a supervised task while $\eqref{eq:vae}$ is unsupervised learning; but if we regard the VAE as a supervised learning task whose label is the input itself $x$, then it becomes a special case of $\eqref{eq:vib}$.
So, compared to the original supervised learning task, the changes brought by the variational information bottleneck are:
1. Introducing the concepts of mean and variance, adding a reparameterization operation;
2. Adding the KL divergence as an extra loss term.
Exactly the same as the VAE!
Implementing the variational information bottleneck in Keras is extremely simple. I've defined a layer that you can readily use:
from keras.layers import Layer
import keras.backend as K

class VIB(Layer):
    """变分信息瓶颈层
    """
    def __init__(self, lamb, **kwargs):
        self.lamb = lamb
        super(VIB, self).__init__(**kwargs)
    def call(self, inputs):
        z_mean, z_log_var = inputs
        u = K.random_normal(shape=K.shape(z_mean))
        kl_loss = - 0.5 * K.sum(K.mean(1 + z_log_var - K.square(z_mean) - K.exp(z_log_var), 0))
        self.add_loss(self.lamb * kl_loss)
        u = K.in_train_phase(u, 0.)
        return z_mean + K.exp(z_log_var / 2) * u
    def compute_output_shape(self, input_shape):
        return input_shape[0]
Usage is simple—just make small modifications to your existing task, as shown here:
https://github.com/bojone/vib/blob/master/cnn_imdb_vib.py
Result: compared to a model without VIB, the model with VIB added converges faster, and easily reaches 89%+ validation accuracy, whereas the model without VIB typically only reaches 88%+ accuracy, and converges more slowly.
Variational Discriminator Bottleneck
The original paper Deep Variational Information Bottleneck shows that VIB is quite an effective regularization technique, improving the performance of the original model on multiple tasks.
However, the story of the information bottleneck doesn't end there. Not long ago, a paper titled Variational Discriminator Bottleneck was rated as a high-scoring ICLR 2019 paper (the famous BigGAN appeared in the same batch). The authors of this paper were no longer satisfied with merely applying the variational information bottleneck to ordinary supervised tasks—they developed the "Variational Discriminator Bottleneck" and applied it in one fell swoop to GANs, reinforcement learning, and various other tasks, achieving improvements across the board! This gives a glimpse of just how powerful the information bottleneck can be.
Unlike Equation $\eqref{eq:vib}$, the update mechanism of the information bottleneck in Variational Discriminator Bottleneck was modified so as to give it a degree of adaptivity, though the underlying idea remains unchanged: regularizing the model by constraining mutual information. But this is no longer the focus of this article, so interested readers are encouraged to read the original paper.
The Normal Distribution
Through this comparison, we've already found that both VAE and VIB simply introduce reparameterization into the original task, and add a KL divergence term. Intuitively, the role of the regularization term is to push the distribution of the latent variable closer to the standard normal distribution. So what exactly is so good about the normal distribution?
Regularity and decoupling
Honestly, the origins, history, and uses of the normal distribution could fill an entire book. Many of its properties have already been discussed elsewhere, so here I'll only cover the parts that are most relevant to this article.
Actually, the role of the KL divergence is to align the distribution of the latent variable with the (multivariate) standard normal distribution, rather than an arbitrary normal distribution. The standard normal distribution is relatively regular, offering benefits like zero mean and unit variance, but more importantly, it has a highly valuable property: each of its components is decoupled—in probabilistic terms, mutually independent, satisfying $p(x,y)=p(x)p(y)$.
We know that if features are mutually independent, modeling becomes much easier (the naive Bayes classifier is a perfectly accurate model under this assumption), and mutually independent features are also much easier to interpret—so we always want features to be mutually independent. As far back as 1992, Schmidhuber, the father of the LSTM, proposed the PM model (Predictability Minimization), devoted to constructing an autoencoder with decoupled features; see From PM to GAN — Schmidhuber's 22-Year Grudge for the related story. Indeed, in the years before I was even born, the great minds were already working on feature decoupling—which tells you just how valuable it is.
In VAEs (and later, adversarial autoencoders), the distribution of the latent variable is directly aligned with a decoupled prior via the KL divergence. This has the benefit that the latent variable itself ends up close to decoupled, gaining all the advantages of decoupling mentioned above. So now we can answer a question that's often asked:
Q: From the perspective of feature encoding, what advantage does the variational autoencoder have over an ordinary autoencoder?
A: The variational autoencoder uses the KL divergence to pull the latent variable distribution close to the standard normal distribution, thereby decoupling the latent features and simplifying any downstream model built on top of that feature. (Of course, you could also bring in the earlier discussion of the variational information bottleneck to strengthen your answer—e.g. mentioning enhanced generalization, etc. ^_^)
Linear interpolation and convolution
Additionally, the normal distribution has another important property, one that's commonly used to demonstrate the quality of generative models: linear interpolation, as shown below.
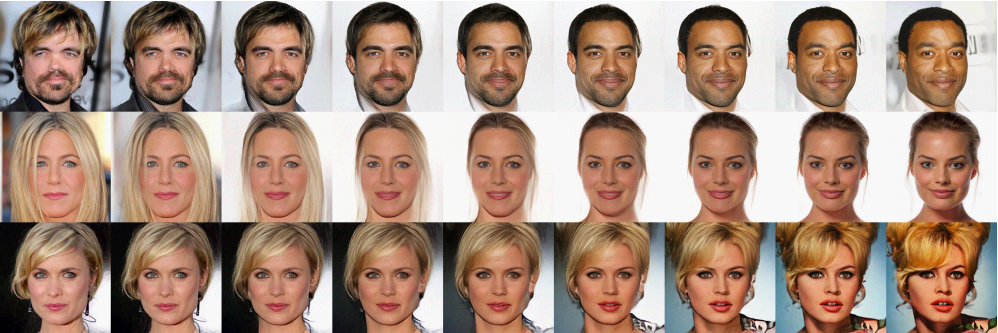 Interpolation results quoted from the Glow model
The process of this linear interpolation is as follows: first sample two random vectors $z_1,z_2\sim \mathcal{N}(0, 1)$; clearly, a good generator will turn both $z_1,z_2$ into realistic images $g(z_1),g(z_2)$. We then consider $g(z_{\alpha})$, where
\begin{equation}z_{\alpha} = (1 - \alpha) z_1 + \alpha z_2,\quad 0 \leq \alpha \leq 1\end{equation}
As $\alpha$ varies from 0 to 1, we expect to see $g(z_{\alpha})$ gradually transition from image $g(z_1)$ to image $g(z_2)$—and indeed, that's exactly what happens.
Why must interpolation be done in the latent-variable space? Why doesn't interpolating directly on the raw images give something valuable? This, too, is actually related to the normal distribution, thanks to the following convolution theorem (this "convolution" refers to the mathematical convolution operator, not the convolutional layer in neural networks):
If $z_1\sim \mathcal{N}(\mu_1, \sigma_1^2),z_2\sim \mathcal{N}(\mu_2, \sigma_2^2)$, and they are mutually independent random variables, then
$$z_1 + z_2 \sim\mathcal{N}(\mu_1+\mu_2, \sigma_1^2+\sigma_2^2)$$
In particular, if $z_1\sim \mathcal{N}(0, 1),z_2\sim \mathcal{N}(0, 1)$, then
$$\alpha z_1 + \beta z_2 \sim \mathcal{N}(0, \alpha^2+\beta^2)$$
This says that the sum of normally distributed random variables is itself normally distributed. What does this imply? It implies that in the world of the normal distribution, the linear interpolation of two variables still remains within that same world. This is not a trivial property, since clearly interpolating between two real samples need not produce another real sample.
For supervised tasks, what's the value of this linear-interpolation property? It turns out to be quite important. We know that labeled datasets are hard to come by. If we can reasonably map the latent-variable space of a finite training set to the standard normal distribution, then we can expect that the portions not covered by the training set may also, in effect, be accounted for, since their latent variables could just be linear interpolations of the latent variables of the existing training set.
In other words, once we've completed supervised training and also regularized the latent-variable distribution to the standard normal distribution, we've effectively already accounted for the "in-between" samples of the training set, which amounts to covering a much larger effective sample space.
Note: We usually consider uniform linear interpolation in the spatial domain, i.e. of the form $\beta = 1-\alpha$, but from the perspective of $\alpha z_1 + \beta z_2 \sim \mathcal{N}(0, \alpha^2+\beta^2)$, the best choice is actually interpolation of the form $\alpha^2+\beta^2=1$, i.e.
$$z_{\theta}=z_1\cdot\cos\theta + z_2\cdot\sin\theta$$
Second, readers might wonder: when a GAN uses a uniform distribution as its prior, can't we also do linear interpolation there? Doesn't that mean this isn't unique to the normal distribution? Actually, the convolution of a uniform distribution is no longer uniform, but its probability density function happens to concentrate near the middle of the original uniform distribution's support (it's just no longer uniform—effectively a subset of the original range), so the interpolation results still look reasonably good, even though it's less elegant in theory. Also, in practice, GAN training these days mostly uses the normal distribution anyway, and it trains better than with the uniform distribution.
Learning and Forgetting
Finally, after all this discussion, everything here maps onto one very intuitive concept: forgetting.
Forgetting is also an important topic in deep learning, and related findings keep popping up from time to time. For example, if we fine-tune a well-trained model on data from a new domain, the model often ends up only working for the new domain, rather than both—this is the "catastrophic forgetting" problem in deep learning. Or take a study from a while back, which found that among the LSTM's three gates, keeping only the "forget gate" is actually sufficient.
As for the information bottleneck discussed at length above, it too corresponds to forgetting. Because the brain's capacity is fixed, you're forced to accomplish your task using limited information, and this process of extraction is precisely what surfaces the valuable information. Take the classic example again: bank tellers can often spot a counterfeit note just by looking at or touching it, but do they really know every detail of a genuine banknote? Could they draw its outline from memory? I doubt it. That's because the brain capacity they've allocated to this task is limited—they only need to recognize the most crucial cues for spotting fakes. This is the brain's own information bottleneck.
The information bottleneck in deep learning discussed earlier can be understood the same way. It's generally believed that the effectiveness of neural networks is rooted in information loss—layer by layer discarding useless information (forgetting it), and ultimately retaining only the effective, generalizable information. But neural networks have so many parameters that this goal isn't always naturally achieved, so the information bottleneck adds a constraint to the network that essentially "forces" it to forget useless information. Precisely because of this, VIB doesn't always improve your original model's performance—if your model has already been "discarding useless information layer by layer (forgetting it) and retaining only the effective, generalizable information," then VIB becomes redundant. VIB is just one regularization term, and like all regularization terms, its effect is never absolute.
This suddenly reminds me of a passage from The Heaven Sword and Dragon Saber, describing Zhang Wuji learning Tai Chi swordsmanship:
What Zhang Sanfeng had passed down to him was the "intent" of the sword, not its "forms." He had to forget every last trace of the sword forms he had just seen in order to grasp their essence—only then could he wield the sword by intent alone in battle, with infinite, ever-changing variation. If even one or two forms remained lodged in his memory, his mind would be constrained, and his swordsmanship could never be pure.
So it turns out that forgetting is the highest realm of mastery! Which is why, although this article might seem to have wandered off-topic, it is in fact a genuine essay — On the Importance of Forgetting.
 Screenshot from "Cult Leader from The Heaven Sword and Dragon Saber"
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.