A Steady Stream of Flow: RealNVP and Glow - The Inheritance and Sublimation of Flow Models
RealNVP and Glow: Inheriting and Elevating the Flow Model
Foreword
In the previous post, The Long, Slow Flow: NICE and the Basic Concepts of Flow Models, we introduced one of the pioneering works of flow models: NICE. From NICE we learned the basic concepts and ideas behind flow models, and I finished with a Keras implementation of NICE.
In this post we turn our attention to NICE's successors: RealNVP and Glow.
[
Your browser does not support video
](/usr/uploads/2018/08/1414535518.mp4)
A sampling demo from Glow (taken from the official Glow blog).
An elegantly designed flow
It has to be said, flow is an exceptionally elegant model in terms of design. In broad strokes, flow is about finding an encoder that maps the input $\boldsymbol{x}$ to a latent variable $\boldsymbol{z}$, such that $\boldsymbol{z}$ follows a standard normal distribution. Thanks to the clever design of flow models, this encoder is invertible, so we can immediately write down the corresponding decoder (generator) from the encoder. That means once the encoder is trained, we automatically get the decoder as well, completing the construction of a generative model.
To pull this off, it's not enough for the model to be invertible — the corresponding Jacobian determinant must also be easy to compute. To that end, NICE proposed the additive coupling layer: by stacking multiple additive coupling layers, the model gains strong fitting power while keeping a unit Jacobian determinant. And that's how a generative model distinct from VAEs and GANs — the flow model — came to be. Through this clever construction, it lets us directly fit the probability distribution itself. more
Uncharted territory
NICE offered this new way of thinking about flow models and ran some simple experiments, but it also left a lot of unexplored space behind. While the design of flow is ingenious, NICE's experiments were rather crude in comparison: it simply stacked fully-connected layers, without demonstrating, say, how to use convolutional layers, and although the paper ran several experiments, in truth only the MNIST experiment really succeeded — not very convincing.
So flow models still needed further development before they could truly shine in the field of generative modeling. That development was carried out by NICE's "successors," RealNVP and Glow. It's fair to say that their work is what made flow models really stand out, turning them into one of the front-runners in generative modeling.
RealNVP
In this section we introduce RealNVP, an improvement over NICE, from the paper Density Estimation Using Real NVP. It generalizes the coupling layer and successfully introduces convolutional layers into the coupling framework, allowing much better handling of image data. Furthermore, it proposes a multi-scale layer design, which reduces computational cost while also providing a strong regularization effect that improves generation quality. With this, the general framework for flow models began to take shape.
The later Glow model largely follows RealNVP's framework, only modifying some parts of it (for instance, introducing invertible 1×1 convolutions to replace the permutation layer). It's worth noting, though, that Glow simplifies RealNVP's structure, showing that some of the more complicated design choices in RealNVP were in fact unnecessary. For that reason, in this post I won't strictly distinguish between RealNVP and Glow when introducing them, but will instead just highlight their main contributions.
Affine coupling layers
As it happens, the first author of both NICE and RealNVP is Laurent Dinh, a PhD student of Bengio's, and I really admire how relentlessly he pursued and refined the flow model. In the original NICE paper he proposed the additive coupling layer, and in fact he did mention a multiplicative coupling layer too, though it wasn't actually used. In RealNVP, the additive and multiplicative coupling layers are combined into a single general "affine coupling layer."
$$\begin{aligned}&\boldsymbol{h}_{1} = \boldsymbol{x}_{1}\\ &\boldsymbol{h}_{2} = \boldsymbol{s}(\boldsymbol{x}_{1})\otimes\boldsymbol{x}_{2} + \boldsymbol{t}(\boldsymbol{x}_{1})\end{aligned}\tag{1}$$
Here both $\boldsymbol{s},\boldsymbol{t}$ are vector functions of $\boldsymbol{x}_1$. Formally, the second equation corresponds to an affine transformation of $\boldsymbol{x}_2$, which is why it's called an "affine coupling layer."
The Jacobian matrix of the affine coupling is still triangular, but the diagonal entries are no longer all 1. Written in block-matrix form,
$$\left[\frac{\partial \boldsymbol{h}}{\partial \boldsymbol{x}}\right]=\begin{pmatrix}\mathbb{I}_d & \mathbb{O} \\ \left[\frac{\partial \boldsymbol{s}}{\partial \boldsymbol{x}_1}\otimes \boldsymbol{x}_2+\frac{\partial \boldsymbol{t}}{\partial \boldsymbol{x}_1}\right] & \boldsymbol{s}\end{pmatrix}\tag{2}$$
Clearly its determinant is just the product of the elements of $\boldsymbol{s}$. To guarantee invertibility, we generally constrain every element of $\boldsymbol{s}$ to be positive, so in practice we usually model the network output $\log \boldsymbol{s}$ directly and then take its exponential $e^{\log \boldsymbol{s}}$.
Note: the affine layer is roughly where RealNVP gets its name — the full name is "real-valued non-volume preserving," which I'll bluntly translate as "实值非体积保持" ("real-valued, non-volume-preserving"). Whereas the determinant of the additive coupling layer is 1, RealNVP's Jacobian determinant is no longer identically 1. And since we know that the geometric meaning of a determinant is volume (see
New Ways to Understand Matrices (5): Volume = Determinant
), a determinant of 1 means the volume is unchanged, whereas an affine coupling layer's determinant not being 1 means the volume does change — hence "non-volume-preserving."
Randomly shuffling dimensions
In NICE, the author mixes information flow by interleaving (which is theoretically equivalent to simply reversing the original vector), as shown below (here I've redrawn it using this post's affine coupling diagrams for consistency):
 NICE mixes information thoroughly via interleaved coupling
RealNVP found that shuffling the vector randomly mixes information even more thoroughly, and yields a lower final loss, as shown below:
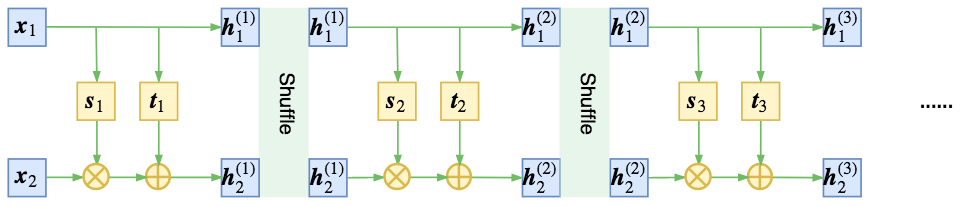 RealNVP randomly shuffles the entire output vector at each step, mixing information more thoroughly and evenly
Here, "random shuffling" means concatenating the two vectors output by each flow step $\boldsymbol{h}_1, \boldsymbol{h}_2$ into a single vector $\boldsymbol{h}$, and then randomly reordering this vector.
Introducing convolutional layers
RealNVP presents a principled way to use convolutional neural networks within flow models, which allows for much better handling of image data, reduces the parameter count, and lets the model exploit parallelism more fully.
Note, though, that convolution isn't automatically appropriate in every setting — using it presupposes that the input has local correlation (in the spatial dimensions). Images do have this property, since neighboring pixels tend to be correlated, so general image models can generally make use of convolution. But notice two operations in flow: (1) splitting the input into two parts $\boldsymbol{x}_1,\boldsymbol{x}_2$ before feeding them into the coupling layer, where the model $\boldsymbol{s},\boldsymbol{t}$ in fact only operates on $\boldsymbol{x}_1$; and (2) before feeding features into the coupling layer, we must randomly shuffle the dimensions of the original features (effectively scrambling them). Both of these operations can destroy local correlation — splitting might cut through pixels that were originally adjacent, and random shuffling could push two originally neighboring pixels far apart.
So if we still want to use convolution, we need some way to preserve this spatial local correlation. An image has three axes: height, width, and channel. The first two are spatial axes and clearly have local correlation, so the only axis we can really "mess with" is the channel axis. For this reason, RealNVP restricts the split and shuffle operations to act only along the channel axis. In other words, after splitting the input along channels into $\boldsymbol{x}_1,\boldsymbol{x}_2$, $\boldsymbol{x}_1$ still retains local correlation; and after shuffling the whole thing consistently along the channel axis, the spatial correlation is likewise preserved, so convolution can be used within the model $\boldsymbol{s},\boldsymbol{t}$.
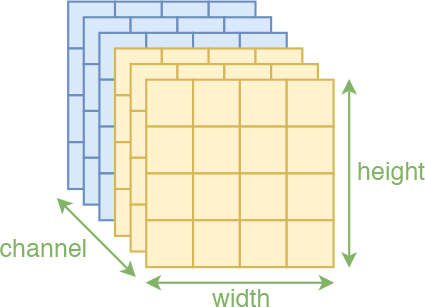 Splitting along the channel axis preserves local spatial correlation
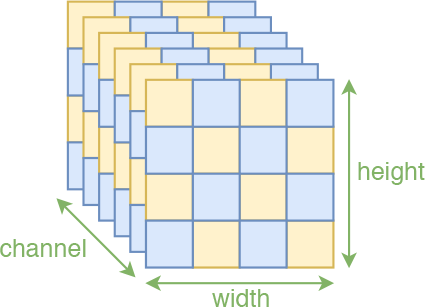 Interleaved (checkerboard) splitting along spatial axes is another way to preserve local spatial correlation
Note: in RealNVP, the operation of splitting the input into two parts is called a mask, since it's equivalent to labeling the original input with 0s and 1s. Besides the channel-wise half-split mask described above, RealNVP actually also introduces an interleaved mask along the spatial axes, shown on the right in the figure above — this is called a checkerboard mask (its pattern resembles a chessboard). This particular kind of split also preserves local spatial correlation; the original paper alternates between the two masking schemes. However, the checkerboard mask is comparatively more complex and doesn't offer any particularly noticeable improvement, so it was dropped in Glow.
But thinking it through, there's an obvious problem. Ordinary images only have three channels, and grayscale images like MNIST have just one — so how can we split that in half? And how do we shuffle it randomly? To solve this, RealNVP introduces an operation called squeeze, which gives the channel axis a higher dimensionality. The idea is simple: just reshape, but do it locally. Specifically, suppose the original image has shape $h\times w\times c$, where the first two axes are spatial. We divide it along the spatial dimensions into blocks of size $2\times 2\times c$ (this 2 can be chosen freely), and then reshape each block directly, turning it into $1\times 1\times 4c$ — meaning the final shape becomes $h/2 \times w/2 \times 4c$.
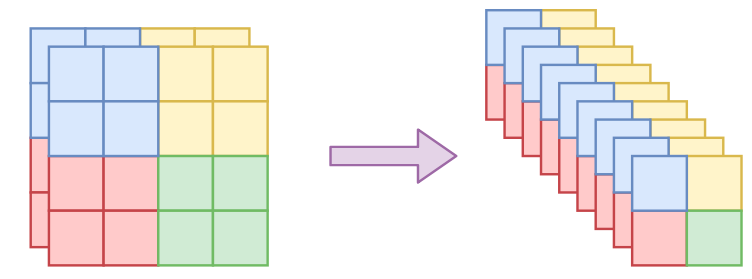 Illustration of the squeeze operation, where the 2x2 patch can be replaced by a patch of any chosen size
With the squeeze operation, we can increase the dimensionality of the channel axis while still preserving local correlation, so everything discussed above can go through as planned. This makes squeeze an indispensable operation for applying flow models to images.
Multi-scale architecture
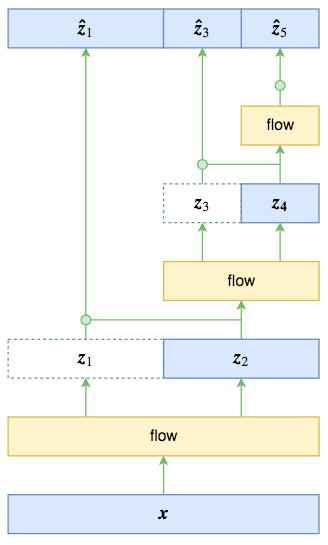 Illustration of the multi-scale architecture in RealNVP
Besides successfully introducing convolutional layers, RealNVP's other major contribution is the multi-scale architecture. Like the use of convolution, this is a strategy that both reduces model complexity and improves results.
The multi-scale structure is actually not complicated, as shown in the figure. After the original input passes through the first flow step (where "flow step" means a composition of several affine coupling layers), the output is the same size as the input. At this point we split it in half into $\boldsymbol{z}_1,\boldsymbol{z}_2$ (again along the channel axis), where $\boldsymbol{z}_1$ is output directly, and only $\boldsymbol{z}_2$ is passed on to the next flow step, and so on. In the particular example shown in the figure, the final output is composed of $\boldsymbol{z}_1,\boldsymbol{z}_3,\boldsymbol{z}_5$, whose total size matches that of the input.
The multi-scale structure has a bit of a "fractal" feel to it; the original paper says it was inspired by VGG. Each multi-scale step directly halves the size of the data, which is obviously quite significant. But there's an important detail that neither the RealNVP nor the Glow paper mentions explicitly — I only understood it after reading the source code — namely, what prior distribution should be used for the final output $[\boldsymbol{z}_1,\boldsymbol{z}_3,\boldsymbol{z}_5]$? Following the usual assumption in flow models, should we just set it to a standard normal distribution?
In fact, since these are outputs at different multi-scale positions, $\boldsymbol{z}_1,\boldsymbol{z}_3,\boldsymbol{z}_5$ are not on equal footing, and directly assigning them a single overall standard normal distribution would be forcing them to be treated as equivalent, which isn't reasonable. The better approach is to write out the conditional probability formula:
$$p(\boldsymbol{z}_1,\boldsymbol{z}_3,\boldsymbol{z}_5)=p(\boldsymbol{z}_1|\boldsymbol{z}_3,\boldsymbol{z}_5)p(\boldsymbol{z}_3|\boldsymbol{z}_5)p(\boldsymbol{z}_5)\tag{3}$$
Since $\boldsymbol{z}_3,\boldsymbol{z}_5$ is fully determined by $\boldsymbol{z}_2$, and $\boldsymbol{z}_5$ is fully determined by $\boldsymbol{z}_4$, the conditioning can be rewritten as:
$$p(\boldsymbol{z}_1,\boldsymbol{z}_3,\boldsymbol{z}_5)=p(\boldsymbol{z}_1|\boldsymbol{z}_2)p(\boldsymbol{z}_3|\boldsymbol{z}_4)p(\boldsymbol{z}_5)\tag{4}$$
RealNVP and Glow both assume the three distributions on the right-hand side are normal distributions, where the mean and variance of $p(\boldsymbol{z}_1|\boldsymbol{z}_2)$ are computed from $\boldsymbol{z}_2$ (this can be done directly via convolution, somewhat like in a VAE), the mean and variance of $p(\boldsymbol{z}_3|\boldsymbol{z}_4)$ are computed from $\boldsymbol{z}_4$, and the mean and variance of $p(\boldsymbol{z}_5)$ are learned directly.
This assumption is clearly much more effective than naively treating them all as standard normal distributions. We can also describe it another way: the above prior assumption is equivalent to performing the following change of variables
$$\boldsymbol{\hat{z}}_1=\frac{\boldsymbol{z}_1 - \boldsymbol{\mu}(\boldsymbol{z}_2)}{\boldsymbol{\sigma}(\boldsymbol{z}_2)},\quad \boldsymbol{\hat{z}}_3=\frac{\boldsymbol{z}_3 - \boldsymbol{\mu}(\boldsymbol{z}_4)}{\boldsymbol{\sigma}(\boldsymbol{z}_4)},\quad \boldsymbol{\hat{z}}_5=\frac{\boldsymbol{z}_5 - \boldsymbol{\mu}}{\boldsymbol{\sigma}}\tag{5}$$
and then assuming that $[\boldsymbol{\hat{z}}_1,\boldsymbol{\hat{z}}_3,\boldsymbol{\hat{z}}_5]$ follows a standard normal distribution. Just as with the scaling layer in NICE, these three transformations each introduce a non-unit Jacobian determinant, meaning we need to add a term of the form $\sum\limits_{i=1}^D\log \boldsymbol{\sigma}_i$ to the loss.
At first glance the multi-scale structure looks like it's purely there to reduce computation, but it's not that simple. Because flow models are invertible, the input and output dimensions must match, and this actually leads to a serious problem of "wasted" dimensions, which typically forces us to use a sufficiently complex network just to mitigate this waste. The multi-scale structure effectively abandons the direct assumption that $p(\boldsymbol{z})$ is standard normal, replacing it with a composite conditional distribution. This way, even though the total dimensionality of input and output is still the same, the outputs at different levels are no longer treated as equivalent, and the model can suppress the dimension-wasting problem by controlling the variance of each conditional distribution (in the extreme case, if the variance is 0, the Gaussian collapses into a Dirac distribution, effectively reducing the dimensionality by 1). A conditional distribution is inherently more flexible than an independent one. And purely from the perspective of the loss, the multi-scale structure acts as a powerful regularizer for the model (analogous to the multiple skip connections found in multi-layer image classification models).
Glow
Overall, Glow builds on RealNVP by introducing an invertible 1x1 convolution to replace the channel-shuffling operation mentioned earlier, and it simplifies and standardizes the original RealNVP model, making it easier to understand and use.
Glow paper: https://papers.cool/arxiv/1807.03039
Glow blog post: https://blog.openai.com/glow/
Glow source code: https://github.com/openai/glow
Invertible 1x1 convolution
This section covers Glow's main contribution: the invertible 1x1 convolution.
Permutation matrices
The invertible 1x1 convolution arises from generalizing the permutation operation. As we know, an important step in flow models is rearranging the dimensions — NICE simply reverses the order, while RealNVP shuffles them randomly. Either way, this corresponds to a permutation operation on a vector.
In fact, a permutation operation on a vector can be described by matrix multiplication. For example, suppose the original vector is $[1, 2, 3, 4]$, and after swapping the first and second entries, and the third and fourth entries, we get $[2, 1, 4, 3]$. This operation can be described by matrix multiplication:
$$\begin{pmatrix}2 \\ 1 \\ 4 \\ 3\end{pmatrix} = \begin{pmatrix}0 & 1 & 0 & 0\\ 1 & 0 & 0 & 0 \\ 0 & 0 & 0 & 1 \\ 0 & 0 & 1 & 0\end{pmatrix} \begin{pmatrix}1 \\ 2 \\ 3 \\ 4\end{pmatrix}\tag{6}$$
where the first term on the right is "the matrix obtained by repeatedly swapping rows or columns of the identity matrix," known as a permutation matrix.
Generalizing the permutation
Given this, a natural idea arises: why not replace the permutation matrix with a general, trainable parameter matrix? The so-called invertible 1x1 convolution is exactly the result of this idea.
Note that when we first laid out the design philosophy of flow models, we already stated clearly that the transformation in a flow model must satisfy two conditions: it must be invertible, and its Jacobian determinant must be easy to compute. If we simply write down the transformation
$$\boldsymbol{h}=\boldsymbol{x}\boldsymbol{W}\tag{7}$$
then this is just an ordinary fully-connected layer without a bias, and there's no guarantee it satisfies these two conditions. So we need to do some preparatory work. First, we require $\boldsymbol{h}$ and $\boldsymbol{x}$ to have the same dimension, i.e., $\boldsymbol{W}$ must be a square matrix — this is the most basic requirement. Second, since this is just a linear transformation, its Jacobian matrix is simply $\left[\frac{\partial \boldsymbol{h}}{\partial \boldsymbol{x}} \right]=\boldsymbol{W}$, so its determinant is $\det \boldsymbol{W}$, meaning we need to add the term $-\log |\det \boldsymbol{W}|$ to the loss. Finally, to guarantee that $\boldsymbol{W}$ is invertible at initialization, it is generally initialized as a "random orthogonal matrix."
Using LU decomposition
The approach above is only a very basic solution. As we know, computing the determinant of a matrix is computationally expensive and prone to overflow. Glow offers a rather clever solution here: making clever use of LU decomposition. Specifically, any matrix can be decomposed as
$$\boldsymbol{W}=\boldsymbol{P}\boldsymbol{L}\boldsymbol{U}\tag{8}$$
where $\boldsymbol{P}$ is a permutation matrix, i.e., the equivalent matrix of the shuffle operation mentioned earlier; $\boldsymbol{L}$ is a lower triangular matrix with all diagonal entries equal to 1; and $\boldsymbol{U}$ is an upper triangular matrix. This form of decomposition is called LU decomposition. Once we know this matrix representation, computing the Jacobian determinant becomes trivial — it equals
$$\log |\det \boldsymbol{W}| = \sum \log|\text{diag}(\boldsymbol{U})|\tag{9}$$
that is, the sum of the logarithms of the absolute values of the diagonal entries of $\boldsymbol{U}$. Since any matrix can be decomposed into the form of $(8)$, why not just directly parametrize $\boldsymbol{W}$ in the form of $(8)$? This way, the cost of the matrix multiplication itself doesn't increase noticeably, but the cost of computing the determinant is drastically reduced, and the computation becomes much simpler. This is exactly the trick given in Glow: first randomly generate an orthogonal matrix, then perform an LU decomposition to obtain $\boldsymbol{P},\boldsymbol{L},\boldsymbol{U}$, fix $\boldsymbol{P}$, also fix the signs of the diagonal entries of $\boldsymbol{U}$, then constrain $\boldsymbol{L}$ to be a lower triangular matrix with all-1 diagonal, and $\boldsymbol{U}$ to be upper triangular, and optimize the remaining parameters of $\boldsymbol{L},\boldsymbol{U}$ during training.
Analysis of the results
The description above is based purely on fully-connected layers. When applied to images, the same operation is carried out on each channel vector, which is equivalent to a 1x1 convolution — hence the name "invertible 1x1 convolution." Actually, I don't think this name is particularly well chosen. Fundamentally it's just a weight-shared, invertible fully-connected layer; calling it a "1x1 convolution" specifically ties it to images and makes it less general.
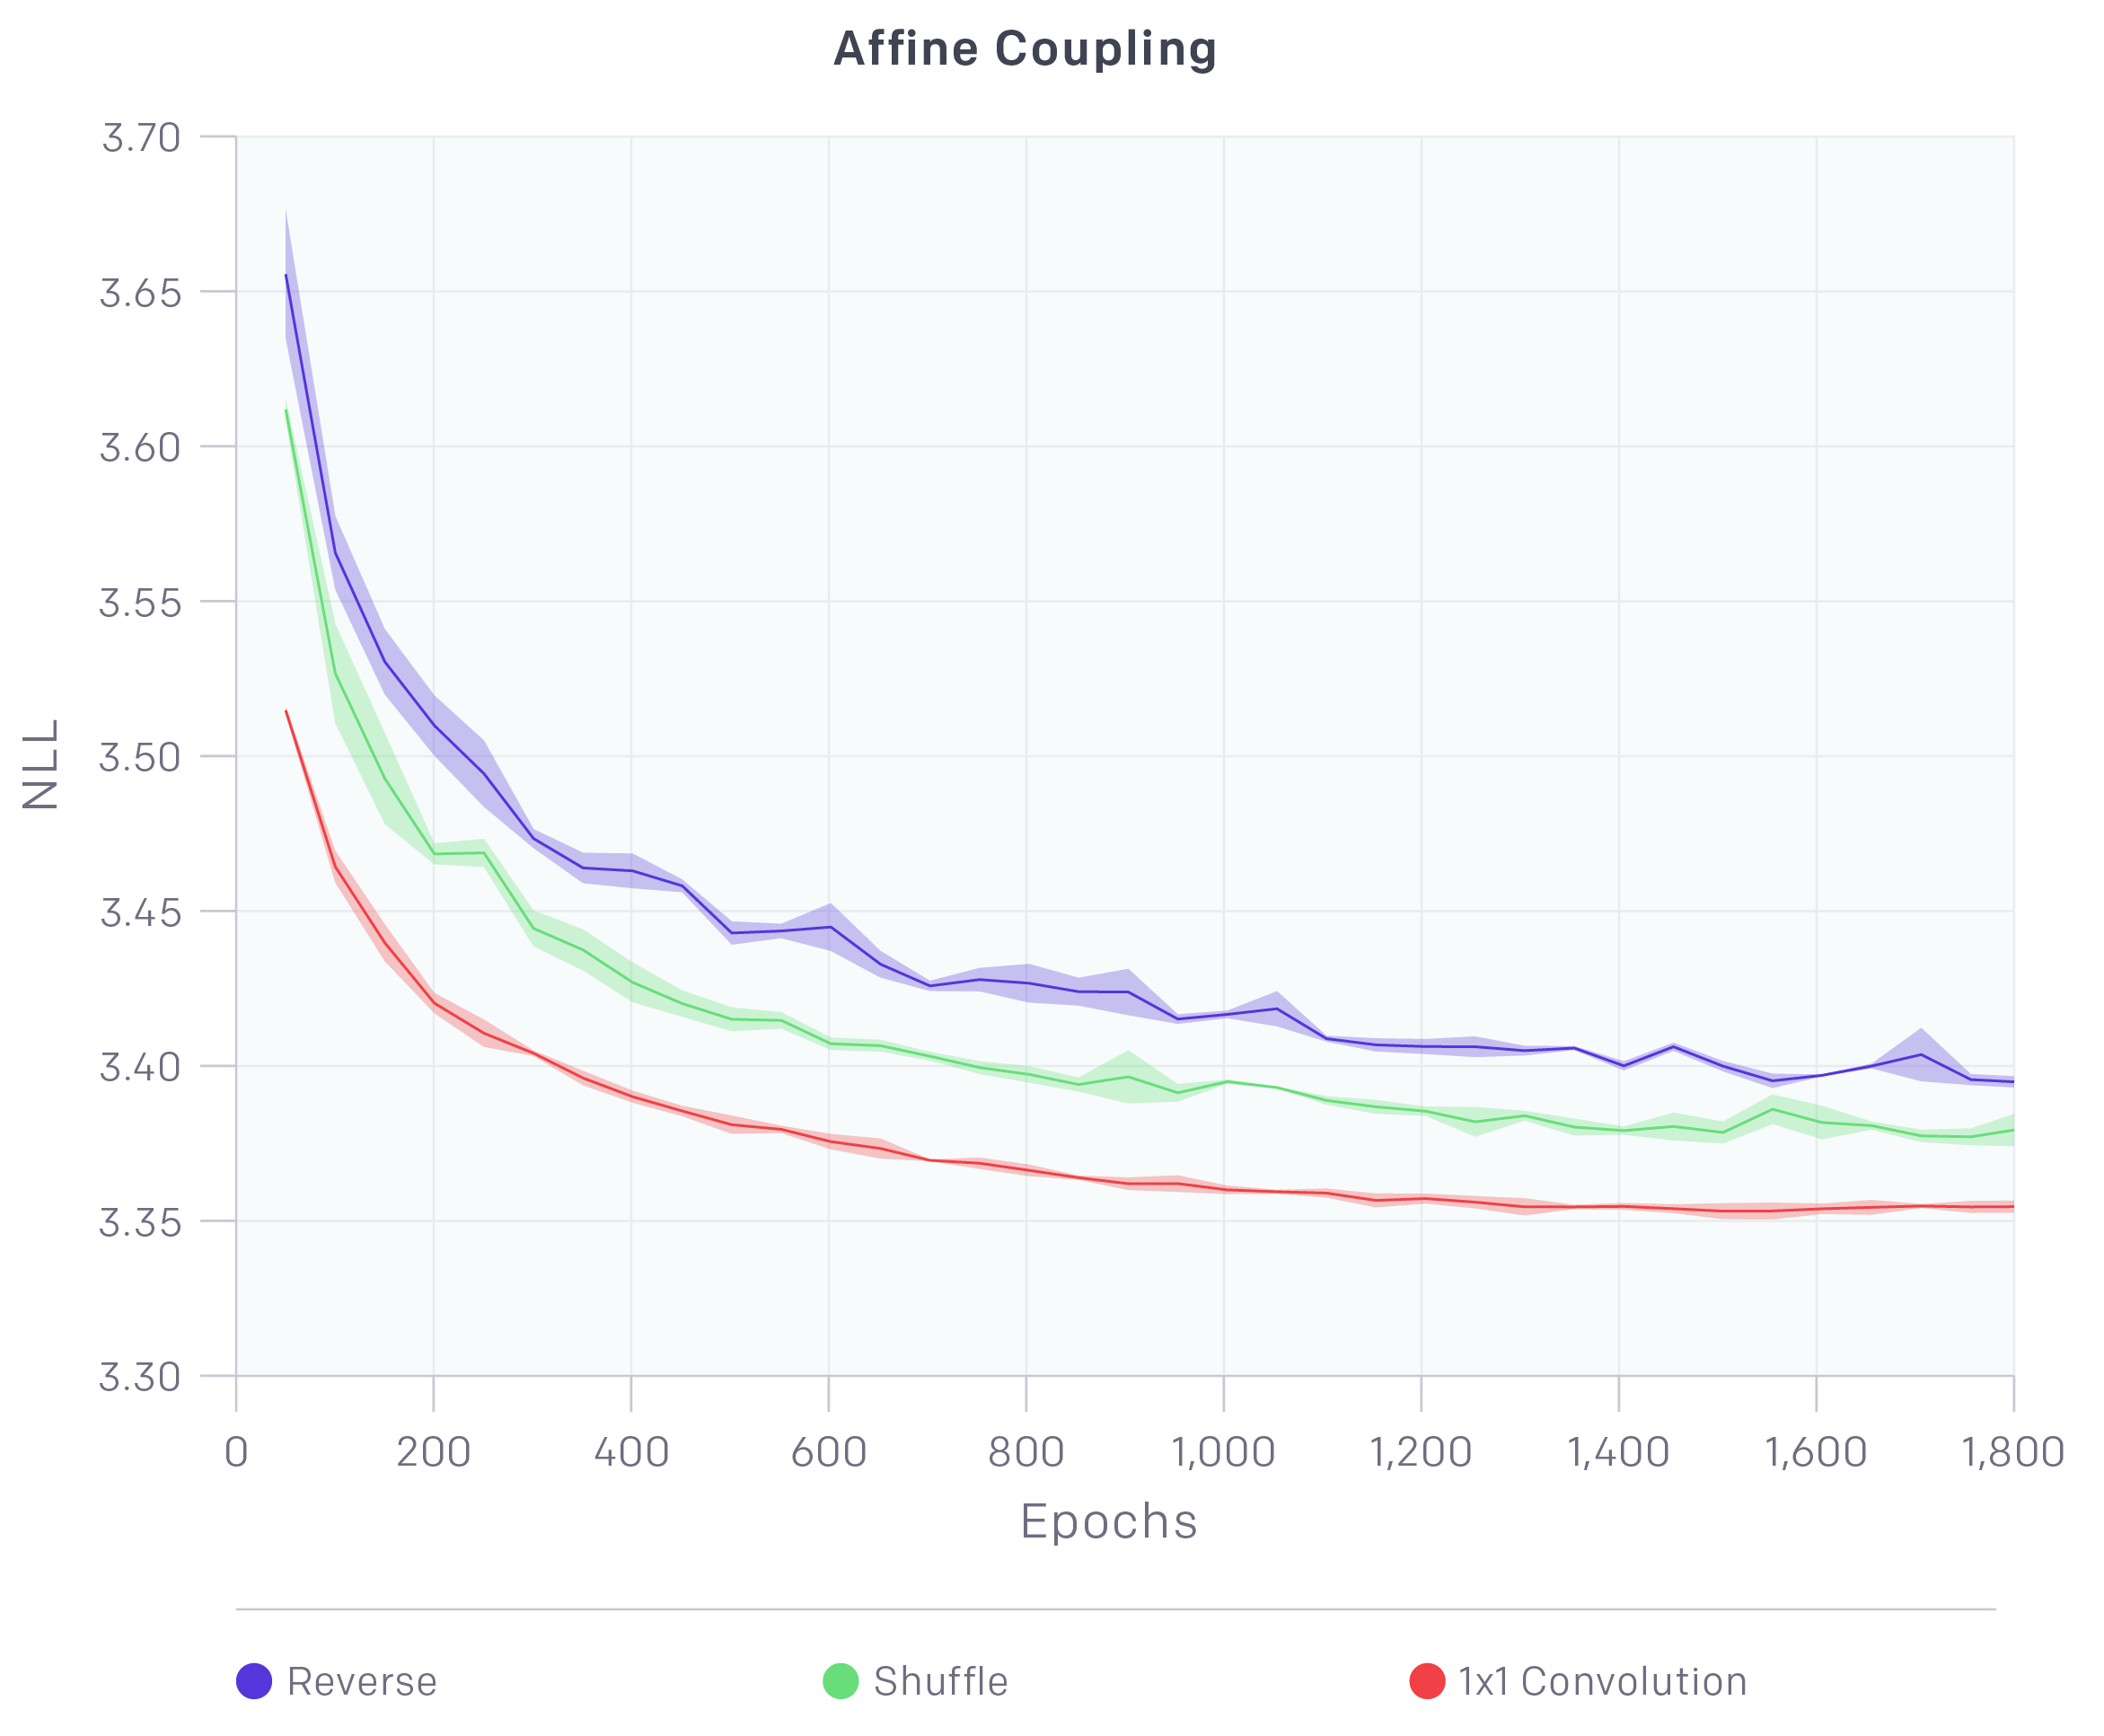 Comparison of final loss curves for three different shuffling schemes (from the OpenAI blog)
The Glow paper includes comparative experiments showing that, compared to plain reversal, shuffling achieves a lower loss, and compared to shuffling, the invertible 1x1 convolution achieves an even lower loss. My own experiments confirm this as well.
However, it should be pointed out that although the invertible 1x1 convolution can lower the loss, there are some caveats. First, a lower loss doesn't necessarily mean better generation quality. For example, if model A uses shuffling and reaches loss = -50000 after 200 epochs, while model B uses the invertible convolution and reaches loss = -55000 after only 150 epochs, then in general, at this point model B's actual results may still be no better than model A's (assuming neither has reached its optimum yet). In fact, the invertible 1x1 convolution can only guarantee that model B will be better once both models are trained to their optimum. Second, in my own simple experiments, it seems that the number of epochs needed to reach saturation with the invertible 1x1 convolution is much greater than with plain shuffling.
Actnorm
RealNVP used a BN layer, whereas Glow proposes a layer called Actnorm to replace BN. However, this so-called Actnorm layer is in fact nothing more than a generalization of the scaling layer used in NICE, i.e., the scale-and-shift transformation mentioned in equation $(5)$:
$$\boldsymbol{\hat{z}}=\frac{\boldsymbol{z} - \boldsymbol{\mu}}{\boldsymbol{\sigma}}\tag{10}$$
where $\boldsymbol{\mu},\boldsymbol{\sigma}$ are all trainable parameters. The innovation Glow's paper claims is to initialize the two parameters $\boldsymbol{\mu},\boldsymbol{\sigma}$ using the mean and variance of the initial batch, but in fact the released source code does not do this at all — it's purely zero-initialized.
So this point deserves some criticism — it's purely a case of putting a new name on an old concept. Of course, the criticism here is directed at OpenAI's habit of coining new concepts in Glow, not at the effectiveness of the layer itself. Adding the scale-and-shift does indeed help train the model better. Moreover, because of Actnorm, the scale transformation in the affine coupling layer becomes somewhat less important. As we've seen, compared to the additive coupling layer, the affine coupling layer adds an extra scale transformation, doubling the computation. But in practice, the improvement from affine coupling over additive coupling is not that large (especially once Actnorm is added), so for training large models, in order to save resources, additive coupling alone is typically used — for instance, Glow's 256x256 high-resolution face generation model uses only additive coupling.
Source code analysis
At this point there's not much left in Glow that requires special explanation. But Glow's overall model structure is quite well organized, so let's break it down step by step to provide a reference for building similar models ourselves. This section is based on my reading of the Glow source code, and is presented mainly through diagrams.
Overall model diagram
Overall, the Glow model isn't complicated — it adds a certain amount of noise to the input, feeds it into an encoder, and finally uses "the mean sum of squares of the output" as the loss function (the log Jacobian determinant produced within the model can be regarded as a regularization term). Note that the loss is not "mean squared error (MSE)" — it's simply the sum of squares of the output, i.e., there's no subtraction of the input involved.
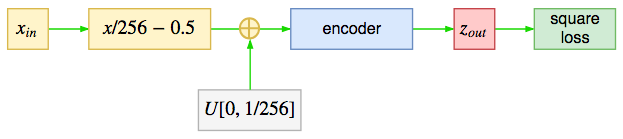 Overall diagram of the Glow model
encoder
Let's break down the encoder from the overall diagram; the general flow is as follows:
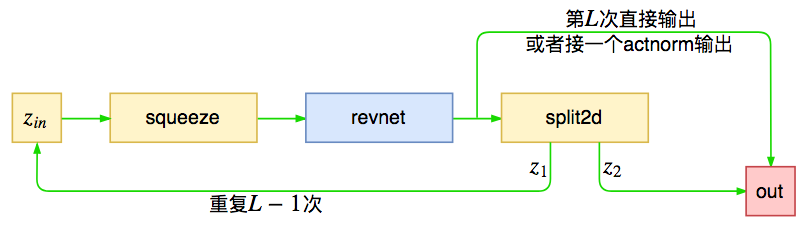 Encoder flow diagram
The encoder consists of $L$ modules, which are named "revnet" in the source code. Each module processes the input, then splits the output in half — one half is passed to the next module, and the other half is output directly. This is exactly the multi-scale structure mentioned earlier. Glow's source code uses $L=3$ by default, but for 256x256 face generation, $L=6$ is used instead.
revnet
Now let's further break down the revnet part of the encoder:
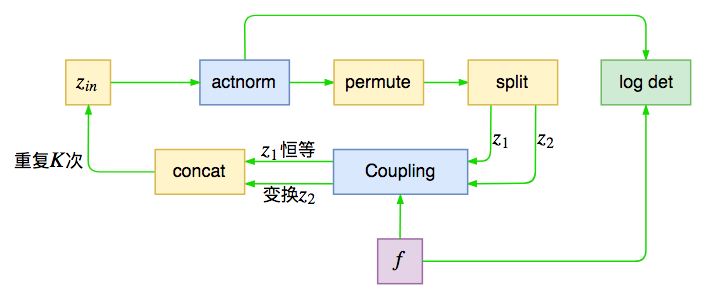 Revnet structure diagram
This is essentially the single-step flow operation described earlier: the input undergoes a scale transformation, then the axes are shuffled, then the input is split, and finally fed into the coupling layer. This is repeated $K$ times, where $K$ is called the "depth" — the default in Glow is 32. Here, both actnorm and the affine coupling layer contribute non-unit Jacobian determinants, meaning they modify the loss, which is also annotated in the diagram.
split2d
The split2d defined in Glow is not simply a splitting operation — it also incorporates a transformation on the split-off portion, which corresponds to the choice of prior distribution for the multi-scale output mentioned earlier.
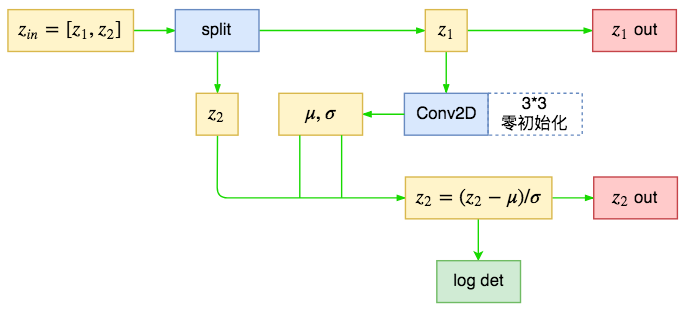 split2d in Glow is not a simple split
Comparing $(5)$ and $(10)$, we can see that the conditional prior distribution differs from Actnorm only in the source of the scale-and-shift quantities: for Actnorm, the scale-and-shift parameters are optimized directly, whereas for the prior distribution here, the scale-and-shift quantities are computed by another part of the network via some model. In effect, this can be regarded as a kind of conditional Actnorm (Cond Actnorm).
f
Finally, there's the model for the transformation inside Glow's coupling layer (the $\boldsymbol{s},\boldsymbol{t}$ of the affine coupling layer), directly named f in the source code. It uses three ReLU convolutional layers:
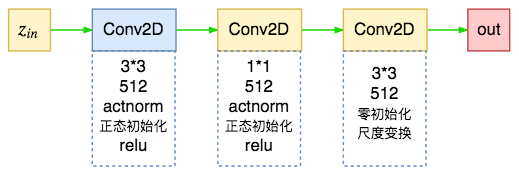 The transformation model for the coupling layer in Glow
The last layer is zero-initialized, so that at initialization the input and output are identical — i.e., the initial state is an identity transformation, which helps in training deep networks.
Reimplementation
As we can see, RealNVP already did most of the heavy lifting, and Glow refines RealNVP by trimming the fat and adding its own small modifications (the invertible 1x1 convolution) along with some standardization. Regardless, this is a model well worth studying.
Keras version
The officially open-sourced Glow is a TensorFlow implementation. Such an interesting model surely deserves a Keras version too — here's my own Keras implementation:
https://github.com/bojone/flow/blob/master/glow.py
(I've already submitted a pull request to Keras's official examples repository — hopefully it will show up on Keras's GitHub in a few days.)
Due to limitations of certain functions, it currently only supports the TensorFlow backend. My testing environments include Keras 2.1.5 + TensorFlow 1.2, and Keras 2.2.0 + TensorFlow 1.8, both tested under Python 2.7.
Testing the results
When I first read about Glow, I was quite excited, as if I'd discovered a new continent. After some study, I found... that Glow really is a new continent, but not one that ordinary folks like myself can easily set foot on.
Take a look at these two issues on Glow's GitHub repo:
How many epochs will it take when training on CelebA?
The samples we show in the paper are after about 4000 training epochs...
Has anyone reproduced the CelebA-HQ results in the paper?
Yes we trained with 40 GPUs for about a week, but samples did start to look good after a couple of days...
So, generating 256x256 high-resolution face images requires 4000 epochs of training, using 40 GPUs for a week — in simpler terms, that's like training on a single GPU for a year... (RIP.)
Well, I might as well give up on this unreachable goal. Let's just play around with a simple 64x64 — actually, let's make it 32x32 — face generation task and produce a demo.
 32x32 faces generated by the Glow model, 150 epochs
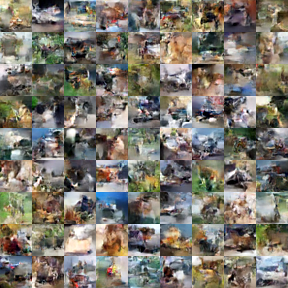 CIFAR-10 generated by the Glow model, 700 epochs
Not bad, I'd say. I used $L=3,K=6$, and each epoch took about 70 seconds (on a GTX 1070). I ran it for 150 epochs — note that "epoch" here doesn't match the usual meaning of the term; my "epoch" here refers to a random draw of 32,000 samples. If I ran through the full dataset every epoch, it would take much longer... With the same model, I also gave CIFAR-10 a try, running it for 700 epochs, but the results weren't great — it looks OK from a distance, but up close it's just noise.
Of course, although CIFAR-10 is small (32x32), generating it is actually much harder than generating faces (regardless of which generative model is used), so let's just skip past that. As for 64x64 faces, I gave that a shot too, foolishly, using $L=3,K=10$ and running for 200 epochs (each epoch now took 6 minutes). The result...
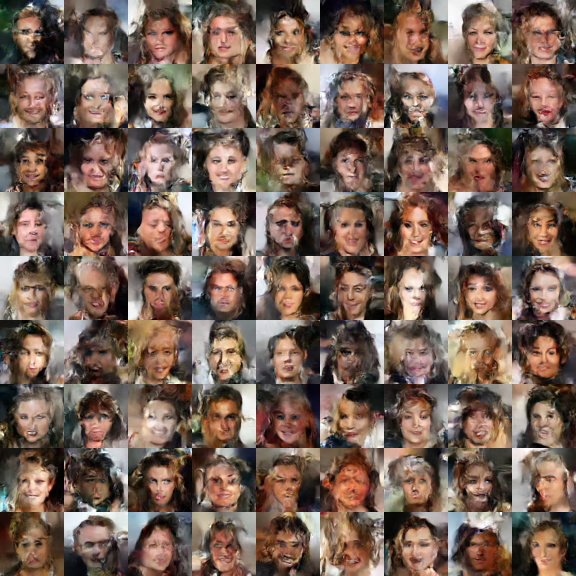 64x64 faces generated by the Glow model, 230 epochs
They're faces, all right, but they look more like demon faces... (It seems the network depth and number of epochs are still insufficient, and I couldn't keep going any longer.)
The annealing parameter also turns out to matter quite a bit. After changing the annealing parameter to 0.8, the same model produces:
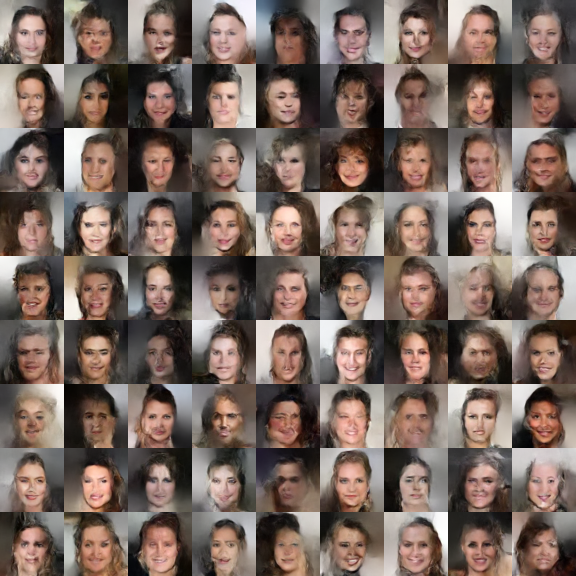 Same model, annealing parameter set to 0.8
Still a bit distorted, but it looks much better.
A hard-won conclusion
Well, this finally brings my introduction to RealNVP and Glow to a close. Out of genuine interest in Glow, I've spent two posts working through all three flow models, and I hope readers have found it useful.
Overall, flow models like Glow really are elegant in design, but the computational cost is still on the high side, and training takes far too long — they're nowhere near as friendly to work with as GANs typically are. Personally, I think flow models still have quite a way to go before they can find solid footing in a generative-model landscape currently dominated by GANs. There's a long road ahead.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.