A Concise Introduction to Conditional Random Fields (CRF), with a Pure Keras Implementation
Last year I wrote a post, CRF In A Nutshell, giving a somewhat rough introduction to the Conditional Random Field (CRF) model. However, that post clearly had a lot of shortcomings — the explanation wasn't very clear or complete, and there was no implementation. Here we revisit this model and fill in the missing pieces.
This post is a concise introduction to the basic principles of CRF. Of course, "concise" is relative — to really understand CRF, we can't avoid some formulas. Readers who only care about how to use it can jump straight to the end.
A Picture Is Worth a Thousand Words
Following the same approach as before, let's compare plain frame-wise softmax with CRF.
Frame-wise softmax
CRF is mainly used for sequence labeling problems, which can be simply understood as classifying every frame in a sequence. Since it's a classification problem, a natural idea is to encode the sequence with a CNN or RNN, then attach a fully connected layer with softmax activation, as shown below:
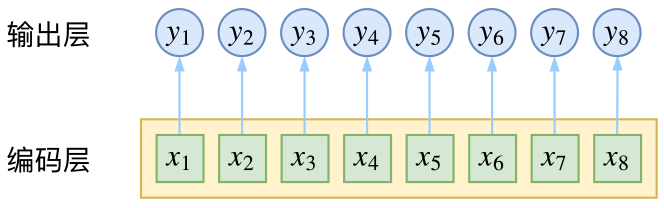 Frame-wise softmax doesn't directly account for contextual dependencies between outputs
Conditional Random Fields
However, when we design the labels — for instance, using the four tags s, b, m, e for character-based word segmentation — the target output sequence itself carries some contextual dependency: for example, s cannot be followed by m or e, and so on. Frame-wise softmax doesn't take this kind of output-level contextual dependency into account, which means these dependencies get pushed onto the encoding layer, and the model is expected to learn them on its own — but sometimes this is asking too much of the model.
CRF is more direct about this: it separates out the output-level dependencies, which lets the model learn more "at ease":
 CRF explicitly accounts for contextual dependencies at the output
The Math
Of course, if all we did was introduce dependencies between outputs, that wouldn't be the whole story of CRF. What's truly elegant about CRF is that it treats the path as the basic unit, and considers the probability of the path itself.
Model Overview
Suppose an input has $n$ frames, and each frame's label has $k$ possible values; then in theory there are $k^n$ different possible outputs. We can visualize this with a simple network diagram. In the figure below, each node represents a possible label, the edges between nodes represent dependencies between labels, and each labeling result corresponds to a complete path through the graph.
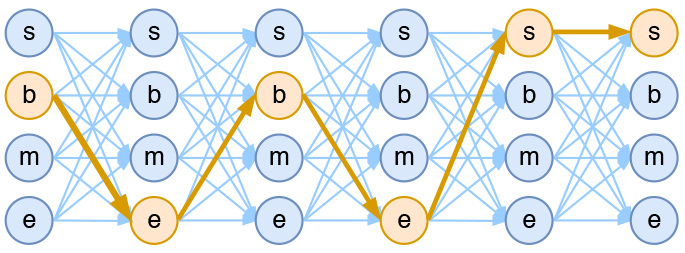 Output network diagram for a 4-tag word segmentation model
In a sequence labeling task, the correct answer is generally unique. For instance, for "今天天气不错" (today the weather is good), if the segmentation result is "今天/天气/不/错", then the target output sequence is bebess, and no other path satisfies the requirement. In other words, in sequence labeling tasks, the basic unit of study should be the path — what we need to do is pick the correct path out of $k^n$ possible paths, which means that, viewed as a classification problem, it's a classification problem of choosing one class out of $k^n$ classes!
This is the fundamental difference between frame-wise softmax and CRF: the former treats sequence labeling as $n$ separate $k$-class classification problems, while the latter treats sequence labeling as a single $1$-class classification problem over $k^n$ possibilities.
Specifically, in the CRF formulation of sequence labeling, what we want to compute is the conditional probability
$$P(y_1,\dots,y_n|x_1,\dots,x_n)=P(y_1,\dots,y_n|\boldsymbol{x}),\quad \boldsymbol{x}=(x_1,\dots,x_n)\tag{1}$$
To estimate this probability, CRF makes two assumptions:
Assumption 1: The distribution is an exponential family distribution.
This assumption implies that there exists a function $f(y_1,\dots,y_n;\boldsymbol{x})$ such that
$$P(y_1,\dots,y_n|\boldsymbol{x})=\frac{1}{Z(\boldsymbol{x})}\exp\Big(f(y_1,\dots,y_n;\boldsymbol{x})\Big)\tag{2}$$
where $Z(\boldsymbol{x})$ is the normalization factor; since this is a conditional distribution, the normalization factor depends on $\boldsymbol{x}$. This function $f$ can be thought of as a scoring function — exponentiating the score and normalizing it yields a probability distribution.
Assumption 2: Dependencies between outputs only occur between adjacent positions, and these dependencies are additive in the exponent.
This assumption means that $f(y_1,\dots,y_n;\boldsymbol{x})$ can be further simplified to
$$\begin{aligned}f(y_1,\dots,y_n;\boldsymbol{x})=&h(y_1;\boldsymbol{x})+g(y_1,y_2;\boldsymbol{x})+h(y_2;\boldsymbol{x})+g(y_2,y_3;\boldsymbol{x})+h(y_3;\boldsymbol{x})\\ &+\dots+g(y_{n-1},y_n;\boldsymbol{x})+h(y_n;\boldsymbol{x})\end{aligned}\tag{3}$$
In other words, we now only need to score each label and each pair of adjacent labels separately, then sum all the scores to get the total score.
Linear-Chain CRF
Even after all this simplification, in general the probability model represented by equation $(3)$ is still too complex to solve directly. Given that current deep learning models — RNNs or stacked CNNs, for instance — are already fairly good at capturing the relationship between each $y$ and the input $\boldsymbol{x}$, we might as well assume that the function $g$ is independent of $\boldsymbol{x}$, giving us
$$\begin{aligned}f(y_1,\dots,y_n;\boldsymbol{x})=h(y_1;\boldsymbol{x})+&g(y_1,y_2)+h(y_2;\boldsymbol{x})+\dots\\ +&g(y_{n-1},y_n)+h(y_n;\boldsymbol{x})\end{aligned}\tag{4}$$
In this case $g$ is really just a finite trainable parameter matrix, while the single-label scoring function $h(y_i;\boldsymbol{x})$ can be modeled by an RNN or CNN. Hence this model is tractable, with the probability distribution becoming
$$P(y_1,\dots,y_n|\boldsymbol{x})=\frac{1}{Z(\boldsymbol{x})}\exp\left(h(y_1;\boldsymbol{x})+\sum_{t=1}^{n-1}\Big[g(y_t,y_{t+1})+h(y_{t+1};\boldsymbol{x})\Big]\right)\tag{5}$$
This is the concept of the linear-chain CRF.
The Normalization Factor
To train the CRF model, we use maximum likelihood, i.e. we use
$$-\log P(y_1,\dots,y_n|\boldsymbol{x})\tag{6}$$
as the loss function, which can be computed as
$$-\left(h(y_1;\boldsymbol{x})+\sum_{t=1}^{n-1}\Big[g(y_t,y_{t+1})+h(y_{t+1};\boldsymbol{x})\Big]\right)+\log Z(\boldsymbol{x})\tag{7}$$
The first term here is the log of the numerator of the original probability expression — the score of the target sequence. Although it looks a bit roundabout, it's not hard to compute. The real difficulty lies in the log of the denominator, the term $\log Z(\boldsymbol{x})$.
The normalization factor, also known in physics as the partition function, requires us to sum the exponentiated scores over all possible paths. As noted earlier, the number of such paths grows exponentially ($k^n$), so computing it directly is essentially infeasible.
In fact, the intractability of the normalization factor is a common headache for almost all probabilistic graphical models. Fortunately, in the CRF model, because we only consider dependencies between neighboring labels (the Markov assumption), we can compute the normalization factor recursively, reducing what was originally an exponential computation to a linear one. Specifically, let's denote the normalization factor computed up to time $t$ as $Z_t$, and split it into $k$ parts:
$$Z_t = Z^{(1)}_t + Z^{(2)}_t + \dots + Z^{(k)}_t\tag{8}$$
where $Z^{(1)}_t,\dots,Z^{(k)}_t$ is the exponential sum of scores over all paths up to the current time $t$ that end at label $1,\dots,k$. Then we can compute recursively:
$$\begin{aligned}Z^{(1)}_{t+1} = &\Big(Z^{(1)}_t G_{11} + Z^{(2)}_t G_{21} + \dots + Z^{(k)}_t G_{k1} \Big) H_{t+1}(1|\boldsymbol{x})\\ Z^{(2)}_{t+1} = &\Big(Z^{(1)}_t G_{12} + Z^{(2)}_t G_{22} + \dots + Z^{(k)}_t G_{k2} \Big) H_{t+1}(2|\boldsymbol{x})\\ &\qquad\qquad\vdots\\ Z^{(k)}_{t+1} =& \Big(Z^{(1)}_t G_{1k} + Z^{(2)}_t G_{2k} + \dots + Z^{(k)}_t G_{kk} \Big) H_{t+1}(k|\boldsymbol{x}) \end{aligned}\tag{9}$$
which can be written compactly in matrix form as
$$\boldsymbol{Z}_{t+1} = \boldsymbol{Z}_{t} \boldsymbol{G}\otimes H(y_{t+1}|\boldsymbol{x})\tag{10}$$
where $\boldsymbol{Z}_{t}=\Big[Z^{(1)}_t,\dots,Z^{(k)}_t\Big]$; and $\boldsymbol{G}$ is the matrix obtained by exponentiating each element of the matrix $g$ (as mentioned earlier, in the simplest case $g$ is just a matrix representing the score of transitioning from one label to another), i.e. $\boldsymbol{G}_{ij}=e^{g_{ij}}$; and $H(y_{t+1}|\boldsymbol{x})$ is the exponential of the scores that the encoding model $h(y_{t+1}|\boldsymbol{x})$ (RNN, CNN, etc.) assigns to each label at position $t+1$, i.e. $H(y_{t+1}|\boldsymbol{x})=e^{h(y_{t+1}|\boldsymbol{x})}$, which is also a vector. In equation $(10)$, the step $\boldsymbol{Z}_{t} \boldsymbol{G}$ is matrix multiplication yielding a vector, while $\otimes$ denotes element-wise multiplication of two vectors.
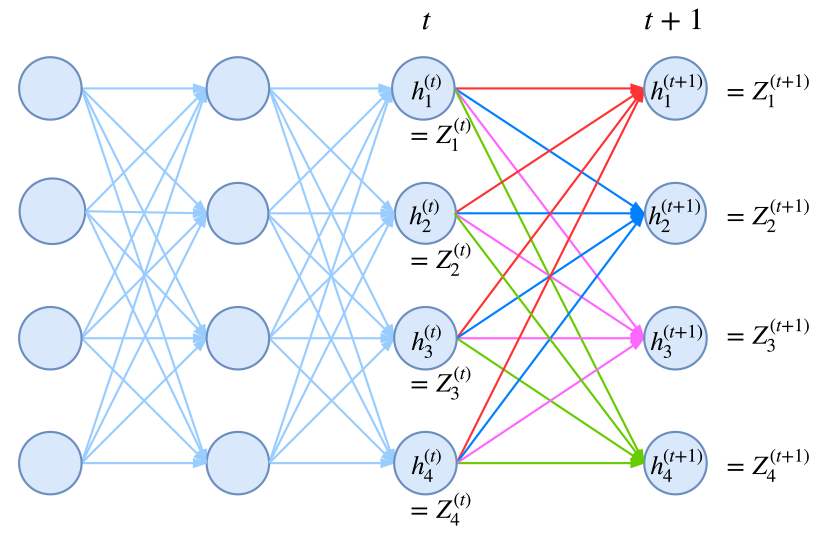 Illustration of the recursive computation of the normalization factor. The computation from time t to t+1 includes the transition probabilities and the probability of node j+1 itself
Readers unfamiliar with this may find equation $(10)$ a bit hard to swallow at first. Try writing out the normalization factor for $n=1,n=2,n=3$ explicitly and looking for the recursive relationship — with a bit of patience, equation $(10)$ should become clear.
Dynamic Programming
Once we've written down the loss function $-\log P(y_1,\dots,y_n|\boldsymbol{x})$, we can train the model, since modern deep learning frameworks all come with automatic differentiation — as long as we can write a differentiable loss, the framework will handle the optimization for us.
The last remaining step, then, is: once the model is trained, how do we find the optimal path given an input? Just as before, this is a problem of choosing the best path out of $k^n$ possibilities, and again, thanks to the Markov assumption, it can be converted into a dynamic programming problem, solved with the Viterbi algorithm, with computational cost proportional to $n$.
Dynamic programming has come up many times on this blog already. Its recursive idea is: if you cut an optimal path into two segments, each segment is itself a (locally) optimal path. Type "dynamic programming" into the search box on the right side of this blog and you'll find plenty of related introductions, so I won't repeat them here.
Implementation
After some tweaking, I've arrived at a concise implementation of the linear-chain CRF under the Keras framework — this might be the shortest CRF implementation out there. Below I share the final implementation and explain the key points.
Key Implementation Points
As explained above, the difficulty in implementing CRF lies in computing $-\log P(y_1,\dots,y_n|\boldsymbol{x})$, and the essential difficulty is computing the normalization factor part, $Z(\boldsymbol{x})$. Thanks to the Markov assumption, we arrive at the recursive equations $(9)$ or $(10)$, which should already represent the general way of computing $Z(\boldsymbol{x})$.
So how do we implement this kind of recursive computation in a deep learning framework? Note that, from the computation-graph perspective, this defines a graph via recursion, and the length of this graph is not fixed. This should pose no difficulty for a dynamic-graph framework like PyTorch, but it's quite tricky for TensorFlow or Keras-on-TensorFlow, since they're static-graph frameworks.
That said, it's not impossible — we can use the built-in RNN function to compute it! As we know, an RNN is essentially performing the recursive computation
$$\boldsymbol{h}_{t+1} = f(\boldsymbol{x}_{t+1}, \boldsymbol{h}_{t})\tag{11}$$
Newer versions of TensorFlow and Keras both allow us to define custom RNN cells, which means we can define the function $f$ ourselves, and the backend will automatically handle the recursion for us. So all we need to do is design an RNN such that the quantity we want to compute, $\boldsymbol{Z}$, corresponds to the RNN's hidden state!
This is the most elegant part of the CRF implementation.
As for the rest, these are some details, including:
1. To avoid numerical overflow, we usually need to work in log space, but since the normalization factor is an exponential sum, we end up with expressions of the form $\log\left(\sum_{i=1}^k e^{a_i}\right)$. The trick for computing this is:
$$\log\left(\sum_{i=1}^k e^{a_i}\right)=A + \log\left(\sum_{i=1}^k e^{a_i-A}\right),\quad A = \max \{a_1,\dots,a_k\}$$
Both TensorFlow and Keras already have a built-in logsumexp function for this, so we can just call it directly.
2. As for computing the numerator (i.e., the score of the target sequence), the trick is commented in the code — it's mainly done by dot-multiplying the "target sequence" with the "predicted sequence" to extract the target score.
3. How to mask the padding portion for variable-length inputs? I don't think Keras handles this very elegantly. To implement this masking simply, my approach is to introduce one extra label — for example, if the original labels for segmentation are s, b, m, e, we introduce a fifth label, say x, and set the label of all padding positions to x. Then, when computing the CRF loss, we can simply ignore the existence of this fifth label. See the code for the specific implementation.
A Quick Look at the Code
Here's the pure-Keras CRF layer implementation — feel free to use it:
# -*- coding:utf-8 -*-

from keras.layers import Layer
import keras.backend as K

class CRF(Layer):
    """纯Keras实现CRF层
    CRF层本质上是一个带训练参数的loss计算层,因此CRF层只用来训练模型,
    而预测则需要另外建立模型。
    """
    def __init__(self, ignore_last_label=False, **kwargs):
        """ignore_last_label:定义要不要忽略最后一个标签,起到mask的效果
        """
        self.ignore_last_label = 1 if ignore_last_label else 0
        super(CRF, self).__init__(**kwargs)

    def build(self, input_shape):
        self.num_labels = input_shape[-1] - self.ignore_last_label
        self.trans = self.add_weight(name='crf_trans',
                                     shape=(self.num_labels, self.num_labels),
                                     initializer='glorot_uniform',
                                     trainable=True)

    def log_norm_step(self, inputs, states):
        """递归计算归一化因子
        要点:1、递归计算;2、用logsumexp避免溢出。
        技巧:通过expand_dims来对齐张量。
        """
        inputs, mask = inputs[:, :-1], inputs[:, -1:]
        states = K.expand_dims(states[0], 2)  # (batch_size, output_dim, 1)
        trans = K.expand_dims(self.trans, 0)  # (1, output_dim, output_dim)
        outputs = K.logsumexp(states + trans, 1)  # (batch_size, output_dim)
        outputs = outputs + inputs
        outputs = mask * outputs + (1 - mask) * states[:, :, 0]
        return outputs, [outputs]

    def path_score(self, inputs, labels):
        """计算目标路径的相对概率(还没有归一化)
        要点:逐标签得分,加上转移概率得分。
        技巧:用“预测”点乘“目标”的方法抽取出目标路径的得分。
        """
        point_score = K.sum(K.sum(inputs * labels, 2), 1, keepdims=True)  # 逐标签得分
        labels1 = K.expand_dims(labels[:, :-1], 3)
        labels2 = K.expand_dims(labels[:, 1:], 2)
        labels = labels1 * labels2  # 两个错位labels,负责从转移矩阵中抽取目标转移得分
        trans = K.expand_dims(K.expand_dims(self.trans, 0), 0)
        trans_score = K.sum(K.sum(trans * labels, [2, 3]), 1, keepdims=True)
        return point_score + trans_score  # 两部分得分之和

    def call(self, inputs):  # CRF本身不改变输出,它只是一个loss
        return inputs

    def loss(self, y_true, y_pred):  # 目标y_pred需要是one hot形式
        if self.ignore_last_label:
            mask = 1 - y_true[:, :, -1:]
        else:
            mask = K.ones_like(y_pred[:, :, :1])
        y_true, y_pred = y_true[:, :, :self.num_labels], y_pred[:, :, :self.num_labels]
        path_score = self.path_score(y_pred, y_true)  # 计算分子(对数)
        init_states = [y_pred[:, 0]]  # 初始状态
        y_pred = K.concatenate([y_pred, mask])
        log_norm, _, _ = K.rnn(self.log_norm_step, y_pred[:, 1:], init_states)  # 计算Z向量(对数)
        log_norm = K.logsumexp(log_norm, 1, keepdims=True)  # 计算Z(对数)
        return log_norm - path_score  # 即log(分子/分母)

    def accuracy(self, y_true, y_pred):  # 训练过程中显示逐帧准确率的函数,排除了mask的影响
        mask = 1 - y_true[:, :, -1] if self.ignore_last_label else None
        y_true, y_pred = y_true[:, :, :self.num_labels], y_pred[:, :, :self.num_labels]
        isequal = K.equal(K.argmax(y_true, 2), K.argmax(y_pred, 2))
        isequal = K.cast(isequal, 'float32')
        if mask == None:
            return K.mean(isequal)
        else:
            return K.sum(isequal * mask) / K.sum(mask)
Excluding comments and the accuracy-computation code, the actual CRF code is only about 30 lines — I'd say this counts as a concise CRF implementation by any framework's standards.
Implementing complex models purely in Keras is a rather interesting exercise. So far it's only been tested on the TensorFlow backend; in principle it should be compatible with the Theano and CNTK backends, though some manual tweaking might be needed.
Example Usage
My GitHub repo also includes an example of Chinese word segmentation implemented with CNN+CRF, using the Bakeoff 2005 corpus. The example is a complete word segmentation implementation, including the Viterbi algorithm, segmentation output, and so on.
GitHub link: https://github.com/bojone/crf/
You may also find these related earlier posts of mine useful:
1. Chinese Word Segmentation Series 4: Sequence-to-sequence character tagging based on bidirectional LSTM
2. Chinese Word Segmentation Series 6: Chinese word segmentation based on fully convolutional networks
Conclusion
That wraps up the introduction. I hope you found it useful, and I hope the final implementation helps you in your own work.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.