Three Flavors of Capsules: Matrix Capsules with EM Routing
As it happens, not long after the paper Dynamic Routing Between Capsules was released, a new capsule paper, Matrix Capsules with EM Routing, had already been made public anonymously (under the anonymous review process of ICLR 2018). The authors are now known: Geoffrey Hinton, Sara Sabour, and Nicholas Frosst. As you might expect, Hinton is indeed one of the authors.
As everyone knows, when "founding father"-level figures like Hinton publish something, it tends to be fairly heavyweight. So what's distinctive about this new paper?
In the course of working through this, the article Understanding Matrix Capsules with EM Routing gave me a great deal of insight, and the related discussions among various experts on Zhihu also sped up my reading. My thanks to them here.
Paper abstract
Let's first recall the diagram from the previous post, One More New Year's Feast: From K-Means to Capsules:
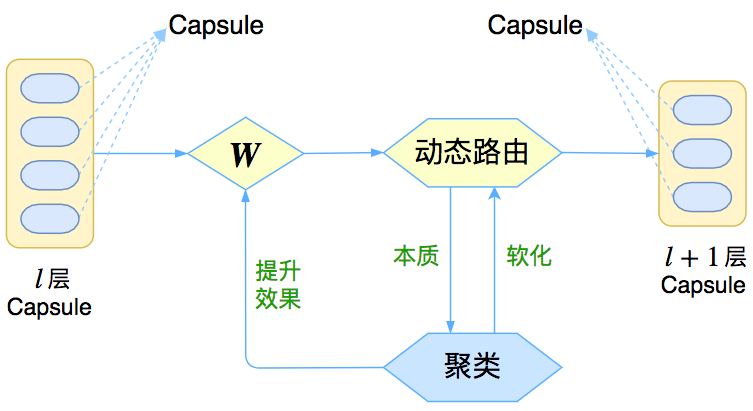 Schematic diagram of the Capsule framework
This diagram shows that Capsules essentially describe a modeling framework, within which many components can be customized—most obviously the clustering algorithm; you could say "there are as many kinds of dynamic routing as there are clustering algorithms." So what did Hinton change this time? In short, this new paper introduces the following new elements:
1. Capsules were originally represented by vectors; now they are represented by matrices;
2. The clustering algorithm has been replaced with a GMM (Gaussian Mixture Model);
3. In the experimental section, a Capsule version of convolution is implemented.
A wave of questions
Given the three points above, readers will naturally have a lot of thoughts and questions, such as:
Vector vs. matrix
What's the difference between a matrix and a vector? Can't a matrix be flattened into a vector anyway?
There is actually a bit of a difference. Take, for example, a $4\times 4$ matrix versus a 16-dimensional vector—what's the difference? The answer is that in a matrix, elements at different positions carry different importance, whereas in a vector, every element is equally important. Readers familiar with linear algebra will also sense that the diagonal elements of a matrix "seem" to carry more weight than the other elements. From a computational standpoint, we can also see the difference: to transform a 16-dimensional vector into another 16-dimensional vector, we need a $16\times 16$ transformation matrix; but to transform a $4\times 4$ matrix into another $4\times 4$ matrix, we only need a $4\times 4$ transformation matrix—a reduction in parameter count. From this angle, the underlying purpose of switching Capsules from vectors to matrices may well be to reduce computational cost.
Cubic arrays?
Will future Capsules be "cubic arrays" or even higher-order tensors?
Unlikely. Because multiplication of higher-order tensors is, in essence, still a form of second-order matrix multiplication.
GMM vs. K-Means
How different is GMM clustering from the K-Means clustering you discussed earlier?
This needs to be viewed from two angles. On one hand, GMM can be seen as an upgraded version of K-Means, and it is inherently differentiable, so it doesn't need the earlier "softening" trick; if K-Means uses Euclidean distance, then K-Means is a limiting case of GMM. On the other hand, K-Means allows us more flexibility in using other similarity measures, whereas GMM is essentially locked into (weighted) Euclidean distance—the metric is "hard-coded," which is a drawback. All in all, the two are roughly on par with each other.
Capsule convolution
What's this "Capsule version of convolution"? Why wasn't it in the previous paper?
What we call dynamic routing is essentially equivalent to a fully-connected layer in deep learning, while a convolutional layer in deep learning is a locally-connected layer. So it's clear that all we need is a "local dynamic routing," and we get the Capsule version of convolution. This should really have appeared already in Hinton's previous paper, since it has nothing to do with the specific routing algorithm used—but for whatever reason, Hinton only implemented it in this new paper.
A brief introduction to the GMM model
Since this new paper uses GMM for clustering, it's worth spending some effort understanding GMM. Understanding the GMM algorithm is genuinely interesting, quite apart from Capsules—because the GMM model can greatly deepen our understanding of probabilistic models and machine learning theory (especially unsupervised learning theory). As a preview: in what follows, I've substantially simplified the derivation of GMM, which should make it easier for readers to follow.
Of course, readers who only want to understand the core idea of Capsules can selectively skip the more theoretical parts.
Essence
In our minds, it's best not to think of GMM as a clustering algorithm, but rather as a genuine unsupervised learning algorithm that attempts to learn the distribution of the data. The data itself consists of individual points, while the distribution is a whole; moving from studying the data itself to studying the data's distribution is a qualitative shift.
GMM stands for Gaussian Mixed Model. (There's also another "GMM" in the field—the Generalized Method of Moments, a parameter estimation method—but here we're discussing the former.) Specifically, given a set of existing vectors $\boldsymbol{x}_1,\dots,\boldsymbol{x}_n$, GMM seeks to find the distribution $p(\boldsymbol{x})$ that they satisfy. Of course, we can't search aimlessly; we need to posit a relatively simple form. GMM assumes that this batch of data can be split into several parts (classes), each studied separately, i.e.,
$$p(\boldsymbol{x})=\sum\limits_{j=1}^k p(j)p(\boldsymbol{x}|j)\tag{1}$$
Here $j$ represents the class, taking values $1,2,\dots,k$; since $p(j)$ has nothing to do with $\boldsymbol{x}$, we can treat it as a constant distribution, denoted $p(j)=\pi_j$. Then $p(\boldsymbol{x}|j)$ is the probability distribution within that class—GMM's defining feature is using a probability distribution to describe a class. What form should we choose? We take the simplest one, the normal distribution; note that here $\boldsymbol{x}$ is a vector, so we need to consider the multivariate normal distribution, whose general form is
$$N(\boldsymbol{x};\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j)=\frac{1}{(2\pi)^{d/2}(\det\boldsymbol{\Sigma}_j)^{1/2}}\exp\left(-\frac{1}{2}(\boldsymbol{x}-\boldsymbol{\mu}_j)^{\top}\boldsymbol{\Sigma}_j^{-1}(\boldsymbol{x}-\boldsymbol{\mu}_j)\right)\tag{2}$$
where $d$ is the number of components of the vector $\boldsymbol{x}$. Now we have the basic form of the model:
$$\begin{aligned}p(\boldsymbol{x})=\sum\limits_{j=1}^k p(&j)\times p(\boldsymbol{x}|j)=\sum\limits_{j=1}^k\pi_j N(\boldsymbol{x};\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j)\\ \downarrow& \qquad\,\,\downarrow\\ \pi_j& \,\,\cdot\,\, N(\boldsymbol{x};\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j) \end{aligned}\tag{3}$$
Solving the model
Now that we have the model, the unknown parameters are $\pi_j,\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j$—how do we determine them?
The ideal approach is maximum likelihood estimation, but there's no closed-form solution, so it needs to be turned into an EM procedure. Even so, the derivation process is fairly hard to follow (it involves differentiating a determinant). Here I'll give a much simpler and more transparent derivation, based on the following fact—for a normal distribution, maximum likelihood estimation gives the same result as the method-of-moments estimate using the first two moments. (Trust me, this should be one of the simplest derivations of GMM you'll find.)
Put plainly, isn't $\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j$ just the mean (vector) and (co)variance (matrix) of the normal distribution? Why not just compute the mean and variance directly from the samples? It's not that simple, because what we've assumed is a mixture of normal distributions; if we compute the mean and variance directly, we only get the mean and variance of the mixture as a whole, not the mean and variance of each individual normal component $p(\boldsymbol{x}|j)$.
However, we can use Bayes' rule to rework this. First we have
$$p(j|\boldsymbol{x})=\frac{p(\boldsymbol{x}|j)p(j)}{p(\boldsymbol{x})}=\frac{\pi_j N(\boldsymbol{x};\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j)}{\sum\limits_{j=1}^k\pi_j N(\boldsymbol{x};\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j)}\tag{4}$$
For the mean vector, for example, we have
$$\boldsymbol{\mu}_j = \int p(\boldsymbol{x}|j)\boldsymbol{x}d\boldsymbol{x}=\int p(\boldsymbol{x}) \frac{p(j|\boldsymbol{x})}{p(j)}\boldsymbol{x}d\boldsymbol{x}=E\left[\frac{p(j|X)}{p(j)}X\right]\tag{5}$$
Here $E[]$ means taking the expectation over all samples, so we can obtain
$$\boldsymbol{\mu}_j = \frac{1}{n}\sum\limits_{i=1}^n \frac{p(j|\boldsymbol{x}_i)}{p(j)}\boldsymbol{x}_i = \frac{1}{\pi_j n}\sum\limits_{i=1}^np(j|\boldsymbol{x}_i)\boldsymbol{x}_i\tag{6}$$
where the expression for $p(j|\boldsymbol{x})$ has already been given in $(4)$. Similarly, for the covariance matrix, we have
$$\boldsymbol{\Sigma}_j = \frac{1}{\pi_j n}\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)(\boldsymbol{x}_i-\boldsymbol{\mu}_j)(\boldsymbol{x}_i-\boldsymbol{\mu}_j)^{\top}\tag{7}$$
and then
$$\pi_j = p(j) = \int p(j|\boldsymbol{x})p(\boldsymbol{x})d\boldsymbol{x}=E\left[p(j|X)\right]\tag{8}$$
so
$$\pi_j = \frac{1}{n}\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)\tag{9}$$
In theory, we would need to solve a huge system of equations involving $(4),(6),(7),(9)$, but that's impractical to work with directly, so instead we solve it iteratively, giving the iterative algorithm:
$$\text{EM algorithm 1}:\left\{\begin{aligned} &p(j|\boldsymbol{x}_i) \leftarrow \frac{\pi_j N(\boldsymbol{x}_i;\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j)}{\sum\limits_{j=1}^k\pi_j N(\boldsymbol{x}_i;\boldsymbol{\mu}_j,\boldsymbol{\Sigma}_j)}\\ &\boldsymbol{\mu}_j \leftarrow \frac{1}{\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)}\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)\boldsymbol{x}_i\\ &\boldsymbol{\Sigma}_j \leftarrow \frac{1}{\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)}\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)(\boldsymbol{x}_i-\boldsymbol{\mu}_j)(\boldsymbol{x}_i-\boldsymbol{\mu}_j)^{\top}\\ &\pi_j \leftarrow \frac{1}{n}\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i) \end{aligned}\right.$$
To highlight the weighted-average nature of the process, the iteration above first applies an identity transformation to equation $(9)$ and then substitutes it into equation $(6),(7)$. In the iteration above, the first equation is called the $E$ step, and the latter three are called the $M$ step; the whole algorithm is called the EM algorithm. Below is an animation found online showing the GMM iteration process—you can see that GMM's advantage is that it can identify clusters shaped like general quadric surfaces, whereas K-Means can only identify spherical clusters.
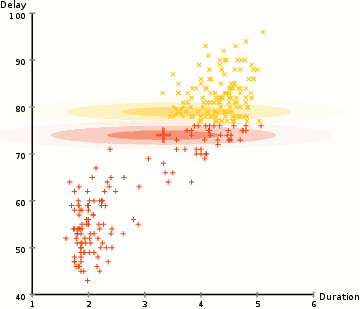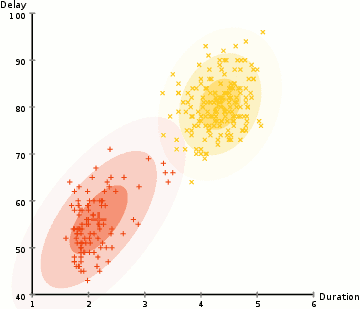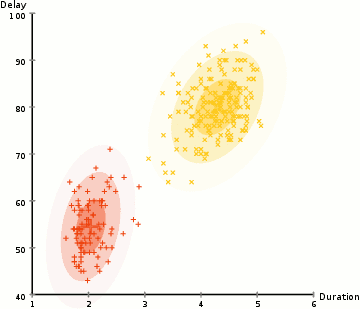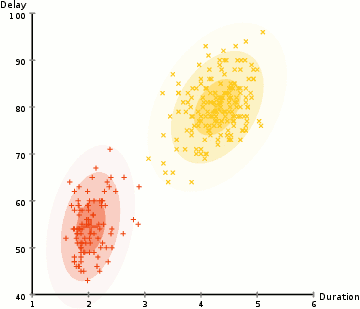 Illustration of the GMM iteration process
Simplification
In Capsules, an even simpler form of GMM is actually used. In the discussion above, we used the general normal distribution, i.e., equation $(2)$, but that requires computing the inverse and determinant of a matrix, which is fairly costly. A simpler model assumes the covariance matrix is diagonal, $\boldsymbol{\Sigma}_j = \text{diag}\boldsymbol{\sigma}^2_j$, where $\boldsymbol{\sigma}^2_j$ is the variance vector of class $j$; then $\boldsymbol{\sigma}_j$ is the standard-deviation vector, and $\boldsymbol{\sigma}_j^{l}$ denotes its $l$-th component. This effectively decouples the components of $\boldsymbol{x}$, treating each component as independent, and equation $(2)$ becomes
$$N(\boldsymbol{x};\boldsymbol{\mu}_j,\boldsymbol{\sigma}^2_j)=\prod_{l=1}^d\frac{1}{\sqrt{2\pi}\sigma_j^{l}}\exp\left(-\frac{1}{2(\sigma_j^{l})^2}(x^{l}-\mu_j^{l})^2\right)\tag{10}$$
and the iteration process simplifies to:
$$\text{EM algorithm 2}:\left\{\begin{aligned} &p(j|\boldsymbol{x}_i) \leftarrow \frac{\pi_j N(\boldsymbol{x}_i;\boldsymbol{\mu}_j,\boldsymbol{\sigma}^2_j)}{\sum\limits_{j=1}^k\pi_j N(\boldsymbol{x}_i;\boldsymbol{\mu}_j,\boldsymbol{\sigma}^2_j)}\\ &\boldsymbol{\mu}_j \leftarrow \frac{1}{\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)}\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)\boldsymbol{x}_i\\ &\boldsymbol{\sigma}^2_j \leftarrow \frac{1}{\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)}\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i)(\boldsymbol{x}_i-\boldsymbol{\mu}_j)^2\,[\text{elementwise square}]\\ &\pi_j \leftarrow \frac{1}{n}\sum\limits_{i=1}^n p(j|\boldsymbol{x}_i) \end{aligned}\right.$$
Even simpler
What if all the $\sigma_{j}^{l}$ take the same constant value $\sigma$? Then we get
$$N(\boldsymbol{x};\boldsymbol{\mu}_j,\sigma)=\frac{1}{\sqrt{2\pi}\sigma^d}\exp\left(-\frac{1}{2\sigma^2}\Vert \boldsymbol{x}-\boldsymbol{\mu}_j\Vert^2\right)\tag{11}$$
This makes the whole distribution even simpler; interestingly, the Euclidean distance now appears inside the exponent's parentheses.
Going even further, what if we let $\sigma\to 0$? Then the term inside the exponent's parentheses goes to negative infinity. It's not hard to show that for each $\boldsymbol{x}_i$, only the $N(\boldsymbol{x}_i;\boldsymbol{\mu}_j,\sigma^2)$ corresponding to the $\Vert \boldsymbol{x}_i-\boldsymbol{\mu}_j^2\Vert^2$ dominates; then, by equation $(4)$, $p(j|\boldsymbol{x}_i)$ becomes either 0 or 1 (the $j$ that minimizes $\Vert \boldsymbol{x}_i-\boldsymbol{\mu}_j^2\Vert^2$ gets its $p(j|\boldsymbol{x}_i)$ set to 1, and all others to 0), meaning that any point belongs only to the cluster center nearest to it—which coincides with K-Means using Euclidean distance. So, Euclidean-distance-based K-Means can be viewed as a limiting case of GMM.
The new routing algorithm
Back to the main topic—Capsules. We said that Matrix Capsules with EM Routing uses the GMM algorithm to perform clustering; let's now look at exactly how this is done.
Matrix -> vector
It has to be said that the notation in the new paper is used in a fairly chaotic way—perhaps being able to see the truth through a mess of symbols is what makes someone a true master. Here, drawing on some online explanatory material as well as my own reading, I'll offer some clarification.
First, we use a matrix $\boldsymbol{P}_i$ to represent the Capsules of layer $l$, which has $n$ Capsules in total, i.e., $i=1,\dots,n$; and a matrix $\boldsymbol{M}_j$ to represent the Capsules of layer $l+1$, which has $k$ Capsules in total—i.e., they are clustered into $k$ classes, $j=1,\dots,k$. In the paper, each Capsule's matrix is $4\times 4$-shaped, called the Pose matrix. Then we can begin the GMM process—and in doing GMM, the matrix is once again treated as a vector, so in the EM routing step, $\boldsymbol{P}_i$ is a vector, i.e., $d=16$. The whole process uses the simplified version of GMM, i.e., with the covariance matrix constrained to be diagonal.
So, following the earlier discussion, we obtain the new dynamic routing algorithm:
$$\text{new dynamic routing 1}:\left\{\begin{aligned} &p_{ij} \leftarrow N(\boldsymbol{P}_i;\boldsymbol{\mu}_j,\boldsymbol{\sigma}^2_j)\\ &R_{ij} \leftarrow \frac{\pi_j p_{ij} }{\sum\limits_{j=1}^k\pi_j p_{ij} },\,\,r_{ij}\leftarrow \frac{R_{ij}}{\sum\limits_{i=1}^n R_{ij}}\\ &\boldsymbol{M}_j \leftarrow \sum\limits_{i=1}^n r_{ij}\boldsymbol{P}_i\\ &\boldsymbol{\sigma}^2_j \leftarrow \sum\limits_{i=1}^n r_{ij}(\boldsymbol{P}_i-\boldsymbol{M}_j)^2\\ &\pi_j \leftarrow \frac{1}{n}\sum\limits_{i=1}^n R_{ij} \end{aligned}\right.$$
Here I've denoted $p_{ij}=N(\boldsymbol{x}_i;\boldsymbol{\mu}_j,\boldsymbol{\sigma}^2_j),R_{ij}=p(j|\boldsymbol{x}_i)$, keeping the notation as close as possible to the original paper for ease of comparison. The idea behind this dynamic routing is consistent with that in Dynamic Routing Between Capsules: in both cases, the Capsules of layer $l$ serve as the cluster centers for the Capsules of layer $l+1$—only the clustering method differs.
Activation value
In Dynamic Routing Between Capsules, the magnitude of a vector was used to represent how salient a feature is. Can we do the same here? The answer is no. Because we're using GMM for clustering, and GMM is based on weighted Euclidean distance (which is fundamentally still Euclidean distance), a characteristic of Euclidean-distance-based clustering is that the cluster center vector is a (weighted) average of the vectors within the class (as can be seen from the iteration formula for $\boldsymbol{M}_j$ above). Being an average, it can't reflect the property of "the more followers, the greater the influence," as was already noted in One More New Year's Feast: From K-Means to Capsules.
Since a Capsule's magnitude can no longer measure feature salience, we're forced to add an extra scalar $a$ to represent the salience of that Capsule. So in this paper, a Capsule is actually "a matrix + a scalar," and this scalar is called the "activation value" in the paper, as shown below:
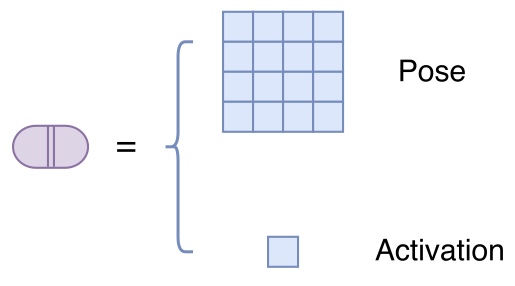 In this version, a Capsule is "matrix + scalar"
As a measure of a Capsule's salience, the most direct choice for $a_j$ would seem to be $\pi_j$, since the Capsules in layer $l+1$ are the cluster centers, and $\pi_j$ represents the probability of that class. However, we cannot simply choose $\pi_j$, for two reasons:
1. $\pi_j$ is normalized, whereas what we want is simply the intrinsic salience of the feature itself, not its relative salience compared to other features (put more plainly, we want to perform multiple binary classifications rather than one multi-way classification, so overall normalization is not what we need);
2. $\pi_j$ does reflect how many "followers" are in a class, but numbers alone don't guarantee strength—unity matters too.
So how should this activation value be defined? The formula given in the paper is:
$$a_j=logistic\left(\lambda\left(\beta_a-\beta_u\sum\limits_i R_{ij}-\sum\limits_h cost_j^h\right)\right)\tag{12}$$
I suspect many readers, after seeing this formula and the paper's "derivation," are still left puzzled. In fact, this formula has a rather elegant origin—information entropy.
Now that we're using GMM for clustering, the result is a probability distribution $p(\boldsymbol{X}|j)$ describing each class, and the "degree of uncertainty" of this distribution can be used to measure the "degree of unity" of the class. Put more plainly: the greater the "uncertainty" (meaning the distribution is closer to uniform), the more this class is still in a state of turmoil, each member going its own way—so the activation value should be smaller. The smaller the "uncertainty" (meaning the distribution is more concentrated), the more this class has unified and modernized—so the activation value should be larger.
So we can use uncertainty to describe this activation value, and we know that uncertainty is measured by information entropy, giving us:
$$\begin{aligned}S_j =& - \int p(\boldsymbol{x}|j)\ln p(\boldsymbol{x}|j)d\boldsymbol{x}\\ =& - \frac{1}{p(j)}\int p(j|\boldsymbol{x})p(\boldsymbol{x})\ln p(\boldsymbol{x}|j)d\boldsymbol{x}\\ =&- \frac{1}{p(j)} E\left[p(j|\boldsymbol{x})\ln p(\boldsymbol{x}|j)\right]\\ =&-\frac{1}{n\pi_j}\sum\limits_{i=1}^n R_{ij}\ln p_{ij}\\ =&-\frac{1}{\sum\limits_{i=1}^n R_{ij}}\sum\limits_{i=1}^n R_{ij}\ln p_{ij}\\ =&-\sum\limits_{i=1}^n r_{ij}\ln p_{ij}\end{aligned}\tag{13}$$
This is exactly the $cost_j^h$ in the paper—so the paper's $cost$ is nothing but entropy, with such a clear and intuitive meaning! And the fact that smaller entropy is better is such a natural piece of logic! (Why not directly integrate to compute the entropy of the normal distribution analytically, rather than going about it this roundabout way? Because a direct integral gives a theoretical result, whereas here we want an empirical result computed from this actual batch of data.)
Note: if readers have trouble following the sampling-based computation, please read the section Numerical Computation vs. Sampling-Based Computation in Variational Autoencoders (II): A Bayesian Perspective.
After simplification, the result is (the original paper's computation appears to contain an error):
$$S_j = \frac{d}{2}+\left(\sum\limits_{l=1}^d \ln \boldsymbol{\sigma}_j^l+\frac{d}{2}\ln (2\pi)\right)\sum\limits_i r_{ij}\tag{14}$$
Supplementary derivation:
Here the assumption is that $p_{ij}$ corresponds to a $d$-dimensional independent normal distribution, so we just need to compute the entropy of each dimension and sum them:
$$\begin{aligned}S_j^l =& \sum_{i} - r_{ij} \ln p_{ij}^l\\ > =&\sum_{i} - r_{ij} \ln \left[\frac{1}{\sqrt{2\pi}\boldsymbol{\sigma}_j^l}\exp\left(-\frac{(\boldsymbol{x}_i^l-\boldsymbol{\mu}_{j}^l)^2}{2(\boldsymbol{\sigma}_{j}^l)^2}\right)\right]\\ > =&\left(\frac{1}{2}\ln 2\pi + \ln\boldsymbol{\sigma}_j^l\right)\sum_{i} r_{ij}+\frac{\sum\limits_{i}r_{ij}\left(\boldsymbol{x}_i^l-\boldsymbol{\mu}_{j}^l\right)^2}{2(\boldsymbol{\sigma}_{j}^l)^2} > \end{aligned}$$
Note that the numerator of the final term is precisely the defining formula for variance, while the denominator is twice the variance, so this final term is just "variance/variance" divided by 2, i.e.,
$$S_j^l = \sum_{i} - r_{ij} \ln p_{ij}^l=\left(\frac{1}{2}\ln 2\pi + \ln\boldsymbol{\sigma}_j^l\right)\sum_{i} r_{ij}+\frac{1}{2}$$
hence
$$S_j = \sum_{l=1}^d S_j^l =\left(\frac{d}{2}\ln 2\pi + \sum_{l=1}^d\ln\boldsymbol{\sigma}_j^l\right)\sum_{i} r_{ij}+\frac{d}{2}$$
Since smaller entropy means greater salience, we use $-S_j$ to measure feature salience, but we still want to compress it into the range 0 to 1. So we apply a simple rescaling followed by a sigmoid activation:
$$a_j = sigmoid\left( \lambda \left( \beta_a - \left(\beta_u+\sum\limits_{l=1}^d \ln \boldsymbol{\sigma}_j^l \right)\sum\limits_i r_{ij}\right)\right)\tag{15}$$
Equations $(15)$ and $(13)$ are essentially equivalent; the expression above amounts to a weighted sum of $-S_j$ and $\pi_j$—that is, jointly accounting for $-S_j$ (unity) and $\pi_j$ (numbers). Here $\beta_a,\beta_u$ is optimized via backpropagation, while $\lambda$ is gradually increased over training (an annealing strategy, which is the paper's own choice—I don't think it's actually necessary). $\beta_a,\beta_u$ might depend on $j$, meaning each higher-level capsule could be assigned its own set of trainable parameters $\beta_a,\beta_u$. I say "might" because the paper never really clarifies this—readers may want to adjust it according to their own experiments and needs.
Making routing explicit
Once we have the formula for $a_j$, since we noted earlier that $a_j$ and $\pi_j$ share some commonality—both being a kind of class weight—Hinton, in order to make the whole routing process more compact, simply replaces $\pi_j$ with $a_j$ directly. This substitution doesn't exactly correspond to the original GMM iteration, but the meaning is similar, and it still converges. This gives us the corrected dynamic routing:
$$\text{new dynamic routing 2}:\left\{\begin{aligned} &p_{ij} \leftarrow N(\boldsymbol{P}_i;\boldsymbol{\mu}_j,\boldsymbol{\sigma}^2_j)\\ &R_{ij} \leftarrow \frac{a_j p_{ij} }{\sum\limits_{j=1}^k a_j p_{ij} },\,\,r_{ij}\leftarrow \frac{R_{ij}}{\sum\limits_{i=1}^n R_{ij}}\\ &\boldsymbol{M}_j \leftarrow \sum\limits_{i=1}^n r_{ij}\boldsymbol{P}_i\\ &\boldsymbol{\sigma}^2_j \leftarrow \sum\limits_{i=1}^n r_{ij}(\boldsymbol{P}_i-\boldsymbol{M}_j)^2\\ & cost_j \leftarrow \left(\beta_u+\sum\limits_{l=1}^d \ln \boldsymbol{\sigma}_j^l \right)\sum\limits_i r_{ij} \\ & a_j \leftarrow sigmoid\left( \lambda \left(\beta_a - cost_j\right)\right) \end{aligned}\right.$$
Resist the urge to faint—we're almost at the end. This algorithm is now essentially complete, but you'll notice that if we stack multiple layers of Capsules together, we've missed a detail: $\boldsymbol{P}_i$ is the Capsule matrix from the previous layer, which we've already used—but what about the activation value from the previous layer (denoted $a^{last}_i$)? Don't forget that in matrix Capsules, every Capsule is a matrix plus a scalar; using only the matrix is clearly incomplete. Hinton inserts the activation value at the $r_{ij}\leftarrow \frac{R_{ij}}{\sum\limits_{i=1}^n R_{ij}}$ step, giving:
$$\text{new dynamic routing 3}:\left\{\begin{aligned} &p_{ij} \leftarrow N(\boldsymbol{P}_i;\boldsymbol{\mu}_j,\boldsymbol{\sigma}^2_j)\\ &R_{ij} \leftarrow \frac{a_j p_{ij} }{\sum\limits_{j=1}^k a_j p_{ij} },\,\,r_{ij}\leftarrow \frac{a^{last}_i R_{ij}}{\sum\limits_{i=1}^n a^{last}_i R_{ij}}\\ &\boldsymbol{M}_j \leftarrow \sum\limits_{i=1}^n r_{ij}\boldsymbol{P}_i\\ &\boldsymbol{\sigma}^2_j \leftarrow \sum\limits_{i=1}^n r_{ij}(\boldsymbol{P}_i-\boldsymbol{M}_j)^2\\ & cost_j \leftarrow \left(\beta_u+\sum\limits_{l=1}^d \ln \boldsymbol{\sigma}_j^l \right)\sum\limits_i r_{ij} \\ & a_j \leftarrow sigmoid\left( \lambda \left(\beta_a - cost_j\right)\right) \end{aligned}\right.$$
This should be the corrected dynamic routing algorithm as it stands—if I've understood it correctly—since the original paper really is extremely hard to parse. Many readers probably missed this particular detail. Why? Because the notation in the paper is used like this:
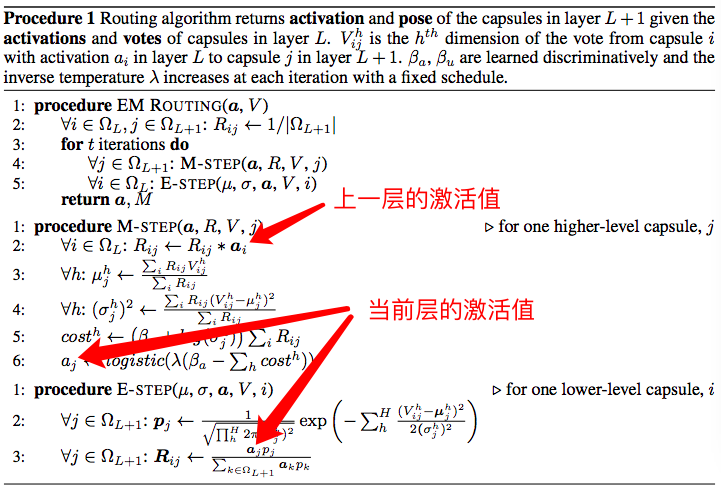 Poor notation choices in the original paper
(Surprised? Delighted?)
One more small thing—readers may notice that, following our own definitions, we should have $\sum\limits_i r_{ij}=1$; why not just simplify directly? Honestly, I don't know why either. The $cost_j$ used in the paper actually isn't $r_{ij}$, but rather $a^{last}_i R_{ij}$! That is:
$$\text{new dynamic routing 4}:\left\{\begin{aligned} &p_{ij} \leftarrow N(\boldsymbol{P}_i;\boldsymbol{\mu}_j,\boldsymbol{\sigma}^2_j)\\ &R_{ij} \leftarrow \frac{a_j p_{ij} }{\sum\limits_{j=1}^k a_j p_{ij} },\,\,r_{ij}\leftarrow \frac{a^{last}_i R_{ij}}{\sum\limits_{i=1}^n a^{last}_i R_{ij}}\\ &\boldsymbol{M}_j \leftarrow \sum\limits_{i=1}^n r_{ij}\boldsymbol{P}_i\\ &\boldsymbol{\sigma}^2_j \leftarrow \sum\limits_{i=1}^n r_{ij}(\boldsymbol{P}_i-\boldsymbol{M}_j)^2\\ & cost_j \leftarrow \left(\beta_u+\sum\limits_{l=1}^d \ln \boldsymbol{\sigma}_j^l \right)\sum\limits_i a^{last}_i R_{ij} \\ & a_j \leftarrow sigmoid\left( \lambda \left(\beta_a - cost_j\right)\right) \end{aligned}\right.$$
Well, I have no more energy left to complain—Hinton can play it however he likes. Even if we can force some explanation onto this (perhaps the rough idea is that this layer's activation value should still be modulated by the previous layer's activation value), it doesn't really offer any further insight.
Weight matrices
Last but not least, just as in the previous paper, we equip each index pair $(i,j)$ with a weight matrix $\boldsymbol{W}_{ij}$ (called the viewpoint-invariant matrix), obtaining the "vote matrix" $\boldsymbol{V}_{ij}=\boldsymbol{P}_{i}\boldsymbol{W}_{ij}$; dynamic routing is then performed on these, giving the final dynamic routing algorithm:
$$\text{new dynamic routing (full)}:\left\{\begin{aligned} &p_{ij} \leftarrow N(\boldsymbol{V}_{ij};\boldsymbol{\mu}_j,\boldsymbol{\sigma}^2_j)\\ &R_{ij} \leftarrow \frac{a_j p_{ij} }{\sum\limits_{j=1}^k a_j p_{ij} },\,\,r_{ij}\leftarrow \frac{a^{last}_i R_{ij}}{\sum\limits_{i=1}^n a^{last}_i R_{ij}}\\ &\boldsymbol{M}_j \leftarrow \sum\limits_{i=1}^n r_{ij}\boldsymbol{V}_{ij}\\ &\boldsymbol{\sigma}^2_j \leftarrow \sum\limits_{i=1}^n r_{ij}(\boldsymbol{V}_{ij}-\boldsymbol{M}_j)^2\\ & cost_j \leftarrow \left(\beta_u+\sum\limits_{l=1}^d \ln \boldsymbol{\sigma}_j^l \right)\sum\limits_i a^{last}_i R_{ij} \\ & a_j \leftarrow sigmoid\left( \lambda \left(\beta_a - cost_j\right)\right) \end{aligned}\right.$$
Closing remarks
Assessment
After this whole analysis, hopefully it's clear that this new version of Capsules and its routing algorithm isn't actually all that complicated. The main point of the new paper is the use of GMM to perform clustering. GMM is a clustering algorithm grounded in a probabilistic model; once you firmly grasp this "probabilistic model" characteristic and look for probability-related quantities, it isn't hard to understand where the expression $a_j$ comes from—this is probably the hardest single point in understanding the whole paper. As for replacing vectors with matrices, that seems to be purely a way of reducing computation and parameter count, with no fundamental change otherwise.
It's just that the new paper inherits the old paper's obscure style of exposition, compounded by chaotic notation, which makes it considerably harder to understand—another mark against the authors' writing.
Of course, there are still some genuinely puzzling, hard-to-motivate elements in the paper—such as the substitution of $r_{ij}$ by $a^{last}_i R_{ij}$ in $cost_j$ mentioned above. If anyone has a more illuminating way of thinking about this, please feel free to leave a comment and discuss.
Reflections
At this point, I've finally worked through Matrix Capsules with EM Routing thoroughly. As for code, I won't be writing any, because honestly I'm not particularly fond of this new version of Capsules and dynamic routing, and I don't want to reinvent the wheel again.
This is my third article on understanding Capsules. Compared to other posts on Scientific Spaces, these three articles are rather "massive" in length—they carry the weight of my thinking and understanding about Capsules. Each one took several days to write, as I tried as much as possible to combine theory with accessible language, and to lay out the whole chain of reasoning clearly. I hope these words help readers understand Capsules more quickly. Of course, my own understanding is limited, so if there's anything misleading here, please feel free to point it out in the comments.
Of course, I'd much rather the authors of Capsules themselves explain their new theory in more intuitive, more illuminating language—that would save us science communicators a fair amount of effort. After all, Capsules really might be the future of deep learning—how could it possibly be left so murky?
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.