What exactly makes it so hard to train a 1000-layer Transformer?
As we all know, Transformers keep getting bigger nowadays, but this "bigger" usually means "wider" rather than "deeper." For example, although GPT-3 has hundreds of billions of parameters, it's still only a 96-layer Transformer model, far from the kind of depth we can imagine. So what's holding Transformers back from going "deeper"? Some readers might think it's compute, but a "wide and shallow" model doesn't require much less compute than a "narrow and deep" one, so compute isn't really the main constraint. Ultimately, it comes down to the inherent training difficulty of Transformers. The common view is that deep models are hard to train because of vanishing or exploding gradients, yet in practice, even after fixing the gradient behavior through various tricks, deep models remain hard to train.
Some recent work (such as Admin) points out that the fundamental difficulty in training deep models lies in "incremental explosion" — that is, the deeper the model, the larger the perturbation it induces on the output. Last week's paper DeepNet: Scaling Transformers to 1,000 Layers follows this line of thought to carry out a scale analysis, and based on the results, adjusts the model's normalization and initialization scheme, ultimately succeeding in training a 1000-layer Transformer model. The whole analysis process is quite instructive, so let's go through it together.
Incremental explosion
The full analysis in the original paper is fairly long, and some of its assumptions or descriptions are, on closer inspection, not entirely rigorous. So in this post, I'll try to fix these issues and attempt to arrive at similar results in a more reasonable way.
Suppose the loss function is $\mathcal{L}(\boldsymbol{\theta})$, with $\boldsymbol{\theta}$ as its parameters. Consider the increment in the loss function when the parameters change from $\boldsymbol{\theta}$ to $\boldsymbol{\theta}+\Delta\boldsymbol{\theta}$:
\begin{equation}\Delta\mathcal{L} = \mathcal{L}(\boldsymbol{\theta}+\Delta\boldsymbol{\theta}) - \mathcal{L}(\boldsymbol{\theta}) \approx \langle\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta}),\Delta\boldsymbol{\theta}\rangle\end{equation}
For SGD we have $\Delta\boldsymbol{\theta}=-\eta \nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})$, so $\Delta\mathcal{L} \approx -\eta\Vert\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})\Vert^2$. Suppose the model has $N$ layers, each with $K$ parameter matrices ($K$ close to a constant). With Xavier initialization and various normalization techniques, we can arrange for the gradient norm of each parameter matrix to be on the order of $\mathcal{O}(1)$, so we get $\Delta\mathcal{L}=\mathcal{O}(\eta NK)$. Therefore, the update magnitude at each step of the model is proportional to the model depth $N$: the deeper the model, the larger the update. This means that in the early stages of training, a deeper model is more likely to fall into a bad local optimum, after which training stalls or even collapses — this is the "incremental explosion" problem.
There are two ways to address this. One is to use a smaller learning rate in the early stage of training (no larger than order $\eta/N$), and then gradually increase it — this is the Warmup trick. The other is to adjust the initialization scheme so that the gradient of the parameters is of order $\mathcal{O}(1/\sqrt{N})$, which automatically cancels out the effect of model depth.
Order-of-magnitude analysis
How do we achieve the second approach? We can try to analyze the gradients of the Transformer. However, computing exact gradients is quite tedious, and in fact we don't need exact gradients at all — we just need an order-of-magnitude analysis of the gradients. So we can use the following "magnitude decomposition" trick to turn this into a problem about derivatives of scalars.
For a matrix $\boldsymbol{W}$, we decompose it in the form $\boldsymbol{W}=\lambda \boldsymbol{U}$, where
\begin{equation}\lambda = \mathop{\text{argmin}}_{\kappa > 0} \Vert \boldsymbol{W}\boldsymbol{W}^{\top}/\kappa^2 - \boldsymbol{I}\Vert,\quad \end{equation}
In plain terms, we're decomposing a matrix into the product of a scalar $\lambda$ and a matrix $\boldsymbol{U}$ that is as close to orthogonal as possible. Since $\boldsymbol{U}$ is close to an orthogonal matrix, it serves as a kind of standard reference frame, while the corresponding $\lambda$ represents the magnitude of the matrix $\boldsymbol{W}$. If $\boldsymbol{W}$ uses Xavier initialization, then $\lambda$ is equivalent to the gain parameter within it, i.e., on top of standard Xavier initialization we further multiply by $\lambda$. This is because the result of Xavier initialization is already close to an orthogonal matrix — see A Geometric Perspective on Parameter Initialization Strategies for more on this.
Under this decomposition, we have
\begin{equation}\frac{\partial \mathcal{L}(\lambda \boldsymbol{U})}{\partial \lambda} = \left\langle\frac{\partial \mathcal{L}(\lambda \boldsymbol{U})}{\partial (\lambda \boldsymbol{U})}, \boldsymbol{U}\right\rangle = \left\langle\frac{\partial \mathcal{L}(\boldsymbol{W})}{\partial \boldsymbol{W}}, \boldsymbol{U}\right\rangle\end{equation}
This means that $\frac{\partial \mathcal{L}}{\partial \lambda}$ and $\frac{\partial \mathcal{L}}{\partial \boldsymbol{W}}$ are proportional to each other in magnitude, so doing an order-of-magnitude analysis on $\frac{\partial \mathcal{L}}{\partial \lambda}$ is equivalent to doing one on $\frac{\partial \mathcal{L}}{\partial \boldsymbol{W}}$. In this way, $\frac{\partial \mathcal{L}}{\partial \lambda}$ acts as a simple "probe" at the order of magnitude $\frac{\partial \mathcal{L}}{\partial \boldsymbol{W}}$, turning the original matrix derivative into a scalar derivative, which reduces the difficulty of the analysis.
Feedforward gradients
Many experimental results show that although Pre Norm is easier to train than Post Norm, Post Norm tends to give better final performance. So the original paper keeps the Post Norm structure, while considering a more general form (DeepNorm):
\begin{equation}\boldsymbol{x}_{l+1} = \text{LN}(\alpha\boldsymbol{x}_l + F(\boldsymbol{x}_l)) = \text{LN}(\boldsymbol{x}_l + F(\boldsymbol{x}_l)/\alpha)\end{equation}
where $\alpha > 0$ is a constant. For simplicity, let's first consider the FFN layer, in which case
\begin{equation}\boldsymbol{x}_{l+1} = \text{LN}(\boldsymbol{x}_l + \phi(\boldsymbol{x}_l \boldsymbol{W}_1)\boldsymbol{W}_2/\alpha)\end{equation}
Here $\phi$ is the activation function, typically ReLU or one of its variants (Swish, GeLU, etc.), which (approximately) satisfy $\phi(\lambda x) = \lambda \phi(x),\forall \lambda > 0$. Using the magnitude decomposition probe from the previous section, we get
\begin{equation}\boldsymbol{x}_{l+1} = \text{LN}(\underbrace{\boldsymbol{x}_l + \lambda_1 \lambda_2 \phi(\boldsymbol{x}_l \boldsymbol{U}_1)\boldsymbol{U}_2/\alpha}_{\text{denote}\boldsymbol{z}_{l+1}})\label{eq:ffn}\end{equation}
Taking the gradient with respect to $\lambda$:
\begin{equation}\begin{aligned} \frac{\partial \mathcal{L}}{\partial \lambda_1} = \frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}\frac{\partial \boldsymbol{z}_{l+1}}{\partial \lambda_1} = \frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}\frac{\lambda_2 \phi(\boldsymbol{x}_l \boldsymbol{U}_1)\boldsymbol{U}_2}{\alpha} \\ \frac{\partial \mathcal{L}}{\partial \lambda_2} = \frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}\frac{\partial \boldsymbol{z}_{l+1}}{\partial \lambda_2} = \frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}\frac{\lambda_1 \phi(\boldsymbol{x}_l \boldsymbol{U}_1)\boldsymbol{U}_2}{\alpha} \end{aligned}\end{equation}
We assert that both $\frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}$ and $\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}$ are of order $\mathcal{O}(1)$, and since $\boldsymbol{U}_1$ and $\boldsymbol{U}_2$ are both close to orthogonal matrices, $\phi(\boldsymbol{x}_l \boldsymbol{U}_1)\boldsymbol{U}_2$ is also of order $\mathcal{O}(1)$. Therefore we finally get
\begin{equation}\frac{\partial \mathcal{L}}{\partial \lambda_1} = \mathcal{O}\left(\frac{\lambda_2}{\alpha}\right),\quad \frac{\partial \mathcal{L}}{\partial \lambda_2} = \mathcal{O}\left(\frac{\lambda_1}{\alpha}\right)\end{equation}
Self-attention
Now let's consider self-attention. For the purposes of the order-of-magnitude analysis, it suffices to consider single-head attention, which has the form
\begin{equation}\boldsymbol{x}_{l+1} = \text{LN}(\boldsymbol{x}_l + \sigma(\boldsymbol{x}_l \boldsymbol{W}_q\boldsymbol{W}_k^{\top}\boldsymbol{x}_l^{\top})\boldsymbol{x}_l\boldsymbol{W}_v\boldsymbol{W}_o/\alpha)\end{equation}
where $\sigma(\cdot)$ is shorthand for the softmax operation; here we omit the attention scaling operation. After magnitude decomposition, the above becomes
\begin{equation}\boldsymbol{x}_{l+1} = \text{LN}(\underbrace{\boldsymbol{x}_l + \lambda_v\lambda_o \sigma (\lambda_q\lambda_k\boldsymbol{x}_l \boldsymbol{U}_q\boldsymbol{U}_k^{\top}\boldsymbol{x}_l^{\top})\boldsymbol{x}_l\boldsymbol{U}_v\boldsymbol{U}_o/\alpha}_{\text{denote}\boldsymbol{z}_{l+1}})\label{eq:sa}\end{equation}
Now we can take the gradient with respect to each $\lambda$ separately. Because of the presence of softmax, the gradient with respect to $\lambda_q,\lambda_k$ itself will actually be very small and won't noticeably affect the final update magnitude, so it suffices to consider the update magnitude with respect to $\lambda_v,\lambda_o$:
\begin{equation}\begin{aligned} \frac{\partial \mathcal{L}}{\partial \lambda_v} = \frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}\frac{\partial \boldsymbol{z}_{l+1}}{\partial \lambda_v} = \frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}\frac{\lambda_o \sigma (\lambda_q\lambda_k\boldsymbol{x}_l \boldsymbol{U}_q\boldsymbol{U}_k^{\top}\boldsymbol{x}_l^{\top})\boldsymbol{x}_l\boldsymbol{U}_v\boldsymbol{U}_o}{\alpha} \\ \frac{\partial \mathcal{L}}{\partial \lambda_o} = \frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}\frac{\partial \boldsymbol{z}_{l+1}}{\partial \lambda_o} = \frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}\frac{\lambda_v \sigma (\lambda_q\lambda_k\boldsymbol{x}_l \boldsymbol{U}_q\boldsymbol{U}_k^{\top}\boldsymbol{x}_l^{\top})\boldsymbol{x}_l\boldsymbol{U}_v\boldsymbol{U}_o}{\alpha} \end{aligned}\end{equation}
Again we assert that both $\frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}$ and $\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}$ are of order $\mathcal{O}(1)$, and note that softmax produces a probability distribution, which is then used to take a weighted average over the tokens of $\boldsymbol{x}_l$. In general, the vector before and after averaging will be of the same order of magnitude, so we also take $\sigma (\lambda_q\lambda_k\boldsymbol{x}_l \boldsymbol{U}_q\boldsymbol{U}_k^{\top}\boldsymbol{x}_l^{\top})\boldsymbol{x}_l\boldsymbol{U}_v\boldsymbol{U}_o$ to be of order $\mathcal{O}(1)$. Hence the result parallels that of the FFN layer:
\begin{equation}\frac{\partial \mathcal{L}}{\partial \lambda_v} = \mathcal{O}\left(\frac{\lambda_o}{\alpha}\right),\quad \frac{\partial \mathcal{L}}{\partial \lambda_o} = \mathcal{O}\left(\frac{\lambda_v}{\alpha}\right)\end{equation}
Preliminary conclusion
Now, whether for FFN or self-attention, we've arrived at similar conclusions. For simplicity, suppose the magnitude of every parameter (at least at initialization) is the same, i.e., all the $\lambda$ take the same value. Then the overall conclusion is
\begin{equation}\frac{\partial \mathcal{L}}{\partial \lambda} = \mathcal{O}\left(\frac{\lambda}{\alpha}\right)\end{equation}
That is, the gradient is of order $\mathcal{O}(\lambda/\alpha)$. On the other hand, we say a Transformer model with $N$ layers generally has $N$ self-attention layers plus $N$ FFN layers, so strictly speaking the number of layers is $2N$. Therefore, following the analysis in the "Incremental explosion" section, we need to bring the gradient down to order $\mathcal{O}(1/\sqrt{2N})$; the above tells us this can be achieved by setting $\lambda/\alpha=1/\sqrt{2N}$. The original paper's bound is somewhat looser, giving the result $\lambda/\alpha = 1/\sqrt{4N}$, which is equivalent at the order-of-magnitude level.
We've now obtained a proportional relationship between $\lambda$ and $\alpha$, but this doesn't directly give us the specific values of $\lambda$ and $\alpha$. According to the paper, from a symmetry standpoint, we set $\lambda=1/\alpha$, from which we can solve for
\begin{equation}\alpha = (2N)^{1/4},\quad \lambda = (2N)^{-1/4}\label{eq:result}\end{equation}
However, an appeal to symmetry alone is clearly not fully convincing — we need to understand what actually differs between different choices. To this end, let's compare two other pairs of solutions:
Alternative solution 1: $\alpha=1,\lambda=(2N)^{-1/2}$. In this case, the parameter initialization is shrunk to $(2N)^{-1/2}$ times its original value, and the gradient is also shrunk to $(2N)^{-1/2}$ times its original value. According to SGD's $\Delta\boldsymbol{\theta}=-\eta \nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})$, the per-step update magnitude is likewise $(2N)^{-1/2}$ times its original value — that is, the relative learning magnitude before and after adjustment is unchanged. This means that even though we may start at the $\lambda=\mathcal{O}((2N)^{-1/2})$ order of magnitude, after just a few training steps we could drift away from that scale.
Alternative solution 2: $\alpha=(2N)^{1/2},\lambda=1$. In this case, the parameter initialization is not shrunk, but the gradient is still shrunk to $(2N)^{-1/2}$ times its original value. According to SGD's $\Delta\boldsymbol{\theta}=-\eta \nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})$, the per-step update magnitude is also $(2N)^{-1/2}$ times its original value, so the relative learning magnitude is significantly reduced before and after adjustment, which could result in very slow learning.
Both of these seem to have their own drawbacks, so the solution $\eqref{eq:result}$, sitting between the two, seems to make more sense. It keeps the gradient scaled down to $(2N)^{-1/2}$ times its original value while making the initial learning steps slightly slower — but not too slow — implicitly playing the role of Warmup.
Various optimizers
The analysis above is all based on SGD, but in practice we rarely train NLP models directly with SGD; more often we use adaptive learning-rate optimizers, which mainly fall into two categories: one uses second moments to correct the learning rate, e.g. Adam, AdamW; the other further corrects the learning rate using the parameter norm, e.g. LAMB, AdaFactor. The original paper's approach is essentially: "we derive things on SGD, then verify on Adam that it still works reasonably well" — but theoretically speaking, these results don't fully carry over. In this section we'll do a more targeted analysis for these cases.
For Adam-type optimizers, the update magnitude at each step is approximately $\Delta\boldsymbol{\theta}=-\eta\,\text{sign}(\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta}))$, so $\Delta\mathcal{L} \approx -\eta\Vert\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})\Vert_1$: it's proportional to the first power of the gradient rather than the second. So, in order to make the update magnitude independent of the number of layers, the gradient should be shrunk to $1/(2N)$ times its original value, i.e. we should have $\lambda/\alpha=1/(2N)$. If we likewise set $\lambda=1/\alpha$, then
\begin{equation}\alpha = (2N)^{1/2},\quad \lambda = (2N)^{-1/2}\end{equation}
For LAMB-type optimizers, the per-step update magnitude is approximately $\Delta\boldsymbol{\theta}=-\eta\Vert\theta\Vert\,\text{sign}(\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta}))$, so $\Delta\mathcal{L} \approx -\eta\Vert\theta\Vert\Vert\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})\Vert_1$. Noting that the scaling ratio of the parameters is $\lambda$ and that of the gradients is $\lambda/\alpha$, we get $\Delta\mathcal{L}=\mathcal{O}(2N\lambda^2/\alpha)$, hence $\lambda^2/\alpha=1/(2N)$. Note that for this class of optimizers, the relative update magnitude at each step is always the same (equal to the learning rate $\eta$), and no matter how we adjust $\alpha,\lambda$, this relative update magnitude never changes — so we can simply take $\alpha=1,\lambda=(2N)^{-1/2}$.
The results are summarized and compared as follows:
$$\begin{array}{c|cc|cc} \hline \text{optimizer} & \Delta\boldsymbol{\theta} & \Delta\mathcal{L} & \alpha & \lambda \\ \hline \text{SGD} & -\eta \nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta}) & -\eta\Vert\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})\Vert^2 & (2N)^{1/4} & (2N)^{-1/4}\\ \text{Adam} & -\eta\,\text{sign}(\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})) & -\eta\Vert\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})\Vert_1 & (2N)^{1/2}& (2N)^{-1/2}\\ \text{LAMB} & -\eta\Vert\theta\Vert\,\text{sign}(\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})) & -\eta\Vert\theta\Vert\Vert\nabla_{\boldsymbol{\theta}}\mathcal{L}(\boldsymbol{\theta})\Vert_1 & 1 & (2N)^{-1/2}\\ \hline \end{array}$$
A post-hoc check
In the derivations of the previous two sections, we relied on the assertion that "both $\frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}$ and $\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}$ are of order $\mathcal{O}(1)$" — does this actually hold? Let's check it after the fact.
It's actually quite simple. After the adjustments described above, whether for the FFN layer $\eqref{eq:ffn}$ or the self-attention layer $\eqref{eq:sa}$, in the initial stage the weight of each residual branch is scaled down to $\lambda^2/\alpha$ times its original value. Regardless of which optimizer's result we use, $\lambda^2/\alpha$ turns out to be a fairly small number, which means that in the initial stage the whole model is effectively close to an identity function. Consequently, $\frac{\partial \mathcal{L}}{\partial \boldsymbol{x}_{l+1}}$ and $\frac{\partial \boldsymbol{x}_{l+1}}{\partial \boldsymbol{z}_{l+1}}$ are naturally both of order $\mathcal{O}(1)$, so the conclusion is self-consistent with the assertion.
Additionally, some readers might wonder whether the same analysis can be applied to the Pre Norm structure. The answer is yes, and the conclusion turns out to be essentially the same, except that since normalization is placed before the residual branch, there's no longer a need to introduce the parameter $\alpha$. So the conclusion is that, in the Post Norm results above, all instances of $\alpha$ are simply set to 1, and the corresponding $\lambda$ are recomputed accordingly.
Finally, readers may wonder, after all this effort discussing how to make the model deeper: does depth really matter that much? Yes — the original paper presents a striking experimental result: a 200-layer "deep and narrow" model (3.2 billion parameters) beats the previous SOTA "shallow and wide" 48-layer model (12 billion parameters).
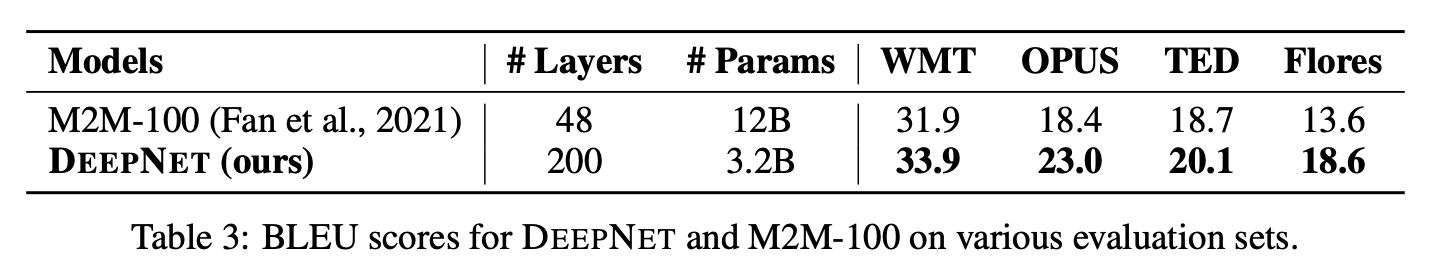 The "deep and narrow" model outperforms the "shallow and wide" model
Summary
This post analyzed the bottleneck in making Transformers "deeper" and gave the corresponding solution. The main ideas come from Microsoft's newly released DeepNet, and I've simplified and refined the original paper's analysis process to some extent.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.