Questions and Communications Regarding the Originality of WhiteningBERT
In the post You Probably Don't Need BERT-flow: A Linear Transformation That Rivals BERT-flow, inspired by BERT-flow, I proposed an alternative approach called BERT-whitening, which is simpler than BERT-flow but achieves comparable or even better results on most datasets. In addition, it can be used to reduce the dimensionality of sentence vectors to speed up retrieval. Later, together with several collaborators, I supplemented the BERT-whitening experiments and wrote them up as an English paper, Whitening Sentence Representations for Better Semantics and Faster Retrieval, which was posted to Arxiv on March 29 of this year.
However, about a week later, a paper titled WhiteningBERT: An Easy Unsupervised Sentence Embedding Approach (hereafter referred to as WhiteningBERT) appeared on Arxiv, whose content overlaps heavily with BERT-whitening. Some readers who noticed this reported back to me that they suspected WhiteningBERT had plagiarized BERT-whitening. This post reports to readers who are concerned about this matter the outcome of my communications with the authors of WhiteningBERT.
Timeline
First, let's review the relevant timeline of BERT-whitening, to help everyone follow the sequence of events: more
January 11, 2021: Published the post You Probably Don't Need BERT-flow: A Linear Transformation That Rivals BERT-flow on this blog, introducing BERT-whitening for the first time. At this point the post did not yet include the dimensionality-reduction section;
January 19, 2021: The BERT-whitening blog post was reposted to the WeChat public account "夕小瑶的卖萌屋" (link). Through this dual publication on the blog and the public account, I believe BERT-whitening had already spread fairly widely, at least within the domestic (Chinese) NLP community;
January 20, 2021: Tencent researcher Liu pointed out to me that BERT-whitening is essentially just PCA, and could therefore also be used for dimensionality reduction. Upon testing, the dimension-reduced sentence vectors actually improved performance on some tasks — fast and good — so I updated the blog post with this content;
January 23, 2021: Feeling that BERT-whitening still had some academic value, I invited Mr. Liu and Mr. Cao to join me in supplementing the experiments and writing an English paper to submit to ACL2021, at which point there was only a little over a week left before the deadline;
February 2, 2021: Fortunately, we finished the experiments and the paper in time and submitted it before the ACL2021 deadline;
March 26, 2021: The ACL2021 review results came out. We felt they weren't very optimistic, so we didn't bother with the rebuttal, and instead planned to post the paper directly to Arxiv;
March 29, 2021: The English paper on BERT-whitening, Whitening Sentence Representations for Better Semantics and Faster Retrieval, was posted on Arxiv;
April 5, 2021: The WhiteningBERT paper, WhiteningBERT: An Easy Unsupervised Sentence Embedding Approach, appeared on Arxiv;
September 26, 2021: The Accepted Papers list for EMNLP2021 was published, confirming that WhiteningBERT had been accepted at EMNLP2021.
Readers may wonder: it's already been half a year since April 5, so why am I only bringing this up now? First, because the BERT-whitening method is relatively simple, I couldn't rule out the possibility that someone else independently arrived at the same result, so I didn't pay much attention when WhiteningBERT first appeared on Arxiv. Second, even granting the assumption (purely hypothetically) that WhiteningBERT did copy BERT-whitening, it would still just be a minor matter of posting something to Arxiv — not a big deal — so it wasn't worth spending time on.
However, once I learned that WhiteningBERT had been accepted at EMNLP2021, the nature of the matter was no longer "no big deal." So I decided to try to communicate with the authors of WhiteningBERT, hoping they could demonstrate the originality of WhiteningBERT, so as to avoid unnecessary misunderstandings. What follows is an account of our communication process.
Email Correspondence
On September 26, I sent the first email to all the authors of WhiteningBERT, with the following content:
Dear authors,
First, congratulations on your paper "WhiteningBERT: An Easy Unsupervised Sentence Embedding Approach" being accepted at EMNLP21.
However, I've found that your paper is nearly identical in method to my blog post published on January 11, 2021, at https://kexue.fm/archives/8069 — even the final naming of the method is almost exactly the same. I therefore have reason to doubt the originality of your method.
As such, I believe it is necessary for you to provide evidence that your work is indeed independently original (for example, manuscript editing records proving that your work began before January 11). If not, I request that you withdraw the paper from EMNLP and issue a public apology. If there is no response to either of these two points, I will have no choice but to initiate a public discussion online.
Looking forward to your reply.
Since I had just learned of this at the time and was somewhat emotional, the wording was not very friendly — I apologize for that. Later that same day, the first author of WhiteningBERT replied to me:
Hello,
Thank you for your letter, and for your attention to our work!
First, we believe that our work (submitted to Arxiv on April 5, 2021) and your "Whitening Sentence Representations for Better Semantics and Faster Retrieval" (submitted to Arxiv on March 29, 2021) constitute concurrent work. The two papers have similarities, but the claims we wish to make and the story we tell are not nearly identical, which is mentioned and cited in our paper.
Second, regarding research on unsupervised sentence representations, we had already been working on this as early as last year. We hoped to obtain unsupervised sentence representations based on existing pretrained models, and explored multiple approaches such as inter-layer combination, data augmentation, introducing graph structures, linear transformations, pretraining, knowledge transfer, and so on, and experimented with them on some sentence semantic similarity tasks. Some methods that didn't work aren't mentioned, and in the end we arrived at three simple and useful conclusions, which we summarized into this experimental paper. As for the final name WhiteningBERT, it was chosen because one of our methods used PCA whitening — admittedly this name is a bit clickbait-y, but for convenience we ultimately renamed it WhiteningBERT when writing the paper. (Our original name was MatchingBERT — the screenshot below shows that some of the files' last modification times were in July 2020.)
Third, regarding the originality of the method, we never claimed that the PCA whitening algorithm was our own invention. In fact, all three methods in our conclusions are quite simple, and many papers and tutorials have introduced whitening methods before, so we admit that the novelty is limited.
Finally, regarding the content similarity you mentioned (including the blog post you cited) and the concern about insufficient novelty — during the EMNLP2021 review process, reviewers already raised and discussed this, and the PC, including the final SPC, were aware of the whole background. But in the end they still decided to accept the paper, which I believe suggests that the PC still found value in our work.
Best regards
The reply also included two screenshots:
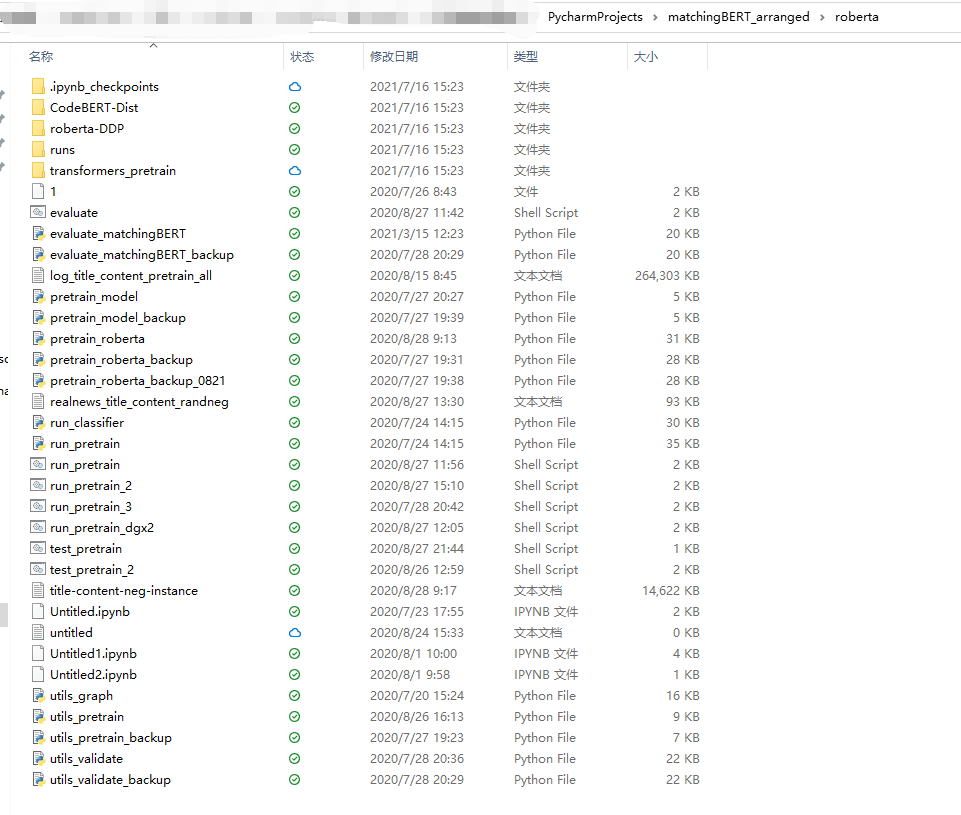 Screenshot 1: MatchingBERT project timestamps
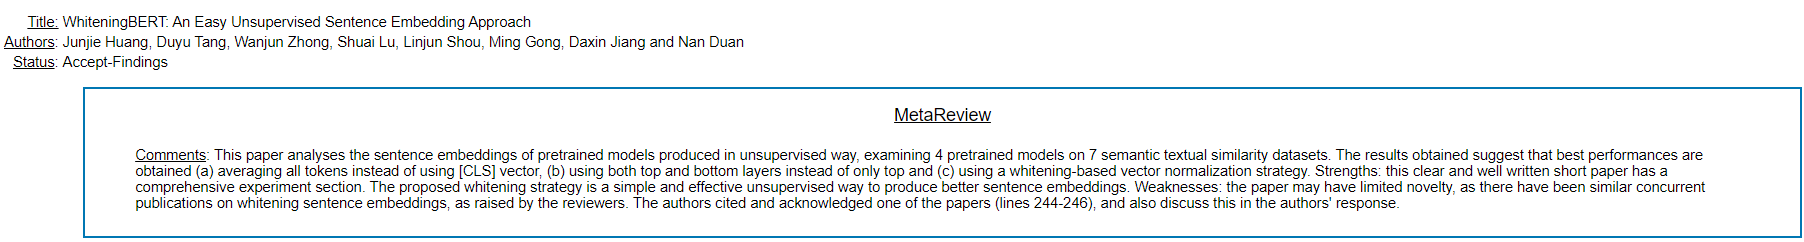 Screenshot 2: Meta review screenshot
At this point, I was quite grateful that the first author was willing to actively communicate on this issue. However, the first author's reply did not resolve my doubts, so I replied again that same day:
Hello,
Thank you for your reply. However, what I'm questioning is not your novelty — I'm questioning your originality.
1. I know Microsoft has many people specifically researching various NLP tasks, but this doesn't negate my doubt;
2. Screenshot 1 can only serve as very weak evidence that you were working on something called "MatchingBERT" early on, but I have no way of confirming what the content of MatchingBERT itself actually was;
3. Screenshot 2 likewise does not negate my doubt.
As for "the PC, including the final SPC, were aware of the whole background" — do you mean that the PC and SPC, knowing that "a Chinese blog post introduced the same method more than two months before WhiteningBERT was submitted to Arxiv; and an English paper introduced the same method a week before WhiteningBERT was submitted to Arxiv," still didn't question your originality and accepted the paper anyway?
The above exchange all took place on September 26. After that, up until October 5, I still had not received any response from any of the WhiteningBERT authors, so I emailed all the authors again to follow up:
Dear authors, sorry to disturb your National Day holiday spirit.
After I raised my concerns to you, the first author replied to me that same day, and I promptly replied to the first author's email — the full exchange is attached below. But since my reply, I have not received any further response from any of the authors. In the spirit of science, I do not wish to cause any misunderstanding, so I would like to further confirm the relevant details of this matter. So, forgive me for bothering you once more — are you certain there will be no further response to this matter?
Soon after, the first author replied to me by email:
Hello,
We have currently requested our company's legal department to evaluate this matter, and the legal department will respond regarding it. Since it is currently the National Day holiday, we hope you understand!
Best regards,
Personal Views
Honestly, receiving this email from the first author left me with very mixed feelings — shock, confusion, and a bit of speechlessness. Initially, I wasn't even sure how serious this matter was, so I decided to send an email inquiry first, to avoid any misunderstanding or awkwardness later. If the authors could demonstrate the independent origin of WhiteningBERT, that would have been a happy outcome for everyone, giving both readers and myself a satisfactory explanation. Instead, the authors have delayed responding directly to this question, and instead turned to consulting their legal department — what kind of move is that?
As I mentioned earlier when describing the timeline, when we decided to write up BERT-whitening and submit it to ACL2021, there was less than two weeks left before the deadline. Yet in that less-than-two-week span, we managed to complete the experiments and write the paper (even with our rather weak English). So, if WhiteningBERT really was proposed before BERT-whitening, then with such a strong lineup of authors, surely they should have been able to finish the experiments and paper long ago — or at the very least, after the BERT-whitening blog post was published, they should have posted their own paper to Arxiv to demonstrate their originality? How is it such a coincidence that they waited until after the English BERT-whitening paper appeared on Arxiv to release their own?
Of course, even with these doubts, we still cannot definitively characterize this matter — for no other reason than that BERT-whitening is simple enough that independently arriving at the same result cannot be ruled out. That's precisely why the email exchange happened. So we're back to the authors' "mysterious move" — what exactly was the reasoning behind handing this off to the legal department?
In fact, this matter itself is hard to substantiate with concrete evidence of plagiarism, so even if the WhiteningBERT authors don't respond at all, there's no legal risk involved for them. The reason I hoped the authors could provide relevant proof was purely a moral appeal, not an attempt to "bring anyone to justice." This is a scientific matter, not a public-relations matter. So even if the legal department can eliminate any legal risk for the authors, if the authors continue to refuse to provide substantive proof, how can the doubts in the minds of readers and myself ever be resolved?
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.