On the Usability of the Dimensionality Formula "n > 8.33 log N"
In an earlier post, The Minimum Entropy Principle (VI): How Should We Choose the Dimension of Word Embeddings?], we derived a word embedding dimension formula, "$n > 8.33\log N$," based on the idea of minimum entropy. Then, in The Astonishing Johnson-Lindenstrauss Lemma: Applications], we further pointed out that this result agrees with the $\mathcal{O}(\log N)$ given by the JL lemma.
Since the theory looks quite elegant, a natural question from readers is: how does it hold up experimentally? Is the coefficient 8.33 optimal? This post gives a brief summary of related findings on this question.
Word Embeddings
First, let's just plug in numbers directly: when $N$ is 100,000, $8.33\log N\approx 96$; when $N$ is 5,000,000, $8.33\log N\approx 128$. This shows that, at least at the order-of-magnitude level, the formula's output matches quite well with the dimensions we actually use in practice — back in the word embedding era, the embeddings we trained ourselves were typically around 100 dimensions. Some readers might object: most open-source word embeddings today are 300-dimensional, and BERT's embedding layer even reaches 768 dimensions — doesn't that clearly deviate from your result? more
In fact, the fact that open-source embeddings like FastText are 300-dimensional doesn't rule out the possibility that 128 dimensions could achieve similar performance. As for BERT, it isn't really a word embedding model to begin with, so the number of dimensions it chooses has no direct bearing on the choice of word embedding dimension. Moreover, ALBERT has already shown that low-rank factorization of the embedding layer (reducing it to 128 dimensions) barely changes model performance, which suggests that BERT's 768-dimensional embeddings are, to some extent, redundant.
As for the evaluation of word embeddings, there's a fairly comprehensive 2015 paper, How to Generate a Good Word Embedding?], worth consulting. It shows that improvements from word embeddings tend to plateau once dimensionality exceeds about 50 — which can also serve as a piece of supporting evidence for $n > 8.33\log N$.
Attention
Another piece of indirect experimental evidence for the formula $n > 8.33\log N$ comes from the attention mechanism. As we analyzed in The Astonishing Johnson-Lindenstrauss Lemma: Applications], the computation formula for the attention matrix is mathematically equivalent to the Skip-Gram model for word embeddings. This means that the formula $n > 8.33\log N$ can equally be applied to the question of choosing head_size in attention mechanisms.
In the attention mechanism, $N$ should be taken as the sequence length. A common pretraining length is 512; substituting this in gives $8.33\log 512\approx 52$, which is very close to the current mainstream head_size of $64$. This indirectly confirms the usability of $n > 8.33\log N$. Conversely, if we accept this formula, it explains why the head_size in attention only needs to be 64, and it also indirectly explains why attention mechanisms use multiple small heads rather than a single large head.
For more on the relationship between head_size choice and expressive power in attention mechanisms, see On the Expressive Power of Self-Attention Matrices].
Graph Networks
If we treat each word as a node and the co-occurrence between words as an edge, then Skip-Gram can also be viewed as a simple graph model. So, in principle, the results on choosing word embedding dimension should also apply to choosing embedding dimensions in graph networks.
For results along these lines, see the paper Graph Entropy Guided Node Embedding Dimension Selection for Graph Neural Networks], which considers both the feature entropy and the structural entropy of a graph. The feature entropy part is similar to Skip-Gram, adopting the same approximation as in The Minimum Entropy Principle (VI): How Should We Choose the Dimension of Word Embeddings?], so this part is essentially the same formula $n > 8.33\log N$.
By combining the feature entropy and structural entropy, and using the resulting computed value as the embedding dimension for graph networks across a range of graph tasks, the experimental results show that this method indeed yields a fairly optimal choice of dimension:
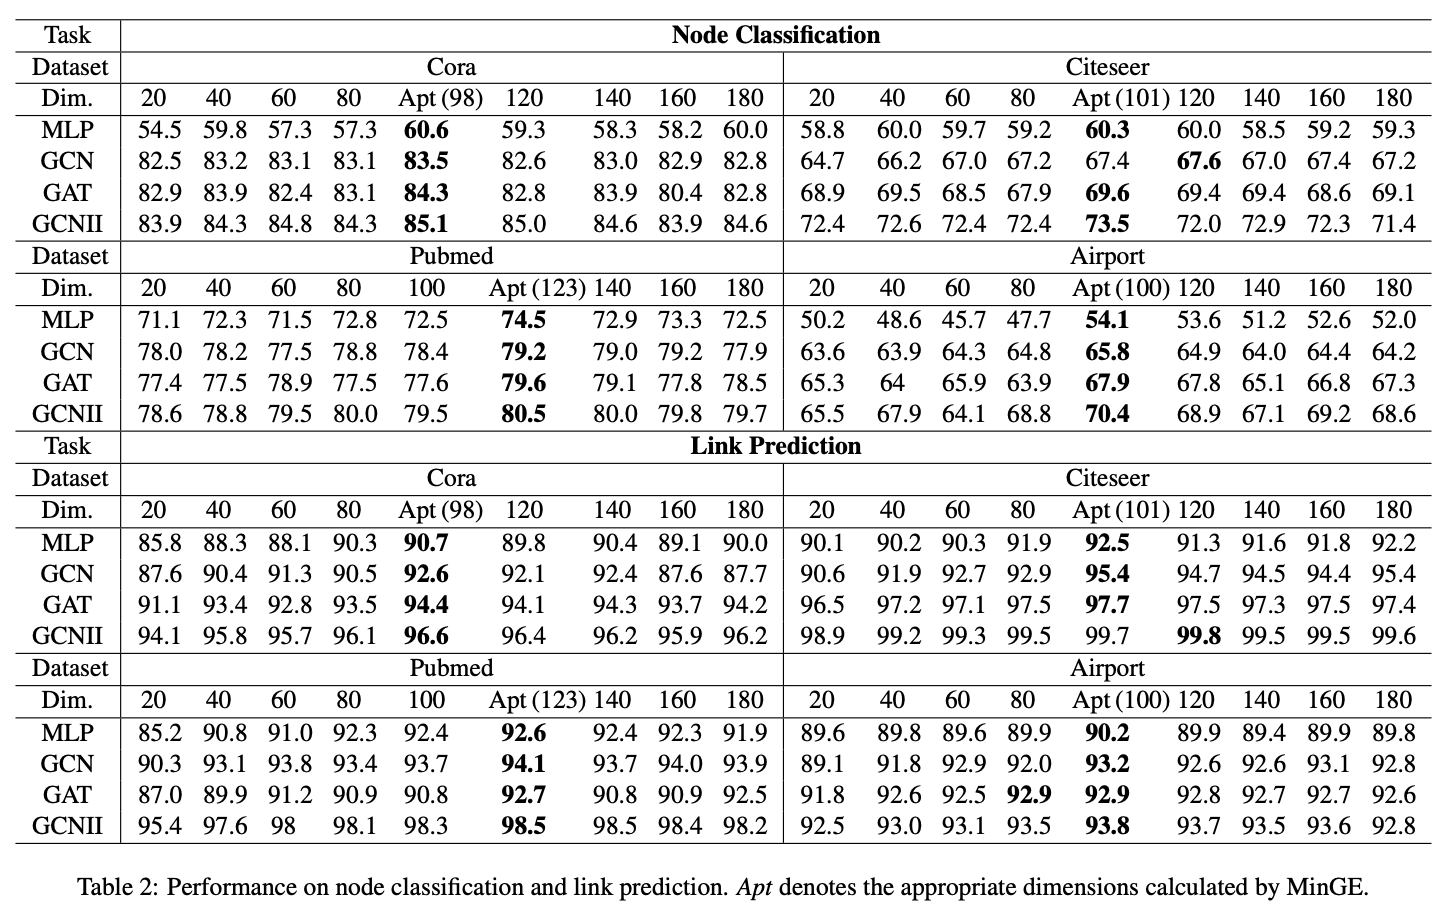 Entropy-based dimension selection
Brief Summary
This post has examined the usability of the previously derived dimension-selection formula $n > 8.33\log N$, drawing together existing experimental results from word embeddings, attention, and graph networks. These results show that the formula yields reasonably sensible dimension estimates, and also suggest that determining the constant $\log N$ in the JL lemma via entropy may be a viable approach.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.