A Roundup of Some Recent Non-Transformer Work
Lately everyone has probably had their eyeballs "swept up" to some degree by a wave of MLP-related work. A number of research institutions—Google chief among them—have been pulling off one bold move after another, trying to "attack" the Transformer model from multiple angles. The fiercest of these are the models billed as "pure MLP," which almost give one the feeling that an era of "MLP is all you need" has arrived.
Behind this dazzling flurry of moves, is it a case of "returning to simplicity" through the principle that great truths are simple, or is it "reheating leftovers" once the well of ideas has run dry? Let's ride this wave of enthusiasm and take stock of some of the recent related work.
Busy Days in May
Strange things happen every day, but May has had more than its share. Since the start of this month, it seems as if all the major institutions made a pact: one non-Transformer work after another has come out, as if "spring winds arrived overnight, and a thousand pear trees bloomed." Just among the papers the author happened to come across on Arxiv, there are already as many as seven (and the month isn't even over yet—seven papers all pointed in an extremely similar direction), spanning multiple tasks including NLP and CV, truly more than one can keep up with: more
MLP-Mixer: An all-MLP Architecture for Vision - Google Research
Beyond Self-attention: External Attention using Two Linear Layers for Visual Tasks - Tsinghua University
Do You Even Need Attention? A Stack of Feed-Forward Layers Does Surprisingly Well on ImageNet - Oxford University
Are Pre-trained Convolutions Better than Pre-trained Transformers? - Google Research
ResMLP: Feedforward networks for image classification with data-efficient training - Facebook AI
FNet: Mixing Tokens with Fourier Transforms - Google Research
Pay Attention to MLPs - Google Research
The papers above are listed in the order in which they appeared on arXiv. As you can see, the main force is still Google. Google was the one who set off the "Attention is all you need" trend back in the day, and now it's Google again delivering the "heavy blows" against the Transformer—truly a company that never stops digging new holes for itself.
Chatting Over Wine
So what insights can we actually draw from this line of work? Should we hurry to jump on this bandwagon? In this section, let's briefly walk through the papers above, see what they're really about, and consider whether they might spark a genuinely new modeling trend.
Synthesizer
To interpret the MLP-related work above, we have to mention Google's Synthesizer, published in Synthesizer: Rethinking Self-Attention in Transformer Models last May. In fact, if you're already familiar with Synthesizer, several of the papers in the list above can be summarized in a single line.
In an earlier post, Google's New Work Synthesizer: We Still Don't Understand Self-Attention Well Enough, we already gave a brief interpretation of Synthesizer. Setting aside the scaling factor, attention computation can be decomposed as
\begin{equation}\boldsymbol{O}=\boldsymbol{A}\boldsymbol{V},\quad \boldsymbol{A}=softmax(\boldsymbol{B}),\quad \boldsymbol{B}=\boldsymbol{Q}\boldsymbol{K}^{\top}\end{equation}
where $\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V}$ is a transformation of the input sequence—something anyone familiar with self-attention should already know, so I won't spell it out. Synthesizer experimented with several new algorithms for $\boldsymbol{B}$, the most striking of which is called Random: it treats the entire $\boldsymbol{B}$ as a parameter matrix (either randomly initialized and then updated, or fixed).
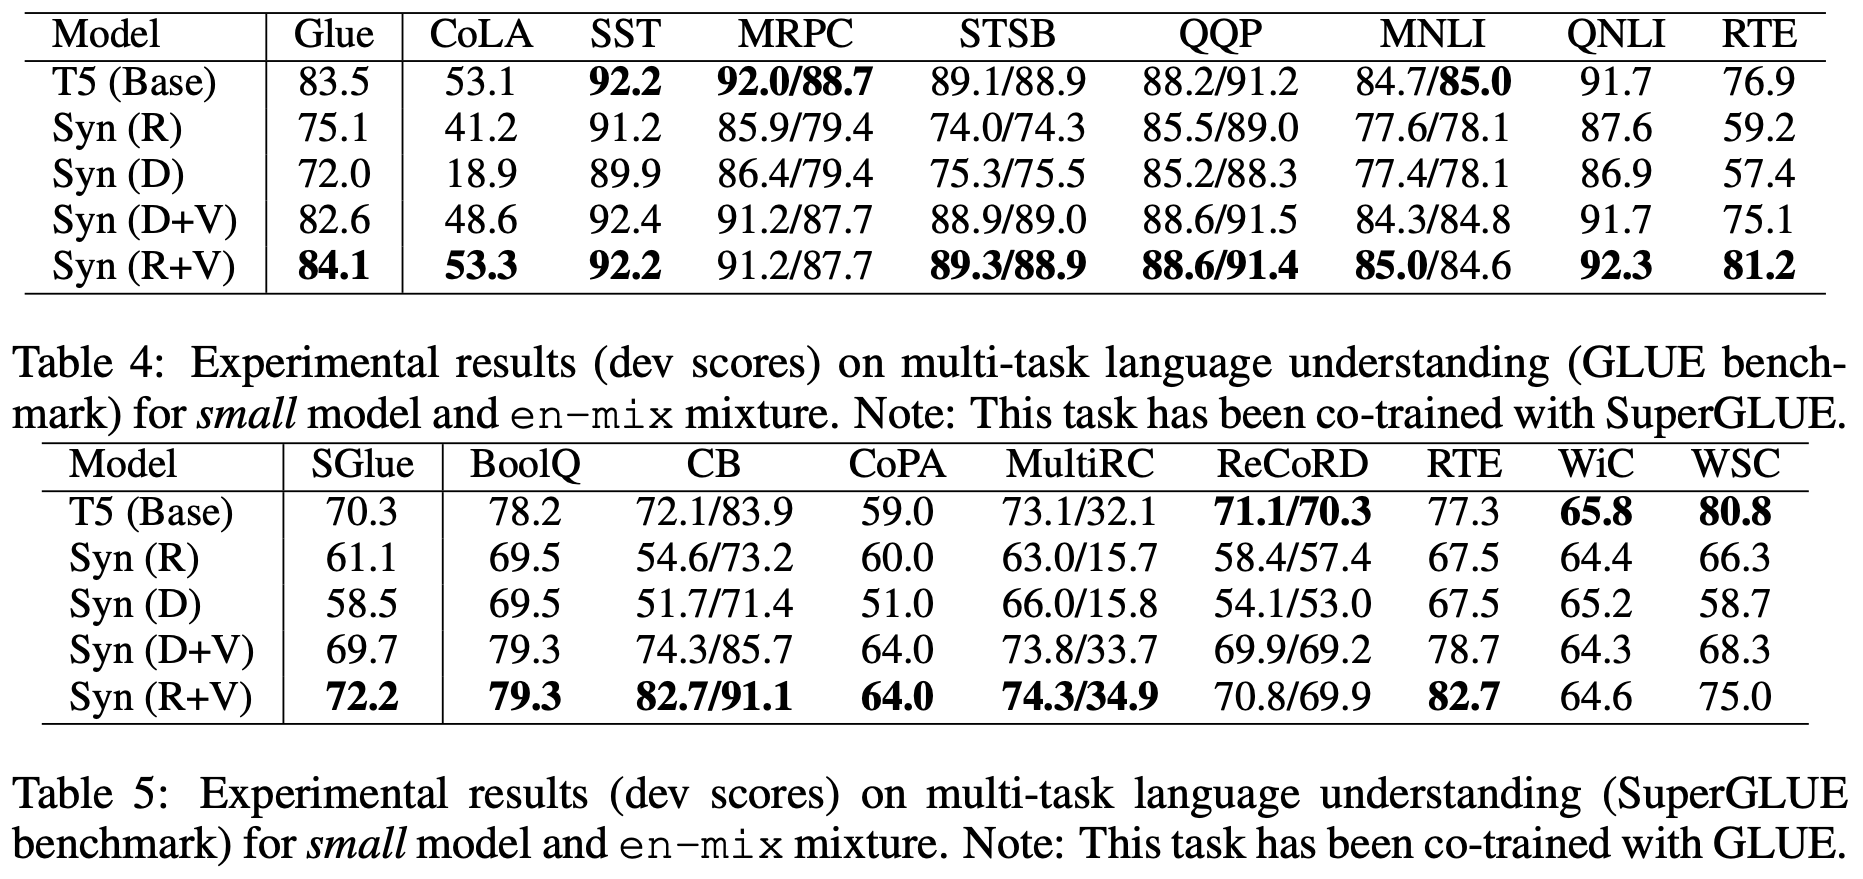 Synthesizer's pretraining + fine-tuning experimental results. The baseline is T5, where "R" is the Random mode, equivalent to an MLP.
In the Random setting, the attention matrix no longer varies with the input sample—all samples share the same attention matrix—yet it still achieves solid results, which at the time was a real shock to people's intuitive understanding of attention. Synthesizer's experiments were quite extensive, covering machine translation, summarization, dialogue generation, and pretraining + fine-tuning. In fact, most of the papers listed above have far less extensive experiments than Synthesizer did.
MLP-Mixer
Synthesizer probably never expected that, a year later, it would get a new name and suddenly become popular.
The MLP-Mixer proposed in MLP-Mixer: An all-MLP Architecture for Vision is, in essence, Synthesizer's Random mode with the softmax activation removed. That is, it sets $\boldsymbol{B}$ as a trainable parameter matrix and then simply computes $\boldsymbol{A}=\boldsymbol{B}$. That's basically the whole model. Aside from that, the only difference is that MLP-Mixer targets CV tasks while Synthesizer targets NLP tasks.
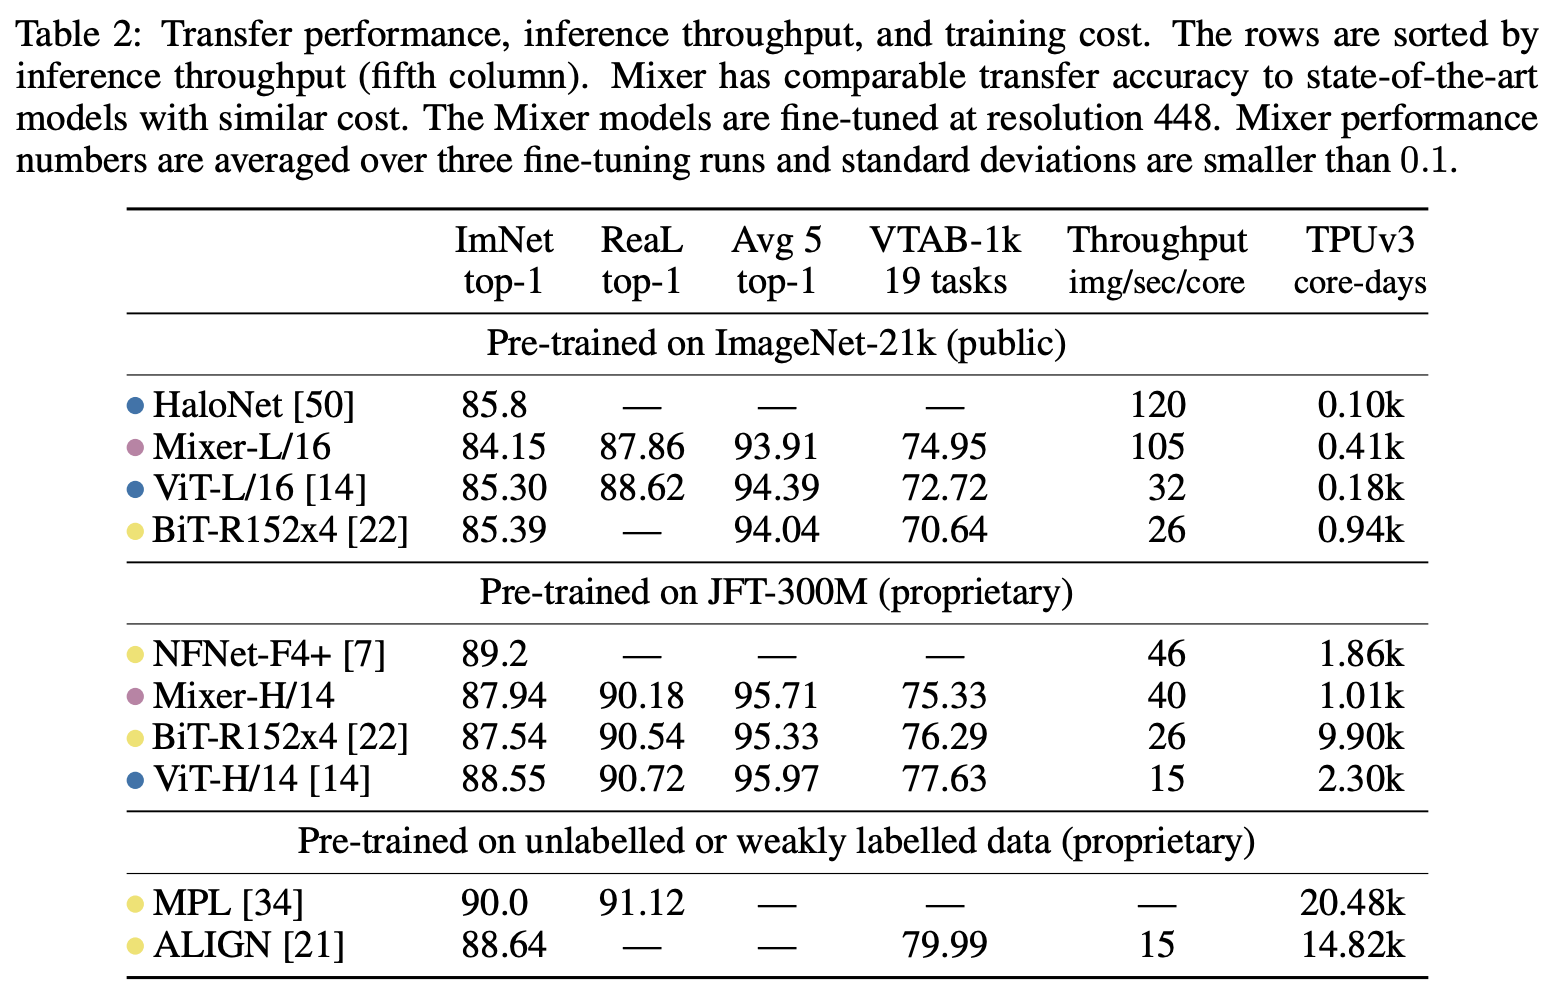 Partial experimental results of MLP-Mixer
By the way, as for why this model is called MLP-Mixer: the authors gave this directly-trainable attention pattern the name "token-mixing MLP," and renamed the original FFN as "channel-mixing MLP" (previously known as a position-wise FC). Whatever you call it, it's marketed as "just MLP," hence the model name MLP-Mixer.
In fact, the author thinks a more standard way to describe this would be "a 1D convolution with window size 1." But whether it's this paper or the earlier Attention Is All You Need, both went out of their way to invent their own names for otherwise ordinary operations, deliberately downplaying—or even ignoring—their connection to convolution. It seems no effort was spared in pursuit of "A Good Title Is All You Need."
Interestingly, this exact point drew criticism from LeCun: if it's really supposed to be a standard MLP, the input should be flattened into a one-dimensional vector before being passed through a transformation matrix.
External Attention
From an analogical standpoint, Synthesizer's Random mode, or MLP-Mixer, is equivalent to setting both $\boldsymbol{Q}$ and $\boldsymbol{K}$ in attention to parameter matrices. The External Attention proposed in Beyond Self-attention: External Attention using Two Linear Layers for Visual Tasks, meanwhile, sets $\boldsymbol{K}$ and $\boldsymbol{V}$ to (fixed-size) parameter matrices, again with experiments on CV tasks.
There'd be nothing wrong with this in itself—after all, in deep learning, results are king, and if the results are good, you get a paper. But personally, I think a lot of the claims in the External Attention paper don't hold up well under scrutiny.
First, it calls itself "two linear layers," deliberately downplaying its connection to attention (is admitting it's a special case of attention that embarrassing?). Then it claims that "by introducing two external memory units (i.e., $\boldsymbol{K}$ and $\boldsymbol{V}$ set as parameters), it implicitly learns the features of the entire dataset"—this claim isn't exactly wrong, but in fact any parameter of any model could be described this way; it's not a distinguishing feature of External Attention. It also claims to achieve linear complexity, but that requires fixing the length of $\boldsymbol{K},\boldsymbol{V}$—in which case it really should be compared against LinFormer, which also achieves linear complexity (the paper compares against Performer instead, but Performer reduces complexity through a different mechanism, so LinFormer would be the more meaningful comparison).
Setting the wording issues aside, the working mechanism of External Attention still seems a bit puzzling. It's not hard to see that External Attention encodes each feature in isolation—translated to NLP terms, that would mean each word is encoded independently, with no interaction with context at all, which surely shouldn't work. So why does it work in CV?
Stack of FFN
As for the paper Do You Even Need Attention? A Stack of Feed-Forward Layers Does Surprisingly Well on ImageNet, it's highly overlapping with MLP-Mixer, though written in a much more verbose way. It simply passes the input through a regular FFN, transposes the output, passes it through another FFN, then transposes back. If you're already familiar with Transformers, you can quickly see what's going on here.
The paper itself is quite short—only 4 pages total, including 1 page of code and half a page of references, leaving really just 2.5 pages of main text—more like a research note. Perhaps the authors themselves wanted to dig deeper into this direction, but Google's MLP-Mixer came out first, making further pursuit of the idea somewhat pointless, so they rushed to publish what they had. (This part of the story is purely the author's own speculation.)
Pre-trained CNN
As it happens, CNNs were actually the earliest models tried (for seq2seq tasks) as a replacement for RNNs—Facebook's Convolutional Sequence to Sequence Learning was published even earlier—but it was quickly overshadowed by Google's Attention Is All You Need. After GPT, BERT, and other models followed, Transformer-based models became the dominant mainstream, and CNNs received relatively little in-depth study.
The paper Are Pre-trained Convolutions Better than Pre-trained Transformers? helps confirm the effectiveness of "CNN + pretraining." According to the paper's results, whether trained directly with downstream supervision or pretrained-then-fine-tuned, CNN models based on dilated convolutions or dynamic convolutions slightly outperform Transformer models, and CNN models are also faster. By the way, this paper has already been accepted at ACL2021, so it was actually written well before this—it just happened to be released this month.
 Whether pretrained or not, CNNs show their own advantages
The main insight this paper gives us is: improvements from pretraining and improvements from model architecture shouldn't be conflated. Pretraining techniques often boost various models regardless of architecture; one shouldn't automatically associate pretraining with Transformers, nor should pretraining be combined only with Transformers. In fact, the author was rather fond of CNNs before as well, having used the design of "dilated gated CNN" (DGCNN) to achieve good results on multiple tasks, and this paper once again affirms the value of CNNs. That said, the author probably still won't shift primary focus toward CNN research.
First, theoretically speaking, CNNs are fundamentally incapable of capturing sufficiently long-range dependencies—this is an inherent limitation. Although dilated convolutions and similar tricks can quickly expand the CNN's receptive field, they only make it "relatively large," not achieve the theoretically complete, single-step coverage that Transformers provide. Second, purely from an efficiency standpoint, there's still plenty of room to optimize Transformers themselves; if the only reason to switch to CNNs is execution speed, that argument feels somewhat weak. Also, the $\mathcal{O}(n^2)$ complexity of Transformer attention actually opens up more room to tinker (as in UniLM), enabling many more creative variations (as in K-BERT).
Overall, we shouldn't deny the value of CNNs, but if one is already fairly focused on Transformers, there's no need to divert too much effort toward CNNs.
ResMLP
As for the ResMLP proposed by Facebook in ResMLP: Feedforward networks for image classification with data-efficient training, it's essentially no different from the aforementioned MLP-Mixer and Stack of FFN—its description reads very similarly to Stack of FFN too. Ignoring minor details, one could even consider the three models to be essentially the same. Finally, ResMLP's experiments are also on CV tasks.
FNet
In the author's view, the FNet proposed in FNet: Mixing Tokens with Fourier Transforms is the most interesting of the seven papers in the list. In a sense, FNet is also a special case of MLP-Mixer, but a very interesting one: MLP-Mixer's attention matrix is obtained through direct parameter optimization, whereas FNet's "parameter matrix" comes directly from a Fourier transform! So FNet's "attention layer" has no trainable parameters whatsoever!
We can actually understand FNet from an attention perspective too. Ignoring the normalization factor, attention computation can roughly be written as:
\begin{equation}\boldsymbol{O}=\boldsymbol{A}\boldsymbol{V},\quad \boldsymbol{A}=\exp(\boldsymbol{B}),\quad \boldsymbol{B}=\boldsymbol{Q}\boldsymbol{K}^{\top}\end{equation}
Here, $\boldsymbol{Q},\boldsymbol{K}$ is originally a $n\times d$ matrix. FNet says: $\boldsymbol{Q},\boldsymbol{K}$ can be replaced with a $n\times 1$ matrix:
\begin{equation}\boldsymbol{Q}=\boldsymbol{K}=\begin{pmatrix}0 \\ 1 \\ 2 \\ \vdots \\ n - 1\end{pmatrix}\end{equation}
Yes, you read that right—it just brazenly swaps it for a $n\times 1$ matrix made up of $0\sim n-1$. Of course, if you did that, $\exp(\boldsymbol{B})$ would explode exponentially as you go further along. To avoid this, FNet instead uses:
\begin{equation}\boldsymbol{A}=\exp(\text{i}\boldsymbol{B})\end{equation}
That is, by switching to imaginary exponents, there's no more explosion! Just this simple move gives us the Fourier-transform-based FNet. The original paper applies the Fourier transform along both the sequence-length and feature dimensions, keeps only the real part, and uses this operation to replace self-attention. As for computing the Fourier transform, we have the so-called "Fast Fourier Transform (FFT)" algorithm, with complexity $\mathcal{O}(n\log n)$, so FNet can also efficiently handle long sequences.
Some of FNet's results are shown in the table below. Looking purely at pretraining and downstream task performance, FNet has no real advantage, but its results on Long-Range Arena (a benchmark for testing a model's long-range capability) are actually quite good.
 FNet's pretraining + fine-tuning experimental results
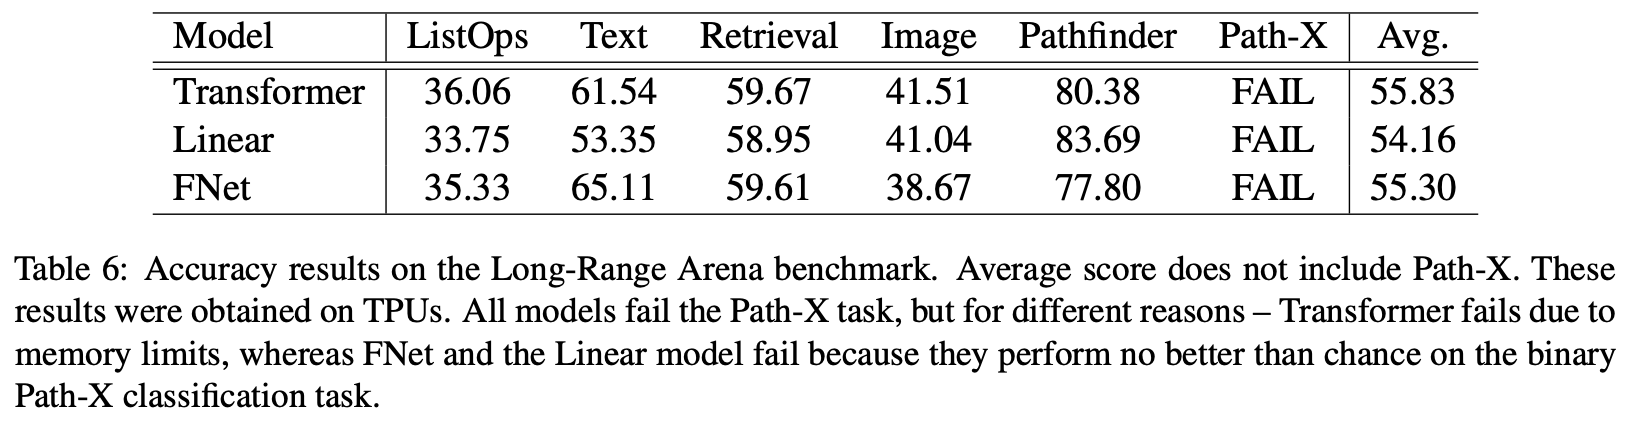 FNet's Long-Range Arena experimental results
Of course, the fact that FNet's brazen approach even works at all is already something of a miracle. The biggest shock it delivers is: even this works?! Why would a Fourier transform work here? The author doesn't know the answer either. Some commentary online suggests that this shows attention is fundamentally a kind of change of coordinate basis, and the Fourier transform is also a basis change, so the two play a similar role. This explanation does feel like it touches on something fundamental—there's also a paper at ICLR2021, Is Attention Better Than Matrix Decomposition?, which replaces attention with SVD and also achieves good results, further supporting the "basis change" interpretation (SVD is also a form of basis change). But how to preserve sequential order under a basis change, and which basis change is more suitable, remain completely open questions.
gMLP / aMLP
Finally, the gMLP and aMLP introduced in Pay Attention to MLPs represent fairly conventional exploration of new architectures—essentially an enhanced version of MLP-Mixer. The "g" in gMLP stands for "gate": simply put, gMLP combines MLP-Mixer with a gating mechanism, while the "a" in aMLP stands for "attention," combining attention with gMLP.
Specifically, gMLP roughly computes as follows:
\begin{equation}\begin{aligned} &[\boldsymbol{X}_1, \boldsymbol{X}_2] = \boldsymbol{X} \\ &\boldsymbol{Y} = \boldsymbol{W}\boldsymbol{X}_2 + \boldsymbol{b} \\ &\boldsymbol{O} = \boldsymbol{X}_1 \otimes \boldsymbol{Y} \end{aligned}\end{equation}
In short, the input is split in half along the feature dimension; one half is passed through an MLP-Mixer and used as the gate for the other half. aMLP, meanwhile, combines an MLP-Mixer with a simple single-head self-attention to serve as the gate:
\begin{equation}\begin{aligned} &[\boldsymbol{X}_1, \boldsymbol{X}_2] = \boldsymbol{X} \\ &\boldsymbol{Y}_1 = \boldsymbol{W}\boldsymbol{X}_2 + \boldsymbol{b} \\ &\boldsymbol{Y}_2 = SelfAttention(\boldsymbol{X}) \\ &\boldsymbol{O} = \boldsymbol{X}_1 \otimes (\boldsymbol{Y}_1 + \boldsymbol{Y}_2) \end{aligned}\end{equation}
The paper's experiments are fairly comprehensive, covering both CV and NLP. Based on the reported results, gMLP slightly underperforms standard self-attention, while aMLP generally outperforms self-attention, further confirming the value of the gating mechanism. That said, whether it's gMLP or aMLP, both feel heavily hand-engineered—good enough to pad out a paper, but personally I don't think they offer much new inspiration for the direction of model development.
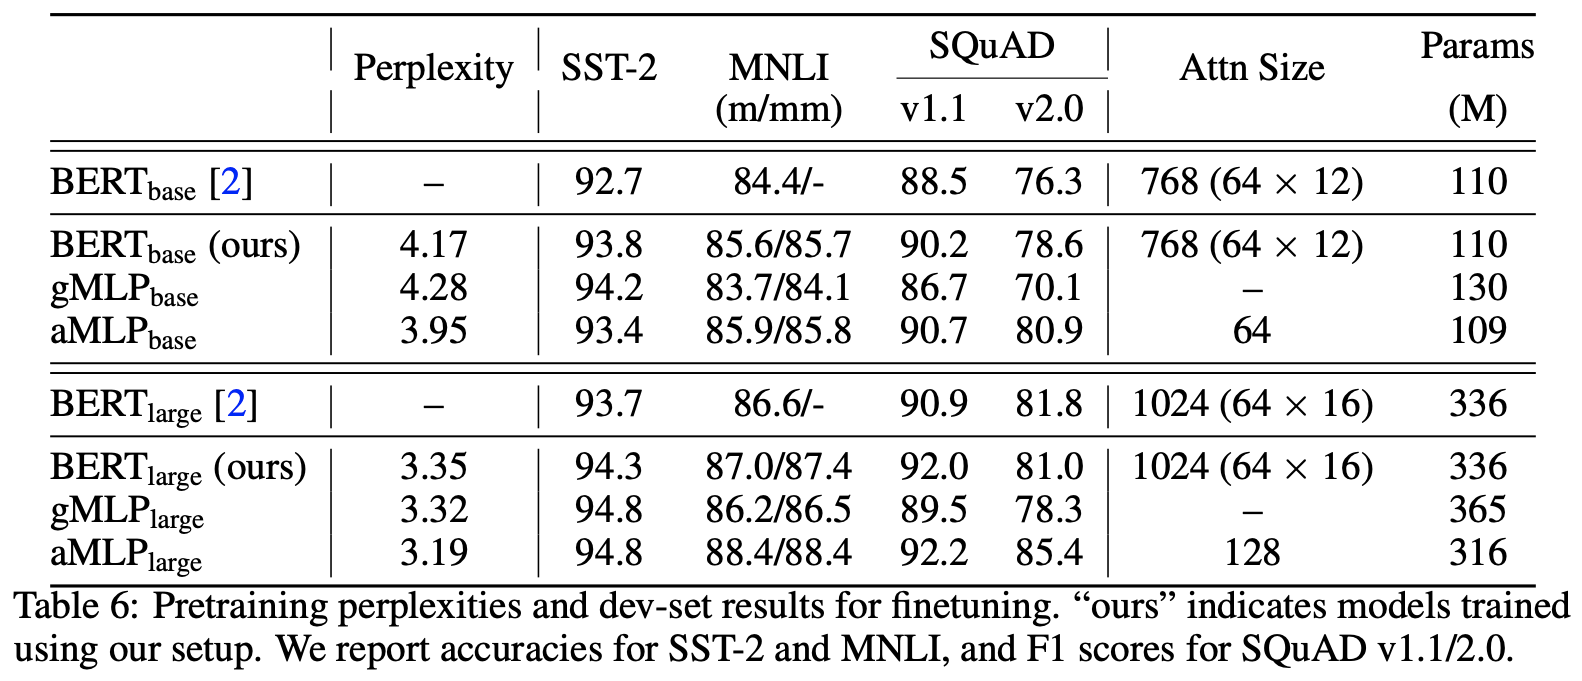 NLP experimental results for gMLP, aMLP
Where Does the Road Lead
From the above reading, we can see that MLP-Mixer, Stack of FFN, and ResMLP can, in fact, all be viewed as special cases of last year's Synthesizer—and technically speaking, they're even less rich in content than Synthesizer was, so they're really not that interesting as pieces of work. As for its improved versions, gMLP / aMLP, these are quite ordinary architecture-tinkering exercises—anyone with enough compute could do this—so they're not particularly interesting either. External Attention calls itself "two linear layers," but is in fact just a variant of attention, and its mechanism and experimental comparisons are not made entirely clear. The genuinely interesting works are CNN pretraining and FNet: one decouples the concepts of "pretraining improvement" and "model improvement," while the other's use of the Fourier transform delivers a real conceptual jolt.
Overall, this body of work is still far from mature—at best, it provides preliminary validation of effectiveness, and it can't even be called elegant yet. For instance, apart from FNet, none of these so-called "all-MLP" models can elegantly handle variable-length inputs. MLP-Mixer, Stack of FFN, and ResMLP simply run experiments on (fixed-size) images, so they don't need to worry about this issue; Synthesizer / gMLP / aMLP do run NLP experiments, but they all appear to rely on forced truncation, which isn't exactly elegant. So while this line of work has, to some extent, opened up new avenues of thought, it has really left us with more open questions than answers.
So should we jump on this bandwagon? Personally, I don't think it's worth investing much effort—keeping half an eye on it should suffice. Setting aside the elegance issues mentioned above, the practical value of this work is itself questionable. The main supposed benefit of replacing attention with MLP is speed—and sure, it is a bit faster—but the theoretical complexity is still $\mathcal{O}(n^2)$, which means there's no fundamental improvement, and the speedup usually comes at some cost in performance. If the goal is purely "faster but slightly worse," there's plenty that can be done directly with the Transformer itself (the simplest being to remove a layer or two)—there's no need to switch to MLPs, and doing so actually reduces the degrees of freedom for exploration. Of course, from a purely exploratory, academic standpoint, it's meaningful to try new models from many angles, but this shouldn't be mixed with too much artificial engineering, or it turns into a process of structurally overfitting to the task—which is hard to take seriously.
Moreover, for NLP, what we probably care most about is performance in the "pretraining + fine-tuning" setting. Unfortunately, a series of NLP experiments starting from Synthesizer shows that models replacing attention with MLP might achieve competitive results on some particular task, but their transferability tends to be poor—that is, the pretraining results alone might look decent, but "pretraining + fine-tuning" performance usually falls short of Transformers. This isn't hard to understand: by turning the attention matrix into a fixed parameter, that matrix becomes more strongly tied to the specific task, unlike the adaptively generated attention matrix in Transformers, which has much better adaptability.
When the Music Stops
This post reviewed some recent "non-mainstream" work, mainly efforts to replace Transformers with MLP-based, non-Transformer architectures and achieve competitive results. Overall, while this body of work looks varied on the surface, there's a common thread running through it, and it does feel a bit like "old wine in new bottles"—not much of it offers genuinely new insight.
This entire piece represents only the author's own musings from behind closed doors, and reflects only personal opinions. If there are any inaccuracies, readers' understanding and correction would be much appreciated.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.