Transformer Upgrade Path: 1. Tracing the Origins of Sinusoidal Positional Encoding
I've recently been experimenting with understanding and improving Transformers, and have arrived at some experience and conclusions that seem worth sharing. So I'm starting a series to summarize these, which I'll call "Transformer Upgrade Path" — the name represents both a deepening of understanding and improvements in results.
As the first article in this series, I'll present my new understanding of the Sinusoidal positional encoding proposed by Google in Attention is All You Need:
\begin{equation}\left\{\begin{aligned}&\boldsymbol{p}_{k,2i}=\sin\Big(k/10000^{2i/d}\Big)\\ &\boldsymbol{p}_{k, 2i+1}=\cos\Big(k/10000^{2i/d}\Big) \end{aligned}\right.\label{eq:sin}\end{equation}
where $\boldsymbol{p}_{k,2i},\boldsymbol{p}_{k,2i+1}$ are respectively the $2i,2i+1$-th component of the encoding vector for position $k$, and $d$ is the vector dimension.
As an explicit solution for positional encoding, Google's original paper devotes remarkably little discussion to it, only briefly mentioning that it can express relative positional information. Later, some interpretations appeared on platforms like Zhihu, and some of its properties gradually became well known, but overall the picture remains rather fragmented. In particular, for foundational questions like "how was this actually derived?" and "does it really have to take this form?", there hasn't been a very satisfying answer.
So this article focuses on exactly these questions. As you read through the reasoning, you may well end up sharing my feeling — the more you think about it, the more you marvel at how ingenious and elegant this design really is~ more
Taylor Expansion
Suppose our model is $f(\cdots,\boldsymbol{x}_m,\cdots,\boldsymbol{x}_n,\cdots)$, where the marked $\boldsymbol{x}_m,\boldsymbol{x}_n$ denotes the $m,n$-th input. Without loss of generality, let $f$ be a scalar function. For a pure attention model without an attention mask, the model is fully symmetric, meaning for any $m,n$ we have
\begin{equation}f(\cdots,\boldsymbol{x}_m,\cdots,\boldsymbol{x}_n,\cdots)=f(\cdots,\boldsymbol{x}_n,\cdots,\boldsymbol{x}_m,\cdots)\end{equation}
This is exactly why Transformers cannot perceive position — full symmetry. In simple terms, the function naturally satisfies the identity $f(x,y)=f(y,x)$, so we cannot tell from the output whether the input was $[x,y]$ or $[y,x]$.
So what we need to do is break this symmetry — for instance, by adding a distinct encoding vector at each position:
\begin{equation}\tilde{f}(\cdots,\boldsymbol{x}_m,\cdots,\boldsymbol{x}_n,\cdots)=f(\cdots,\boldsymbol{x}_m + \boldsymbol{p}_m,\cdots,\boldsymbol{x}_n + \boldsymbol{p}_n,\cdots)\end{equation}
Generally speaking, as long as the encoding vector differs at each position, this full symmetry is broken, meaning we can use $\tilde{f}$ in place of $f$ to handle ordered input. But now we want to go further and analyze the properties of positional encoding, even obtain an explicit solution, so we can't stop here.
To simplify the problem, let's first consider only the positional encodings at the two positions $m,n$, treating them as perturbation terms, and expand via Taylor series to second order:
\begin{equation}\tilde{f}\approx f + \boldsymbol{p}_m^{\top} \frac{\partial f}{\partial \boldsymbol{x}_m} + \boldsymbol{p}_n^{\top} \frac{\partial f}{\partial \boldsymbol{x}_n} + \frac{1}{2}\boldsymbol{p}_m^{\top} \frac{\partial^2 f}{\partial \boldsymbol{x}_m^2}\boldsymbol{p}_m + \frac{1}{2}\boldsymbol{p}_n^{\top} \frac{\partial^2 f}{\partial \boldsymbol{x}_n^2}\boldsymbol{p}_n + \underbrace{\boldsymbol{p}_m^{\top} \frac{\partial^2 f}{\partial \boldsymbol{x}_m \partial \boldsymbol{x}_n}\boldsymbol{p}_n}_{\boldsymbol{p}_m^{\top} \boldsymbol{\mathcal{H}} \boldsymbol{p}_n}\end{equation}
As we can see, the first term is position-independent, and terms 2 through 5 each depend on only a single position, so they carry purely absolute positional information. The sixth term is the first one that involves both $\boldsymbol{p}_m,\boldsymbol{p}_n$ simultaneously — we denote it $\boldsymbol{p}_m^{\top} \boldsymbol{\mathcal{H}} \boldsymbol{p}_n$ — and we hope it can express some relative positional information.
(This Taylor expansion follows the response by 纳米酱 to the Zhihu question Why does BERT use learned position embeddings instead of sinusoidal position encoding?.)
Relative Position
Let's start with a simple example: suppose $\boldsymbol{\mathcal{H}}=\boldsymbol{I}$ is the identity matrix, so that $\boldsymbol{p}_m^{\top} \boldsymbol{\mathcal{H}} \boldsymbol{p}_n = \boldsymbol{p}_m^{\top} \boldsymbol{p}_n = \langle\boldsymbol{p}_m, \boldsymbol{p}_n\rangle$ is simply the inner product of two positional encodings. We would like this term, in this simple case, to express relative positional information — that is, we want there to exist some function $g$ such that
\begin{equation}\langle\boldsymbol{p}_m, \boldsymbol{p}_n\rangle = g(m-n)\label{eq:r1}\end{equation}
Here $\boldsymbol{p}_m, \boldsymbol{p}_n$ is a $d$-dimensional vector; let's begin with the simplest case $d=2$.
For a 2-dimensional vector, we can use complex numbers to carry out the derivation, treating the vector $[x,y]$ as the complex number $x + y\text{i}$. Using the rules of complex multiplication, we readily obtain:
\begin{equation}\langle\boldsymbol{p}_m, \boldsymbol{p}_n\rangle = \text{Re}[\boldsymbol{p}_m \boldsymbol{p}_n^*]\end{equation}
where $\boldsymbol{p}_n^*$ is the complex conjugate of $\boldsymbol{p}_n$, and $\text{Re}[]$ denotes the real part of a complex number. To satisfy equation $\eqref{eq:r1}$, we can suppose there exists a complex number $\boldsymbol{q}_{m-n}$ such that
\begin{equation}\boldsymbol{p}_m \boldsymbol{p}_n^* = \boldsymbol{q}_{m-n}\end{equation}
Taking the real part of both sides then gives us equation $\eqref{eq:r1}$. To solve this equation, we can use the exponential form of complex numbers, i.e., setting $\boldsymbol{p}_m=r_m e^{\text{i}\phi_m}, \boldsymbol{p}_n^*=r_n e^{-\text{i}\phi_n}, \boldsymbol{q}_{m-n}=R_{m-n} e^{\text{i}\Phi_{m-n}}$, which gives
\begin{equation}r_m r_n e^{\text{i}(\phi_m - \phi_n)} = R_{m-n} e^{\text{i}\Phi_{m-n}}\quad\Rightarrow\quad \left\{\begin{aligned}&r_m r_n = R_{m-n}\\ & \phi_m - \phi_n=\Phi_{m-n}\end{aligned}\right.\end{equation}
For the first equation, substituting $n=m$ gives $r_m^2=R_0$, meaning $r_m$ is a constant — for simplicity let's set it to 1. For the second equation, substituting $n=0$ gives $\phi_m - \phi_0=\Phi_m$; for simplicity set $\phi_0=0$, so $\phi_m=\Phi_m$, i.e., $\phi_m - \phi_n=\phi_{m-n}$. Substituting into $n=m-1$ gives $\phi_m - \phi_{m-1}=\phi_1$, so $\{\phi_m\}$ is simply an arithmetic sequence, with general solution $m\theta$. Therefore, in the 2-dimensional case we obtain the solution for positional encoding:
\begin{equation}\boldsymbol{p}_m = e^{\text{i}m\theta}\quad\Leftrightarrow\quad \boldsymbol{p}_m=\begin{pmatrix}\cos m\theta \\ \sin m\theta\end{pmatrix}\end{equation}
Since inner products satisfy linear superposition, we can express higher, even-dimensional positional encodings as a combination of multiple 2-dimensional positional encodings:
\begin{equation}\boldsymbol{p}_m = \begin{pmatrix}e^{\text{i}m\theta_0} \\ e^{\text{i}m\theta_1} \\ \vdots \\ e^{\text{i}m\theta_{d/2-1}}\end{pmatrix}\quad\Leftrightarrow\quad \boldsymbol{p}_m=\begin{pmatrix}\cos m\theta_0 \\ \sin m\theta_0 \\ \cos m\theta_1 \\ \sin m\theta_1 \\ \vdots \\ \cos m\theta_{d/2-1} \\ \sin m\theta_{d/2-1} \end{pmatrix}\label{eq:r2}\end{equation}
This likewise satisfies equation $\eqref{eq:r1}$. Of course, this is only a solution to equation $\eqref{eq:r1}$, not the unique one — but for our purposes, finding one simple solution is enough.
Long-Range Decay
Based on the assumptions above, we've derived the form of positional encoding $\eqref{eq:r2}$, which is essentially identical in form to the standard Sinusoidal positional encoding $\eqref{eq:sin}$, except that the placement of $\sin,\cos$ differs slightly. Generally speaking, neurons in a neural network are unordered, so even if we permute the various dimensions, it remains a perfectly valid positional encoding. Thus, apart from the fact that the individual $\theta_i$ values haven't been fixed, equations $\eqref{eq:r2}$ and $\eqref{eq:sin}$ are essentially no different.
The choice in equation $\eqref{eq:sin}$ is $\theta_i = 10000^{-2i/d}$ — what's the significance of this choice? As it turns out, this form has a nice property: as $|m-n|$ increases, $\langle\boldsymbol{p}_m, \boldsymbol{p}_n\rangle$ tends toward zero. Intuitively, inputs with larger relative distance should have weaker correlation, so this property matches our intuition. But then, given that these are periodic trigonometric functions, how can they exhibit a decaying trend?
This is indeed a remarkable phenomenon, arising from the asymptotic vanishing of highly oscillatory integrals. Specifically, we can write the inner product as
\begin{equation}\begin{aligned} \langle\boldsymbol{p}_m, \boldsymbol{p}_n\rangle =&\, \text{Re}\left[e^{\text{i}(m-n)\theta_0} + e^{\text{i}(m-n)\theta_1} + \cdots + e^{\text{i}(m-n)\theta_{d/2-1}}\right]\\ =&\,\frac{d}{2}\cdot\text{Re}\left[\sum_{i=0}^{d/2-1} e^{\text{i}(m-n)10000^{-i/(d/2)}}\frac{1}{d/2}\right]\\ \sim&\, \frac{d}{2}\cdot\text{Re}\left[\int_0^1 e^{\text{i}(m-n)\cdot 10000^{-t}}dt\right] \end{aligned}\end{equation}
which turns the problem into an asymptotic estimation of the integral $\int_0^1 e^{\text{i}(m-n)\theta_t}dt$. This kind of oscillatory integral estimation is quite common in quantum mechanics, and we could borrow methods from there for analysis — but for our purposes, the most direct approach is simply to plot the integral result using Mathematica:
\[Theta][t_] = (1/10000)^t;
f[x_] = Re[Integrate[Exp[I*x*\[Theta][t]], {t, 0, 1}]];
Plot[f[x], {x, -128, 128}]
From the resulting plot we can indeed see a decaying trend:
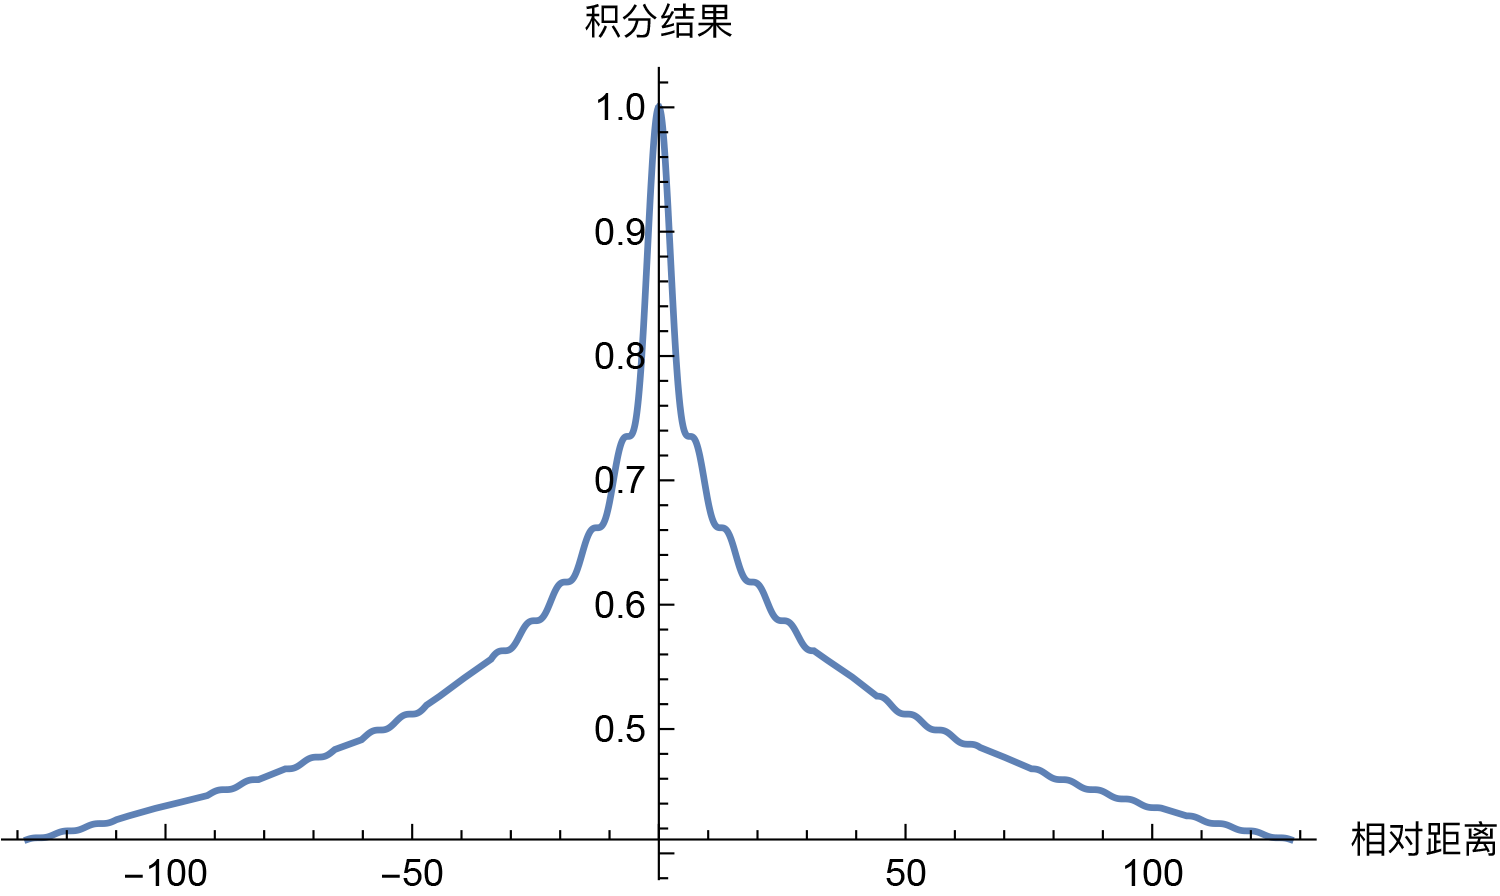 Estimating the decay trend of the Sinusoidal positional encoding inner product via direct integration
So the question arises: must we use $\theta_t = 10000^{-t}$ in order to get this long-range decay trend? Certainly not. In fact, for the scenario at hand, "almost" any monotonic smooth function $\theta_t$ on $[0,1]$ would make the integral $\int_0^1 e^{\text{i}(m-n)\theta_t}dt$ exhibit an asymptotic decay trend — for instance, the power function $\theta_t = t^{\alpha}$. So is there anything special about $\theta_t = 10000^{-t}$? Let's compare a few results.
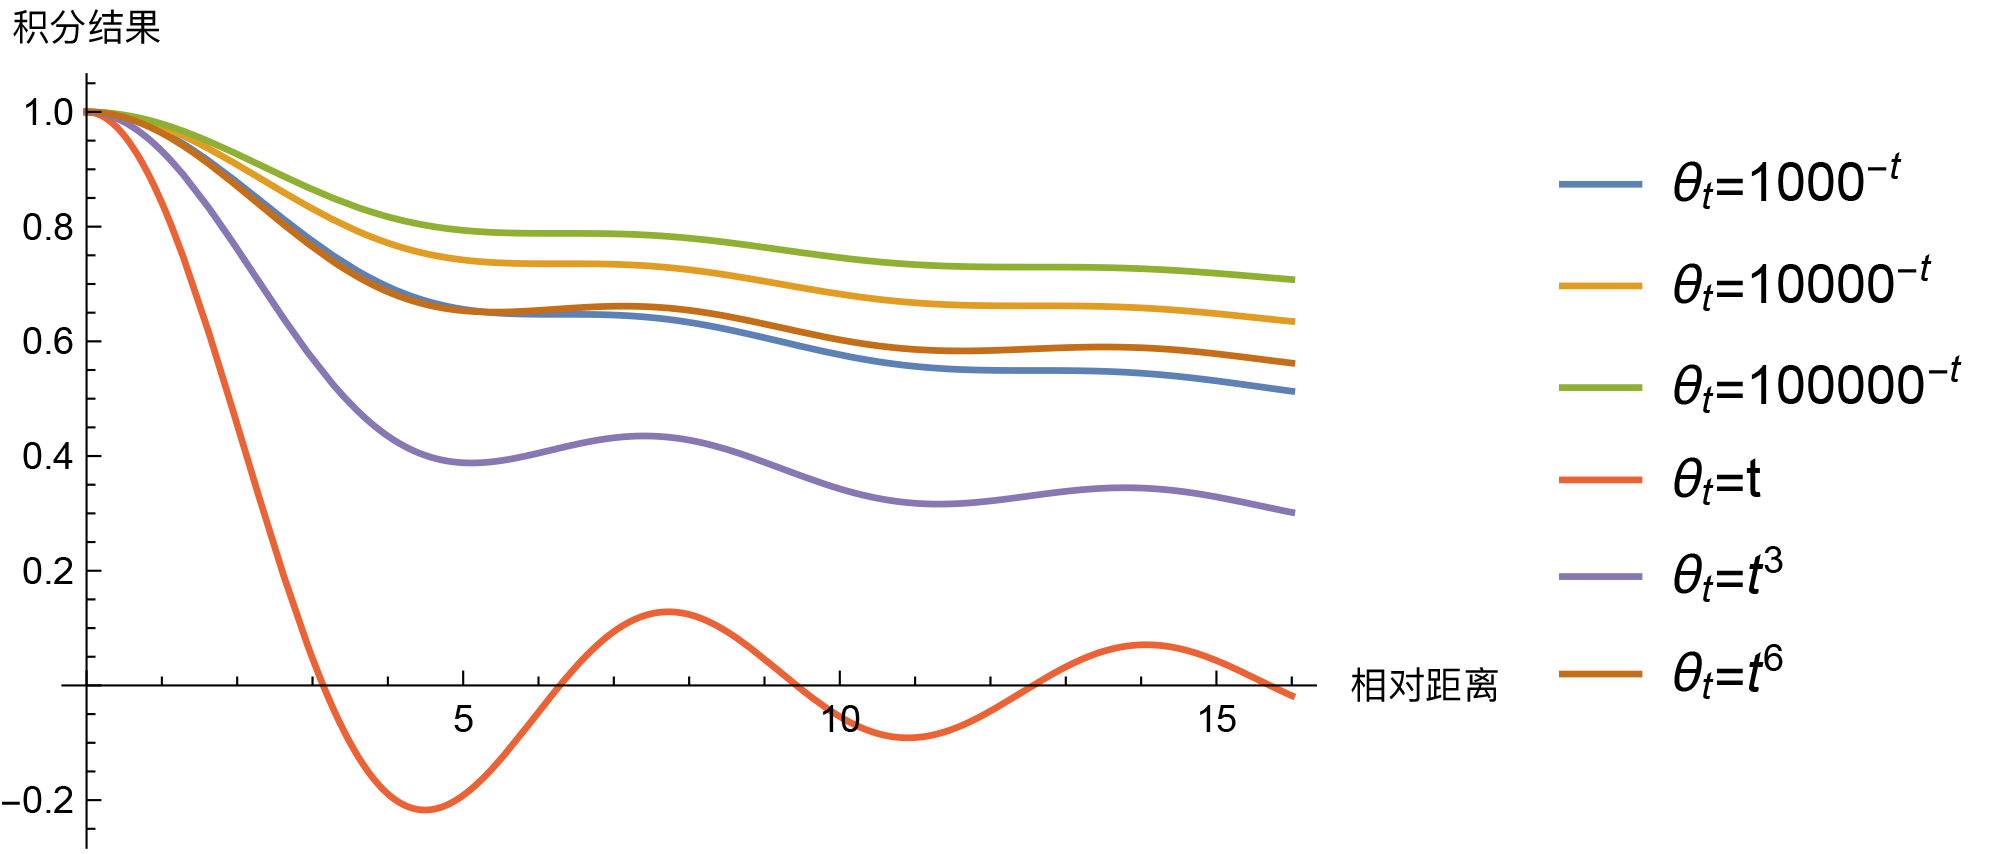 Integral results for several different θt (short-range trend)
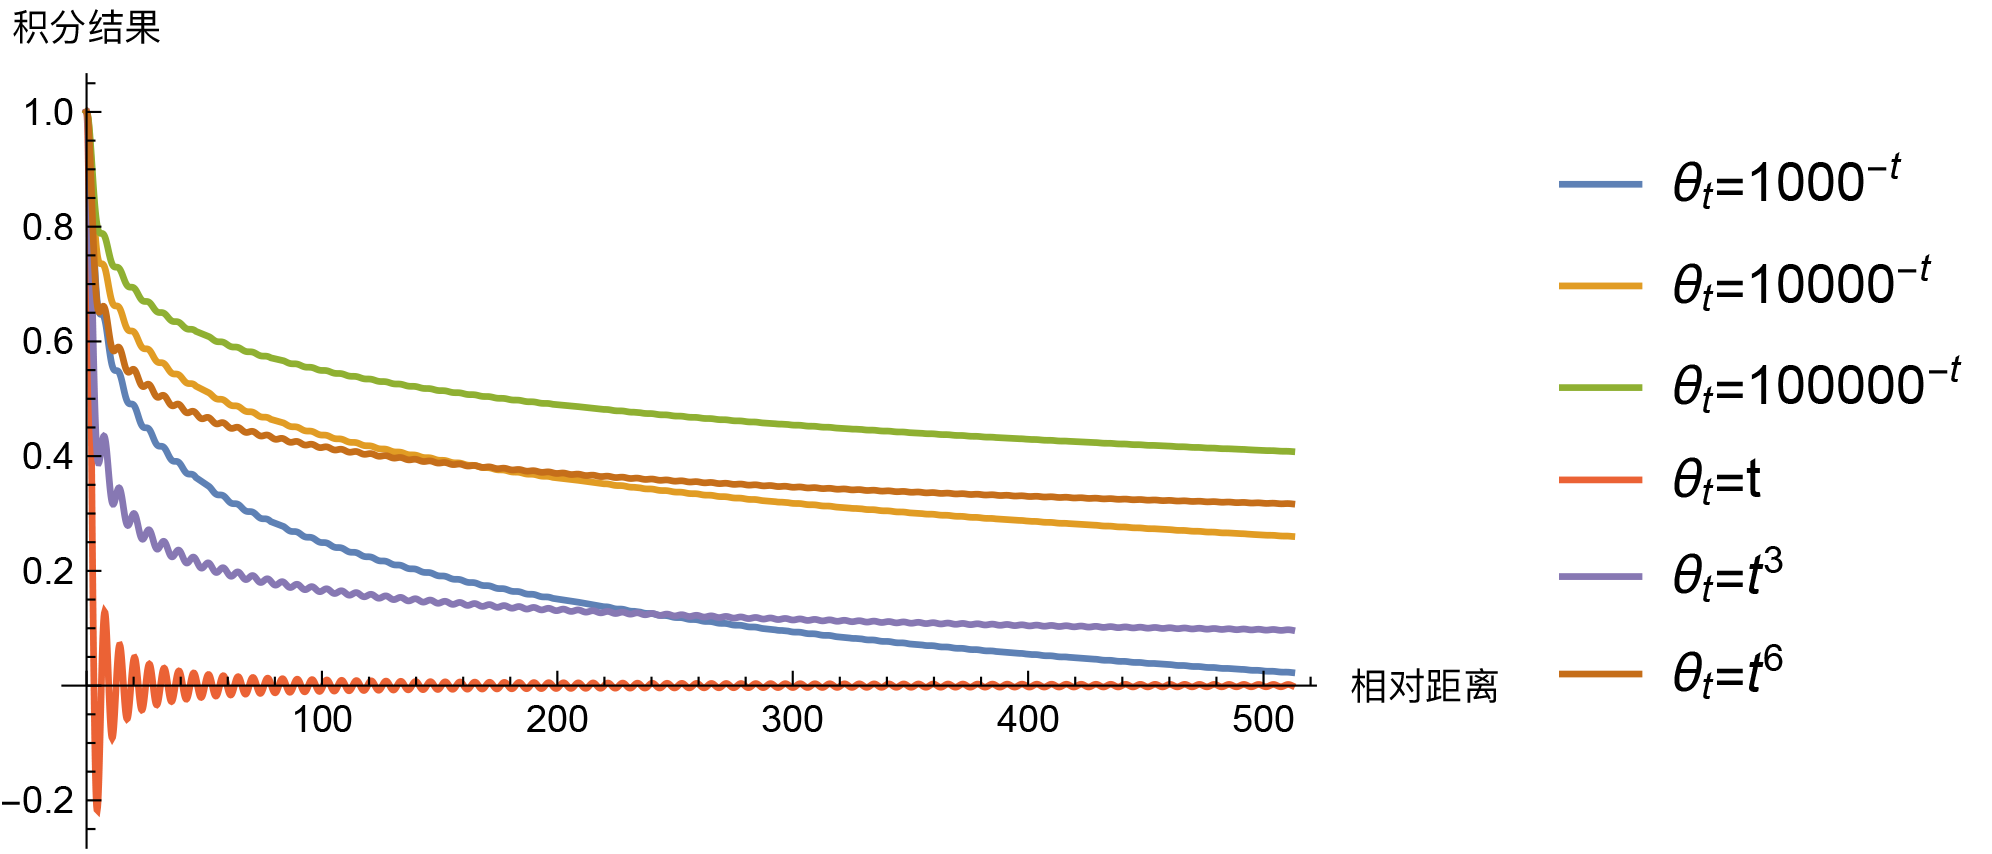 Integral results for several different θt (long-range trend)
Looking at this, apart from $\theta_t=t$ being somewhat anomalous (it crosses the horizontal axis), the others don't show much clear distinction — it's hard to say which is definitively better or worse. It's really just that power functions decay faster at short distances, while exponential functions decay faster at long distances; the closer $\theta_t$ is to 0 overall, the more slowly the whole thing decays, and so on. Seen this way, $\theta_t = 10000^{-t}$ is really just a compromise choice, without anything particularly special about it — if it were up to me, I'd probably choose $\theta_t = 1000^{-t}$ instead. Another option would be to simply use $\theta_i = 10000^{-2i/d}$ as the initialization values for the various $\theta_i$, and then make them trainable, letting the model fine-tune them automatically — that way you don't need to agonize over which to pick.
The General Case
In the previous two sections, we demonstrated the idea of expressing relative positional information through absolute positional encoding, and showed that, combined with the long-range decay constraint, we can "reverse-engineer" the Sinusoidal positional encoding, while also giving other possible choices for $\theta_i$. But let's not forget — up to this point, our derivation has been based on the simple case where $\boldsymbol{\mathcal{H}}=\boldsymbol{I}$. For the general case $\boldsymbol{\mathcal{H}}$, does using the above Sinusoidal positional encoding still retain these nice properties?
If $\boldsymbol{\mathcal{H}}$ is a diagonal matrix, then the properties above can be preserved to some extent. In this case
\begin{equation}\boldsymbol{p}_m^{\top} \boldsymbol{\mathcal{H}} \boldsymbol{p}_n=\sum_{i=1}^{d/2} \boldsymbol{\mathcal{H}}_{2i,2i} \cos m\theta_i \cos n\theta_i + \boldsymbol{\mathcal{H}}_{2i+1,2i+1} \sin m\theta_i \sin n\theta_i\end{equation}
By the product-to-sum formulas we get
\begin{equation}\sum_{i=1}^{d/2} \frac{1}{2}\left(\boldsymbol{\mathcal{H}}_{2i,2i} + \boldsymbol{\mathcal{H}}_{2i+1,2i+1}\right) \cos (m-n)\theta_i + \frac{1}{2}\left(\boldsymbol{\mathcal{H}}_{2i,2i} - \boldsymbol{\mathcal{H}}_{2i+1,2i+1}\right) \cos (m+n)\theta_i \end{equation}
We can see that this indeed contains the relative position $m-n$, except it may include an extra term $m+n$; if this isn't wanted, the model can let $\boldsymbol{\mathcal{H}}_{2i,2i} = \boldsymbol{\mathcal{H}}_{2i+1,2i+1}$ cancel it out. In this special case, what we've shown is that Sinusoidal positional encoding endows the model with the possibility of learning relative position — exactly what positional information is actually needed is then left for training to determine.
In particular, for the equation above, the long-range decay property still holds. For instance, taking the first sum term, by analogy with the approximation in the previous section, it corresponds to the integral
\begin{equation}\sum_{i=1}^{d/2} \frac{1}{2}\left(\boldsymbol{\mathcal{H}}_{2i,2i} + \boldsymbol{\mathcal{H}}_{2i+1,2i+1}\right) \cos (m-n)\theta_i \sim \int_0^1 h_t e^{\text{i}(m-n)\theta_t}dt\end{equation}
Likewise, some known results on oscillatory integrals (see Oscillatory Integrals, Study Notes 3 — One-Dimensional Oscillatory Integrals and Applications, etc.) tell us that under fairly mild conditions, this oscillatory integral tends to zero as $|m-n|\to\infty$, so the long-range decay property is preserved.
If $\boldsymbol{\mathcal{H}}$ is not a diagonal matrix, then unfortunately, the above properties are hard to reproduce. We can only hope that the diagonal part of $\boldsymbol{\mathcal{H}}$ dominates, in which case the properties above would still be approximately preserved. The diagonal part dominating means that the correlation between any two dimensions of the $d$-dimensional vector is relatively small, satisfying a certain degree of decoupling. For embedding layers, this assumption has some justification: I examined the covariance matrices of BERT's trained word embedding matrix and position embedding matrix, and found that the diagonal elements were noticeably larger than the off-diagonal elements — confirming that the assumption of diagonal dominance has some validity.
Discussion
Some readers might object: no matter how much you praise Sinusoidal positional encoding, that doesn't change the fact that directly trained (learned) positional encodings perform better than Sinusoidal ones. Indeed, experiments have shown that in thoroughly pretrained Transformer models like BERT, learned positional encodings do tend to outperform Sinusoidal ones — I'm not disputing that. What this article aims to do is to derive, from certain principles and assumptions, why Sinusoidal positional encoding can serve as an effective positional encoding — not to claim it's necessarily the best one.
The derivation rests on certain assumptions, and if the resulting outcome isn't good enough, that suggests the assumptions don't quite match reality. So where might the issue lie for Sinusoidal positional encoding? Let's reflect step by step.
Step one: the Taylor expansion, which relies on $\boldsymbol{p}$ being small. I also checked this in BERT, and found that the average norm of word embeddings is larger than that of positional embeddings, which suggests that treating $\boldsymbol{p}$ as small is reasonable to some extent — though exactly how reasonable is hard to say, since although embedding norms are larger, they're not overwhelmingly so. Step two: assuming $\boldsymbol{\mathcal{H}}$ is the identity matrix — since we analyzed in the previous section that it's likely diagonally dominant, assuming the identity matrix probably isn't too big a problem either. Step three: assuming that relative position is expressed via the inner product of two absolute position vectors — intuitively this seems reasonable, as the interaction between absolute positions ought to be capable of expressing a certain degree of relative positional information. The final step: determining $\theta_i$ via the automatic long-range decay property — this in itself should also be fine, but this is the step with the most room for variation, since there are so many possible forms for $\theta_i$, including even a trainable $\theta_i$, making it hard to pick out the most sensible one. So if Sinusoidal positional encoding isn't good enough, this step is well worth reflecting on too.
Summary
Overall, this article has attempted to reverse-engineer Sinusoidal positional encoding from a set of assumptions. These assumptions have their own justifications as well as their own issues, so the resulting Sinusoidal positional encoding has both merits worth noting and imperfections. But regardless, in current deep learning practice, being able to derive an explicit solution for a specific problem — rather than relying on brute-force fitting — Sinusoidal positional encoding is a rare and precious example, and one well worth pondering over.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.