From a Dynamical Perspective on Optimization Algorithms (VI): Why Doesn't SimSiam Collapse?
Since SimCLR], work on unsupervised feature learning in CV has exploded, to the point of being dizzying. Most of these works are based on contrastive learning, i.e. they construct positive and negative samples in some appropriate way and then perform classification-style learning. Yet among this crowd of similar works there are always a few mavericks — such as Google's BYOL] and the more recent SimSiam] — which propose that feature learning can be accomplished using positive samples alone, a refreshingly different idea. But without negative samples to hold things in check, how does the model avoid collapsing into a meaningless constant model? This is the most thought-provoking and rewarding question raised by these two papers.
SimSiam offers an answer that many people found convincing, but the author feels that SimSiam merely rephrases the problem rather than truly solving it. In my view, the success of models like SimSiam and GANs owes a great deal to the fact that they use gradient-based optimizers (rather than some stronger or weaker alternative), so any explanation that doesn't take the optimization dynamics into account is incomplete. Here, I will try to analyze, from a dynamical perspective, why SimSiam does not collapse.
SimSiam
Before looking at SimSiam, let's first look at BYOL, from the paper Bootstrap your own latent: A new approach to self-supervised Learning]. Its learning procedure is quite simple: it maintains two encoders, a Student and a Teacher, where the Teacher is the exponential moving average of the Student, and the Student in turn learns from the Teacher — somewhat like lifting yourself off the ground by pulling on your own bootstraps. The schematic is as follows:
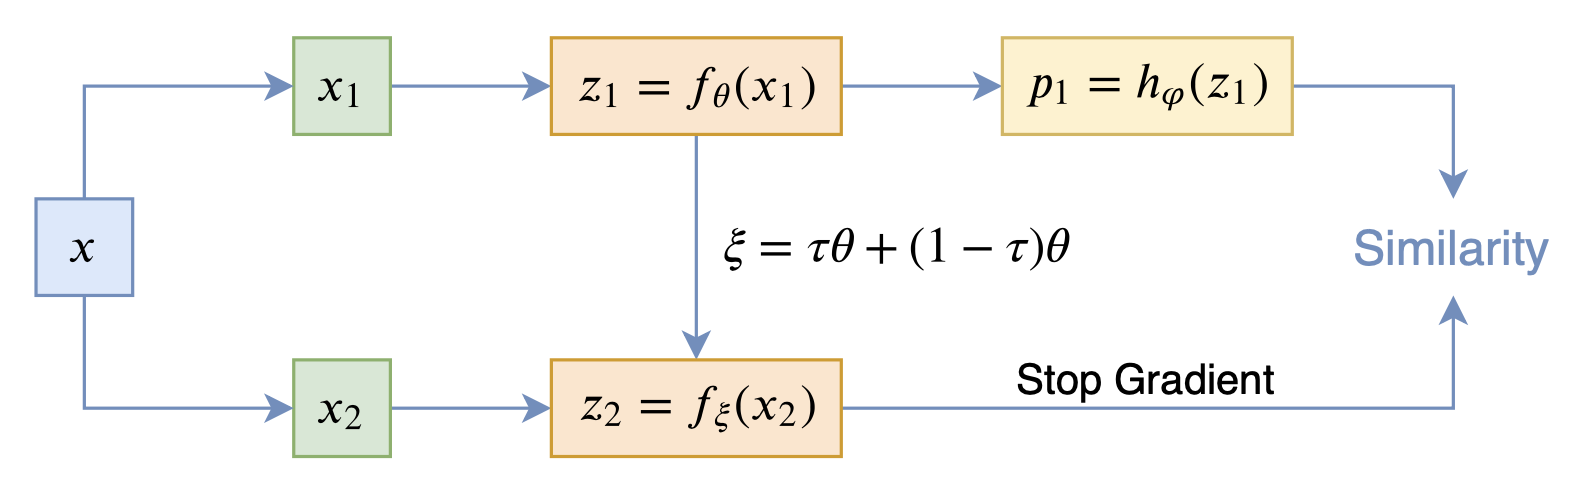 BYOL schematic]
SimSiam comes from the paper Exploring Simple Siamese Representation Learning], and is even simpler: it directly removes BYOL's moving average:
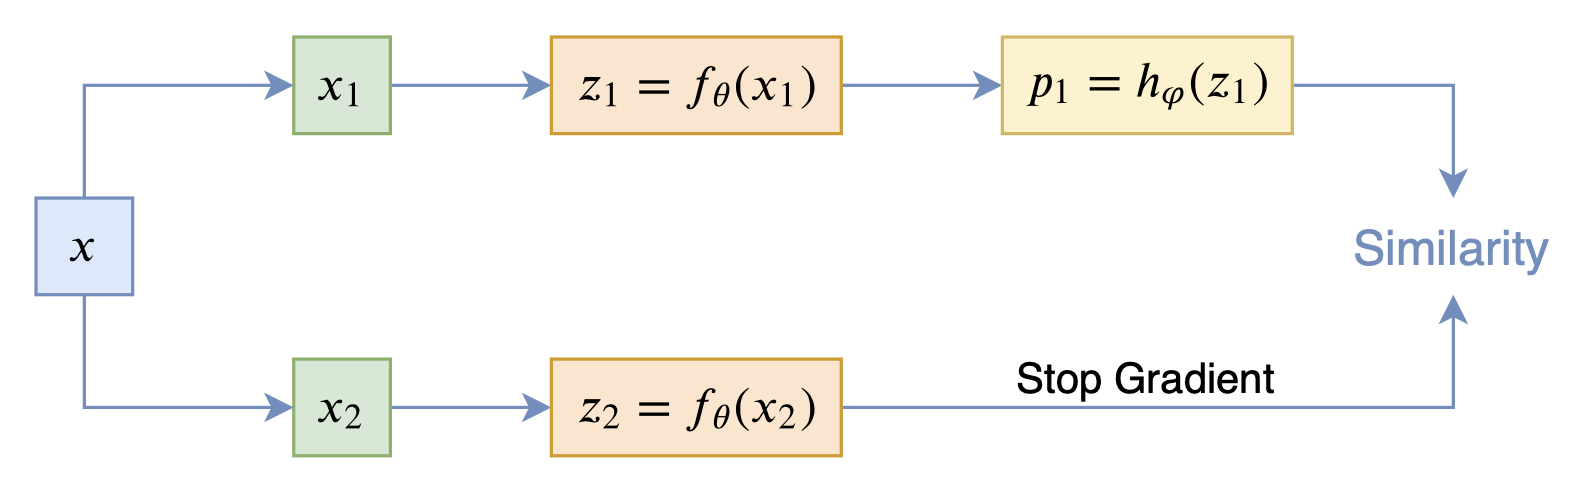 SimSiam schematic]
In effect, SimSiam is equivalent to setting BYOL's moving-average coefficient $\tau$ to 0, which shows that BYOL's moving average is not strictly necessary. To pinpoint the key components of the algorithm, SimSiam also ran a large number of ablation experiments, confirming that the stop_gradient operator and the predictor module $h_{\varphi}(z)$ are the keys to SimSiam not collapsing. To explain this phenomenon, SimSiam proposed that the optimization process is effectively equivalent to alternately optimizing
\begin{equation}\mathcal{L}(\theta, \eta)=\mathbb{E}_{x, \mathcal{T}}\left[\left\Vert\mathcal{F}_{\theta}(\mathcal{T}(x))-\eta_{x}\right\Vert^2\right]\label{eq:simsiam}\end{equation}
where $x$ denotes a training sample and $\mathcal{T}$ denotes a data augmentation. There are already plenty of explanations of this online, and the original paper itself is not difficult to read, so I won't go into detail here.
Dynamical Analysis
However, I think that translating our understanding of the SimSiam algorithm into an "alternating optimization of $\mathcal{L}(\theta, \eta)$" framing is just a rephrasing, and doesn't really give a substantive answer. The reason is obvious: $\mathcal{L}(\theta, \eta)$ as currently formulated still admits degenerate solutions — the model could simply let all the $\eta_{x}$'s equal the same vector, and have $\mathcal{F}_{\theta}$ output that same constant vector. Without explaining why the alternating optimization of $\mathcal{L}(\theta, \eta)$ doesn't collapse, we still haven't really answered the question.
Below I'll lay out what I believe are the key factors behind SimSiam's non-collapse, and use a simple example to show that explaining the non-collapse requires bringing in the dynamics. Of course, my discussion here is itself incomplete, and perhaps even not fully rigorous — I'm just offering a new angle to stimulate further thought.
The Deep Image Prior
First, it has long been observed that a randomly initialized CNN can be used directly to extract visual features, with performance that is not particularly bad — a finding that traces back to the 2009 paper What is the best multi-stage architecture for object recognition?], which can be understood as showing that CNNs naturally possess an inherent capacity for processing images. This property was later given a fancier name, the "deep image prior," from the paper Deep Image Prior], which ran experiments showing that starting from a randomly initialized CNN, without any supervised learning, one can accomplish tasks such as image inpainting and denoising — further confirming that CNNs naturally have an inherent capacity for image processing.
As I understand it, the "deep image prior" arises from three factors:
1. The continuity of images: an image itself can be directly treated as a continuous-valued vector, unlike in NLP where an embedding layer must be learned. This means a crude approach like "raw image features + K-nearest-neighbors" can already accomplish many tasks.
2. The architectural prior of CNNs: the local-receptive-field design of CNNs does indeed closely mimic the visual processing of the human eye, and the visual classification labels we provide are themselves derived from judgments made by our own eyes — so the two are naturally well matched.
3. Good initialization: this is not hard to understand — no matter how good the model, all-zero initialization would probably not work at all. An earlier post Understanding Model Parameter Initialization Strategies from a Geometric Perspective] briefly discussed initialization methods; from a geometric point of view, mainstream initialization methods are approximately "orthogonal transformations," which preserve as much of the input feature information as possible.
The Dynamics of Non-Collapse
As stated, the deep image prior means that a randomly initialized CNN is already a not-too-bad encoder. So what remains to be done boils down to two things: learn to become better, and don't collapse into a constant.
Learning to become better means designing certain prior signals by hand so that the model can better absorb this prior knowledge. SimSiam, BYOL, and similar methods apply two different data augmentations to the same image, and then require the corresponding feature vectors to be as similar as possible — this is a good form of guiding signal, telling the model that simple transformations should not affect our visual understanding. In fact, this is one of the design elements shared by all contrastive learning methods.
What differs is the "don't collapse into a constant" part. Typical contrastive learning methods construct negative samples to tell the model which images' features should not be close together, thereby preventing collapse. But SimSiam and BYOL are different — having no negative samples, they instead prevent collapse by decomposing the optimization process into two synchronized modules that operate at different speeds. Taking SimSiam as an example again, its optimization objective can be written as
\begin{equation}\mathcal{L}(\varphi, \theta)=\mathbb{E}_{x, \mathcal{T}_1,\mathcal{T}_2}\Big[l\left(h_{\varphi}(f_{\theta}(\mathcal{T}_1(x))), f_{\theta}(\mathcal{T}_2(x))\right)\Big]\end{equation}
Optimizing it with gradient descent gives the corresponding system of dynamical equations:
\begin{equation}\begin{aligned} \frac{d\varphi}{dt} = - \frac{\partial\mathcal{L}}{\partial \varphi} =& -\mathbb{E}_{x, \mathcal{T}_1,\mathcal{T}_2}\bigg[\frac{\partial l}{\partial h}\frac{\partial h}{\partial \varphi}\bigg]\\ \frac{d\theta}{dt} = - \frac{\partial\mathcal{L}}{\partial \theta} =& -\mathbb{E}_{x, \mathcal{T}_1,\mathcal{T}_2}\bigg[\frac{\partial l}{\partial h}\frac{\partial h}{\partial f}\frac{\partial f}{\partial \theta} \color{skyblue}{\,+\underbrace{\frac{\partial l}{\partial f}\frac{\partial f}{\partial \theta}}_{\begin{aligned}\text{SimSiam}\\\text{removed it}\end{aligned}}}\bigg] \end{aligned}\end{equation}
The equation above already marks the difference caused by the presence or absence of the stop_gradient operator. In short, if the stop_gradient operator is added, then $\frac{d\theta}{dt}$ loses its second term, and in that case $\frac{d\varphi}{dt}$ and $\frac{d\theta}{dt}$ jointly share the factor $\frac{\partial l}{\partial h}$. Since $h_{\varphi}$ is closer to the output layer, and the initialized $f_{\theta}$ is already a decent encoder, at the start of training $h_{\varphi}$ gets optimized faster, while the parts closer to the input layer are optimized more slowly. In other words, $\frac{d\varphi}{dt}$ is the fast-dynamics component, while $\frac{d\theta}{dt}$ is the slow-dynamics component; relatively speaking, $\frac{d\varphi}{dt}$ converges to 0 more quickly, meaning $\frac{\partial l}{\partial h}$ rapidly becomes very small. Since $\frac{d\theta}{dt}$ also contains the term $\frac{\partial l}{\partial h}$, $\frac{d\theta}{dt}$ shrinks along with it — and before it has a chance to collapse, the force driving it to collapse has already become negligible, so it never collapses. Conversely, if the second term $\frac{\partial l}{\partial f}\frac{\partial f}{\partial \theta}$ is present (whether added in or kept alone), it acts as a "fast lane": even once $\frac{\partial l}{\partial h}=0$, that second term is still there continuing to drive the collapse.
Let's take a simple, concrete example. Consider
\begin{equation}l = \frac{1}{2}(\varphi\theta - \theta)^2\end{equation}
For simplicity, both $\varphi,\theta$ here are scalars, and the corresponding dynamical equations are
\begin{equation}\frac{d\varphi}{dt}=-(\varphi\theta - \theta)\theta, \quad\frac{d\theta}{dt}=-(\varphi\theta - \theta) \varphi \color{skyblue}{+ \underbrace{(\varphi\theta - \theta)}_{\begin{aligned}\text{SimSiam}\theta\\ \text{removed it}\end{aligned}}}\end{equation}
Suppose $\varphi(0)=0.6, \theta(0)=0.1$ (chosen arbitrarily). The evolution of the two cases is:
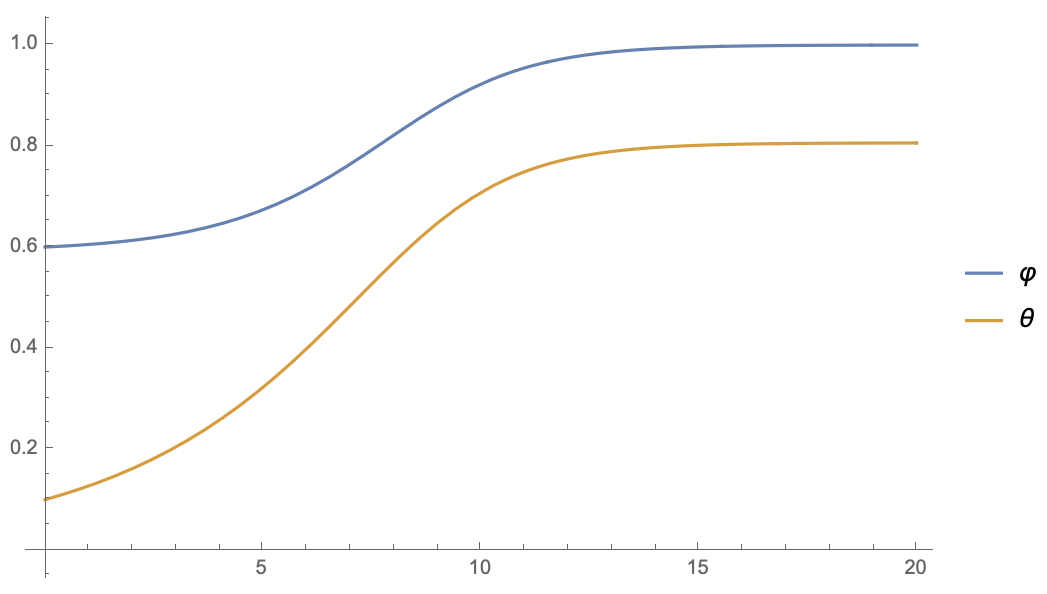 Stopping the gradient of the second θ]
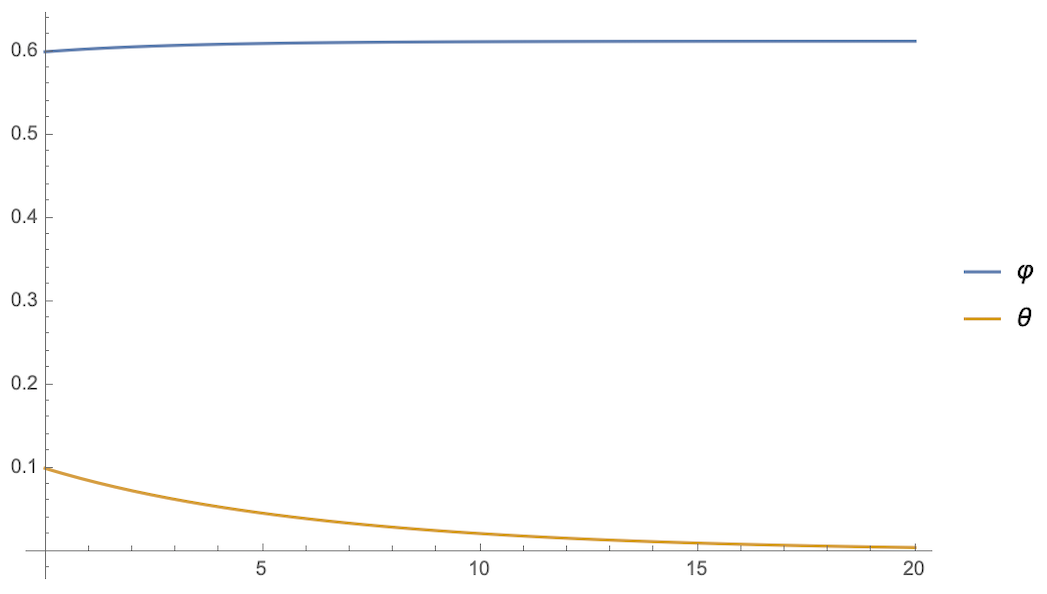 Not stopping the gradient of the second θ]
We can see that once the gradient of the second $\theta$ is stopped, the equations for $\varphi$ and $\theta$ become quite consistent: $\varphi$ rapidly approaches 1, while $\theta$ settles at a nonzero value (meaning no collapse). By contrast, if we add back the second term of $\frac{d\theta}{dt}$ — or even keep only that term — the result is that $\theta$ rapidly approaches 0, and $\varphi$ can never approach 1, meaning the dominant role is taken over by $\theta$.
This example alone isn't especially convincing, but it does simply illustrate the change in dynamics:
The introduction of the predictor ($\varphi$) splits the model's dynamics into two parts, and the introduction of the stop_gradient operator slows down the dynamics of the encoder part ($\theta$), while enhancing the synchrony between the encoder and the predictor. As a result, the predictor fits the target with "lightning speed," so that before the encoder has any chance to collapse, the optimization process has already come to rest.
A Look at the Approximate Expansion
Of course, interpretations are legion, and every one of them is just "hindsight commentary" — the real credit belongs to the discoverers, and we are, at best, riding on their coattails. Let me offer one more such contribution here, sharing another angle from which I view SimSiam. As mentioned at the outset, the SimSiam paper explains SimSiam via alternating optimization of the objective $\eqref{eq:simsiam}$. Let's start from this objective $\eqref{eq:simsiam}$ and dig a bit deeper into why it doesn't collapse.
If we fix $\theta$, then for the objective $\eqref{eq:simsiam}$, we can readily solve for the optimal value of $\eta_x$, which is
\begin{equation}\eta_x=\mathbb{E}_{\mathcal{T}}\left[\mathcal{F}_{\theta}(\mathcal{T}(x))\right]\end{equation}
Substituting this into $\eqref{eq:simsiam}$ gives the optimization objective
\begin{equation}\mathcal{L}(\theta)=\mathbb{E}_{x, \mathcal{T}}\bigg[\Big\Vert\mathcal{F}_{\theta}(\mathcal{T}(x))-\mathbb{E}_{\mathcal{T}}\left[\mathcal{F}_{\theta}(\mathcal{T}(x))\right]\Big\Vert^2\bigg]\end{equation}
Assume that $\mathcal{T}(x)-x$ is a "small" vector, so that expanding to first order around $x$ gives
\begin{equation}\mathcal{L}(\theta)\approx\mathbb{E}_{x, \mathcal{T}}\bigg[\left\Vert\frac{\partial \mathcal{F}_{\theta}(x)}{\partial x}\big(\mathcal{T}(x)-\bar{x}\big)\right\Vert^2\bigg]\label{eq:em-sim}\end{equation}
where $\bar{x}=\mathbb{E}_{\mathcal{T}}\left[\mathcal{T}(x)\right]$ is the average result of the same image over all data augmentation methods — note that in general it is not equal to $x$. Similarly, for the version of SimSiam without stop_gradient and without a predictor, the loss function approximates to
\begin{equation}\mathcal{L}(\theta)\approx\mathbb{E}_{x, \mathcal{T}_1, \mathcal{T}_2}\bigg[\left\Vert\frac{\partial \mathcal{F}_{\theta}(x)}{\partial x}\big(\mathcal{T}_2(x)-\mathcal{T}_1(x)\big)\right\Vert^2\bigg]\label{eq:em-sim-2}\end{equation}
In equation $\eqref{eq:em-sim}$, each $\mathcal{T}(x)$ is subtracted from $\bar{x}$, and one can show that this choice minimizes the loss function; whereas in equation $\eqref{eq:em-sim-2}$, each $\mathcal{T}_1(x)$ is instead subtracted from another augmentation result $\mathcal{T}_2(x)$, which greatly increases both the loss itself and the variance of the estimate.
Does this mean that the reason removing stop_gradient and removing the predictor leads to failure is that the resulting loss function and its variance become too large? Notice that under the first-order approximation we have $\eta_x\approx \mathcal{F}_{\theta}(\bar{x})$; so what if we instead change the optimization objective to
\begin{equation}\mathcal{L}(\theta)=\mathbb{E}_{x, \mathcal{T}}\bigg[\Big\Vert\mathcal{F}_{\theta}(\mathcal{T}(x))-\mathcal{F}_{\theta}(\bar{x})\Big\Vert^2\bigg]\end{equation}
would this then avoid collapse? I haven't verified this myself, so I can't say for sure — readers currently studying related topics might like to check it out. This also raises a related question: once the encoder has been trained this way, which should we use as the feature representation, $\mathcal{F}_{\theta}(x)$ or $\mathcal{F}_{\theta}(\bar{x})$?
Of course, all of this discussion rests on the assumption that "$\mathcal{T}(x)-x$ is a small vector"; if that assumption fails, then this whole section will have been for nothing.
Closing Remarks
This post has attempted to give my own understanding, from a dynamical perspective, of why BYOL and SimSiam do not collapse. Unfortunately, halfway through writing it I realized that some of the analysis I had originally conceived in my head didn't quite hold together, so I trimmed some content and added a new angle, trying my best to keep the piece from petering out — as for polish, well, that's a bit much to ask. Consider this simply notes shared here; if there are any errors, I ask readers' indulgence and welcome corrections.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.