When GPT Meets Chinese Chess: After Writing Articles and Solving Problems, How About a Game of Chess?
 Chinese chess
I wonder if readers have seen QbitAI's article from earlier this year, "The Strongest Writing AI Has Learned Chess and Composition—Language Models Cross Boundaries and Spark Discussion, Ready to Take on Challengers Online", which mentioned that a netizen had trained a chess-playing model using GPT-2. I've always been thinking: how could such a fun thing not have a Chinese version? For international chess, its "Chinese version" is naturally Chinese chess (xiangqi), so I've long wanted to reproduce these results on Chinese chess. After dragging my feet for over half a year, I finally got around to finishing it in the past few days, and I'd like to share it with you here.
Rules of Chess Notation
The General never leaves the palace; the Advisors and Guards stay together and never venture beyond the court.
The Elephant moves diagonally to the four corners; the Horse moves one step then a diagonal leap.
The Cannon must jump over one piece to capture another; the Chariot moves freely east and west.
Only the Pawn moves one step at a time; once across the river, it can move sideways but never retreats.
Memorizing the Game Record
Actually, just by skimming the QbitAI article, one can understand the principle behind GPT-2 playing chess: it's essentially "memorizing game records." Simply put, a chess game record can be represented as a continuous string of text, and GPT-2 excels precisely at memorizing text. So we can use GPT-2 to memorize human game records, and playing chess can then be viewed as predicting the next move in the record given the moves already played. Thus, in theory, this task can indeed be accomplished with GPT-2.
To accomplish this task, we need to understand how computers record chess notation. Regarding notation standards, the commonly used ones are ICCS notation and FEN board representation; details can be found in the articles "Chinese Chess Computer Application Specification (2): Move Notation" and "Chinese Chess Computer Application Specification (2): FEN File Format".
ICCS Notation
Simply put, ICCS notation represents the board using horizontal and vertical coordinates as shown in the figure below, and each move only needs to record the starting and ending coordinates. For example, "h2e2" means moving the piece originally at coordinate (h, 2) to (e, 2); if the current position is a fresh opening, this corresponds to the move "Cannon 2 to 5." This way, each move only requires 4 characters to record, so a game with $n$ moves becomes a string of length $4n$. Of course, if we're feeding this into a model, we don't necessarily have to do it exactly this way—for instance, we could represent "h2" with one id and "e2" with another id, i.e., describing each grid point with a single coordinate rather than two, so that each move only needs two ids to record, thereby shortening the sequence length of the game record. There's no fixed rule here; interested readers are welcome to improve on this themselves.
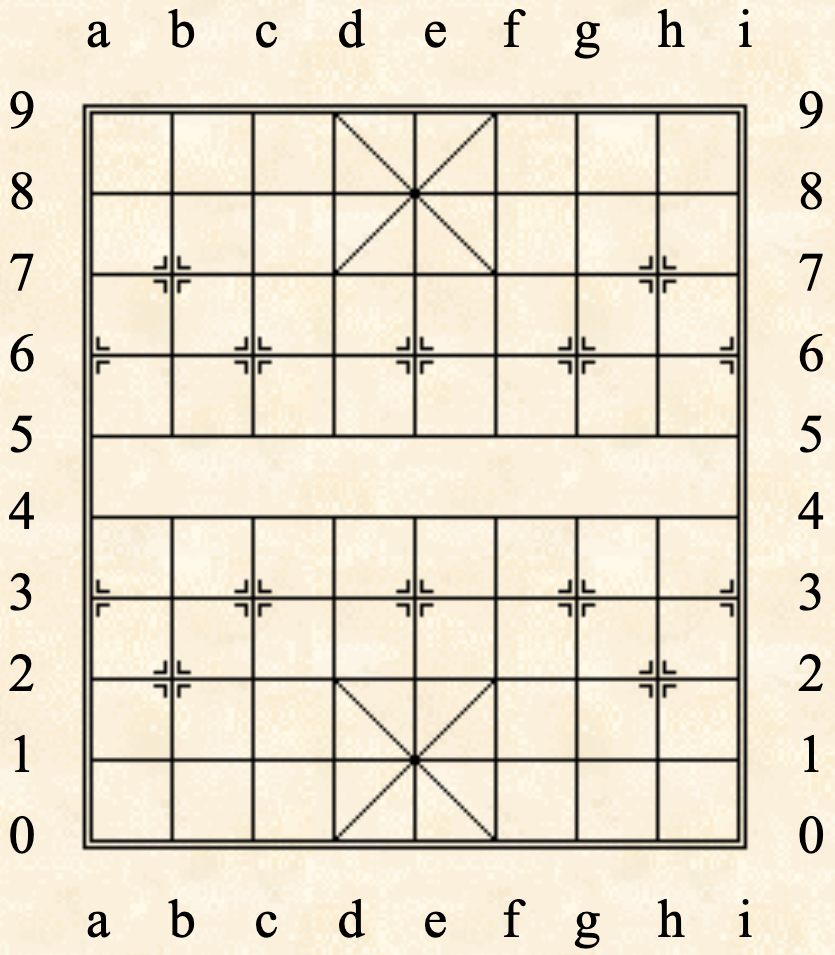 Diagram of ICCS coordinates on the Chinese chess board
FEN Position Notation
As for FEN position notation, it's used to represent which pieces are on the board in the current position and whose turn it is to move. The game records modeled in this article are actually all complete games, so the model here doesn't actually need to use FEN (positions are always assumed to be the default starting position). However, for the convenience of interested readers who want to make improvements, I'll briefly introduce it here. The so-called FEN notation is essentially a way to represent which pieces are in each row. For example, the starting position is represented as "rnbakabnr/9/1c5c1/p1p1p1p1p/9/9/P1P1P1P1P/1C5C1/9/RNBAKABNR w - - 0 1." The red portion represents the board state, where lowercase letters denote Black's pieces and uppercase letters denote Red's pieces, with different rows separated by "/". The meaning of each letter is given in the table below. So "rnbakabnr" represents the first row as Black's "Chariot Horse Elephant Advisor General Advisor Elephant Horse Chariot," "9" indicates that the second row's 9 points are all empty, "1c5c1" means the third row is "1 empty + 1 Black Cannon + 5 empty + 1 Black Cannon + 1 empty," and so on. The green portion indicates whose turn it is to move: "w" for Red, "b" for Black. The remaining parts are generally not very important, and interested readers can check the link themselves.
$$\begin{array}{c} \text{Chinese chess FEN notation meaning table} \\ {\begin{array}{c|c|c|c|c|c|c} \hline \color{red}{R}/\color{black}{r} & \color{red}{N}/\color{black}{n} & \color{red}{B}/\color{black}{b} & \color{red}{A}/\color{black}{a} & \color{red}{K}/\color{black}{k} & \color{red}{C}/\color{black}{c} & \color{red}{P}/\color{black}{p} & \text{Arabic numeral}m\\ \hline \color{red}{\text{rook}}/\color{black}{\text{rook}} & \color{red}{\text{horse}}/\color{black}{\text{horse}} & \color{red}{\text{phase}}/\color{black}{\text{image}} & \color{red}{\text{advisor}}/\color{black}{\text{shi}} & \color{red}{\text{shuai}}/\color{black}{\text{will}} & \color{red}{\text{cannon}}/\color{black}{\text{cannon}} & \color{red}{\text{pawn}}/\color{black}{\text{pawn}} & \text{denote continuous}m\text{slot} \\ \hline \end{array}$$}
\end{array}
Building the Model
Having reviewed the above introduction to notation representation, we know that whether it's the notation for each move or the representation of the board position, everything gets converted into a string of text. Since the reasoning behind chess moves always takes positions and moves as input/output, theoretically modeling chess is entirely a "text processing" problem! This is exactly the theoretical basis for GPT-2 playing chess. Fundamentally speaking, GPT is just BERT plus a language-model-style attention mask, so we could just as well call this approach "BERT playing chess" or "GPT playing chess."
Code
There's not much to say about the model's underlying principle—it's already been covered in a previous article, "From Language Models to Seq2Seq: Transformer as a Play, All Thanks to Masking", and relevant examples include "Conditional Text Generation Based on Conditional Layer Normalization" and "What Grade Level Has BERT Reached? Seq2Seq 'Tackles' Elementary School Math Word Problems"; readers are welcome to look these up themselves. The approach in this article is actually quite simple: we only keep complete game records, treat the ICCS notation of the game as one long sentence, and then train a language model.
Project link: https://github.com/bojone/gpt_cchess
The training process uses progressive training, i.e., gradually increasing the sequence length rather than using a fixed length from the start—some articles refer to this approach as "Curriculum Learning." This approach improves both training speed and convergence speed (shorter sequences at the start mean faster training and easier convergence). Intuitively, it's like letting the model first learn the "opening," then learn "opening + midgame," and finally learn "opening + midgame + endgame," gradually increasing the difficulty. Before training, we loaded BERT's pretrained weights. Readers might wonder whether BERT's weights have anything to do with chess records—actually, they don't really, but regardless, using BERT's weights is better than starting from completely random initialization, and convergence is a bit faster.
Let's Test It
The model script also includes an implementation that lets you play chess interactively against the model, and readers are welcome to try it out themselves. This interactive chess-playing feature was implemented with the help of Python's cchess module, for which I'm grateful. GPT itself is a generative model, but when deciding what move to make next, I didn't use a generative approach (since unconstrained generation might output infeasible moves). Instead, I used a scoring approach: directly generate all feasible moves for the current position, feed them into the model for scoring, and pick the move with the highest score. This guarantees that every move output by the model is feasible, ensuring that you can keep playing against the AI all the way until a winner is decided.
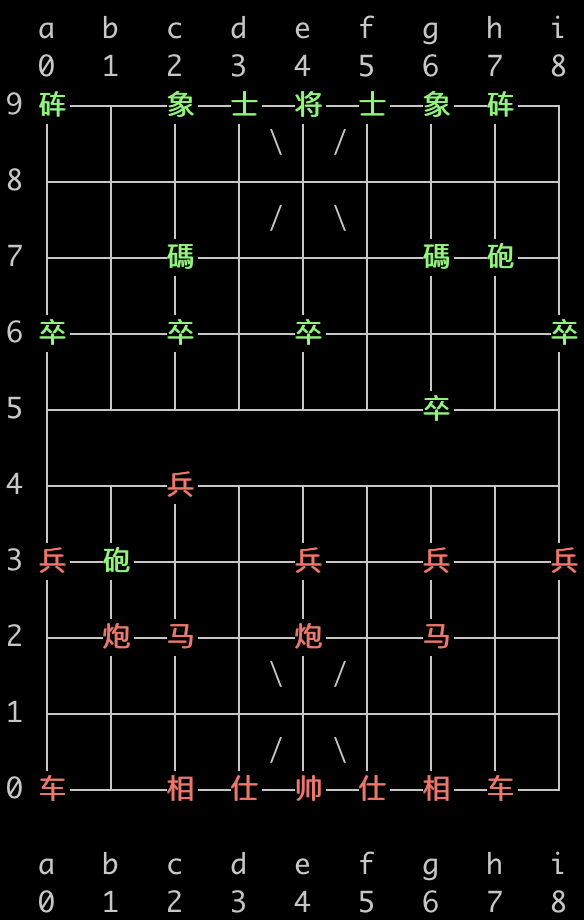 Interactive chess-playing in action
Readers might wonder: isn't enumerating all feasible moves computationally expensive? Actually, for any given position, there aren't that many feasible moves—it can be shown through a simple argument that the number never exceeds 111 (a bit surprising, isn't it? The number of candidate moves at each step in Chinese chess never exceeds 111, rather than being some enormous number). So the batch size for this step never exceeds 111, which is perfectly acceptable.
The derivation is simple: 1 chariot or cannon has at most 17 possible moves, so 2 chariots + 2 cannons have at most 68 possible moves; if all pawns have crossed the river, each pawn has at most 3 possible moves, so 5 pawns have at most 15 possible moves; 1 horse has at most 8 possible moves, so 2 horses have 16; 2 elephants have at most 6 possible moves (1 in the middle position has 4, 1 at the edge has 2); 1 advisor at the central point has at most 4 possible moves (2 advisors actually block each other); finally, the general has at most 2 possible moves. Adding these up gives 68+15+16+6+4+2=111. For details on how such a position is designed, see the Mathematics R&D Forum post "A Puzzle in Designing a Chinese Chess Position".
What most people probably care about is: how good is the resulting model's playing strength, really? I tested it a bit myself, and the rough conclusion is: it can basically play a decent opening, showing reasonable adaptability early on, but once it gets into the midgame, its adaptability drops off significantly. It's also not very sensitive to captures—meaning if you carelessly let it capture your pieces, it might not respond appropriately. These are clearly the drawbacks of a model that purely memorizes game records. That said, as mentioned earlier, every move it outputs is guaranteed to be feasible, so you can keep playing with it all the way to the end of the game.
On Improvements
Some readers might ask: can the model improve its playing strength through self-play? Theoretically, yes, but unfortunately I haven't implemented this—partly because I didn't have the motivation, and partly because I didn't have the computing resources. Also, increasing model size should further improve playing strength; note that the results above only used the Base version (100 million parameters), whereas the netizen mentioned at the beginning of this article who trained GPT-2 to play international chess used a 1.5-billion-parameter GPT-2—15 times larger than ours. Another possible improvement: in the modeling approach above, we directly learned from the entire game record, but arguably, for better playing strength, we should only learn from the winner's moves and not from the loser's moves.
Of course, even if these approaches yield improvements, they're probably limited. Fundamentally, this differs from how we understand the principles of chess-playing. When we play chess, we reason forward based on the current position, but the language-model approach above has no concept of "position" at all—or rather, its notion of position must be inferred from the entire history of moves played so far, which, for the mid-to-late game, involves too many historical moves and is really asking too much of the model. The fix, actually, is quite simple: change the setup to "position as input, move as output." As mentioned earlier, a position can also be represented as text via FEN notation, so this is just a Seq2Seq task after all.
Beyond this, there are other approaches too. For instance, we could treat every position experienced by the winner as a positive sample and every position experienced by the loser as a negative sample, thereby training a binary classification model to judge whether a position is favorable or unfavorable. With such a judgment function in hand, we could again directly enumerate every feasible move and select the best one based on the judgment function's output. And since positions can be represented as text, this effectively turns chess-playing into a text classification task.
In short, thanks to the Transformer model's powerful capacity for modeling text, our ways of thinking about how to model chess-playing have become simpler and more varied.
Summary
This article attempted to use GPT, via bert4keras, to play Chinese chess. The main idea is to give the model the ability to predict the next move by having a language model "memorize game records," and I've also discussed some ideas for improvement. Although the approach here isn't the standard way of modeling the chess-playing task, going through this exercise lets us further appreciate just how powerful language models really are.
I welcome everyone to report the "chess IQ" of whatever chess-playing models you train yourselves, haha~
 Here's an "elephant" pair for you
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.