Breaking through the Bottleneck: Building a Stronger Transformer
Since the publication of Attention is All You Need, Transformer models based on Multi-Head Attention have become popular, and last year's BERT model pushed the popularity of Transformer models to yet another peak. Of course, the exploration of new techniques never stops, and a stream of improvements has emerged one after another: some improve the pretraining task, such as XLNet's PLM or ALBERT's SOP; some improve normalization, such as the shift from Post-Norm to Pre-Norm, or T5's removal of the beta parameter in Layer Norm; some improve the model architecture, such as Transformer-XL; and some improve the training procedure, such as ALBERT's parameter sharing; and so on.
All of these changes have been made outside Attention itself — that is, they all take the reasonableness of Attention for granted, without modifying Attention proper. In this post, I want to introduce two new results that take a different approach: both papers point to a potential modeling bottleneck inside Multi-Head Attention, and propose different schemes to improve it. Both papers come from Google and include fairly thorough experiments, so their conclusions should be quite convincing.
No key_size Is Too Small
The first result comes from the paper Low-Rank Bottleneck in Multi-head Attention Models, which explicitly points out an expressive-power bottleneck inside Multi-Head Attention, and proposes to alleviate this bottleneck by increasing key_size. more
Multi-Head Attention
Let's first briefly recall Multi-Head Attention; readers can also refer back to my earlier post Attention is All You Need: A Brief Read (Introduction + Code). The foundation of Multi-Head Attention is of course Single-Head Attention, also called Scaled-Dot Attention, defined as follows:
\begin{equation}Attention(\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V}) = softmax\left(\frac{\boldsymbol{Q}\boldsymbol{K}^{\top}}{\sqrt{d_k}}\right)\boldsymbol{V}\end{equation}
where $\boldsymbol{Q}\in\mathbb{R}^{n\times d_k}, \boldsymbol{K}\in\mathbb{R}^{m\times d_k}, \boldsymbol{V}\in\mathbb{R}^{m\times d_v}$. Multi-Head Attention projects $\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V}$ using $h$ different projection matrices $h$ times, performs Single-Head Attention $h$ times separately, and then concatenates the results, i.e.
\begin{equation}\begin{aligned}&\boldsymbol{Q}^{(1)}=\boldsymbol{Q}\boldsymbol{W}_Q^{(1)},\boldsymbol{K}^{(1)}=\boldsymbol{K}\boldsymbol{W}_K^{(1)},\boldsymbol{V}^{(1)}=\boldsymbol{V}\boldsymbol{W}_V^{(1)},\boldsymbol{O}^{(1)}=Attention\left(\boldsymbol{Q}^{(1)},\boldsymbol{K}^{(1)},\boldsymbol{V}^{(1)}\right)\\ &\boldsymbol{Q}^{(2)}=\boldsymbol{Q}\boldsymbol{W}_Q^{(2)},\boldsymbol{K}^{(2)}=\boldsymbol{K}\boldsymbol{W}_K^{(2)},\boldsymbol{V}^{(2)}=\boldsymbol{V}\boldsymbol{W}_V^{(2)},\boldsymbol{O}^{(2)}=Attention\left(\boldsymbol{Q}^{(2)},\boldsymbol{K}^{(2)},\boldsymbol{V}^{(2)}\right)\\ &\qquad\qquad\qquad\qquad\vdots\\ &\boldsymbol{Q}^{(h)}=\boldsymbol{Q}\boldsymbol{W}_Q^{(h)},\boldsymbol{K}^{(h)}=\boldsymbol{K}\boldsymbol{W}_K^{(h)},\boldsymbol{V}^{(h)}=\boldsymbol{V}\boldsymbol{W}_V^{(h)},\boldsymbol{O}^{(h)}=Attention\left(\boldsymbol{Q}^{(h)},\boldsymbol{K}^{(h)},\boldsymbol{V}^{(h)}\right)\\ &\boldsymbol{O}=\left[\boldsymbol{O}^{(1)},\boldsymbol{O}^{(2)},\dots,\boldsymbol{O}^{(h)}\right] \end{aligned}\end{equation}
There's a Bottleneck in Attention
In practice, $\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V}$ usually share the same feature dimension $d_k=d_v=d$ (i.e., hidden_size) — for example, 768 in BERT Base. $h$ is usually chosen to be 12, 16, 24, etc. — for example, 12 in BERT base. Once $d,h$ is fixed, the usual choice is to make the projection matrix $\boldsymbol{W}\in\mathbb{R}^{d\times (d/h)}$, meaning that in each Attention Head, the original $d$-dimensional input is projected down to $d/h$ dimensions, the Attention computation is performed there, and the output is also $d/h$-dimensional; finally the $h$ results of dimension $d/h$ are concatenated to give an output of dimension $d$. Here $d/h$ is usually called head_size.
In Attention, the key step is
\begin{equation}\boldsymbol{P}=softmax\left(\frac{\boldsymbol{Q}\boldsymbol{K}^{\top}}{\sqrt{d_k}}\right)\label{eq:softmax}\end{equation}
This step describes the pairwise relationship between vectors of $\boldsymbol{Q}$ and $\boldsymbol{K}$. We can think of $\boldsymbol{P}$ as a bivariate joint distribution (in fact it's $n$ univariate distributions, though that detail isn't important here). If the sequence lengths are all $n$, meaning each element has $n$ possible values, then this distribution has a total of $n^2$ values.
However, once we project $\boldsymbol{Q},\boldsymbol{K}$ down to a low dimension, the number of parameters involved is only $n\times (d/h)$, giving a total parameter count of $2nd/h$. So equation $\eqref{eq:softmax}$ is effectively using $2nd/h$ parameters to approximate a quantity that itself has $n^2$ values, and typically $2nd/h \ll n^2$ — especially when $h$ is large. This modeling is a bit like "asking too much of the model," which is exactly what the original paper means by "Low-Rank Bottleneck."
Why Not Try Increasing key_size?
So what's the solution? The most direct idea is to make $2nd/h$ larger, which means either reducing the number of heads $h$, or increasing the hidden_size $d$. But having more Attention heads itself also strengthens the model's expressive power, so reducing $h$ just to relieve the low-rank bottleneck might be a net loss; and while increasing $d$ would naturally strengthen the model's overall expressive power, it would also cause a sharp increase in model size and compute, which doesn't seem like a great option either.
Is there any other way? Yes! When we project $\boldsymbol{Q},\boldsymbol{K},\boldsymbol{V}$ down to a low dimension using projection matrices, we've been projecting them all to the same $d/h$ dimensions — but actually their dimensions don't have to be equal. All that's really required is that the dimensions of $\boldsymbol{Q},\boldsymbol{K}$ match (since we need to take an inner product). To distinguish them, we usually call the dimension of $\boldsymbol{Q},\boldsymbol{K}$ the key_size, while the dimension of $\boldsymbol{V}$ is called head_size. Changing the key_size without changing head_size doesn't affect the model's hidden_size at all.
So the solution proposed in this paper is to increase the model's key_size. This increases Attention's expressive power without changing the model's overall hidden_size, and only slightly increases the amount of computation.
Additional note:
In fact, the original paper considers increasing key_size and head_size simultaneously, then applying a dimension-reducing transformation matrix after concatenating the Multi-Head Attention outputs. However, I believe that since this concatenation-plus-reduction step is just a linear transformation, the real improvement fundamentally comes from increasing key_size — so this post only emphasizes that step.
Also, if you increase key_size and head_size at the same time, both compute and memory consumption increase noticeably, whereas increasing only key_size adds much less overhead.
Let's Look at the Experimental Results
The idea of increasing key_size is simple and easy to implement, but does it actually work? Let's look at the original paper's experimental results. All experiments use BERT as the baseline; there are many charts, so it's best to check the original paper directly. Here I'll just share one representative result:
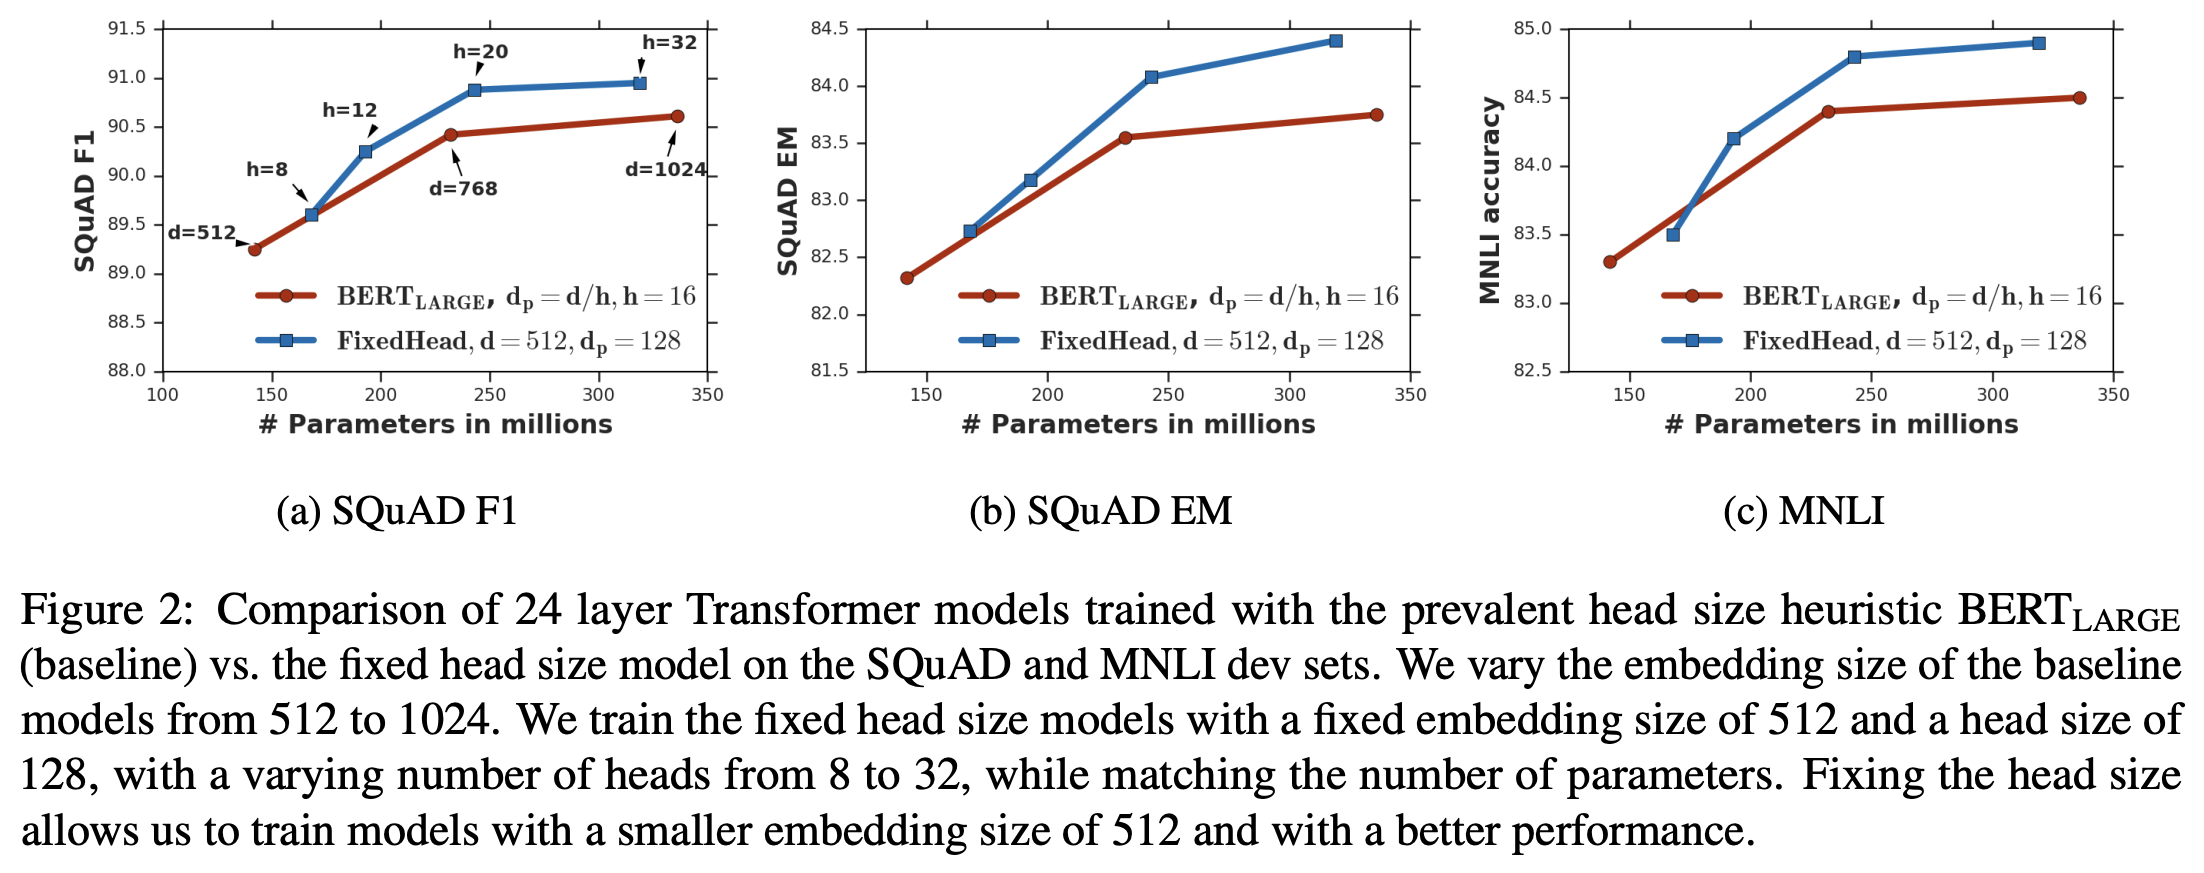 Keeping a relatively large key_size lets the model perform better with the same parameter budget
This result shows that if we fix a relatively large key_size (e.g., 128), we can adjust the model's hidden_size and number of heads so that the total parameter count matches the original BERT design, yet performance improves! So increasing key_size is indeed meaningful — even after readjusting the overall parameter count back to the original size, it still improves the model's performance to some degree. This is undoubtedly an important guide for designing new Transformer models (especially small-scale ones).
Finally, here are two RoBERTa small models we pretrained with increased key_size, which we welcome everyone to use (we call them RoBERTa+):
https://github.com/ZhuiyiTechnology/pretrained-models
No Model Should Lack Talking
The second improvement to Multi-Head Attention comes from the paper Talking-Heads Attention. Although this paper doesn't explicitly point out its connection to the previous one, I believe they are actually addressing the same problem from a different angle: it points out that in current Multi-Head Attention, the computation of each head is mutually isolated, and that by letting heads "talk" to each other, one can obtain a more powerful Attention design — hence the title "Talking-Heads Attention."
From a Single Distribution to a Mixture Distribution
In the previous paper, we mentioned the low-rank bottleneck — that because key_size is too small, $\boldsymbol{Q}^{(i)}{\boldsymbol{K}^{(i)}}^{\top}$ has insufficient expressive power, and so after softmax it can't adequately model a full bivariate distribution. Besides increasing key_size, is there another way to alleviate this problem? Yes — for example, the mixture-distribution idea used in this paper.
A mixture distribution is a superposition (e.g., a weighted average) of multiple simple distributions, and it can greatly enhance the expressive power of the original distribution. A classic example is the Gaussian mixture model: a Gaussian distribution is just a common simple distribution, but a mixture of several Gaussians (also called a Gaussian Mixture Model, GMM) is a much more powerful distribution. In theory, given enough component Gaussians, a Gaussian mixture can approximate any probability distribution. This example tells us that if we want to increase the expressive power of the distribution inside Attention without increasing key_size, we can consider superposing multiple low-rank distributions.
So where do these "multiple" low-rank distributions come from? We already have Multi-Head — each head carries its own low-rank distribution, so we can just superpose them directly. That's exactly Talking-Heads Attention. Concretely, it takes the form:
\begin{equation}\begin{aligned}&\hat{\boldsymbol{J}}^{(1)}=\boldsymbol{Q}^{(1)}{\boldsymbol{K}^{(1)}}^{\top},\quad\hat{\boldsymbol{J}}^{(2)}=\boldsymbol{Q}^{(2)}{\boldsymbol{K}^{(2)}}^{\top},\quad\cdots,\quad\hat{\boldsymbol{J}}^{(h)}=\boldsymbol{Q}^{(h)}{\boldsymbol{K}^{(h)}}^{\top}\\ &\begin{pmatrix}\boldsymbol{J}^{(1)} \\ \boldsymbol{J}^{(2)} \\ \vdots \\ \boldsymbol{J}^{(h)}\end{pmatrix}=\begin{pmatrix}\lambda_{11} & \lambda_{12}& \cdots & \lambda_{1h}\\ \lambda_{21} & \lambda_{22} & \cdots & \lambda_{2h}\\ \vdots & \vdots & \ddots & \vdots\\ \lambda_{h1} & \lambda_{h2} & \cdots & \lambda_{hh} \end{pmatrix}\begin{pmatrix}\hat{\boldsymbol{J}}^{(1)} \\ \hat{\boldsymbol{J}}^{(2)} \\ \vdots \\ \hat{\boldsymbol{J}}^{(h)}\end{pmatrix}\\ &\boldsymbol{P}^{(1)}=softmax\left(\boldsymbol{J}^{(1)}\right),\boldsymbol{P}^{(2)}=softmax\left(\boldsymbol{J}^{(2)}\right),\dots,\boldsymbol{P}^{(h)}=softmax\left(\boldsymbol{J}^{(h)}\right)\\ &\boldsymbol{O}^{(1)}=\boldsymbol{P}^{(1)} \boldsymbol{V}^{(1)},\quad \boldsymbol{O}^{(2)}=\boldsymbol{P}^{(2)} \boldsymbol{V}^{(2)},\quad ,\cdots,\quad\boldsymbol{O}^{(h)}=\boldsymbol{P}^{(h)} \boldsymbol{V}^{(h)}\\ &\boldsymbol{O}=\left[\boldsymbol{O}^{(1)},\boldsymbol{O}^{(2)},\dots,\boldsymbol{O}^{(h)}\right] \end{aligned}\end{equation}
This looks complicated to write out, but it's actually simple: it just means using a parameter matrix $\boldsymbol{\lambda}$, applied after $\boldsymbol{Q}\boldsymbol{K}^{\top}$ and before softmax, to superpose the results of the different $\boldsymbol{Q}\boldsymbol{K}^{\top}$. This connects the originally isolated Attention Heads — a simple form of "talking."
Two additional notes on the formula above:
1. For simplicity, I've omitted the scaling factor $\sqrt{d_k}$ in the formula above; readers can add it back in if needed.
2. A more general form of Talking-Heads Attention allows the $\boldsymbol{J}=\boldsymbol{\lambda}\hat{\boldsymbol{J}}$ step to increase dimensionality, i.e., superposing more than $h$ mixture components before using another parameter matrix to reduce dimensionality again. This is not a particularly important improvement, so I won't dwell on it here.
Let's Look at the Experimental Results Again
Whether this really works, of course, still comes down to the experimental results. The experimental lineup in this paper is unprecedentedly strong — it includes results with BERT, ALBERT, and T5 as baselines all at once! As we all know, BERT, ALBERT, and T5 were each, at some point, the best NLP model around, and T5 in particular still sits at the top of the SuperGLUE leaderboard, far ahead of second place. And this Talking-Heads Attention manages to push their already impressive results to a new high!
As always, check the paper for the full details — here I'll show one fairly typical result:
 Experimental results show that with the Talking-Head mechanism, keeping hidden_size fixed, more heads leads to better results
This result shows that when using Talking-Head Attention, keeping hidden_size fixed, the more heads you have (correspondingly, the smaller key_size and head_size are), the better the performance. This looks like it contradicts the previous paper's conclusion about increasing key_size, but in fact this precisely demonstrates the clear boost that mixture distributions give to distribution-fitting power: it can take a single distribution that's weakened by shrinking key_size and, through superposition, turn it into a much more powerful fitting distribution. Of course, this doesn't mean you should just set key_size=1 and call it done, since with key_size=1 the compute cost would be noticeably larger than the original BERT base — in practice you need to balance performance against compute cost.
The table above is just the tip of the iceberg of the original paper's experiments. Here's another experimental table to give you a sense of just how extensive the experimental lineup is:
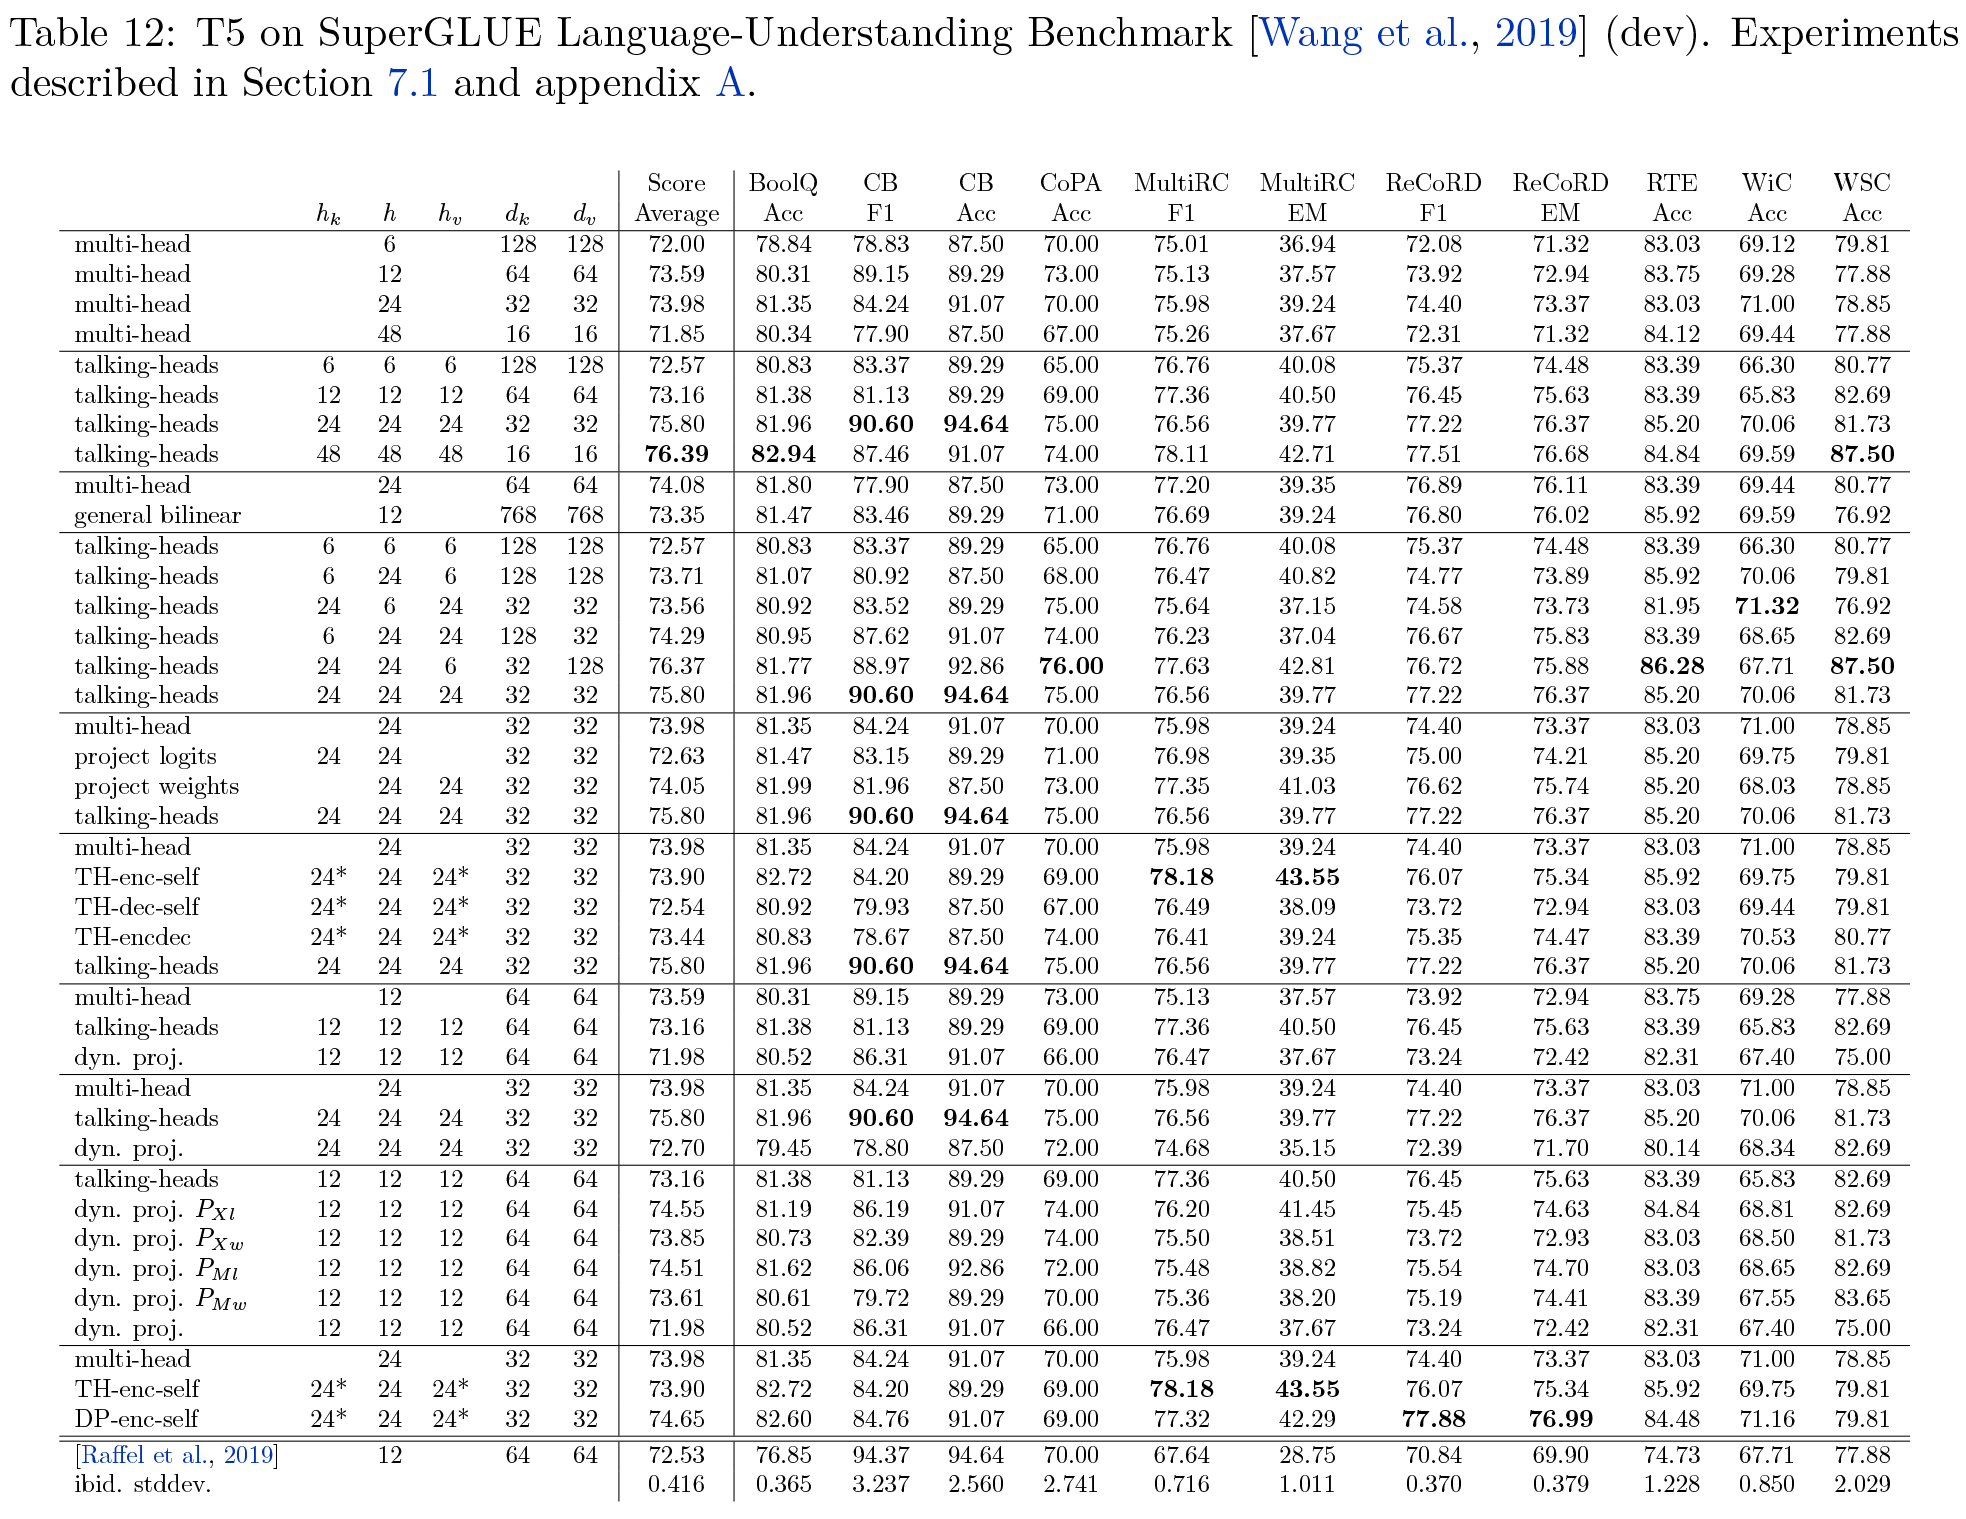 Experimental results of T5 + Talking-Heads Attention on SuperGLUE
Almost every task, every hyperparameter combination, was tested and reported. Such a massive experimental effort is basically something only Google could pull off, and the whole paper is clearly saturated with "T5 style" (readers who haven't read the T5 paper yet can go check out Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer to get a feel for it). And sure enough, one of the co-authors, Noam Shazeer, is also one of the authors of T5.
All I can say is that this kind of massive barrage of experiments feels like it's announcing to us:
No need to question it — we've tuned every hyperparameter there is to tune, and our Talking-Heads Attention wins.
Interlude: A Curious Writing Style
That said, when I first came across Talking-Heads Attention on Arxiv, my initial impression was that it was a junk paper. Why? Because it's written like this:
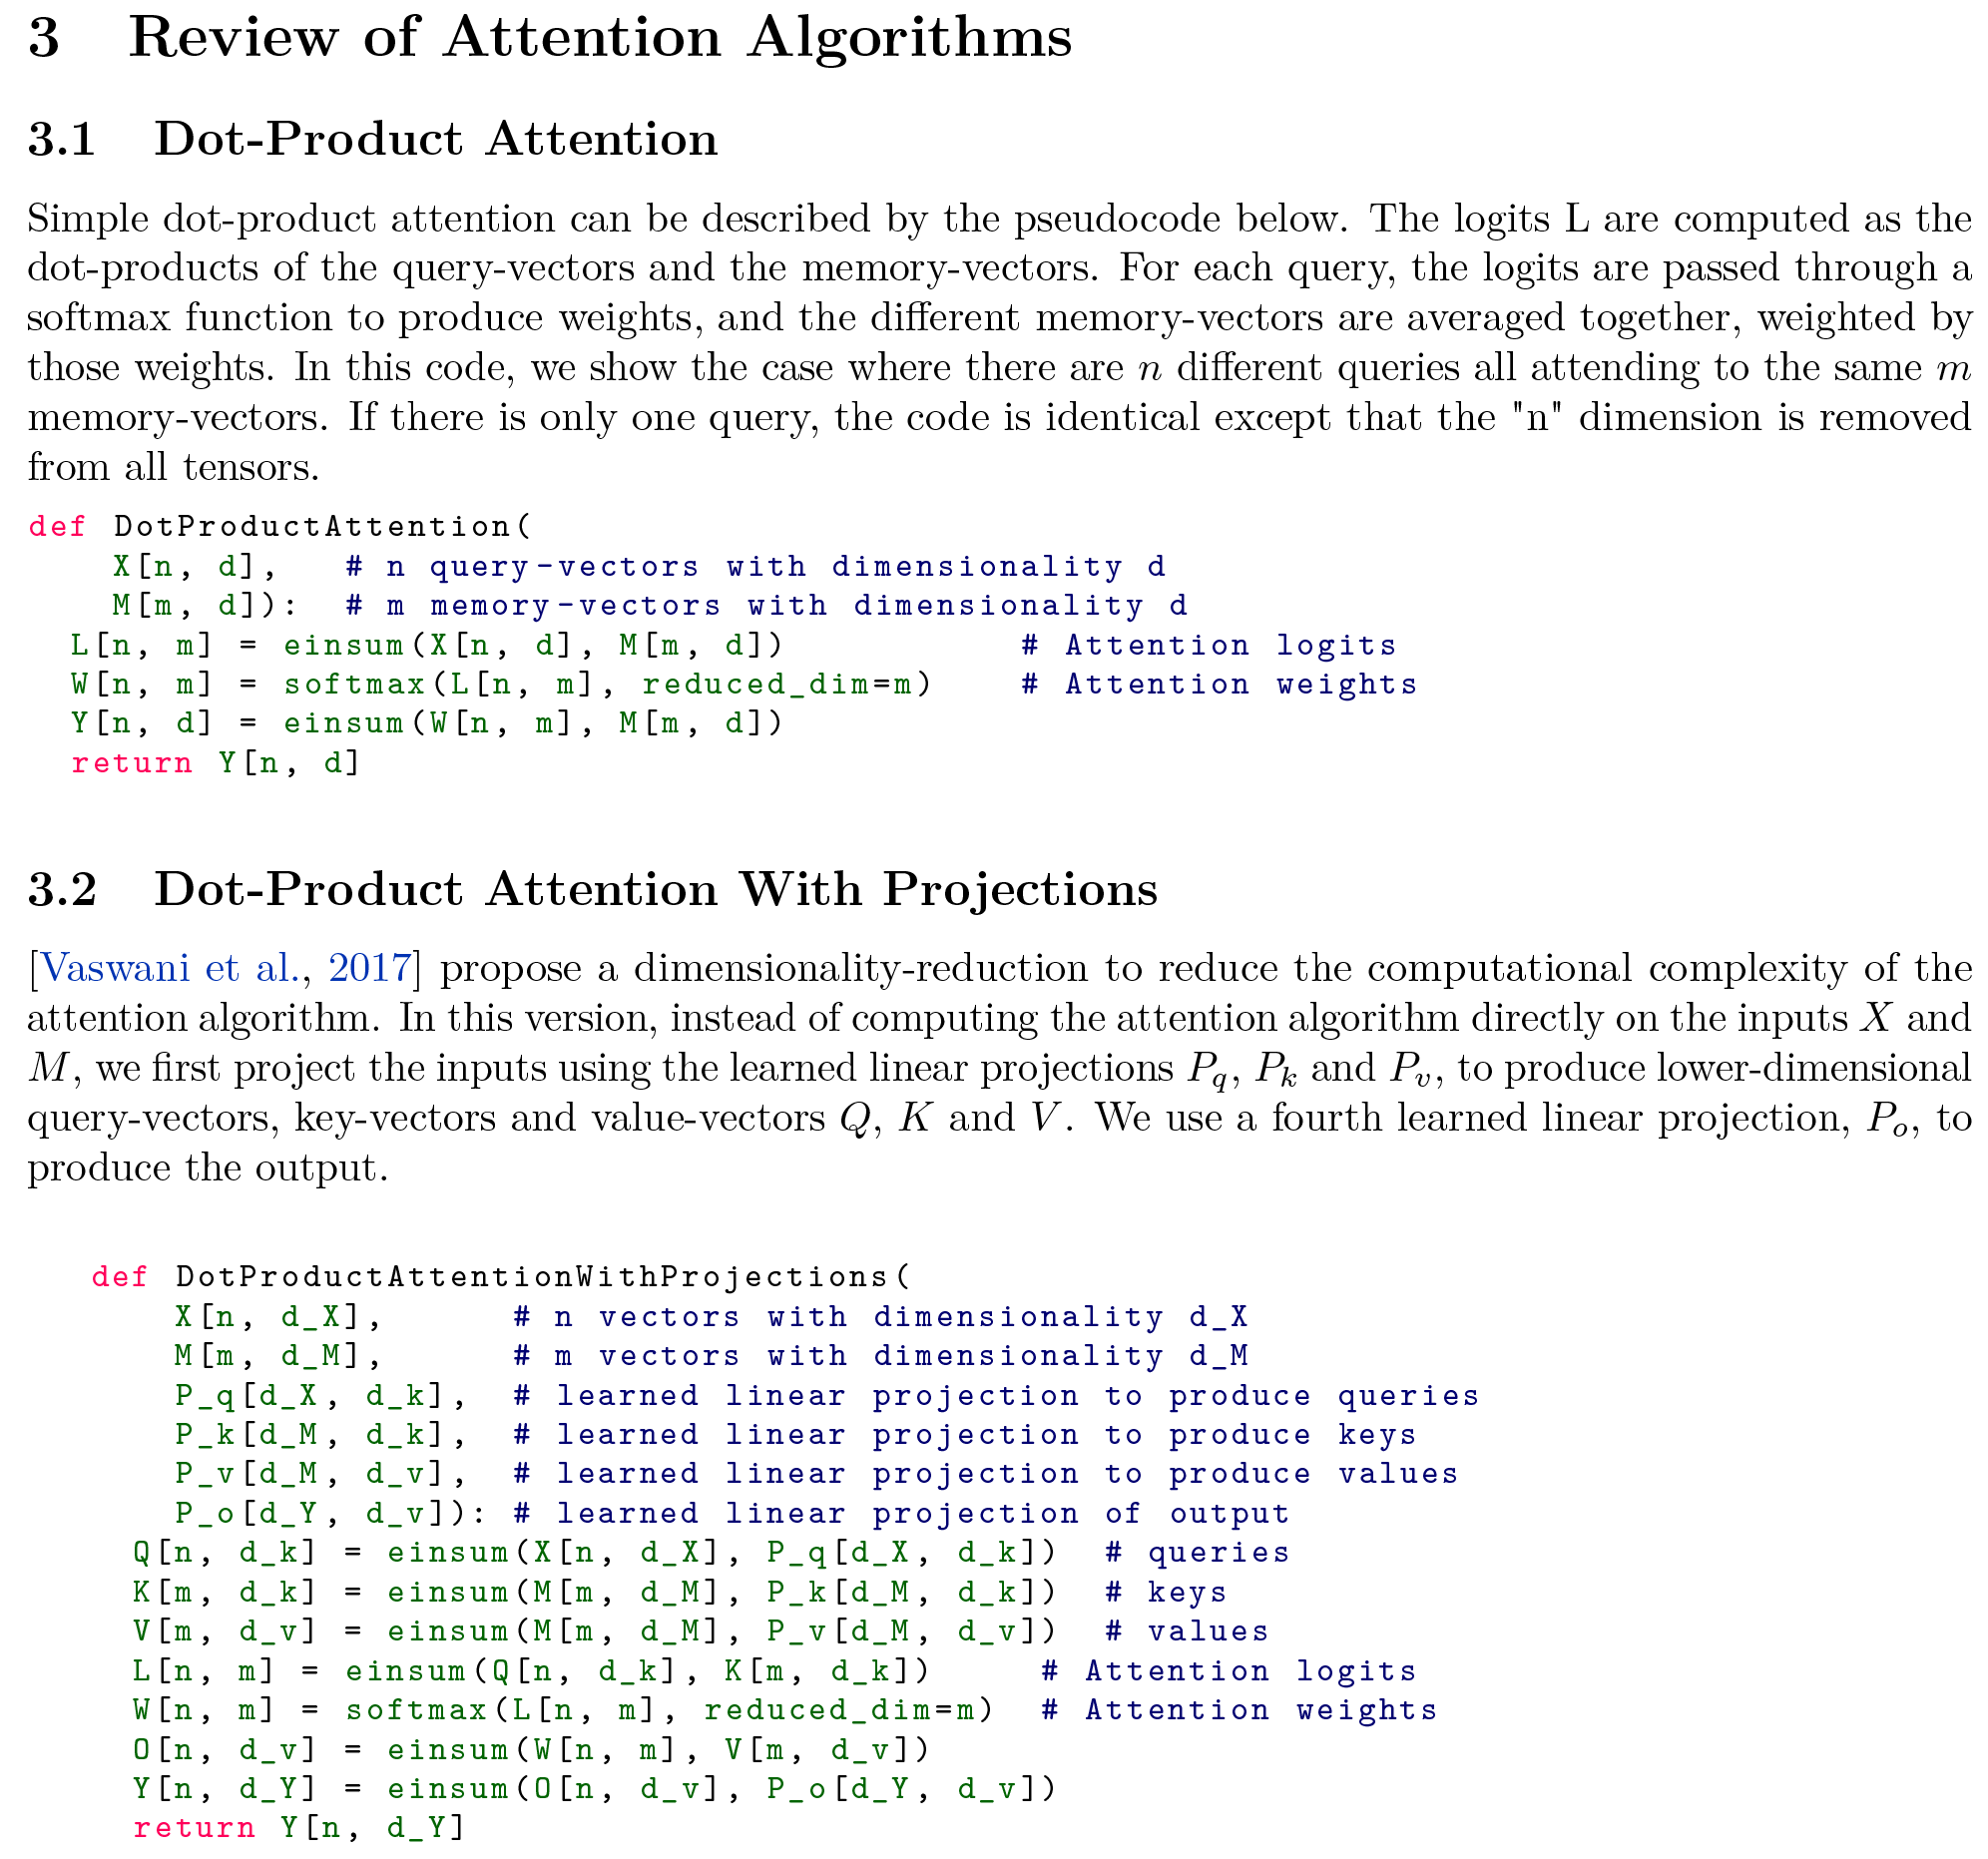 Pseudocode from Talking-Heads Attention
Who would have imagined that such a powerful paper wouldn't contain a single mathematical equation, and would instead be filled entirely with pseudocode!! Actually, it's not even really pseudocode — it feels more like the Python code from the experiments was copy-pasted directly into the paper, right into the main body of the text! In my experience, it's usually only low-quality papers that do this, so my first reaction upon seeing it was "this must be junk." Only Google's top researchers could get away with being this cavalier about it — if I hadn't been patient enough to skim a few more lines, if I hadn't happened to notice the mention of T5, and if I hadn't gone back to check that the authors were, without exception, all from Google, I would have tossed this powerful paper straight into the recycle bin as junk.
But being cavalier has its price: even though this paper — with such a strong and effective experimental lineup — has been out for over a month now, it doesn't seem to have gotten much attention, which is probably partly due to this idiosyncratic style.
A Small Summary at the End
This post introduced two follow-up works improving Multi-Head Attention. Although the details of their improvements differ, both can be said to address the "low-rank bottleneck" problem, arriving at similar destinations by different paths. Both works come from Google and include extensive experiments, so their conclusions are fairly convincing. Readers currently working on architectural improvements to models may find them worth referencing.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.