ON-LSTM: Expressing Hierarchical Structure with Ordered Neurons
Today I'll introduce an interesting LSTM variant: ON-LSTM, where "ON" stands for "Ordered Neurons" — in other words, the neurons inside this kind of LSTM are arranged in a specific order, which lets it express richer information. ON-LSTM comes from the paper Ordered Neurons: Integrating Tree Structures into Recurrent Neural Networks. As the name suggests, giving the neurons a specific ordering is meant to integrate hierarchical (tree) structure into the LSTM, so that the LSTM can automatically learn hierarchical structural information. This paper has another distinction: it was one of the two Best Papers at ICLR 2019, which shows that incorporating hierarchical structure into neural networks (rather than relying purely on simple fully-connected links) is a topic of shared interest among many researchers.
I came across ON-LSTM through an introduction from Synced (机器之心), which mentioned that besides improving language model performance, it could even learn a sentence's syntactic structure in an unsupervised way! It was precisely this feature that drew me in deeply, and its recent recognition as an ICLR 2019 Best Paper only strengthened my resolve to fully understand it. After nearly a week of careful reading and derivation, I finally got somewhere, hence this post.
Before formally introducing ON-LSTM, I can't help but complain first that this paper is written extremely poorly. A design that is actually quite vivid and intuitive is described in an unnecessarily obscure way — the core of it lies in the definitions of $\tilde{f}_t$ and $\tilde{i}_t$, which are dropped into the text with almost no buildup and hardly any explanation. I read it several times at the start and it still felt like an indecipherable scripture... In short, the writing really leaves something to be desired.
Background
As is customary, the first half of a post like this has to cover some background first.
Recap of LSTM
Let's first recall the ordinary LSTM. Using common notation, a standard LSTM is written as:
\begin{equation}\begin{aligned} f_{t} & = \sigma \left( W_{f} x_{t} + U_{f} h_{t - 1} + b_{f} \right) \\ i_{t} & = \sigma \left( W_{i} x_{t} + U_{i} h_{t - 1} + b_{i} \right) \\ o_{t} & = \sigma \left( W_{o} x_{t} + U_{o} h_{t - 1} + b_{o} \right) \\ \hat{c}_t & = \tanh \left( W_{c} x_{t} + U_{c} h_{t - 1} + b_{c} \right)\\ c_{t} & = f_{t} \circ c_{t - 1} + i_{t} \circ \hat{c}_t \\ h_{t} & = o_{t} \circ \tanh \left( c_{t} \right)\end{aligned}\label{eq:lstm}\end{equation}
If you're already familiar with neural networks, there's nothing mysterious about this structure: $f_t,i_t,o_t$ are simply three single-layer fully-connected models, whose inputs are the historical information $h_{t-1}$ and the current information $x_t$, activated with sigmoid. Since sigmoid outputs lie between 0 and 1, they can be interpreted as "gates," respectively called the forget gate, input gate, and output gate. Personally, I feel the name "gate" isn't quite fitting — "valve" might be a better description.
With the gates in hand, $x_t$ is combined into $\hat{c}_t$, and then combined with the preceding "gates" via the $\circ$ operation (elementwise multiplication, sometimes also denoted $\otimes$), to produce a weighted sum of $c_{t-1}$ and $\hat{c}_t$.
Below is a diagram I drew myself illustrating the LSTM computation flow:
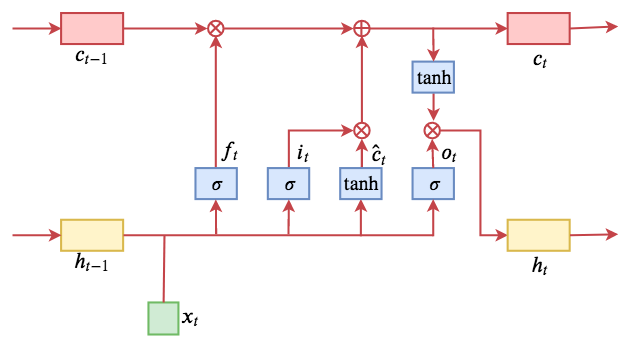 Diagram of the LSTM computation flow
Language and order information
In common neural networks, neurons are typically unordered — for instance, the forget gate $f_t$ is a vector whose elements have no particular positional pattern. If we shuffled the positions of all the vectors involved in the LSTM computation in the same way, and shuffled the order of the weights accordingly, the output would merely become a reordering of the original vector (and, in a multi-layer setting, could even remain completely unchanged) — the amount of information carried would be unaffected, and it would not hinder subsequent networks from using it.
In other words, neither LSTM nor ordinary neural networks make use of any ordering information among neurons. ON-LSTM attempts to order these neurons and use this ordering to represent certain specific structures, thereby putting the neurons' ordering information to use.
The object of ON-LSTM's thinking is natural language. A natural sentence can generally be represented as a set of hierarchical structures; when abstracted out by hand, these structures are what we call syntactic information. ON-LSTM hopes that a model can naturally learn such hierarchical structure during training, and that once training is finished, this structure can be extracted (visualized) — this is precisely where the ordering information of neurons mentioned above comes into play. (I had done related research on this before: The Minimum Entropy Principle (III): "Crossing the River by Feeling the Stones" — Sentence Templates and Language Structure.)
To reach this goal, we need a notion of levels: the lower the level, the finer-grained the linguistic structure it represents, and the higher the level, the coarser-grained the structure. For instance, in a Chinese sentence, "characters" can be considered the lowest-level structure, "words" the next level up, and above that phrases, and so on. The higher the level, the coarser the granularity, and correspondingly, the larger its span within the sentence.
Using the original paper's illustration:
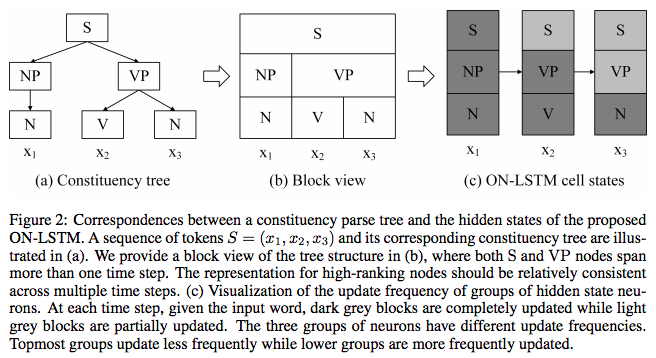 Hierarchical structure leads to different spans for different levels, i.e., information at different levels propagates over different distances. This will ultimately lead us to represent hierarchical structure in matrix form so that it can be incorporated into the neural network.
ON-LSTM
That last sentence — "the higher the level, the coarser the granularity, and correspondingly, the larger its span within the sentence" — may sound like a truism, but it is actually the guiding principle behind ON-LSTM's design. First, it requires that our design of the ON-LSTM encoding be able to distinguish information at higher versus lower levels. Second, it also tells us that high-level information should be retained longer in the encoding interval corresponding to high levels (i.e., not easily filtered out by the forget gate), whereas low-level information should be more easily forgotten in its corresponding interval.
Design: interval-wise updates
With this guiding principle in hand, we can start building the model. Suppose that once the neurons in ON-LSTM are sorted, elements of the vector $c_t$ with smaller indices represent lower-level information, while elements with larger indices represent higher-level information. Then the gate structure and output structure of ON-LSTM remain the same as in an ordinary LSTM:
\begin{equation}\begin{aligned} f_{t} & = \sigma \left( W_{f} x_{t} + U_{f} h_{t - 1} + b_{f} \right) \\ i_{t} & = \sigma \left( W_{i} x_{t} + U_{i} h_{t - 1} + b_{i} \right) \\ o_{t} & = \sigma \left( W_{o} x_{t} + U_{o} h_{t - 1} + b_{o} \right) \\ \hat{c}_t & = \tanh \left( W_{c} x_{t} + U_{c} h_{t - 1} + b_{c} \right)\\ h_{t} & = o_{t} \circ \tanh \left( c_{t} \right) \end{aligned}\label{eq:update-o0}\end{equation}
The difference lies in the update mechanism from $\hat{c}_t$ to $c_t$.
Next, we initialize an all-zero $c_t$, i.e., with no memory at all — imagine it as an empty USB drive. We then store the historical information and the current input into $c_t$ according to a certain rule (i.e., update $c_t$). Before each update to $c_t$, we first predict two integers $d_f$ and $d_i$, representing the levels of the historical information $h_{t-1}$ and the current input $x_t$ respectively:
\begin{equation}\begin{aligned} d_f = F_1\left(x_t, h_{t-1}\right) \\ d_i = F_2\left(x_t, h_{t-1}\right) \end{aligned}\end{equation}
As for the concrete structure of $F_1, F_2$, we'll fill that in later — let's first make the core idea clear. This is exactly why I take issue with the original paper's writing: it defines $\text{cumax}$ right off the bat, without ever properly explaining the underlying idea, either before or after.
Once we have $d_f,d_i$, there are two possibilities:
1. $d_f \leq d_i$, which means the level of the current input $x_t$ is higher than the level of the historical record $h_{t-1}$. This means the two streams of information overlap, and the current input needs to be integrated into levels greater than or equal to $d_f$, as follows:
\begin{equation}\begin{aligned} c_t = \begin{pmatrix}\hat{c}_{t,< d_f} \\ f_{t,[d_f:d_i]}\circ c_{t-1,[d_f:d_i]} + i_{t,[d_f:d_i]}\circ \hat{c}_{t,[d_f:d_i]} \\ c_{t-1,> d_i} \end{pmatrix}\end{aligned}\label{eq:update-o1}\end{equation}
This formula says that, since the current input is at a higher level, it affects the intersecting part $[d_f, d_i]$, which is updated by the ordinary LSTM update formula; the part below $d_f$ is directly overwritten with the corresponding part of the current input $\hat{c}_t$; and the part above $d_i$ keeps the corresponding part of the historical record $c_{t-1}$ unchanged.
This update formula matches our intuition, since we have already sorted the neurons so that neurons at earlier positions store lower-level structural information. As for the current input, it clearly is more likely to affect low-level information, so the "reach" of the current input is $[0, d_i]$ (from the bottom up) — or, equivalently, the storage space required by the current input is $[0, d_i]$. As for the historical record, it retains high-level information, so its "reach" is $[d_f, d_{\max}]$ (from the top down, where $d_{\max}$ is the highest level) — or one could say that the storage space required by the historical information is $[d_f, d_{\max}]$. In the non-overlapping parts, each "minds its own business" and retains its own information; in the overlapping part, information must be merged, which reduces to the ordinary LSTM.
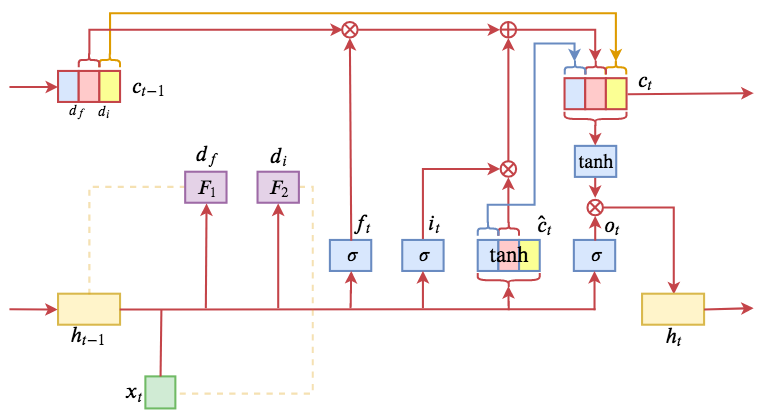 ON-LSTM design diagram. The core idea is to sort the LSTM's neurons and then update them piecewise.
2. $d_f > d_i$, which means the historical record $h_{t-1}$ and the current input $x_t$ do not overlap at all. Then the interval $(d_i, d_f)$ is "left unattended," so it simply keeps its initial state (i.e., all zeros, which can be understood as nothing having been written there); as for the rest, the current input writes its own information directly into the $[0, d_i]$ interval, while the historical information writes directly into the $[d_f, d_{\max}]$ interval. In this case, the current input and historical information together do not fill up the entire storage space, leaving some capacity unused (the all-zero part in the middle):
\begin{equation}\begin{aligned} c_t = \begin{pmatrix}\hat{c}_{t,\leq d_i} \\ 0_{(d_i : d_f)} \\ c_{t-1,\geq d_f} \end{pmatrix}\end{aligned}\label{eq:update-o2}\end{equation}
Here $(d_i : d_f)$ denotes the interval greater than $d_i$ and less than $d_f$, while the earlier $[d_f : d_i]$ denotes the interval greater than or equal to $d_f$ and less than or equal to $d_i$.
At this point we can understand the basic principle of ON-LSTM: after sorting the neurons, it uses positional order to represent the level of information — lower or higher — and when updating the neurons, it first predicts the level of the historical information $d_f$ and the level of the input $d_i$ separately, and uses these two levels to perform an interval-wise update of the neurons.
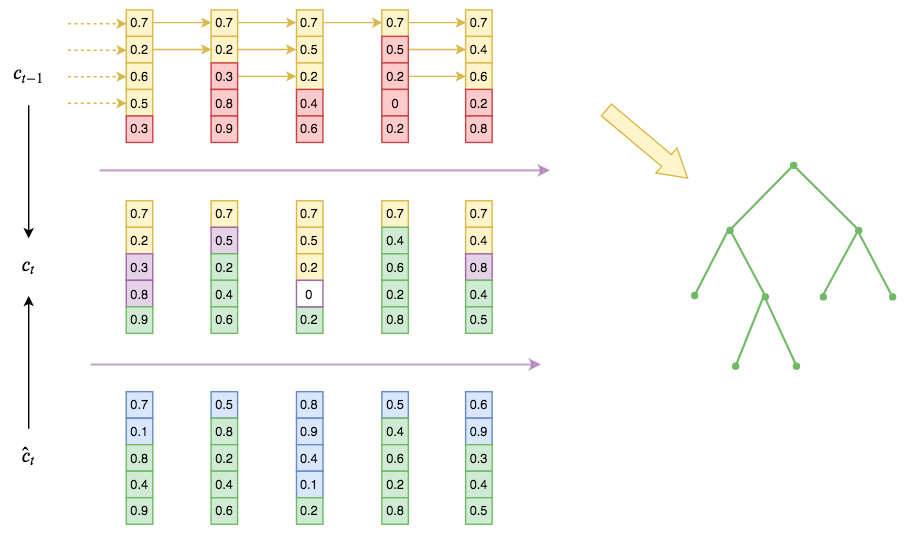 Illustration of ON-LSTM's interval-wise update. The numbers in the figure are randomly generated; the top row is the historical information, the bottom row is the current input, and the middle row is the currently integrated output. The yellow part at the top represents the historical information level (master forget gate), the green part at the bottom represents the input information level (master input gate); the yellow part in the middle is historical information copied directly, the green part is input information copied directly, the purple part is the intersecting information merged in the LSTM manner, and the white part is the mutually unrelated "blank zone." From the copying and propagation of historical information (the yellow part at the top), we can extract a corresponding hierarchical structure like the one shown on the right (note that the hierarchical structure on the right does not correspond exactly to the drawing process — it is only a rough illustration; readers should focus on an intuitive sense of the figure and the model rather than scrutinizing the exact correspondence).
In this way, high-level information can be preserved over a considerably long distance (because the high levels directly copy the historical information, so it may keep being copied without change), while low-level information can be updated at every single step (because the low levels directly copy the input, and the input keeps changing). Thus, hierarchical structure is embedded by grading information. Put more plainly, this is a grouped update scheme: information in higher groups travels further (larger span), while information in lower groups has a smaller span, and these different spans form the hierarchical structure of the input sequence.
(Please read this passage repeatedly, checking it against the figure above if needed, until you fully understand it — this passage can be considered the design manifesto of ON-LSTM.)
Realization: piecewise softening
The problem we now need to solve is how to predict these two levels, i.e., how to construct $F_1, F_2$. It isn't hard to use a model to output an integer, but such a model is typically non-differentiable and cannot be readily integrated into the whole model for backpropagation. So a better approach is to "soften" it, i.e., to seek some smooth approximation.
To carry out this softening, let's first rewrite $\eqref{eq:update-o1},\eqref{eq:update-o2}$. Introduce the notation $1_k$, denoting a $d_{\max}$-dimensional vector (i.e., a one-hot vector) whose $k$-th position is 1 and all others are 0. Then $\eqref{eq:update-o1},\eqref{eq:update-o2}$ can be uniformly written as
\begin{equation}\begin{aligned}\tilde{f}_t & = \stackrel{\rightarrow}{\text{cs}}\left(1_{d_f}\right), \quad \tilde{i}_t = \stackrel{\leftarrow}{\text{cs}}\left(1_{d_i}\right) \\ \omega_t & = \tilde{f}_t \circ \tilde{i}_t \quad (\text{used to denote intersection})\\ c_t & = \underbrace{\omega_t \circ \left(f_{t} \circ c_{t - 1} + i_{t} \circ \hat{c}_t \right)}_{\text{intersection part}} + \underbrace{\left(\tilde{f}_t - \omega_t\right)\circ c_{t - 1}}_{\text{greater than}\max\left(d_f, d_i\right)\text{part of}} + \underbrace{\left(\tilde{i}_t - \omega_t\right)\circ \hat{c}_{t}}_{\text{less than}\min\left(d_f,d_i\right)\text{part of}} \end{aligned}\label{eq:update-o3}\end{equation}
where $\stackrel{\rightarrow}{\text{cs}}$/$\stackrel{\leftarrow}{\text{cs}}$ are the rightward/leftward cumsum operations, respectively:
\begin{equation}\begin{aligned}\stackrel{\rightarrow}{\text{cs}}([x_1,x_2,\dots,x_n]) & = [x_1, x_1+x_2, \dots,x_1+x_2+\dots+x_n]\\ \stackrel{\leftarrow}{\text{cs}}([x_1,x_2,\dots,x_n]) & = [x_1+x_2+\dots+x_n,\dots,x_n+x_{n-1},x_n]\end{aligned}\end{equation}
Note that the result given by $\eqref{eq:update-o3}$ here is completely equivalent to the result given by the case-by-case definition of $\eqref{eq:update-o1},\eqref{eq:update-o2}$. This can be seen just by noting that $\tilde{f}_t$ gives a $d_{\max}$-dimensional vector that is all 1's from position $d_f$ onward and 0 elsewhere, while $\tilde{i}_t$ gives a $d_{\max}$-dimensional vector that is all 1's from position 0 up to position $d_i$ and 0 elsewhere. So $\omega_t = \tilde{f}_t \circ \tilde{i}_t$ gives precisely a vector that is 1 on the intersection and 0 everywhere else (if there is no intersection, it's the all-zero vector) — so the term $\omega_t \circ \left(f_{t} \circ c_{t - 1} + i_{t} \circ \hat{c}_t \right)$ handles the intersecting part. Meanwhile, $\left(\tilde{f}_t - \omega_t\right)$ gives a $d_{\max}$-dimensional vector that is all 1's from position $\max\left(d_f,d_i\right)$ onward and 0 elsewhere, precisely marking the range of the historical information $[d_f, d_{\max}]$ with the intersection removed; and $\left(\tilde{i}_t - \omega_t\right)$ gives a $d_{\max}$-dimensional vector that is all 1's from position $0\sim \min\left(d_f,d_i\right)$ and 0 elsewhere, precisely marking the range of the current input $[0, d_i]$ with the intersection removed.
Now, the update formula for $c_t$ is described by equation $\eqref{eq:update-o3}$, where the two one-hot vectors $1_{d_f},1_{d_i}$ are determined by two integers $d_f,d_i$, which in turn are predicted by a model $F_1, F_2$. So we might as well have the model directly predict $1_{d_f},1_{d_i}$ itself. Of course, even if we predict two one-hot vectors, this doesn't change the fact that the whole update process remains non-differentiable. However, we can consider replacing $1_{d_f},1_{d_i}$ with ordinary floating-point vectors, for instance:
\begin{equation}\begin{aligned}1_{d_f}\approx& softmax\left( W_{\tilde{f}} x_{t} + U_{\tilde{f}} h_{t - 1} + b_{\tilde{f}} \right)\\ 1_{d_i}\approx& softmax\left( W_{\tilde{i}} x_{t} + U_{\tilde{i}} h_{t - 1} + b_{\tilde{i}} \right) \end{aligned}\end{equation}
In this way, using a fully-connected layer that maps to $h_{t-1}$ and $x_t$, we can predict two vectors and apply $softmax$, which serves as an approximation to $1_{d_f},1_{d_i}$ and is fully differentiable. Substituting these in place of $1_{d_f},1_{d_i}$ into $\eqref{eq:update-o3}$ then gives us ON-LSTM's update formula for $c_t$:
\begin{equation}\begin{aligned}\tilde{f}_t & = \stackrel{\rightarrow}{\text{cs}}\left(softmax\left( W_{\tilde{f}} x_{t} + U_{\tilde{f}} h_{t - 1} + b_{\tilde{f}} \right)\right)\\ \tilde{i}_t & = \stackrel{\leftarrow}{\text{cs}}\left(softmax\left( W_{\tilde{i}} x_{t} + U_{\tilde{i}} h_{t - 1} + b_{\tilde{i}} \right)\right) \\ \omega_t & = \tilde{f}_t \circ \tilde{i}_t \quad (\text{used to denote intersection})\\ c_t & = \underbrace{\omega_t \circ \left(f_{t} \circ c_{t - 1} + i_{t} \circ \hat{c}_t \right)}_{\text{intersection part}} + \underbrace{\left(\tilde{f}_t - \omega_t\right)\circ c_{t - 1}}_{\text{greater than}\max\left(d_f, d_i\right)\text{part of}} + \underbrace{\left(\tilde{i}_t - \omega_t\right)\circ \hat{c}_{t}}_{\text{less than}\min\left(d_f,d_i\right)\text{part of}} \end{aligned}\end{equation}
Writing the remaining part (i.e., $\eqref{eq:update-o0}$) together as well, the complete update formula for ON-LSTM is:
\begin{equation}\begin{aligned} f_{t} & = \sigma \left( W_{f} x_{t} + U_{f} h_{t - 1} + b_{f} \right) \\ i_{t} & = \sigma \left( W_{i} x_{t} + U_{i} h_{t - 1} + b_{i} \right) \\ o_{t} & = \sigma \left( W_{o} x_{t} + U_{o} h_{t - 1} + b_{o} \right) \\ \hat{c}_t & = \tanh \left( W_{c} x_{t} + U_{c} h_{t - 1} + b_{c} \right)\\ \tilde{f}_t & = \stackrel{\rightarrow}{\text{cs}}\left(softmax\left( W_{\tilde{f}} x_{t} + U_{\tilde{f}} h_{t - 1} + b_{\tilde{f}} \right)\right)\\ \tilde{i}_t & = \stackrel{\leftarrow}{\text{cs}}\left(softmax\left( W_{\tilde{i}} x_{t} + U_{\tilde{i}} h_{t - 1} + b_{\tilde{i}} \right)\right) \\ \omega_t & = \tilde{f}_t \circ \tilde{i}_t\\ c_t & = \omega_t \circ \left(f_{t} \circ c_{t - 1} + i_{t} \circ \hat{c}_t \right) + \left(\tilde{f}_t - \omega_t\right)\circ c_{t - 1} + \left(\tilde{i}_t - \omega_t\right)\circ \hat{c}_{t}\\ h_{t} & = o_{t} \circ \tanh \left( c_{t} \right)\end{aligned}\end{equation}
Here is the corresponding diagram. Comparing it with the LSTM's $\eqref{eq:lstm}$, you can see exactly where the main changes lie. The newly introduced $\tilde{f}_t$ and $\tilde{i}_t$ are called by the authors the "master forget gate" and "master input gate," respectively.
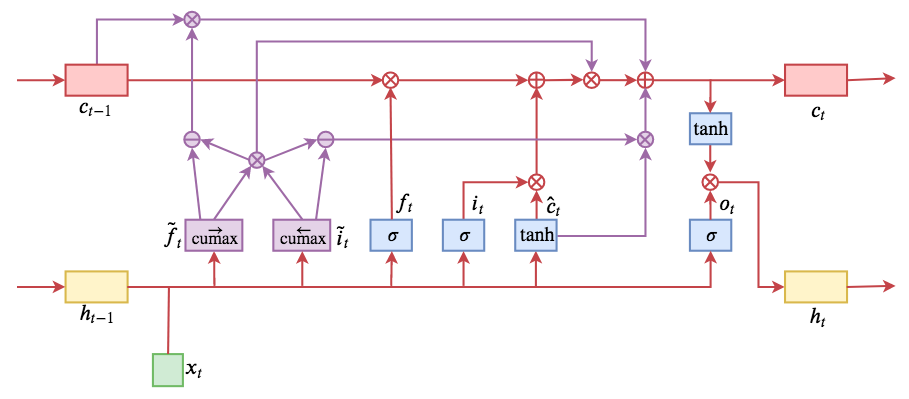 Diagram of the ON-LSTM computation flow. The main idea is to smooth the piecewise function into a differentiable one using cumax.
Notes:
1. In the paper, $\stackrel{\rightarrow}{\text{cs}}(softmax(x))$ is abbreviated as $\text{cumax}(x)$ — this is merely a change in notation.
2. Viewed as a sequence, $\hat{f}_t$ is monotonically increasing, while $\hat{i}_t$ is monotonically decreasing.
3. For $\tilde{i}_t$, the paper defines it as
\begin{equation}1-\text{cumax}\left( W_{\tilde{i}} x_{t} + U_{\tilde{i}} h_{t - 1} + b_{\tilde{i}} \right)\end{equation}
This choice produces a similarly monotonically decreasing vector, and in general there's no real difference — but from the standpoint of symmetry, I think my choice is somewhat more reasonable.
Experiments and Reflections
Below I'll briefly summarize the experiments on ON-LSTM, including the original author's implementation (PyTorch) as well as my own reproduction (Keras), and finally share some thoughts of mine on ON-LSTM.
Author's implementation: https://github.com/yikangshen/Ordered-Neurons
My own implementation: https://github.com/bojone/on-lstm
(Given my limited expertise, my understanding and reproduction may contain errors — if readers spot any, please feel free to point them out, thanks. My own reproduction is currently only guaranteed to run under Python 2.7 + TensorFlow 1.8 + Keras 2.24; other environments are not guaranteed.)
Grouping the hierarchy
The vector $\tilde{f}_t,\tilde{i}_t$ representing the hierarchy needs to undergo the $\circ$ operation together with $f_t$ and others, which means their dimensions (i.e., number of neurons) must match. But we know that, depending on the requirements, the number of hidden neurons in an LSTM can reach several hundred or even several thousand, which would mean the number of levels described by $\tilde{f}_t,\tilde{i}_t$ is also in the hundreds or thousands. In practice, however, the total number of levels in a sequence's hierarchical structure (if it exists at all) generally isn't very large, so there's a bit of a mismatch here.
The authors of ON-LSTM came up with a fairly sensible solution: suppose the number of hidden neurons is $n$, which can be factored as $n=pq$. Then we only need to construct a $\tilde{f}_t,\tilde{i}_t$ with $p$ neurons, and repeat each neuron of $\tilde{f}_t,\tilde{i}_t$ $q$ times in sequence, giving us a $\tilde{f}_t,\tilde{i}_t$ of dimension $n$, which is then used in the $\circ$ operation with $f_t$ and so on. For example, with $n=6=2\times 3$, we first construct a 2-dimensional vector such as $[0.1, 0.9]$, and then repeat each entry 3 times in sequence to get $[0.1, 0.1, 0.1, 0.9, 0.9, 0.9]$.
This way, we both reduce the total number of levels and reduce the number of parameters in the model, since $p$ can typically be taken fairly small (1–2 orders of magnitude smaller than $n$). Hence, compared to an ordinary LSTM, ON-LSTM doesn't add much in terms of parameter count.
Language modeling
The authors ran a number of experiments, including language modeling, syntactic evaluation, logical inference, and so on, achieving state-of-the-art results in many of them, generally outperforming ordinary LSTMs — which demonstrates that the hierarchical structure information introduced by ON-LSTM is indeed valuable. The one I'm most familiar with is language modeling, so let me just include a screenshot of the language modeling experiment:
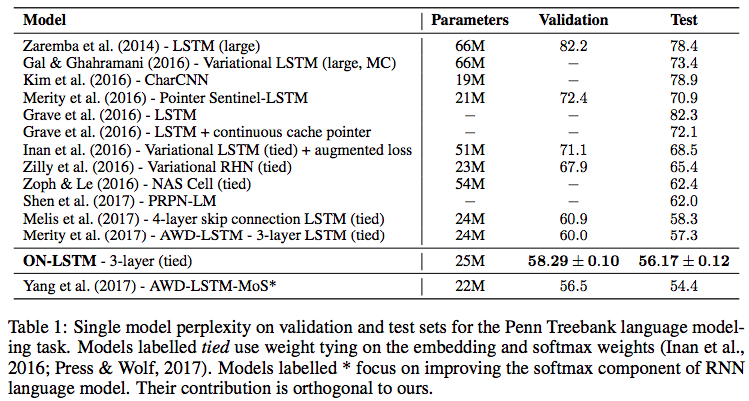 Language modeling experiment results from the original ON-LSTM paper
Unsupervised syntax
If ON-LSTM only outperformed ordinary LSTMs on some routine language tasks, it wouldn't really count as a breakthrough. But one exciting property of ON-LSTM is that it can extract the hierarchical tree structure of an input sequence in an unsupervised manner from a trained model (such as a language model). Here's the idea behind the extraction:
First, let's consider:
\begin{equation}p_f = softmax\left( W_{\tilde{f}} x_{t} + U_{\tilde{f}} h_{t - 1} + b_{\tilde{f}} \right)\end{equation}
This is the result of $\tilde{f}_t$ before $\stackrel{\rightarrow}{\text{cs}}$, and based on our earlier derivation, it's a softened version of the level $d_f$ of historical information, so we can write:
\begin{equation}d_f\approx\mathop{\text{argmax}}_{k} p_f(k)\end{equation}
Here $p_f(k)$ refers to the $k$-th element of the vector $p_f$. However, since $softmax$ contained within $p_f$ is itself already a "softened" operator, in this case it may be better to consider a "softened" version of $\text{argmax}$ (see Musings on Function Smoothing: Differentiable Approximations to Non-Differentiable Functions), i.e.:
\begin{equation}d_f\approx \sum_{k=1}^n k\times p_f(k)=n\left(1 - \frac{1}{n}\sum_{k=1}^n \tilde{f}_t(k)\right)+1\end{equation}
The second equality is an identity transformation, which readers can verify for themselves (Equation $(15)$ in the original paper has an error). This gives us a formula for computing the level, which, when $n$ is fixed, depends directly on $\left(1 - \frac{1}{n}\sum\limits_{k=1}^n \tilde{f}_t(k)\right)$
This way, we can use the sequence
\begin{equation}\left\{d_{f,t}\right\}_{t=1}^{\text{seq_len}}=\left\{\left(1 - \frac{1}{n}\sum\limits_{k=1}^n \tilde{f}_t(k)\right)\right\}_{t=1}^{\text{seq_len}}\end{equation}
to represent the variation in levels across the input sequence. With this level sequence in hand, we can extract the hierarchical structure using the following greedy algorithm:
Feed the input sequence $\left\{x_{t}\right\}$ into a pretrained ON-LSTM to obtain the corresponding level sequence $\left\{d_{f,t}\right\}$, then find the index of the maximum value in the level sequence, say $k$, and split the input sequence into partitions accordingly: $[x_{t < k}, [x_k, x_{t > k}]]$. Then repeat the above procedure on the subsequences $x_{t < k}$ and $x_{t > k}$, until every subsequence has length 1.
The rough intuition behind the algorithm is to split at the point of highest level (since this means the historical information contained there is the least, and its connection to everything preceding it is weakest, making it most likely the start of a new substructure), then recurse, gradually recovering the nested structure implicit in the input sequence. The authors trained a three-layer ON-LSTM as a language model, then used the $\tilde{f}_t$ of the middle layer to compute the levels, and compared them against annotated syntactic structures, finding fairly high accuracy. I also tried this myself on Chinese corpora: https://github.com/bojone/on-lstm/blob/master/lm_model.py
As for the results — since I've never done syntactic parsing and don't really understand it, I'm not sure how to evaluate it. It seems to kind of make sense, but also seems a bit off in places, so I'll leave readers to judge for themselves. In the past year or two, there's actually been quite a bit of research on unsupervised syntactic parsing, and one probably needs to read through all of it to get a deeper understanding of ON-LSTM.
Input: 苹果的颜色是什么 (What is the color of the apple)
Output:
[
[
[
'苹果 (apple)',
'的 (of)'
],
[
'颜色 (color)',
'是 (is)'
]
],
'什么 (what)'
]
Input: 爱真的需要勇气 (Love really needs courage)
Output:
[
'爱 (love)',
[
'真的 (really)',
[
'需要 (needs)',
'勇气 (courage)'
]
]
]
Thoughts and digressions
Let's finish up by thinking through a few questions together.
Is there still research value in RNNs?
Some readers might be puzzled: it's already 2019, and people are still studying RNN-based models? Is there still any point? In recent years, Attention-based and language-model pretrained models like BERT and GPT have improved performance on many NLP tasks, and some articles have even flatly declared that "RNNs are dead." Is that really true? I think RNNs are alive and well, and won't be dying anytime soon, for at least the following reasons:
First, models like BERT achieve gains of maybe one or two percentage points on some tasks at the cost of orders of magnitude more compute — that kind of cost-benefit ratio is only worthwhile for academic research or leaderboard chasing, and is almost useless in engineering practice (at least, not directly usable). Second, RNN-based models have some unique advantages of their own — for instance, they can easily simulate a counting function, and in many sequence analysis scenarios RNNs perform extremely well. Third, in almost every seq2seq model (even within BERT-based setups), the decoder is essentially some form of RNN, since decoding is fundamentally recursive. How could RNNs possibly disappear?
Is a unidirectional ON-LSTM enough?
Readers might also wonder: since you want to extract hierarchical structure, but you only used a unidirectional ON-LSTM, doesn't that mean the current-level analysis doesn't depend on future inputs at all — which seems at odds with reality? I share this puzzlement myself, but the authors' experiments show that this already works well enough. It may be that the overall structure of natural language tends to be local and unidirectional (left-to-right), so for natural language, unidirectionality suffices.
Would bidirectionality generally be better? If so, would it need to be trained with a masked-language-model approach like BERT? And how would the level sequence even be computed in a bidirectional setting? None of these questions have complete answers yet. As for whether the structure extracted unsupervised necessarily matches the hierarchical structure understood by humans — that's also uncertain, since without much supervisory guidance, the neural network ends up "understanding things in its own way." Fortunately, it seems the network's "own way" overlaps quite a bit with the way humans understand things.
Why does extracting the hierarchy rely on $d_f$ rather than $d_i$?
Readers might wonder: there are clearly two master gates, so why is $d_f$ used to extract the hierarchy rather than $d_i$? To answer this, we need to understand what $d_f$ means. We said that $d_f$ represents the level of historical information — in other words, it tells us how much historical information is still needed to make the current decision. If $d_f$ is large, it means the current decision barely relies on historical information at all, implying that a new level begins right here, almost severing the connection to past inputs. It's precisely from this kind of severance and connection that the hierarchical structure is extracted, so only $d_f$ can serve this purpose.
Can this be applied to CNNs or Attention?
Finally, one might wonder: could this design be applied to CNNs or Attention as well? In other words, could we impose an ordering on the neurons of CNNs or Attention, and incorporate hierarchical structure information there too? My personal sense is that it's possible, but it would require a redesign, since the hierarchical structure is assumed to be continuously nested, and the recursive nature of RNNs happens to be well-suited to describing this continuity — whereas the non-recursive nature of CNNs and Attention makes it hard to directly express this kind of continuous nesting.
In any case, I think this is a topic worth pondering, and I'll share further thoughts as they come to me. Of course, readers are also welcome to share their own thinking with me.
Summary
This post traces the origins and development of ON-LSTM, a new variant of LSTM, focusing mainly on the design principles behind its representation of hierarchical structure. Personally, I feel the overall design is quite clever and interesting, and well worth pondering carefully.
Finally, the key to learning and research is developing your own capacity for judgment — don't just follow the crowd, and definitely don't blindly trust clickbait headlines from the media. BERT's Transformer certainly has its strengths, but the charm of RNN models like LSTM should not be underestimated either. I even suspect that RNN models such as LSTM will, at some point in the future, shine even more brilliantly, making the Transformer look rather pale by comparison.
Let's wait and see.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.