Sentence Similarity Model Based on GRU and AM-Softmax
Anyone working in computer vision will know that AM-Softmax originated in face recognition. This post draws on face recognition practice to build a sentence similarity model, and along the way introduces how to implement various margin losses in Keras.
Background
On closer thought, you'll find that sentence similarity and face recognition have a great deal in common.
Existing approaches
As far as I've found, deep-learning approaches to sentence similarity fall into just two camps. The first takes a pair of sentences as input and outputs a 0/1 label indicating how similar they are — in other words, treating it as a binary classification problem, as in the model in Learning Text Similarity with Siamese Recurrent Networks:
 Treating sentence similarity as a binary classification model
This includes this year's PPDai "Magic Mirror Cup" competition, which follows the same format. The other approach takes a triplet as input — "(sentence A, a sentence similar to A, a sentence dissimilar to A)" — and uses a triplet loss, as in Applying Deep Learning To Answer Selection: A Study And An Open Task.
These two approaches can really be seen as one and the same, essentially — they only differ in the loss and training method. But both suffer from a serious problem: severely inadequate negative sampling, which makes improvements very slow to materialize. more
Use case
Let's revisit the scenario in which a sentence similarity model gets used. Typically, we've already stored a large number of FAQ pairs, i.e., "question–answer" corpus pairs. When a new question comes in, we need to compare it against every question already in the database, find the most similar one, and then decide — based on the similarity score and a threshold — whether to give an answer at all.
Notice that this involves two elements. First, "every" — in principle we compare the new question against all questions in the database and pick the most similar one. Second, "threshold" — we don't actually know whether the new question even has an answer in the database, so the threshold determines whether we respond at all. If we blindly always take the top-1 match as the answer regardless of anything, the user experience will suffer badly.
We're mainly concerned with "every" (in fact, once "every" is solved, "threshold" is essentially solved too). "Every" means that during training, for each sentence, aside from the handful of genuinely similar sentences that serve as positives, every other sentence should serve as a negative. But with the approaches above, it's very hard to fully sample all the negatives, and even if we could, training would take forever. This is exactly the drawback mentioned earlier.
Help from faces
I've always felt that, in machine learning, one shouldn't draw overly strict boundaries between subfields — some readers who consider themselves NLP people avoid anything to do with vision, and vice versa. In reality, the gulf between different areas of machine learning isn't nearly as wide as people think; the underlying essence of many things is the same, only the application scenario differs. For instance, the so-called sentence similarity model corresponds almost exactly to the face recognition task, and face recognition is by now a fairly mature field — clearly something we can borrow from.
Setting the model aside for a moment, let's picture the use case for face recognition. Say a company uses face recognition for clock-in. Once you have a face recognition model, you'd first store photos of the company's employees, and then every morning, take a live photo of an employee (obviously it won't exactly match any stored photo), and determine whether this is indeed an employee, and if so, which one.
Now imagine swapping "face" for "sentence" in the scenario above — doesn't that describe exactly the use case for a sentence similarity model?
Clearly, a sentence similarity model can be thought of as "face recognition for NLP."
The model
Sentence similarity and face recognition are alike in nearly every respect: from how the model gets used, to how it's built, down to the scale of the datasets — they're strikingly close. So almost every model and trick from face recognition can be applied to sentence similarity.
Formulating it as classification
In fact, the triplet loss mentioned earlier is also one of the standard ways to train face recognition models. There's nothing wrong with triplet loss per se — if you tune it carefully and retrain, it can actually work quite well. It's just that in many cases it's simply too inefficient. Nowadays, the more standard approach is to treat it as a multi-class classification problem.
For example, suppose the training set contains 100,000 different people, five face images each, giving 500,000 training images in total. We then train a CNN to extract features from the images and build a 100,000-way classification model. Yes — it's the same kind of classification problem as MNIST, just with a vastly larger number of classes: one class per distinct person. Sentence similarity can be tackled the same way — split the training set into groups of "paraphrases," and treat each group as a class, again turning sentence similarity into a classification problem.
Note, though, that this is purely for training — the resulting classification model itself may be completely useless in the end. This isn't hard to picture: we might train a face recognition model on some public face database, but our actual use case might be company clock-in, i.e., we need to recognize faces of the company's own employees, who obviously won't appear in any public face database. So the classification model itself is meaningless; what's truly useful is the feature extractor that comes before the classification layer. For example, a typical CNN classifier can be written schematically as two steps:
$$\begin{aligned}\boldsymbol{z} = CNN(\boldsymbol{x})\\ \boldsymbol{p}=\text{softmax}\big(\boldsymbol{z}\boldsymbol{W}\big)\end{aligned}\tag{1}$$
Here $\boldsymbol{x}$ is the input and $\boldsymbol{p}$ is the per-class probability output, where the softmax here needs no bias term. When training as a classification problem, we feed in face images $\boldsymbol{x}$ together with the corresponding one-hot labels $\boldsymbol{p}$, but at inference time we don't use the whole model — we only use the $CNN(\boldsymbol{x})$ part, which is responsible for turning each face image into a fixed-length vector.
Once we have this transformation model (the encoder), we can encode any new face regardless of the scenario, and then reduce the task to comparing these encoded vectors — no longer depending on the original classification model. So the classification model is really just a training scheme: once training is done, it has served its purpose, leaving behind the encoder.
Classification vs. ranking
So is that it? Not quite. As mentioned, what we actually want is a feature extractor (an encoder), trained via a classification scheme, while the model is ultimately used by comparing and ranking the extracted features.
We want to do feature ranking, but we're training via a classification model — are the two equivalent?
The answer is: related, but not equivalent. How does classification actually work? Intuitively, it picks a set of class centers, and then says:
Each sample belongs to whichever center is closest to it.
Of course these class centers are themselves learned, and "distance" here could be any of several things — Euclidean distance, cosine similarity, or inner product; ordinary softmax corresponds to the inner product. This way of doing classification can lead to a classification outcome like the following:
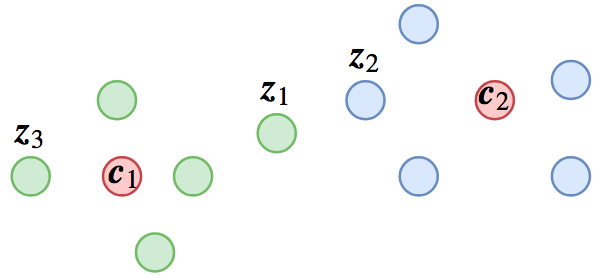 One possible classification outcome, where red dots denote class centers and other dots denote samples
What's wrong with this outcome? Look at the three samples $\boldsymbol{z}_1,\boldsymbol{z}_2,\boldsymbol{z}_3$ in the figure: $\boldsymbol{z}_1,\boldsymbol{z}_3$ is closest to $\boldsymbol{c}_1$, so it's assigned to class 1; $\boldsymbol{z}_2$ is closest to $\boldsymbol{c}_2$, so it's assigned to class 2. Suppose this classification is correct — meaning $\boldsymbol{z}_1,\boldsymbol{z}_3$ really are paraphrases of each other, $\boldsymbol{z}_2$ is not a paraphrase of them, or in the face-recognition analogy, $\boldsymbol{z}_1,\boldsymbol{z}_3$ are images of the same person's face while $\boldsymbol{z}_2$ is someone else's.
From a classification standpoint, this result is perfectly reasonable. But as noted, we're not ultimately after a classification model — we need feature comparisons to be meaningful. And here's exactly where the problem shows up: $\boldsymbol{z}_1,\boldsymbol{z}_2$ are so close together yet belong to different classes, while $\boldsymbol{z}_1$ and $\boldsymbol{z}_3$ are far apart yet belong to the same class. If we used feature-based ranking to find a paraphrase for $\boldsymbol{z}_1$, we'd end up retrieving $\boldsymbol{z}_2$ instead of $\boldsymbol{z}_3$ — a clear mistake.
Losses
What we just described is the non-equivalence between classification and ranking: classification gets it "right," yet ranking based on the resulting features can still go wrong. Of course, as the figure shows, even though the two aren't fully equivalent, a classification model still arranges most features into a reasonable layout — problems only crop up for features near the boundaries.
Margin softmax
It's easy to imagine that the trouble arises precisely at points near the classification boundary, and the root cause is that the classification criterion is too lax. If we tighten that criterion, ranking quality should improve. For instance, we could change the rule to:
The distance from each sample to the center of its own class must be less than half its distance to any other class's center.
Previously we only required the distance to be smaller than the distance to other classes; now we additionally require it to be smaller than half that distance — clearly a stronger condition. Under this stronger rule, the classification result shown in the earlier figure is no longer good enough: although it satisfies $\Vert \boldsymbol{z}_1 - \boldsymbol{c}_1\Vert < \Vert \boldsymbol{z}_1 - \boldsymbol{c}_2\Vert$, it fails to satisfy $\Vert \boldsymbol{z}_1 - \boldsymbol{c}_1\Vert < \frac{1}{2}\Vert \boldsymbol{z}_1 - \boldsymbol{c}_2\Vert$, so the loss needs further refinement.
If training converges under this stricter condition, we can expect that the distance $\boldsymbol{z}_1,\boldsymbol{z}_2$ gets pulled further apart while the distance $\boldsymbol{z}_1,\boldsymbol{z}_3$ gets pulled closer — exactly the outcome we want: larger inter-class distance, smaller intra-class distance.
In fact, the scheme just described is essentially the well-known face-recognition method l-softmax. Many similar losses have been proposed in face recognition, all designed to address this non-equivalence between classification and ranking — for example a-softmax, AM-Softmax, and aAM-Softmax, collectively known as margin softmax. And beyond margin softmax, there's also center loss and various improved versions of triplet loss, among others.
AM-Softmax
I don't work in vision, so I can't go much further into that story — let's get back to the main topic. As mentioned, face recognition can't rely on plain softmax classification; it needs margin softmax. And because sentence similarity models are so analogous to face recognition models, this tells us sentence similarity models need margin softmax too. In short, we should pick some margin softmax variant to implement.
Among the options, the one that works well while being easiest to implement is arguably AM-Softmax, so this post uses it as the example for implementing this family of margin softmax losses, ultimately building a full sentence similarity model.
The idea behind AM-Softmax is actually quite simple. In ordinary softmax we have $\boldsymbol{p}=\text{softmax}\big(\boldsymbol{z}\boldsymbol{W}\big)$. Define
$$\boldsymbol{W} = (\boldsymbol{c}_1,\boldsymbol{c}_2,\dots,\boldsymbol{c}_n)\tag{2}$$
Then softmax can be rewritten as
$$\boldsymbol{p}=\text{softmax}\big(\langle\boldsymbol{z},\boldsymbol{c}_1\rangle, \langle\boldsymbol{z},\boldsymbol{c}_2\rangle, \dots, \langle\boldsymbol{z},\boldsymbol{c}_n\rangle\big)\tag{3}$$
Taking the loss to be cross-entropy gives
$$-\log p_t = - \log \frac{e^{\langle\boldsymbol{z},\boldsymbol{c}_t\rangle}}{\sum\limits_{i=1}^n e^{\langle\boldsymbol{z},\boldsymbol{c}_i\rangle}}\tag{4}$$
where $t$ is the target label. AM-Softmax makes two changes:
1. It L2-normalizes both $\boldsymbol{z}$ and $\boldsymbol{c}_i$, so the inner product becomes a cosine similarity;
2. It subtracts a positive constant $m$ from the target cosine value, then rescales by $s$.
The loss then becomes
$$-\log p_t = - \log \frac{e^{s\cdot(\cos\theta_t -m)}}{e^{s\cdot (\cos\theta_t -m)}+\sum\limits_{i\neq t} e^{s\cdot\cos\theta_i }}\tag{5}$$
where $\theta_i$ denotes the angle between $\boldsymbol{z},\boldsymbol{c}_i$. The original AM-Softmax paper uses $s=30,m=0.35$.
From AM-Softmax we can already see the answer to the problem raised earlier. First, $s$ is necessary because cosine values lie in the range $[-1, 1]$, and proper rescaling is needed to let $p_t$ get sufficiently close to 1 (whenever necessary). Of course, $s$ doesn't change relative magnitudes, so it isn't the core change — the core change is that what used to be $\cos\theta_t $ is replaced by $\cos\theta_t -m$.
Margins to your heart's content
As noted earlier, the non-equivalence between classification and feature ranking can be fixed by tightening the classification criterion. "Tightening," in concrete terms, simply means replacing $\cos\theta_t $ with some new function $\psi(\theta_t) $, such that
$$\psi(\theta_t) < \cos\theta_t\tag{6}$$
Any choice satisfying this can be regarded as a valid "tightening," and AM-Softmax takes $\psi(\theta_t) =\cos\theta_t -m$ — arguably the simplest, crudest choice that satisfies the inequality above (and fortunately, it also works well in practice).
Once you grasp this idea, you can construct all sorts of $\psi(\theta_t)$ functions — in principle, anything satisfying $(6)$ is fair game. As mentioned, l-softmax and a-softmax effectively choose $\psi(\theta_t)=\cos m\theta_t$, where $m$ is an integer. But we know that $\cos m\theta_t < \cos \theta_t$ doesn't always hold, so the original papers had to construct a piecewise function based on $\cos m\theta_t$, which is quite cumbersome and also makes the model extremely hard to train to convergence. In fact, I've experimented with the following alternative:
$$\psi(\theta_t) = \min(\cos m\theta_t, \cos\theta_t)\tag{7}$$
and got results comparable to AM-Softmax (on the sentence similarity task). So this can serve as a simple substitute for l-softmax/a-softmax — I call it "simpler-a-softmax." Readers interested in face recognition are welcome to try it there too.
Implementation
Finally, let's look at how to implement these losses in Keras. The test environment uses Python 2.7, Keras 2.1.5, with the TensorFlow backend.
Basic implementation
Implementing AM-Softmax in the most straightforward way isn't difficult, for example:
from keras.models import Model
from keras.layers import *
import keras.backend as K
from keras.constraints import unit_norm

x_in = Input(shape=(maxlen,))
x_embedded = Embedding(len(chars)+2,
                       word_size)(x_in)
x = CuDNNGRU(word_size)(x_embedded)
x = Lambda(lambda x: K.l2_normalize(x, 1))(x)

pred = Dense(num_train,
             use_bias=False,
             kernel_constraint=unit_norm())(x)

encoder = Model(x_in, x) # 最终的目的是要得到一个编码器
model = Model(x_in, pred) # 用分类问题做训练

def amsoftmax_loss(y_true, y_pred, scale=30, margin=0.35):
    y_pred = y_true * (y_pred - margin) + (1 - y_true) * y_pred
    y_pred *= scale
    return K.categorical_crossentropy(y_true, y_pred, from_logits=True)

model.compile(loss=amsoftmax_loss,
              optimizer='adam',
              metrics=['accuracy'])
Sparse implementation
The code above isn't hard to follow — it relies on y_true being a one-hot target, so we can extract the target cosine value via ordinary multiplication, subtract the margin, and then add back the rest.
If all we're doing is playing with something like 10-class MNIST, the code above is plenty. But in face recognition or sentence similarity settings, we're really dealing with tens of thousands, even hundreds of thousands, of classes. Using one-hot inputs in that regime is extremely memory-hungry (and also more of a headache when preparing the data). Ideally, we'd like y_true to just be the integer id of the target class. For ordinary cross-entropy, Keras already offers sparse_categorical_crossentropy for exactly this need — so can we write a sparse version of AM-Softmax too?
One relatively simple approach is to fold the one-hot conversion into the loss itself, for example:
def sparse_amsoftmax_loss(y_true, y_pred, scale=30, margin=0.35):
    y_true = K.cast(y_true[:, 0], 'int32') # 保证y_true的shape=(None,), dtype=int32
    y_true = K.one_hot(y_true, K.int_shape(y_pred)[-1]) # 转换为one hot
    y_pred = y_true * (y_pred - margin) + (1 - y_true) * y_pred
    y_pred *= scale
    return K.categorical_crossentropy(y_true, y_pred, from_logits=True)
This does achieve the goal, but it merely shifts the cost elsewhere rather than truly avoiding the one-hot conversion. We can use TensorFlow's gather_nd function to genuinely skip the one-hot step — here's some reference code:
def sparse_amsoftmax_loss(y_true, y_pred, scale=30, margin=0.35):
    y_true = K.expand_dims(y_true[:, 0], 1) # 保证y_true的shape=(None, 1)
    y_true = K.cast(y_true, 'int32') # 保证y_true的dtype=int32
    batch_idxs = K.arange(0, K.shape(y_true)[0])
    batch_idxs = K.expand_dims(batch_idxs, 1)
    idxs = K.concatenate([batch_idxs, y_true], 1)
    y_true_pred = K.tf.gather_nd(y_pred, idxs) # 目标特征,用tf.gather_nd提取出来
    y_true_pred = K.expand_dims(y_true_pred, 1)
    y_true_pred_margin = y_true_pred - margin # 减去margin
    _Z = K.concatenate([y_pred, y_true_pred_margin], 1) # 为计算配分函数
    _Z = _Z * scale # 缩放结果,主要因为pred是cos值,范围[-1, 1]
    logZ = K.logsumexp(_Z, 1, keepdims=True) # 用logsumexp,保证梯度不消失
    logZ = logZ + K.log(1 - K.exp(scale * y_true_pred - logZ)) # 从Z中减去exp(scale * y_true_pred)
    return - y_true_pred_margin * scale + logZ
This code runs a bit faster than the previous one-hot version. The key trick is using tf.gather_nd to pull out the target column, then computing the log partition function via logsumexp — presumably the standard way to implement cross-entropy. Building on this, you can adapt it into other forms of margin softmax loss. Now you can pass in just class ids, just like sparse_categorical_crossentropy — and the same idea can be ported to other frameworks.
A preview of results
A complete sentence similarity model can be found here:
https://github.com/bojone/margin-softmax/blob/master/sent_sim.py
This is a character-based model using a GRU as the encoder. The corpus file tongyiju.csv looks like this (the corpus itself isn't shared — readers who want to run it should prepare their own data in this format):
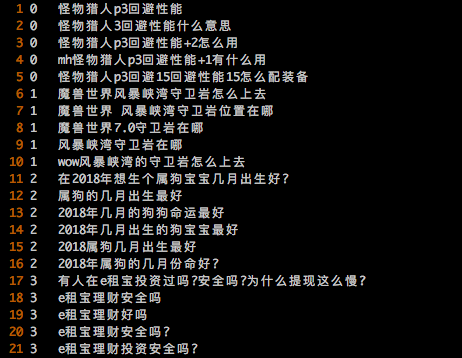 Sentence similarity corpus format
The leading id denotes the sentence group, separated by a tab; sentences in the same group can be treated as paraphrases of one another, while sentences in different groups are non-paraphrases.
Training results: on the training-set classification task, accuracy reaches 90%+, while on the validation set (via the evaluate function), the top-1, top-5, and top-10 accuracies for the various losses are (without careful hyperparameter tuning):
$$\begin{array}{c|c|c|c} \hline & \text{top1 acc} & \text{top5 acc} & \text{top10 acc}\\ \hline \text{softmax} & 0.9077 & 0.9565 & 0.9673\\ \text{AM-Softmax} & 0.9172 & 0.9607 & 0.9709\\ \text{simpler-asoftmax} & 0.9135 & 0.9587 & 0.9697 \\ \hline \end{array}$$
It's worth emphasizing that the evaluate function tests things exactly the way they'd be used in practice: none of the sentences in the validation set have appeared in the training set, and when running evaluate, ranking is done purely within the validation set itself. If, after ranking by similarity, a paraphrase of the input sentence appears among the top $n$ results, the top-n hit count is incremented by one.
Given that, the accuracy is quite respectable and good enough for practical use. Here are a few randomly picked matching examples:
$$\begin{array}{c|c} \hline \text{source sentence} & \text{number of stations in Guangzhou}\\ \hline \text{similarity ranking} & \begin{array}{c|c}\text{similar sentence} & \text{similarity}\\ \hline \text{how many stations in Guangzhou?} & 0.8281\\ \text{how many bus stations in Guangzhou} & 0.7980 \\ \text{how many stations in Tianhe, Guangzhou} & 0.6781\\ \text{how many bus stations in Tianhe, Guangzhou?} & 0.6527\\ \end{array}\\ \hline \end{array}$$
$$\begin{array}{c|c} \hline \text{source sentence} & \text{typical sofa height}\\ \hline \text{similarity ranking} & \begin{array}{c|c}\text{similar sentence} & \text{similarity}\\ \hline \text{typical sofa height} & 0.8658\\ \text{how tall is a living room sofa} & 0.7458 \\ \text{what is the usual height of a sofa} & 0.7173\\ \text{typical sofa height dimension} & 0.6872\\ \end{array}\\ \hline \end{array}$$
$$\begin{array}{c|c} \hline \text{source sentence} & \text{can ps format be converted to ai format}\\ \hline \text{similarity ranking} & \begin{array}{c|c}\text{similar sentence} & \text{similarity}\\ \hline \text{how to convert ps format image to ai format image?} & 0.9351\\ \text{what format to convert photoshop file to open in ai} & 0.6825 \\ \text{ps file can be changed to ai format file} & 0.6531\\ \text{video format conversion mode} & 0.5880\\ \end{array}\\ \hline \end{array}$$
Conclusion
This post lays out my own take on sentence similarity models: I believe the best approach is neither binary classification nor triplet loss, but rather mimicking the margin losses used in face recognition — this is the scheme that improves results the fastest. That said, I haven't done a thorough comparison of all the methods; this conclusion just comes from my own shallow understanding of face recognition, which suggests it should work this way. Readers are welcome to test it out and join the discussion.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.