SVD Decomposition (I): Autoencoders and Artificial Intelligence
At first glance, SVD decomposition looks like a fairly traditional data-mining technique, while the autoencoder is a relatively "advanced" concept from deep learning — the two shouldn't have much in common. Yet this post will argue that, if we ignore activation functions, the two are actually equivalent. Pushing the thought further, we can see that whether it's SVD or an autoencoder, our purpose in reducing dimensionality is not merely to save storage or computation — it is an early manifestation of "intelligence".
Equivalence
Suppose we have a huge matrix $M_{m\times n}$ with $m$ rows and $n$ columns, which may pose problems for both computation and storage. So we consider a decomposition, hoping to find matrices $A_{m\times k}$ and $B_{k\times n}$ such that
$$M_{m\times n}=A_{m\times k}\times B_{k\times n}$$
where the multiplication here is matrix multiplication. As shown below:
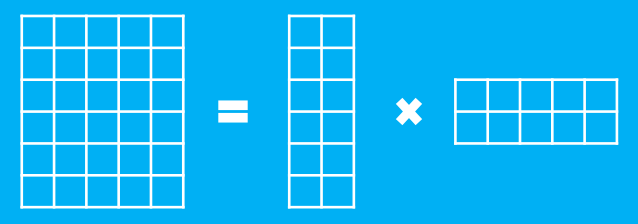 SVDmore
Originally there were $mn$ elements, but now on the right-hand side we have $(m+n)k$ elements. If $k$ is small enough, then $(m+n)k < mn$ holds, and both storage and computation are reduced. Of course, if $k$ is small enough, the equality generally does not hold exactly — it holds only in the sense of minimizing some error — but we won't dwell on that distinction here. This is (the core of) the SVD decomposition described in this post. If the matrix $M_{m\times n}$ is originally sparse (say, a one-hot document matrix or a user rating matrix), then it's usually possible to make $k$ several orders of magnitude smaller while keeping accuracy essentially unchanged. One use of SVD is for building topic models, recommendation systems, and so on. (Note: SVD may be defined differently in some contexts, but at least its basic purpose is as described here.)
So what about autoencoders? Let's ignore activation functions for now and look only at the linear structure. An autoencoder aims to train an identity function $f(x)=x$, but with the middle layer compressed.
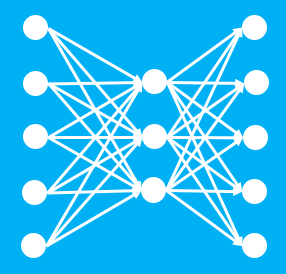 The network structure of an autoencoder
Written mathematically, we want to find matrices $C_{n\times k}$ and $D_{k\times n}$ such that
$$M_{m\times n}=M_{m\times n} \times C_{n\times k}\times D_{k\times n}$$
Here too the equality isn't strict, but holds in the sense of some optimum, as illustrated below:
 Autoencoder
If we then let
$$A_{m\times k} = M_{m\times n} \times C_{n\times k},\quad B_{k\times n} = D_{k\times n}$$
aren't the two exactly equivalent? As long as they are optimized under the same error function (loss function), the results obtained must be equivalent.
In this way we've shown that a three-layer autoencoder without an activation function is in fact equivalent to the traditional SVD decomposition. But even though they're equivalent, the autoencoder is still an innovation, because it reframes matrix decomposition as a neural-network compression-coding problem, which is more intuitive and easier to understand. It also lets us train in batches, rather than having to feed all the data into the decomposition at once as with SVD. (Of course, one could imagine mimicking mini-batch neural-network training to design a "batch SVD decomposition" algorithm, but that wouldn't really serve any purpose.)
Compression and Intelligence
Although the autoencoder is more intuitive for compression and encoding, the physical meaning of SVD decomposition is clearer. This shows that looking at the same thing from different angles can be very illuminating. We can observe the physical meaning of SVD as follows. Consider a document encoding, as shown below, where each column represents a word and each row represents a document. In the figure below, there are five words — A, B, C, D, E — and six documents.
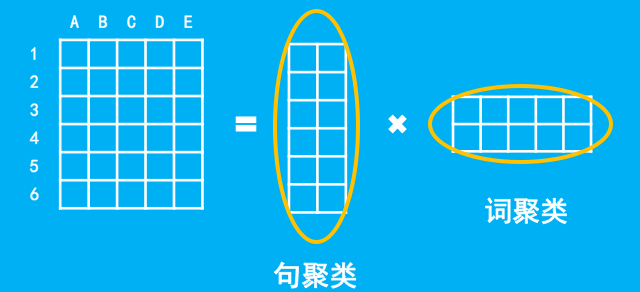 Physical meaning of SVD
As shown, we can interpret the physical meaning of SVD like this: the first decomposed matrix can be seen as clustering the rows, i.e., a simple clustering of the documents; the second decomposed matrix can be seen as clustering the columns, i.e., clustering of the words. And the matrix multiplication represents the matching between document clusters and word clusters. Readers might ask: why should words and documents be clustered into the same number of clusters, rather than different numbers? In fact, a more sensible way to write it is
$$M_{m\times n}=A_{m\times k}\times P_{k\times l} \times Q_{l\times n}$$
This amounts to clustering the documents into $k$ clusters and the words into $l$ clusters, where $P_{k\times l}$ is the matching matrix between document clusters and word clusters, and then setting $P_{k\times l} \times Q_{l\times n}$ to $B_{k\times n}$.
Why bother constructing such a seemingly forced explanation? My purpose is to explain where the "intelligence" exhibited by artificial models actually comes from. We know that humans have a memory function, but once memory reaches a certain point, it's usually not satisfied with mere memorization — instead, we tend to discover the underlying regularities of what we're memorizing, and memorize via those regularities. For example, in language, we classify words into verbs and nouns, and so on, and then we discover patterns such as "verb + noun" often forming a phrase. We may not be able to articulate this pattern explicitly, but it's undeniable that our brains really are carrying out this process of "finding patterns" and "classification." From a data-mining perspective, I think this is a process of compression and clustering: that is, by compressing and then reconstructing, we can mine the commonalities in the data — what we call regularities — and thereby obtain more generalizable results.
This may help answer certain questions — for instance, why deep-learning-based word segmentation models (whether LSTM or CNN based) are so good at recognizing new words. It's because they contain an autoencoder-like structure, and this structure is equivalent to SVD. As explained above, SVD carries the physical meaning of clustering (i.e., finding regularities), which makes it more generalizable and gives it better performance.
Deriving New Words
Too abstract? Not making sense yet? No worries — here's an example right away. This example concerns how we understand words. Take a look at the table below:
$$\begin{array}{c|c|c|c|c|c} \hline & \text{beast} & \text{boundary} & \text{dragon} & \text{spirit} & \text{technique} \\ \hline \text{god} & 1 & 1 & 1 & 1 & 0 \\ \hline \text{magic} & 1 & 1 & 1 & 1 & 1 \\ \hline \end{array}$$
Suppose this is a result compiled from science fiction novels, where words such as "divine beast," "divine realm," "divine dragon," "divine spirit," "demon beast," "demon realm," "demon dragon," "demon spirit," and "demon art" all appear in the novels, each with a frequency of 1 — but "divine art" never appears. Would we then infer that "demon" and "divine" seem to behave similarly in usage, and that "divine art" might be a plausible word too? How do we express this mathematically?
Surprisingly, one way to do this is precisely SVD! That is, we should cluster the usage patterns of the first character (perhaps adjective, verb, noun?), cluster the usage patterns of the second character similarly, and then consider the pairing between clusters. Of course, we don't actually need to tell the computer to cluster into nouns or verbs — the computer doesn't need to understand language the way humans do. We only need to tell it to cluster, and since SVD inherently carries this notion of clustering, simply performing SVD suffices. Here's the concrete experiment:
Take all two-character words in the Jieba segmentation dictionary with frequency at least 100, use the first character as the row index and the second character as the column index, and use the frequency as the value (defaulting to 0 if the word doesn't exist), yielding a matrix. Perform SVD decomposition on this matrix, obtain two matrices, multiply them back together (reconstruction), treat the reconstructed matrix as new frequencies, and compare against the original matrix to see which words gained noticeably higher frequencies.
The result was that I obtained some words that weren't in the original vocabulary at all, such as (just a small sample below):
龙脑 (dragon-brain) 10.271244
龙脚 (dragon-foot) 12.496673
龙腊 (dragon-preserved-meat) 16.860170
龙腿 (dragon-leg) 12.172765
龙莲 (dragon-lotus) 11.362767
龙蔗 (dragon-sugarcane) 67.800909
龙薯 (dragon-potato) 30.580730
七讲 (seven-lecture) 11.439969
七评 (seven-review) 12.362163
七课 (seven-lesson) 11.587767
七郎 (seven-lad) 12.789438
七隐 (seven-hidden) 10.479609
七页 (seven-page) 15.499356
七项 (seven-item) 18.802959
怨怒 (resentful-anger) 29.831461
怨恶 (resentful-evil) 15.875075
怨苦 (resentful-bitter) 24.979326
怪兔 (strange-rabbit) 10.246062
怪奇 (strange-odd) 12.768122
怪孩 (strange-child) 14.391967
怪形 (strange-shape) 14.856068
Among these words, quite a few don't really make sense — in fact, the nonsensical ones far outnumber the plausible ones. But that doesn't really matter, because when processing natural language, the nonsensical ones simply don't occur in real sentences. This gives us a rather remarkable result: through SVD decomposition, our original goal might have been compression or dimensionality reduction, but after reconstruction we ended up deriving a richer vocabulary instead. This seems to be a consequence of clustering and pattern-finding. This differs from statistics-based new-word discovery: these new words don't actually exist in the corpus — they are derived from the compositional regularities of existing words. It's a genuine process of inference, i.e., "intelligence." To put it dramatically, SVD gives us a rudimentary form of artificial intelligence (though of course, it's not the only way to achieve this).
Activation Functions
What on earth are activation functions for? In the experiment above, I stumbled upon a very concrete physical interpretation of activation functions. When we perform SVD decomposition on the matrix and then reconstruct it, some of the resulting elements turn out negative. But since our matrix represents frequencies, and frequencies can't be negative, we discard the negative values (truncating them to 0).
Wait — isn't that exactly the operation of the function $\max(x,0)$? Isn't that the widely-used ReLU activation function? It turns out that the physical meaning of the activation function here is nothing more than discarding (truncating) unimportant elements — an operation that has long been used in classical statistics (discarding negative values, discarding small statistical counts, etc.).
Of course, in neural networks, activation functions carry deeper significance, but in shallow networks (matrix decomposition), the intuitive sense they give us is simply truncation.
Summary
This post has centered on SVD, exploring its physical meaning (clustering), its connection to autoencoders, its intricate relationship with intelligence, and a related experiment. Most of this content is conceptual and intended to deepen our understanding — of models and of artificial intelligence — giving us more confidence when applying these models, rather than merely plugging data into off-the-shelf models.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.