A Brief Exploration of OCR Techniques: 5. Text Segmentation
After the previous step, once we have obtained single-line text regions, we can start thinking about how to segment a single line of text into individual characters. Since the model in step three was built for individual characters, this step is also necessary.
Uniform Segmentation
Based on the assumption that Chinese characters are square-shaped, the simplest segmentation method is in fact uniform segmentation, meaning that we don't make any judgment at all, and simply cut the single-line text into individual square images according to its height. This approach can handle most single-line text, as shown in the image above.
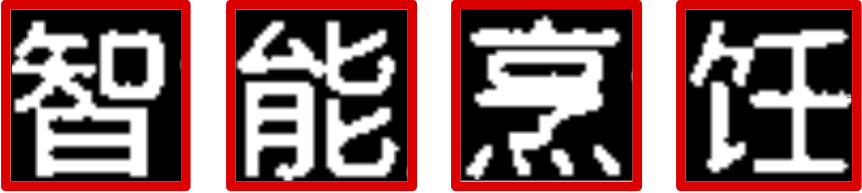 Uniform segmentation successful
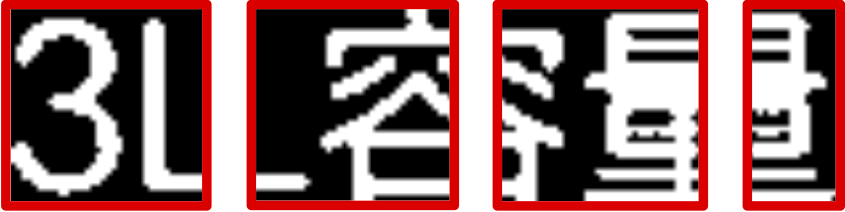 Uniform segmentation failure
Of course, the drawbacks of uniform segmentation are also quite obvious. Most Chinese characters are square-shaped, but most English letters and digits are not, so when Chinese and English text are mixed together, uniform segmentation fails, as shown in the image below. more
Statistical Segmentation
From Figure 15 we can see that, after the preceding operations, the characters have been well separated from one another. So another relatively simple idea is to sum the single-line text image along the vertical direction; the columns where the sum equals zero are exactly the columns where the cut should be made.
This statistical approach can nicely solve the problem of segmenting single lines of mixed Chinese-English text, but it also has certain drawbacks. The most obvious one is that characters such as "小" (small) or "的" (a common function word) end up being cut into two parts.
Before-and-After Comparison
A better approach is to combine the results of the two previous methods, deciding whether to make a cut by comparing whether the regions before and after form a square. The specific steps are:
1. Use the statistical summation approach to obtain candidate cut lines;
2. If the sum of the distances from a candidate cut line to the candidate cut lines on its left and right exceeds 1.2 times the (width or) height, then that candidate cut line is confirmed as an actual cut line;
3. If the resulting region is clearly an elongated rectangle, and it cannot be split according to the two steps above, then it is cut uniformly.
These three steps are fairly simple, and rely on two assumptions: 1) the ratio of width to height for digits and English characters is greater than 60%; 2) the ratio of width to height for Chinese characters is less than 1.2. After testing, this algorithm works well for segmenting the image text features extracted in the earlier steps.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.