A Brief Exploration of OCR Technology: 2. Background and Assumptions
Research Background
Optical Character Recognition (hereafter abbreviated as OCR) refers to converting text in an image into computer-editable text content. Many researchers have long studied related technologies, and quite a few mature OCR technologies and products have emerged, such as Hanwang OCR, ABBYY FineReader, Tesseract OCR, and so on. It's worth noting that ABBYY FineReader not only has a high accuracy rate (including for recognizing Chinese) but can also preserve most of the original layout formatting, making it an extremely powerful commercial OCR software package.
However, among the many finished OCR products, apart from Tesseract OCR, all the others are closed-source, or even commercial software — we can neither embed them into our own programs nor improve upon them. The only open-source option is Google's Tesseract OCR, but its recognition performance isn't particularly good, and its accuracy rate for Chinese recognition is on the low side, leaving considerable room for improvement.
In summary, whether for academic research or practical application, it is necessary to explore and improve OCR technology. Our team divided the complete OCR system into four aspects: "feature extraction," "text localization," "optical recognition," and "language model," tackling them one by one, and ultimately built a usable, complete OCR system for printed text. This system can be used, as an initial step, for recognizing text in images on platforms such as e-commerce sites and WeChat, in order to help judge the authenticity of the information shown in them.
Research Assumptions
In this article, we assume that the text portions of images have the following characteristics: more
1. We assume that the fonts to be recognized in the image are fairly standard printed fonts, such as SimSun, SimHei, Kaiti, running script (行书), and so on;
2. There should be a fairly clear contrast between the text and the background;
3. When designing the model, we assume that the text in the image is laid out horizontally;
4. The strokes of the text should have a certain width, and should not be too thin;
5. The color of any given character should vary at most gradually (i.e., as a gradient);
6. Text is generally formed from relatively dense strokes, and in many cases exhibits a certain degree of connectivity.
As can be seen, these characteristics are all common features of things like e-commerce promotional posters, so these assumptions are all reasonably justified.
Analysis Pipeline
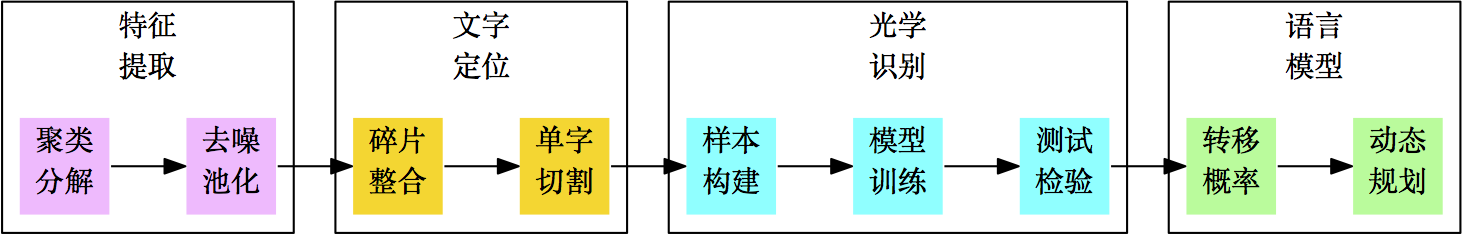 Figure 1: Our experimental workflow diagram
Experimental Platform
The experiments in this article were carried out under CentOS 7 + Python 2.7. For the image processing components, the following extension libraries were used: Numpy, SciPy, Pandas, and Pillow; for the convolutional neural network models, the following extension libraries were used: Keras and Theano. The specific experimental configurations will be discussed further later on.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.