-*- coding:utf-8 -*-
A Simple Thunder VIP Account Grabber (Python)
When working on Windows, I often use Thunder (迅雷) to download things. If the speed is slow or the resource is hard to find — especially for some obscure videos — Thunder's VIP membership service can really save the day. At some point I stumbled across a piece of software called a "Thunder VIP Account Grabber," which fetches temporary VIP accounts for use. This is a pretty nice thing to have, because although subscribing to Thunder membership isn't expensive, I don't download things often enough to justify it, so it always felt like a bit of a waste. With this tool, though, I can grab something for free whenever I need to download.
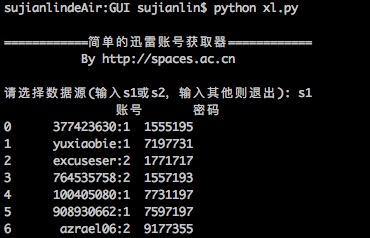 Simple Thunder VIP Account Grabber
Recently I moved over to a Mac, and Thunder is available on Mac too, but that account grabber was an exe file and couldn't run there. I originally assumed the grabber must have some complicated internal workings, but after sniffing the traffic, it turned out the principle behind it is extremely simple. To put it plainly, it's just a basic crawler: the following two websites provide accounts, and the tool simply scrapes accounts from them:
http://yunbo.xinjipin.com/
http://www.fenxs.com
Based on this, I wrote a simple version in Python myself, mainly so I could use it conveniently on my Mac. Readers who need it are welcome to download and use it too — the code is compatible with both Python 2.x and 3.x. The main libraries used are requests and re; pandas and sys are only there to make the output a bit more user-friendly. I originally thought about building a simple GUI with Tkinter, but on second thought, decided it wasn't really necessary~~more
'''
2016.01.21更新:修改了正则表达式的写法,使得更加通用;增加了一个账号来源。
'''
import requests as rq
import re

def get1():
    source = 'http://yunbo.xinjipin.com/articlelist/?33.html'
    web = rq.get(source).text
    url = re.findall('<li><p><a href=\"(.*?)\" title=', web)[0]
    web = rq.get('http://yunbo.xinjipin.com%s'%url)
    web.encoding = 'gb2312'
    web = web.text
    return re.findall(u'迅雷.*?([a-zA-z0-9\:]+?)[密码]+?([a-zA-z0-9]+?)</div>', web)

def get2():
    source = 'http://www.fenxs.com'
    web = rq.get(source).text
    url = re.findall(u'<h2><a href=\"(.*?)\" title=.*?迅雷会员账号分享.*?</a></h2>', web)[0]
    web = rq.get(url).text
    return re.findall(u'迅雷.*?([a-zA-z0-9\:]+?)[密码]+?([a-zA-z0-9]+?)<br />', web)

def get3():
    source = 'http://xlfans.com'
    web = rq.get(source).text
    url = re.findall(u'<h2><a href=\"(.*?)\" title=.*?迅雷会员账号分享.*?</a></h2>', web)[0]
    web = rq.get(url).text
    return re.findall(u'迅雷.*?([a-zA-z0-9\:]+?)[密码]+?([a-zA-z0-9]+?)<br />', web)

if __name__ == '__main__':
    import pandas as pd #方便输出显示
    import sys #判断系统版本

    print u'\n============简单的迅雷账号获取器============\n           By http://kexue.fm\n'
    while True:
        if sys.version_info[0] < 3:
            s = raw_input(u'请选择数据源(输入s1或s2或s3,输入其他则退出): ')
        else:
            s = input(u'请选择数据源(输入s1或s2或s3,输入其他则退出): ')
        if s == 's1':
            print pd.DataFrame(get1(), columns=[u'账号', u'密码'])
        elif s == 's2':
            print pd.DataFrame(get2(), columns=[u'账号', u'密码'])
        elif s == 's3':
            print pd.DataFrame(get3(), columns=[u'账号', u'密码'])
        else:
            break
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.