Project Euler 454: Conquering the "Arena" in Five Days
The semester is coming to an end, and many students are starting their review. I'm still not very familiar with a few of the courses I'm taking this term, and I originally intended to use this time to study them properly. But as luck would have it, five days ago I came across this problem while browsing the programming arena on a mathematics forum:
For a given $L$, the equation
$$\frac{1}{x}+\frac{1}{y}=\frac{1}{n}$$
has $f(L)$ positive integer solutions satisfying $0 < x < y \leq L$. For example $f(6)=1,f(12)=3,f(1000)=1069$. Find $f(10^{12})$.
This problem originates from Project Euler Problem 454: Diophantine reciprocals III. It's short and easy to understand, yet has real depth — exactly the kind of problem I consider ideal. Plus I'd been having a lot of fun learning Python lately, so as soon as I saw this problem I couldn't wait to try it. As a result, my five days vanished, and in the process I exhausted pretty much every programming trick I currently know. Because of the constant testing and running, my computer got much hotter than usual — the poor thing really suffered. The final code, I have to say, is the most exciting piece of code I've ever written. I'm sharing it here for everyone's benefit and mutual encouragement.
The expression above is a fraction, which isn't convenient for programming. Since $n=\frac{xy}{x+y}$, the problem above is equivalent to finding integer solutions of $(x+y)|xy$ (meaning $x+y$ divides $xy$). more
Rambling stage
The most straightforward programming technique here is a double loop. In Python this looks like:
l=1000 #设置上限
s=0 #统计个数
for y in xrange(2,l+1):
 for x in xrange(1,y+1):
 if (x*y)%(x+y)==0:
 s=s+1
print(s)
This is fine for small L, but becomes a serious problem for larger L (it seems even computing $f(10^5)$ already takes quite a while). Notice that we perform $\frac{L(L-1)}{2}$ divisions, meaning the algorithm is at least $\mathcal{O}(L^2)$, which roughly means that if L grows tenfold, the running time becomes 100 times longer! Given that we need to handle $L=10^{12}$, the efficiency of the above algorithm is simply unacceptable.
Optimization
Most of the content in this section comes from user Lwins_G on the mathematics forum.
First, with just one step we can reduce the algorithm to $\mathcal{O}(L)$. It's not hard to prove that a necessary and sufficient condition for $(x+y)|xy$ is that there exists an integer $m,n,k$ satisfying $(m,n)=1$, and
$$x=km(m+n)\quad y=kn(m+n)$$
So we only need to find the solutions of
$$kn(m+n) \leq L,\quad (m,n)=1,\quad m < n$$
Writing out the formula explicitly gives
$$f(L)=\sum_{n=1}^{\sqrt{L}} \sum_{\begin{subarray}{cc} m=1 \\ (n,m)=1 \end{subarray}}^{n-1} \left[ \frac{L}{n(n+m)} \right]$$
This formula is $\mathcal{O}(L)$. Code 1 in the attachment is the algorithm I wrote based on this formula, in Python. The trick to using the formula above is: given $n$, construct a table of integers coprime to $n$, which is similar to constructing a table of primes. If instead we enumerated all $m$ and checked whether $(m,n)$ equals 1, the efficiency would suffer greatly. Running on PyPy, computing $f(10^7)=30093331$ took 1.7 seconds, computing $f(10^8)=349446716$ took 17 seconds, and $f(10^9)=3979600400$ took 190 seconds. This is naturally a big improvement over the double loop, but we're still a long way from being able to compute $f(10^{12})$.
Further optimization
Lwins_G also suggested that the algorithm could be reduced to $\mathcal{O}(L^{3/4})$, as follows:
$$\begin{split} &\sum_{n=1}^{\sqrt{L}} \sum_{\begin{subarray}{cc} m=1 \\ (n,m)=1 \end{subarray}}^{n-1} \left[ \frac{L}{n(n+m)} \right] \\ =&\sum_{n=1}^{\sqrt{L}} \sum_{\begin{subarray}{cc} s=n+1 \\ (n,s)=1 \end{subarray}}^{2n-1} \left[ \frac{L}{ns} \right] \\ =&\sum_{n=1}^{\sqrt{L}} \sum_{s=n+1}^{2n-1} \left[ \frac{L}{ns} \right] \left[ \frac{1}{(n,s)} \right] \\ =&\sum_{n=1}^{\sqrt{L}} \sum_{s=n+1}^{2n-1} \left[ \frac{L}{ns} \right] \sum_{d | (n,s)} \mu(d) \\ =&\sum_{n=1}^{\sqrt{L}} \sum_{d | n} \sum_{\begin{subarray}{cc} n < s \leq 2n-1 \\ d | s \end{subarray}} \left[ \frac{L}{ns} \right] \mu(d) \\ =&\sum_{n=1}^{\sqrt{L}} \sum_{d | n} \mu(d) \sum_{\frac{n}{d} < s' \leq \frac{2n-1}{d}} \left[ \frac{L}{nds'} \right] \\ =&\sum_{n=1}^{\sqrt{L}} \sum_{d | n} \mu(d) \left( \psi\left( \left[ \frac{L}{nd} \right],\frac{2n-1}{d}\right)- \psi\left(\left[ \frac{L}{nd} \right],\frac{n}{d}\right) \right) \end{split}$$
where $\mu(d)$ is the Möbius function, and $ \psi(x,y) = \sum\limits_{n=1}^{y} \left[ \frac{x}{n} \right]$. This derivation is brilliant — it cleverly brings the Möbius function into the problem, (partially) eliminating the constraint $(m,n)=1$. Since computing $\psi(x,y)$ is $\mathcal{O}(\sqrt{x})$, the final formula is naturally $\mathcal{O}(L^{3/4})$.
But at first I couldn't understand why $\psi(x,y)$ is $\mathcal{O}(\sqrt{x})$. So I could only code up the formula before the last equals sign. That's Code 2 in the attachment. The problem involves the Möbius function, and the trick for the Möbius function is again to construct rather than check. It also involves the constraint $d|n$, which requires factorization, but since $n$ only goes up to $\sqrt{L}=10^6$, which isn't very large, we can just do direct trial-division factorization, provided we've prepared a table of primes up to $10^3$ in advance (thanks to the groundwork from my earlier computation of the sum of the first two million primes, this part is very easy and can be done in under half a second). Most entries of the Möbius function are zero, so we only need to find the nonzero terms — that is, all the integers generated by multiplying together the distinct prime factors of $n$ (each appearing only once, even if repeated in the factorization), where each construction uses each prime factor exactly once. These need to be built up via a recursive construction. The advantage of construction is that construction generally uses multiplication, whereas checking requires division, and division is far less efficient than multiplication. Moreover, constructing first and then checking greatly reduces the number of iterations needed.
Code 2's running efficiency improved considerably — computing $f(10^9)$ took only 24 seconds. But strangely, when I used it to compute $f(10^{10})$, it ran for half an hour with no result. So I had to keep optimizing. I realized the main issue was that I didn't know the $\mathcal{O}(\sqrt{x})$ algorithm Lwins_G mentioned for computing $\psi(x,y)$ — what I was using above was just a plain, unoptimized direct computation.
Straight for 10^12
Yesterday I tried optimizing some details in Code 2, but the speed didn't improve noticeably. Today, I continued working on the problem, thinking about the $\mathcal{O}(\sqrt{x})$ algorithm for computing $\psi(x,y)$. Finally, it clicked. Actually, I'd already noticed a pattern a few days earlier: for $\left[\frac{x}{n}\right]$, if $n\leq \sqrt{x}$, then we just have to enumerate and compute directly; but once $n > \sqrt{x}$, the results start appearing in "batches" — that is, as $\left[\frac{x}{n}\right]$ gradually decreases from $\left[\sqrt{x}\right]$ down to 1, we can work backwards: given the value of the quotient, we can determine the range of divisors that produce it. Here's a simple example: $\left[\frac{101}{1}\right]=101,\left[\frac{101}{2}\right]=50$, so we know that as $n$ ranges from 51 to 101, $\left[\frac{101}{n}\right]$ stays at 1 the whole time — meaning we've effectively computed 51 divisions in one shot.
This optimization was a qualitative leap: our computation went from $\mathcal{O}(x)$ to $\mathcal{O}(\sqrt{x})$, so the overall efficiency improved from $\mathcal{O}(L)$ to $\mathcal{O}(L^{3/4})$. Readers might feel that $\mathcal{O}(L)$ and $\mathcal{O}(L^{3/4})$ aren't all that different, but when $L=10^{12}$, the difference is a factor of 1000! That's three orders of magnitude!
I spent most of the afternoon writing $\psi(x,y)$, and didn't even eat dinner (I'd eaten too much at lunch, ha~~). With the improved $\psi(x,y)$ algorithm, computing $f(10^{9})$ became trivially easy, taking less than 3 seconds. But computing $f(10^{10})=44647347052$ took 180 seconds. Still, this was the first time I'd reached $10^{10}$, and I was a bit pleased with myself. At the same time, I found the sudden "explosion" in running time quite strange, and I felt that computing $f(10^{11})$ was hopeless. But then I tried computing $f(2\times 10^{10})$ and $f(3\times 10^{10})$, and the time increase was surprisingly small — especially $f(3\times 10^{10})$, which took only 313 seconds, just a bit more than double $f(10^{10})$'s time. This really surprised me, so I went ahead and directly computed $f(10^{11})=494986959815$. The final result: 782 seconds. There was hope!
This seemed to suggest that the time for $f(10^{10})$ is really the fundamental baseline, on top of which the computation scales with $\mathcal{O}(L^{3/4})$. If that's the case, then computing $f(10^{12})$ might only take around $5000秒$ — about an hour and a half — which would be acceptable.
Still, I decided to improve the algorithm further first, because although $\psi(x,y)$ was fairly efficient, it did some redundant work — after all, what we really need is just the difference between the two ends of $\psi(x,y)$. As with $S_n=a_1+a_2+\dots+a_n$, to compute $S_{n+k}-S_{n}$ we don't necessarily need to compute both $S_{n+k}$ and $S_n$ separately. Tonight I spent most of my time improving $\psi(x,y)$, arriving at the final version of the code in the attachment. Testing it, $f(10^{10})$ took 6 seconds, and $f(10^{11})$ took 23 seconds!! This was way beyond what I expected!! So, straight for $f(10^{12})$.
By then it was already past nine. After entering the code and starting it running, I turned off the screen and went to take a shower, since I was worried something might go wrong — I had no idea whether the time would grow linearly, or whether I'd hit another situation like before, where computing $f(10^{9})$ took less than 3 seconds but computing $f(10^{10})$ took 180 seconds.
When I came back from my shower, I wasn't in a hurry — I calmly hung up my clothes to dry, sat down, and turned the screen back on. The number in front of me left me stunned —
101.629625957 seconds!
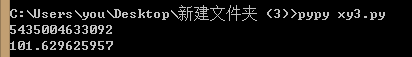 f(10^12)
$f(10^{12})=5435004633092$! This was no ordinary surprise, no ordinary excitement! It worked! I had expected it to take tens of minutes at the very least, and here it was, done in under 2 minutes! This is the fruit of five days of effort — it used up almost every technique I have! The arena challenge has been conquered! (It really does seem like this algorithm achieved $\mathcal{O}(L^{3/4})$ — going from $10^{10}$ to $10^{11}$ to $10^{12}$, the time grows by a factor of about 5 each time, which fits the pattern of $\mathcal{O}(L^{3/4})$, since $10^{3/4}=5.62$. Addendum: I later tested computing $f(10^{13})=59201396855810$, which took only 476.7 seconds — indeed consistent with this pattern.)
Below I've compiled some values for interested readers to reference and compare:
$$\begin{aligned} f(10^2)&=60,\ f(10^3)=1069\\ f(10^4)&=15547,\ f(10^5)=203931\\ f(10^6)&=2524207\\ f(10^7)&=30093331\\ f(10^8)&=349446716\\ f(10^9)&=3979600400\\ f(10^{10})&=44647347052\\ f(10^{11})&=494986959815\\ f(10^{12})&=5435004633092\\ f(10^{13})&=59201396855810 \end{aligned}$$
Attachment download: Project Euler 454 Code.zip
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.