Making Model Training a Bit More Scientific (VI): An Elegant Top-Down Construction
In Making Model Training a Bit More Scientific (V): Fine-Tuning the Learning Rate Based on the Gradient, we opened a new chapter on scheduling the learning rate based on gradient information. But as noted at the end of that post, when deriving the optimal learning rate for the final-point loss under dynamic gradients, we ran into a proof difficulty: specifically, the optimal learning rate sequence we "guessed" via the calculus of variations turned out to be very hard to verify by substituting it back into the bound and bounding things carefully. So, forget about proving optimality — we couldn't even determine whether this sequence was a feasible solution at all.
In this post, we resolve that problem through an elegant construction that yields a more precise result. Judging from the proof itself, this time the conclusion may well have reached a precision that can no longer be improved. This breakthrough again comes from the paper Optimal Linear Decay Learning Rate Schedules and Further Refinements.
Recap of the Problem
Let's first recall where we left off. At the end of the previous post, we obtained the general version of the conclusion from Making Model Training a Bit More Scientific (IV): A New Identity, A New Learning Rate:
\begin{equation}\mathbb{E}[L(\boldsymbol{\theta}_T) - L(\boldsymbol{\theta}^*)] \leq \frac{R^2}{2\eta_{1:T}} + \frac{1}{2}\sum_{t=1}^T\frac{\eta_t^2 G_t^2}{\eta_{\min(t+1, T):T}}\label{leq:last-2}\end{equation}more
We want to find the sequence $\eta_1,\eta_2,\cdots,\eta_T\geq 0$ that minimizes the right-hand side of the above expression. Through a continuous approximation and the calculus of variations, we "guessed" the answer to be
\begin{equation}\eta_t = \frac{R G_t^{-2}}{\sqrt{Q_T}} (1 - Q_t/Q_T)\label{eq:opt-lr-last-x}\end{equation}
where $Q_t=\sum_{k=1}^t G_k^{-2}$. However, we couldn't substitute this back in to prove it, or rather, proving it would require introducing some additional assumptions. If we try to substitute it directly, the main issue is that the denominator on the right-hand side of $\eqref{leq:last-2}$ is $\eta_{t+1:T}$ (when $t < T$), so there's no way to guarantee that $\eta_t/\eta_{t+1:T}$ stays bounded — all sorts of bounding manipulations become difficult. If we could further improve the denominator on the right-hand side of the conclusion to $\eta_{t:T}$, then the proof would follow naturally.
This post is precisely about improving the precision of conclusion $\eqref{leq:last-2}$ further — but not by directly and explicitly improving it. Instead, through careful, deliberate bounding, we construct the optimal learning rate sequence in a top-down manner, thereby achieving an improvement in precision implicitly.
Careful Bounding
Specifically, our starting point is the identity from Making Model Training a Bit More Scientific (IV): A New Identity, A New Learning Rate:
\begin{equation}\begin{aligned} q_T =&\, \frac{1}{w_{1:T}}\sum_{t=1}^T w_t q_t + \sum_{k=1}^{T-1}\left(\frac{1}{w_{k+1:T}} - \frac{1}{w_{k:T}}\right)\sum_{t=k}^T w_t (q_t - q_k) \\ =&\, \frac{1}{w_{1:T}}\sum_{t=1}^T w_t q_t + \sum_{k=1}^{T-1}\left(\frac{1}{w_{k+1:T}} - \frac{1}{w_{k:T}}\right)\sum_{t=k+1}^T w_t (q_t - q_k) \end{aligned}\label{eq:qt-g}\end{equation}
Let $q_t = \mathbb{E}[L(\boldsymbol{\theta}_t) - L(\boldsymbol{\theta}^*)]$, and let $\mathbb{E}$ denote the expectation over all $\boldsymbol{x}_1,\boldsymbol{x}_2,\cdots,\boldsymbol{x}_T$. Substituting into the above gives
\begin{equation}\mathbb{E}[L(\boldsymbol{\theta}_T) - L(\boldsymbol{\theta}^*)] = \frac{1}{w_{1:T}}\sum_{t=1}^T w_t \mathbb{E}[L(\boldsymbol{\theta}_t) - L(\boldsymbol{\theta}^*)] + \sum_{k=1}^{T-1}\left(\frac{1}{w_{k+1:T}} - \frac{1}{w_{k:T}}\right)\sum_{t=k+1}^T w_t \mathbb{E}[L(\boldsymbol{\theta}_t) - L(\boldsymbol{\theta}_k)]\label{eq:qt-g2}\end{equation}
From here on, we'll keep firmly to the principle of "no bounding unless absolutely necessary," so as to achieve as high a precision as possible. First, let's apply convexity for our first bounding step:
\begin{gather} \mathbb{E}[L(\boldsymbol{\theta}_t) - L(\boldsymbol{\theta}^*)] = \mathbb{E}[L(\boldsymbol{x}_t, \boldsymbol{\theta}_t) - L(\boldsymbol{x}_t, \boldsymbol{\theta}^*)] \leq \mathbb{E}[\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\theta}_t - \boldsymbol{\theta}^*)] \\[4pt] \mathbb{E}[L(\boldsymbol{\theta}_t) - L(\boldsymbol{\theta}_k)] = \mathbb{E}[L(\boldsymbol{x}_t, \boldsymbol{\theta}_t) - L(\boldsymbol{x}_t, \boldsymbol{\theta}_k)] \leq \mathbb{E}[\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\theta}_t - \boldsymbol{\theta}_k)] \end{gather}
Note that this requires each $\boldsymbol{\theta}_t$ to depend only on $\boldsymbol{x}_1,\boldsymbol{x}_2,\cdots,\boldsymbol{x}_{t-1}$ at most, which is satisfied in stochastic optimization, and also that the first equality in the second line requires $t\geq k$, which is also clearly satisfied. Substituting into $\eqref{eq:qt-g2}$ gives
\begin{equation}\mathbb{E}[L(\boldsymbol{\theta}_T) - L(\boldsymbol{\theta}^*)] \leq \underbrace{\frac{1}{w_{1:T}}\sum_{t=1}^T w_t \mathbb{E}[\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\theta}_t - \boldsymbol{\theta}^*)]}_{(\text{A})} + \underbrace{\sum_{k=1}^{T-1}\left(\frac{1}{w_{k+1:T}} - \frac{1}{w_{k:T}}\right)\sum_{t=k+1}^T w_t \mathbb{E}[\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\theta}_t - \boldsymbol{\theta}_k)]}_{(\text{B})}\label{leq:last-6-mid}\end{equation}
In Making Model Training a Bit More Scientific (IV): A New Identity, A New Learning Rate, the next step was to bound $(\text{A})$ and $(\text{B})$ in $\eqref{leq:last-6-mid}$ separately and then add them together. Bounding them separately inflated the error and caused trouble for the subsequent proof.
An Identity Transformation
So in this section, we'll instead merge them into a single expression via an identity transformation before applying any bounding, in order to achieve higher precision. First, we again assume that the learning rate is independent of the data $\boldsymbol{x}_t$, so we can pull the expectation $\mathbb{E}$ outside:
\begin{equation}\mathbb{E}[L(\boldsymbol{\theta}_T) - L(\boldsymbol{\theta}^*)] \leq \mathbb{E}\Bigg[\underbrace{\frac{1}{w_{1:T}}\sum_{t=1}^T w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\theta}_t - \boldsymbol{\theta}^*)}_{(\text{A})} + \underbrace{\sum_{k=1}^{T-1}\left(\frac{1}{w_{k+1:T}} - \frac{1}{w_{k:T}}\right)\sum_{t=k+1}^T w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\theta}_t - \boldsymbol{\theta}_k)}_{(\text{B})}\Bigg]\end{equation}
The more complicated part is the second term. Using $\sum_{k=1}^{T-1}\sum_{t=k+1}^T = \sum_{t=1}^T \sum_{k=1}^{t-1}$ to swap the order of summation, we get
\begin{equation}\begin{aligned} (\text{B}) =&\, \sum_{t=1}^T \sum_{k=1}^{t-1}\left(\frac{1}{w_{k+1:T}} - \frac{1}{w_{k:T}}\right) w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\theta}_t - \boldsymbol{\theta}_k) \\ =&\, \sum_{t=1}^T w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot \sum_{k=1}^{t-1}\left(\frac{1}{w_{k+1:T}} - \frac{1}{w_{k:T}}\right) (\boldsymbol{\theta}_t - \boldsymbol{\theta}_k) \\ =&\, \sum_{t=1}^T w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot \left(\left(\frac{1}{w_{t:T}} - \frac{1}{w_{1:T}}\right)\boldsymbol{\theta}_t - \sum_{k=1}^{t-1}\left(\frac{1}{w_{k+1:T}} - \frac{1}{w_{k:T}}\right) \boldsymbol{\theta}_k\right) \\ \end{aligned}\end{equation}
Adding $(\text{A})$ then lets us cancel out the term $\frac{1}{w_{1:T}}w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot\boldsymbol{\theta}_t$ exactly, and what remains, after rearranging, is
\begin{equation}\mathbb{E}[L(\boldsymbol{\theta}_T) - L(\boldsymbol{\theta}^*)] \leq \mathbb{E}\Bigg[\frac{1}{w_{1:T}}\sum_{t=1}^T w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot\Bigg(\underbrace{\frac{w_{1:T}}{w_{t:T}}\boldsymbol{\theta}_t - w_{1:T}\sum_{k=1}^{t-1}\left(\frac{1}{w_{k+1:T}} - \frac{1}{w_{k:T}}\right) \boldsymbol{\theta}_k}_{\text{denote}\boldsymbol{\psi}_t} - \boldsymbol{\theta}^*\Bigg)\Bigg]\end{equation}
If we denote the part shown in the above expression as $\boldsymbol{\psi}_t$, then the right-hand side takes on the standard form of (weighted) average-loss convergence:
\begin{equation}\mathbb{E}[L(\boldsymbol{\theta}_T) - L(\boldsymbol{\theta}^*)] \leq \mathbb{E}\Bigg[\frac{1}{w_{1:T}}\sum_{t=1}^T w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\psi}_t - \boldsymbol{\theta}^*)\Bigg] = \frac{1}{w_{1:T}}\sum_{t=1}^T w_t \mathbb{E}[\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\psi}_t - \boldsymbol{\theta}^*)]\label{leq:last-6-mid2}\end{equation}
The Update Rule
From the definition of $\boldsymbol{\psi}_t$, we can directly verify that
\begin{equation}\boldsymbol{\psi}_{t+1} - \boldsymbol{\psi}_t = \frac{w_{1:T}}{w_{t+1:T}}(\boldsymbol{\theta}_{t+1} - \boldsymbol{\theta}_t)\end{equation}
Therefore, if we update $\boldsymbol{\psi}_t$ according to $\boldsymbol{\psi}_{t+1} = \boldsymbol{\psi}_t - w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)$, then we will have $\boldsymbol{\theta}_{t+1} = \boldsymbol{\theta}_t - \frac{w_t w_{t+1:T}}{w_{1:T}} \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)$:
\begin{equation}\boldsymbol{\psi}_{t+1} = \boldsymbol{\psi}_t - w_t \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\qquad\Rightarrow\qquad\boldsymbol{\theta}_{t+1} = \boldsymbol{\theta}_t - \frac{w_t w_{t+1:T}}{w_{1:T}} \boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\end{equation}
And for $\boldsymbol{\psi}_t$ updated according to this rule, we have already proven, in Making Model Training a Bit More Scientific (II): Extending the Conclusion to Unbounded Domains and Making Model Training a Bit More Scientific (V): Fine-Tuning the Learning Rate Based on the Gradient, that the inequality
\begin{equation}\frac{1}{w_{1:T}}\sum_{t=1}^T w_t \mathbb{E}[\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\cdot(\boldsymbol{\psi}_t - \boldsymbol{\theta}^*)] \leq \frac{1}{2 w_{1:T}}\left(R^2 + \sum_{t=1}^T w_t^2 \mathbb{E}[\Vert\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\Vert^2]\right)\label{leq:avg-3}\end{equation}
holds, where $R = \Vert\boldsymbol{\psi}_1 - \boldsymbol{\theta}^*\Vert$. If we choose the same starting point for $\boldsymbol{\psi}_t$ and $\boldsymbol{\theta}_t$, then we also have $R = \Vert\boldsymbol{\theta}_1 - \boldsymbol{\theta}^*\Vert$.
Some readers might feel something is off here: isn't $\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)$ in the above expression the gradient at $\boldsymbol{\theta}_t$ rather than at $\boldsymbol{\psi}_t$, so shouldn't it be inadmissible to substitute it into the earlier conclusion? On this point, we specifically explained in Making Model Training a Bit More Scientific (V): Fine-Tuning the Learning Rate Based on the Gradient that the role of setting it as the gradient at the current point, $\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\psi}_t)$, is to establish the relationship between $\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\psi}_t)\cdot(\boldsymbol{\psi}_t - \boldsymbol{\theta}^*)$ and the loss function via convexity — but here we don't need that relationship, so swapping in $\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)$ is perfectly fine.
The Strongest Conclusion
Now, substituting conclusion $\eqref{leq:avg-3}$ into $\eqref{leq:last-6-mid2}$ and applying a second round of bounding, we obtain
\begin{equation}\mathbb{E}[L(\boldsymbol{\theta}_T) - L(\boldsymbol{\theta}^*)] \leq \frac{1}{2 w_{1:T}}\left(R^2 + \sum_{t=1}^T w_t^2 G_t^2\right)\label{leq:last-6}\end{equation}
where we've denoted $G_t^2 = \mathbb{E}[\Vert\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\Vert^2]$. In other words, if we run SGD using the learning rate $\eta_t = \frac{w_t w_{t+1:T}}{w_{1:T}}$, then its final-point loss satisfies the above inequality. Since this bound was derived through more careful bounding, it should in principle be tighter than conclusion $\eqref{leq:last-2}$ — but it's somewhat more implicit, because it requires us to first solve for $w_t$ from $\eta_t$ before we can substitute it into the right-hand side to verify it, and solving for $w_t$ explicitly is not a trivial matter.
However, we can work in the reverse direction: derive the optimal $w_t$, and then obtain the optimal $\eta_t$ from $\eta_t = \frac{w_t w_{t+1:T}}{w_{1:T}}$. The minimum of the right-hand side of the above expression was already computed in the previous post Making Model Training a Bit More Scientific (V): Fine-Tuning the Learning Rate Based on the Gradient, and the answer is:
\begin{equation}w_t = \frac{R G_t^{-2}}{\sqrt{Q_T}},\qquad Q_T=\sum_{k=1}^T G_k^{-2}\end{equation}
Then the optimal $\eta_t$ turns out to be
\begin{equation}\eta_t = \frac{w_t w_{t+1:T}}{w_{1:T}} = \frac{R G_t^{-2}}{\sqrt{Q_T}} (1 - Q_t/Q_T)\label{eq:opt-lr-last-x2}\end{equation}
which is exactly $\eqref{eq:opt-lr-last-x}$! This completes the proof of the optimality of $\eqref{eq:opt-lr-last-x}$.
As for what this result itself means, we already gave a preliminary interpretation in the previous post: the first term, $G_t^{-2}$, is inversely proportional to the squared gradient norm, which explains the necessity of early-stage warmup, since gradients tend to be larger early on; and $1 - Q_t/Q_T$ monotonically decays to zero, which explains the necessity of learning rate decay. In particular, if we assume the gradient norm is constant, we recover the linearly decaying learning rate — a schedule commonly used in practice.
Post-Hoc Adjustment
How else might $\eqref{eq:opt-lr-last-x2}$ guide practice? First, it doesn't respect causality by itself, so it can't be used directly. The original paper, Optimal Linear Decay Learning Rate Schedules and Further Refinements, offers a post-hoc verification/adjustment procedure.
The idea is actually quite simple: pick some arbitrary learning rate schedule first and train with it once; then, using the gradient information gathered, compute the optimal learning rate $\eqref{eq:opt-lr-last-x2}$, and check whether its curve matches the schedule we originally chose. If the discrepancy is large, we need to adjust the schedule and retrain — this is called "Refinement" in the paper. This approach is suitable for situations where there's plenty of room for preliminary experiments before the official training run.
The paper gives several examples of refined learning rates, most of which take the form of "Warmup-Decay." In particular, in most experiments the gradient norm in the mid-to-late stages is nearly constant, so the optimal decay shape in the mid-to-late stages is close to linear decay:
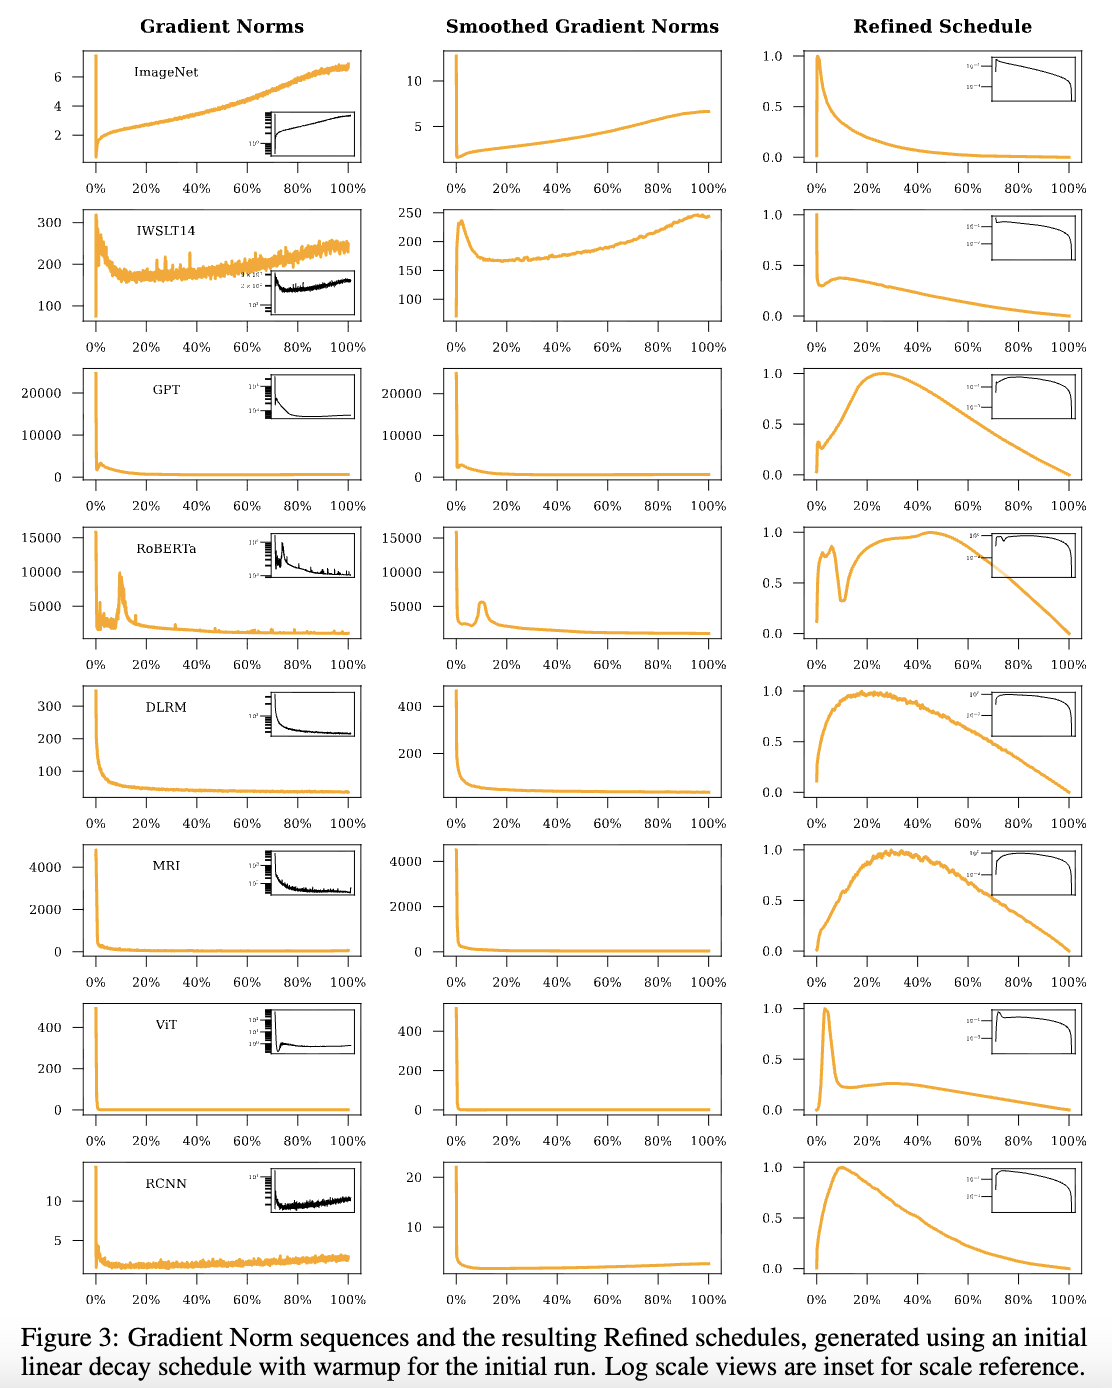 Some examples of refined learning rate schedules
Finally, the above result was derived for SGD, where we have $w_t\propto \mathbb{E}[\Vert\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\Vert^{-2}]$; in practice we can only approximate this with $\Vert\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\Vert^2$, where $\Vert\cdot\Vert$ denotes the L2 norm. For adaptive learning rate optimizers such as Adam, the paper suggests using $w_t\propto \mathbb{E}[\Vert\boldsymbol{g}(\boldsymbol{x}_t, \boldsymbol{\theta}_t)\Vert_1^{-1}]$, i.e., inversely proportional to the L1 norm. We'll discuss adaptive learning rate optimizers in a future post.
An Explicit Version
If we specify our own learning rate schedule $\eta_t$ and want to see just how good it is, this still seems rather cumbersome for now, because $\eqref{leq:last-6}$ is a semi-implicit conclusion: to substitute into the right-hand side and verify it, we would need to solve the equation $\eta_t = \frac{w_t w_{t+1:T}}{w_{1:T}}$. This equation isn't necessarily hard to solve per se — the main issue is that the solution isn't clean, making it inconvenient to use an exact solution for the proof.
Here we push the bounding further to convert it into an explicit conclusion in terms of $\eta_t$. The bounding trick is a bit subtle — it took the author quite a while to work out — but once written out, it's easy enough to follow:
\begin{equation}\eta_t = \frac{w_t w_{t+1:T}}{w_{1:T}} \leq \frac{w_t (w_{t:T} + w_{t+1:T})}{2 w_{1:T}} = \frac{w_{t:T}^2 - w_{t+1:T}^2}{2 w_{1:T}}\end{equation}
Here $w_{t:T}^2$ should be understood according to $(w_{t:T})^2$. Summing both sides from $t\sim T$, we get
\begin{equation}\eta_{t:T} \leq \frac{w_{t:T}^2}{2 w_{1:T}}\end{equation}
Substituting $t=1$ lets us derive $\frac{1}{w_{1:T}} \leq \frac{1}{2\eta_{1:T}}$, and then replacing $t$ with $t+1$ lets us derive $\frac{w_{1:T}}{w_{t+1:T}^2} \leq \frac{1}{2\eta_{t+1:T}}$; combining this further with the definition of $\eta_t$ gives $\frac{w_t^2}{w_{1:T}} = \eta_t^2 \frac{w_{1:T}}{w_{t+1:T}^2} \leq \frac{\eta_t^2}{2\eta_{t+1:T}}$. Finally, rearranging the right-hand side of $\eqref{leq:last-6}$ slightly and substituting in these inequalities gives
\begin{equation}\mathbb{E}[L(\boldsymbol{\theta}_T) - L(\boldsymbol{\theta}^*)] \leq \frac{R^2}{2 w_{1:T}} + \sum_{t=1}^T \frac{w_t^2}{2 w_{1:T}} G_t^2 \leq \frac{R^2}{4 \eta_{1:T}} + \sum_{t=1}^{T-2} \frac{\eta_t^2}{4\eta_{t+1:T}} G_t^2 + \frac{w_{T-1}^2}{2 w_{1:T}} G_{T-1}^2 + \frac{w_T^2}{2 w_{1:T}} G_T^2 \end{equation}
We didn't bound the last two terms here, because by the definition of $\eta_t = \frac{w_t w_{t+1:T}}{w_{1:T}}$ we necessarily have $\eta_T=0$, so $\frac{\eta_t^2}{2\eta_{t+1:T}}$ is infinite both at $t=T-1$ and at $t=T$. This also tells us that $\eta_1,\eta_2,\cdots,\eta_T$ actually has only $T-1$ free parameters, while the corresponding number of "unknowns" $w_1,w_2,\cdots,w_T$ is $T$ — since the number of equations is fewer than the number of unknowns, this gives us a degree of freedom that we can adjust flexibly.
Again from the definition, we have $\eta_{T-1} = \frac{w_{T-1} w_T}{w_{1:T}}$, so by the basic inequality we know
\begin{equation}\frac{w_{T-1}^2}{2 w_{1:T}} G_{T-1}^2 + \frac{w_T^2}{2 w_{1:T}}G_T^2 \geq \frac{w_{T-1} w_T}{w_{1:T}} G_{T-1}G_T = \eta_{T-1}G_{T-1}G_T \end{equation}
Because of this "flexibly adjustable degree of freedom," we can choose $w_{T-1},w_T$ appropriately (i.e., take $w_{T-1} G_{T-1} = w_T G_T$) so that the above inequality becomes an equality, giving us
\begin{equation}\mathbb{E}[L(\boldsymbol{\theta}_T) - L(\boldsymbol{\theta}^*)] \leq \frac{R^2}{4 \eta_{1:T}} + \sum_{t=1}^{T-2} \frac{\eta_t^2}{4\eta_{t+1:T}} G_t^2 + \eta_{T-1} G_{T-1} G_T\end{equation}
The author hasn't come across this particular conclusion in any existing literature, so for now let's treat it as new; its precision is higher than that of $\eqref{leq:last-2}$. Of course, conclusion $\eqref{leq:last-2}$ doesn't strictly apply to learning rate sequences that end at zero, so it's not entirely straightforward to compare directly — but judging from the constant coefficients of the leading two terms, $\eqref{leq:last-2}$ has coefficient $1/2$, whereas the above expression has $1/4$; on average, the precision should be about twice as good.
Summary
At the end of the previous post, we mentioned the difficulty of proving optimality for the final-point-loss-optimal learning rate schedule. In this post, through a top-down, carefully bounded construction, we completed this proof and obtained a higher-precision result, while also discussing the implications of this result for the "Warmup-Decay" mechanism of learning rate schedules.
Translated automatically with claude-sonnet-5; all equations are reproduced verbatim from the source. Copyright remains with the original author.